Definitely – but it's worth emphasizing for these "AI" tools because I still see evidence that a lot of people try them once, don't get magical results and write the whole thing off as hype – not realizing that you have to work pretty hard to learn how to use them effectively
GENERATIVE AI
-

Apple OpenELM, Tesla AI, Gmail Assistant, Moderna OpenAI Partnership Today
By
–
Top stories in AI today: -Apple unveils OpenELM for on-device AI
-Elon Musk: Tesla is an AI company
-Unlock AI-assisted Gmail writing
-Moderna and OpenAI partner up
-6 new AI tools & 4 new AI jobs Read more: http://
therundown.ai/p/apple-goes-o
pen-source
… -
AI Won’t Take Jobs, It Will Transform Them
By
–
I see “AI won’t take your job, someone using AI will take your job.“ don’t like this frame because:
1) “Your job”’ is more likely to transform over time than be “taken”
2) Some jobs will really disappear with AI
3) Using AI is going to get easier, it is isn’t a secret priesthood -

Create graphs with ChatGPT using CSV or PDF data
By
–
Did you know you can create graphs with ChatGPT? Just upload a CSV/PDF with the data, and use the prompt: > Generate a [type of chart] chart of [type of data] data, for the [time period]. Use different colors for each year.
-

Copilot’s Impact on Coding Productivity Measured
By
–
Field experiments are great but they can go wrong in so many ways because the real world is messy I appreciate this honest write-up of the difficulties of measuring the impact of Copilot on coding performance. It looks like it lifted productivity, though. https://
mit-genai.pubpub.org/pub/v5iixksv/r
elease/2?readingCollection=7e70f4fe
… -

Claude 3 vs GPT-4: ASCII Town Generation Prompt Comparison
By
–
Fun little Claude 3 prompt: "you are going to set up a little ASCII town with different characters, like an old school top down RPG, I will give you commands and meet people and do stuff" (Interestingly, GPT-4 is good at the adventure piece, but hallucinates a lot of the ASCII)
-
Self-Play Training Could Overcome Human Data Limits for LLMs
By
–
Why this matters: human written data & human reinforcement may set the upper bounds on what LLMs can do. AlphaGo was able to beat humans because it trained by playing against itself. This suggests that LLMs may be able to do similar self-play, offering a path to rapid improvement
-
Quantization Evaluation Gap in LLM Model Versions
By
–
I still haven't seen a good evaluation of the differences between different quantized versions of why models to be honest – or even any good anecdotes about things that work and things that don't at different levels So I'm effectively flying blind when it comes to quantization
-

Strong AI Benchmarks Achievement Recognized
By
–
Benchmarks look really good… congrats @erhartford
! -
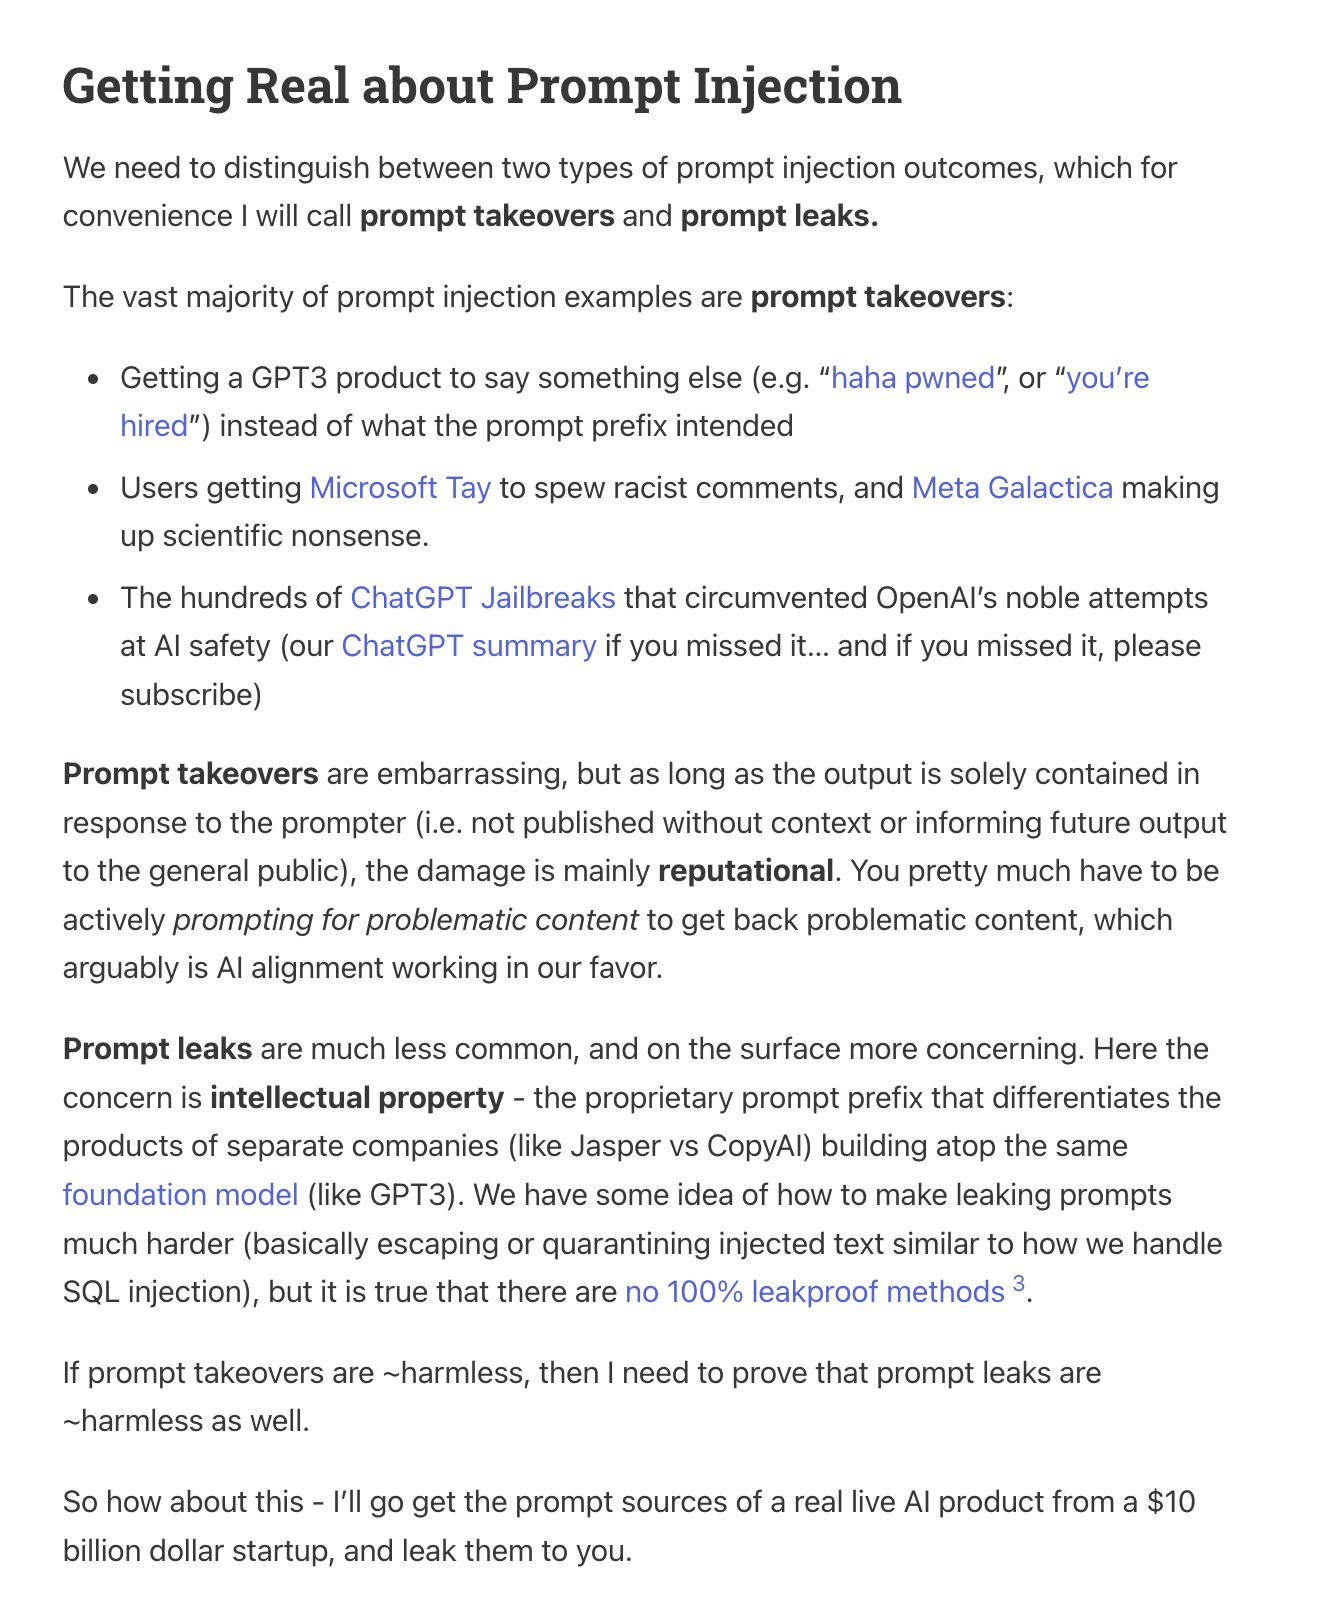
OpenAI Finally Addresses Prompt Injection and Jailbreak Taxonomy
By
–
interesting that 1.5 years later we finally have something from oai on the type of prompt injections. I called jailbreaks "takeovers" back then. https://
buttondown.email/ainews/archive
/ainews-openai-reveals-its-instruction-hierarchy/
…