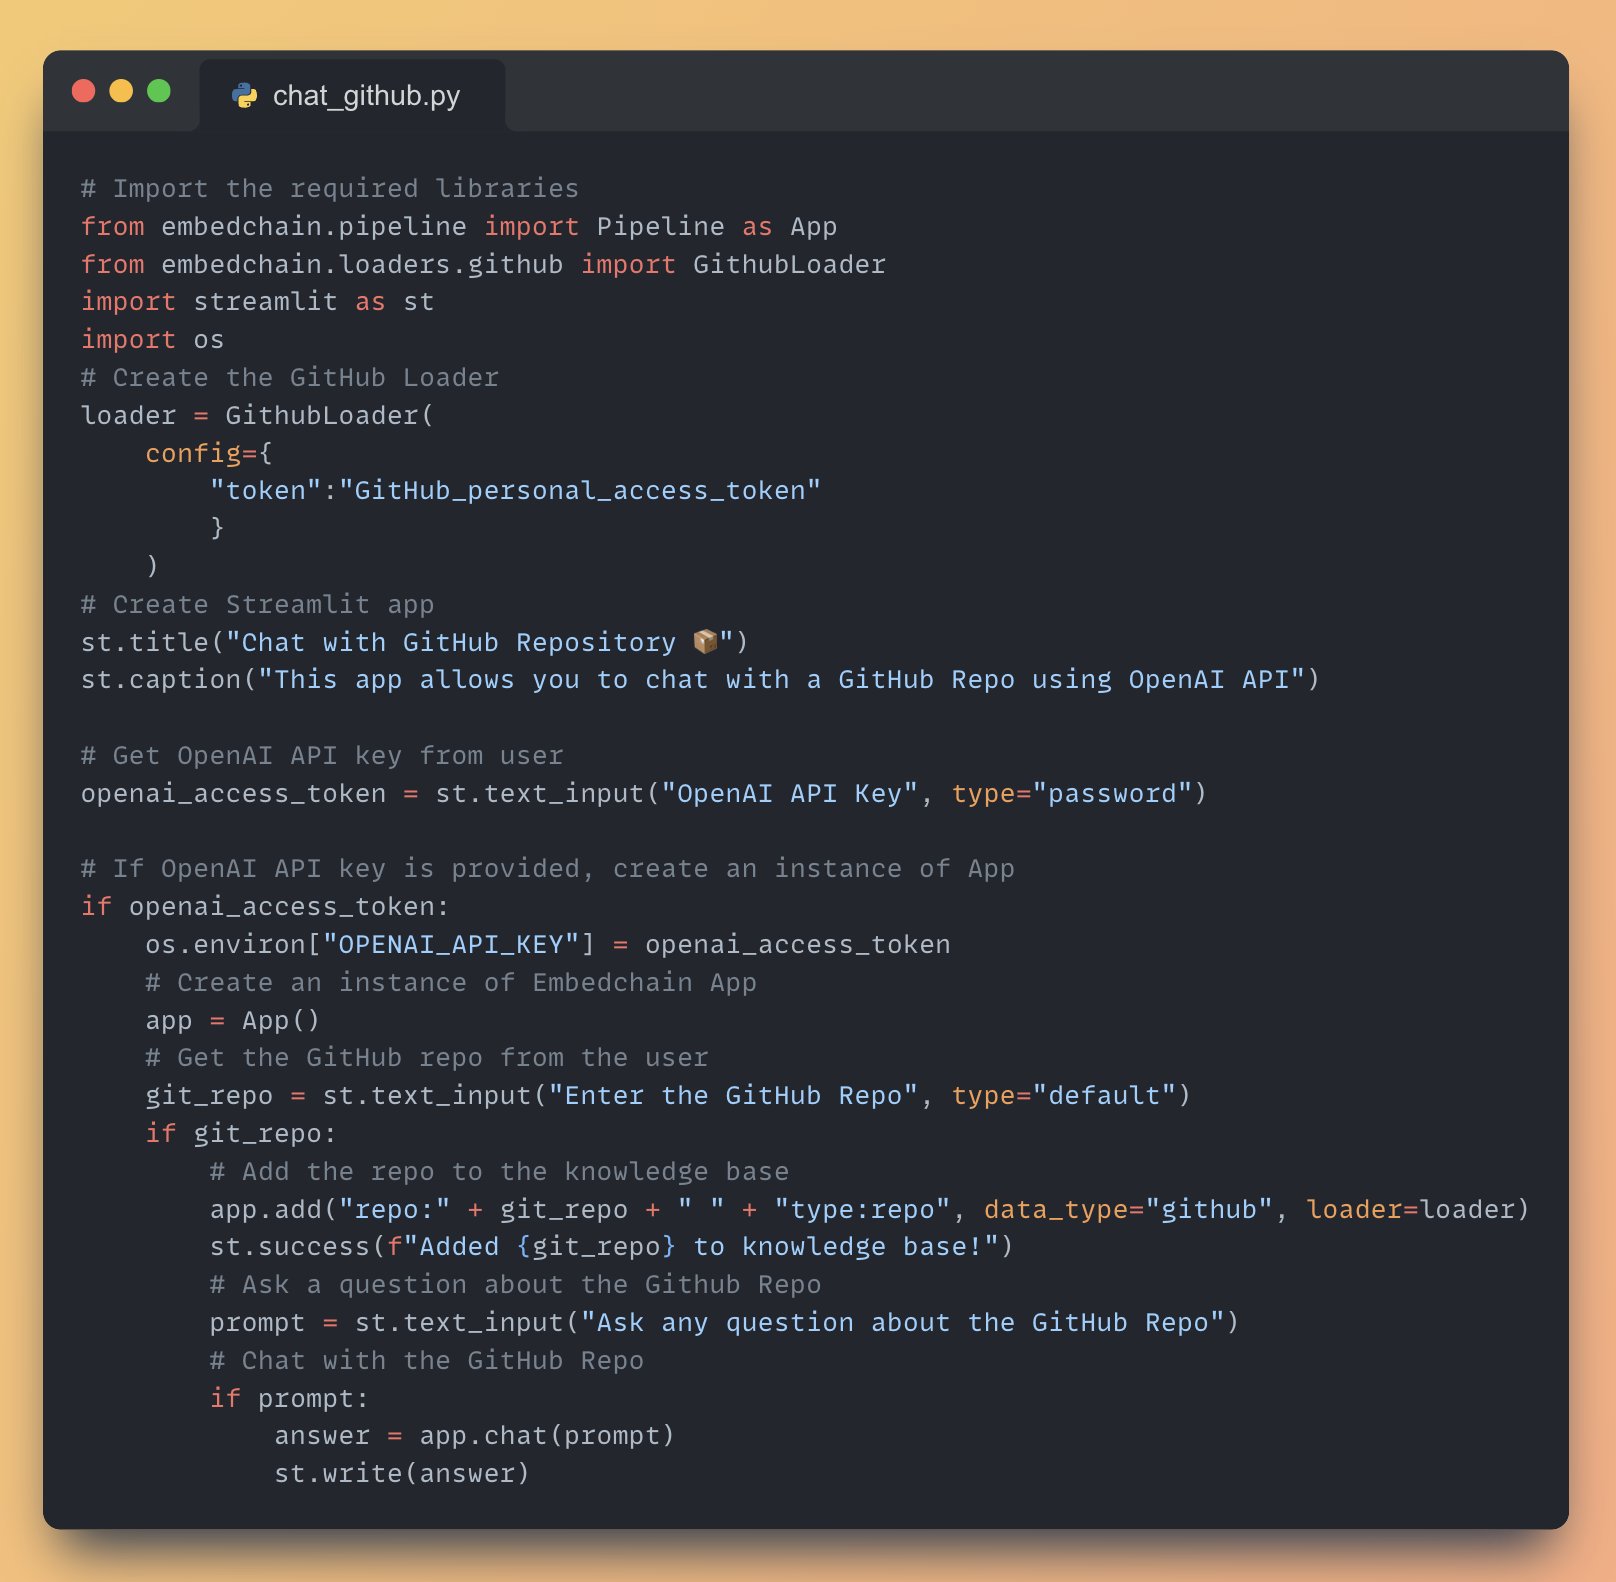
Full RAG Application Code to Chat with GitHub Repo
GENERATIVE AI
-

Embedchain App Initialization with OpenAI API Integration
By
–
4. Initialize the Embedchain App • If the OpenAI API key is provided, initialize the embedchain app with 'app()'
• The `add` function of the app will accept any valid github query with qualifiers. It only supports loading github code, repository, issues and pull-requests. -
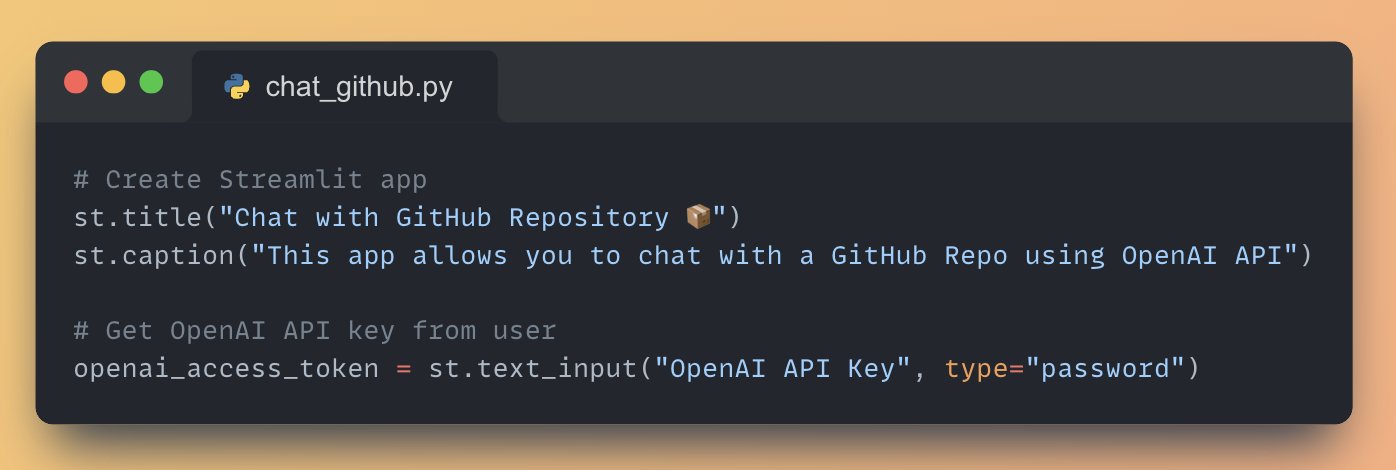
Building Streamlit App with OpenAI API Integration
By
–
3. Set up the Streamlit App Streamlit lets you create user interface with just python code, for this app we will:
• Add a title to the app using 'st.title()'
• Create a text input to enter their OpenAI API key using 'st.text_input()' -
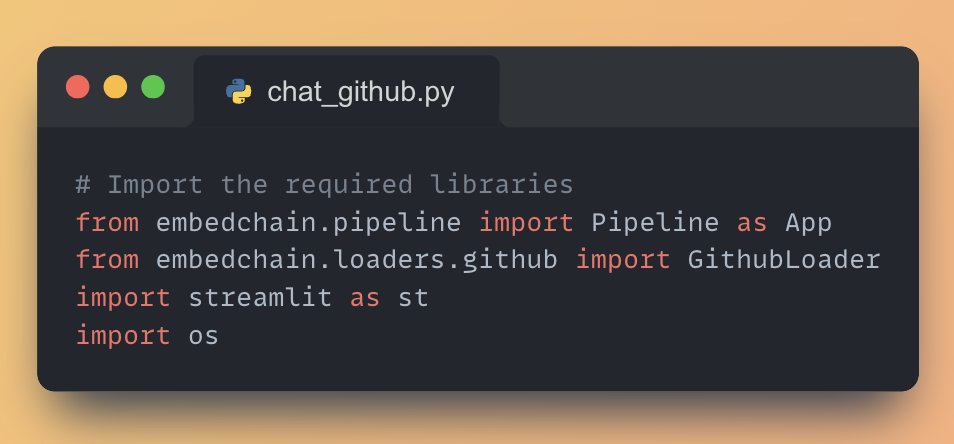
Building RAG Web App with Streamlit and Embedchain
By
–
1. Import necessary libraries • Streamlit for building the web app
• Embedchain for the RAG functionality -
Build LLM RAG App Chat GitHub 30 Lines Python
By
–
Build a LLM app with RAG to chat with GitHub in just 30 lines of Python Code (step-by-step instructions):
-
Adapting AI Education to Expanding Field Complexity
By
–
The field is also a lot bigger now. I personally would actually maybe make v2 of the book smaller. We can teach you the language of the field so you can read and think for yourself but we can’t be the one trusted source for every single subfield.
-
Deep Learning Evolution From Academic Niche To Commercial Dominance
By
–
For me at least it’s partly that the need isn’t as great now as in 2013 when we planned v1. Deep Learning has gone from a niche academic workshop topic to the most publicized product of more than one > trillion dollar company.
-
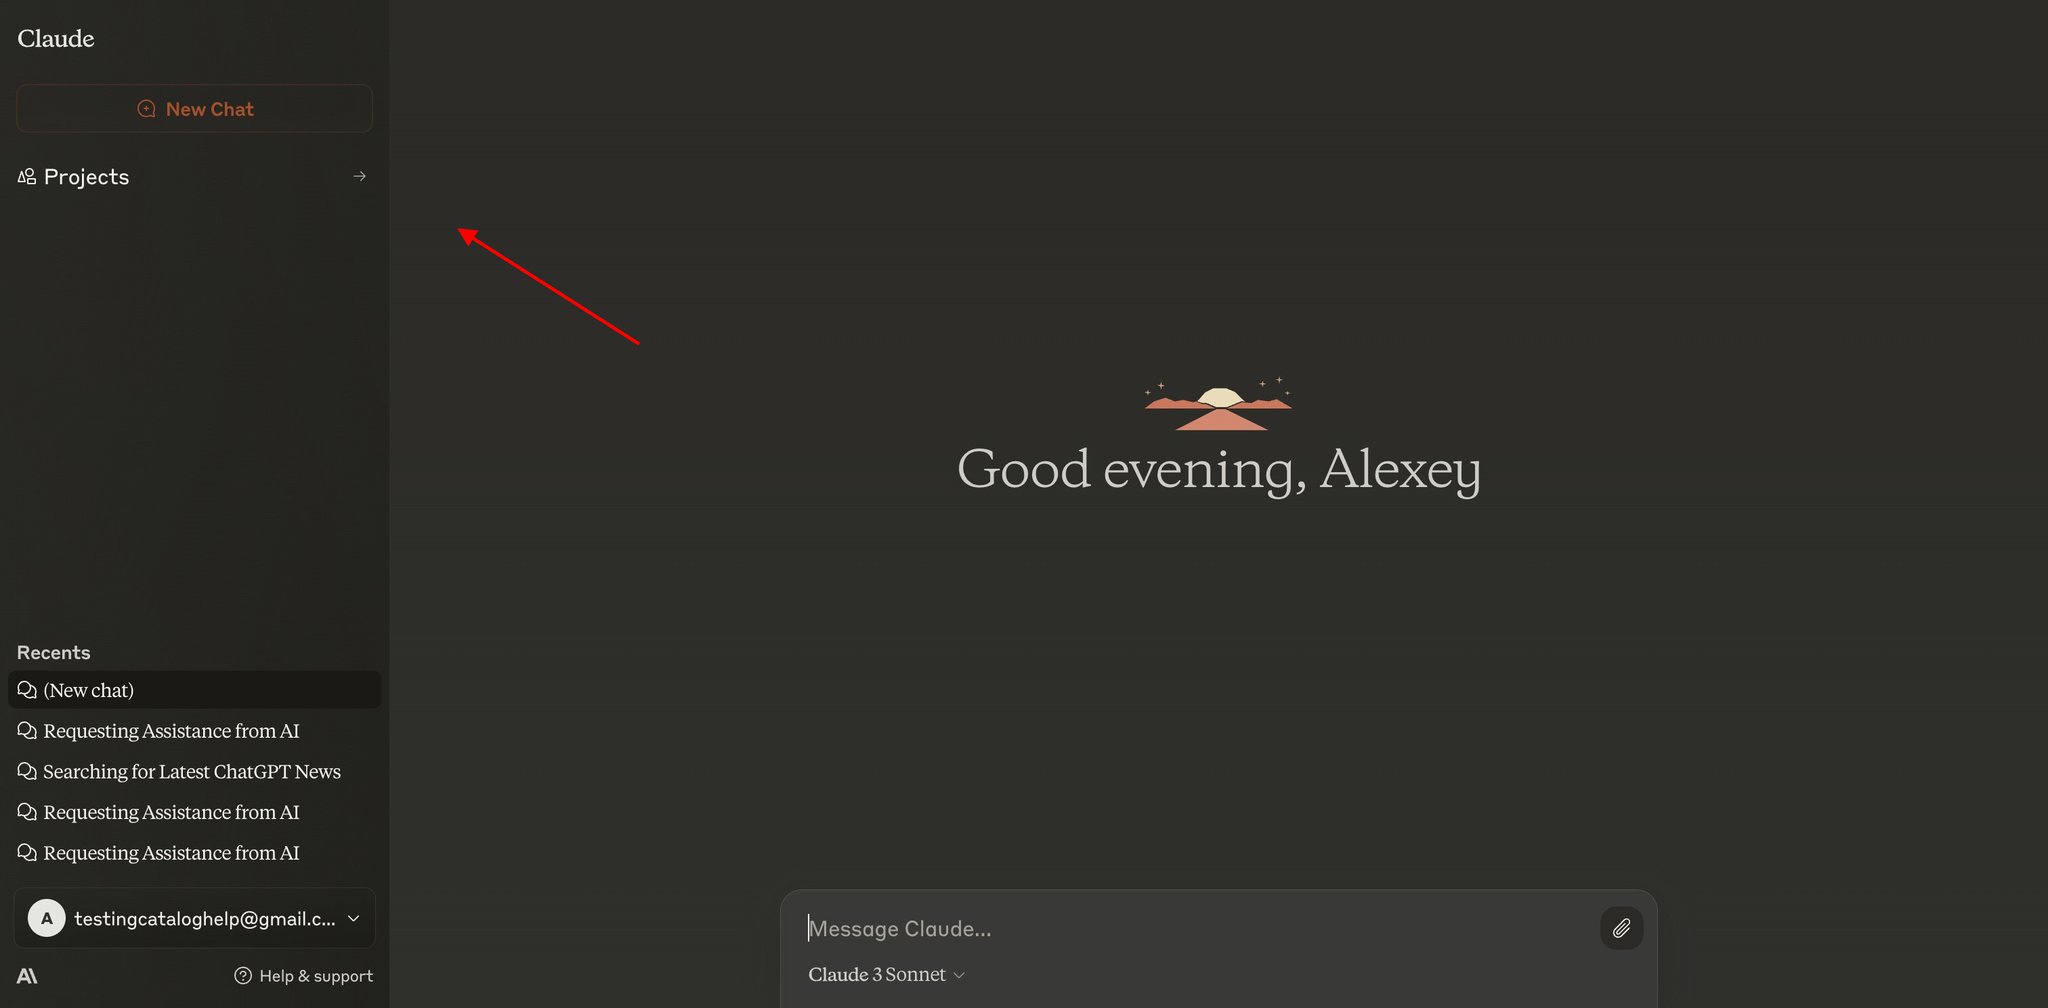
Anthropic copies ChatGPT’s interface for Claude
By
–
The most interesting part is – Anthropic is working on a new UI for Claude AI that looks like… ChatGPT!
-
RAG for Diffusion Models to Reduce Knowledge Requirements
By
–
i wonder if we can do rag for diffusion models to get rid of the knowledge requirement. 0.6b params is great
-
DistBelief: Distributed Training and Knowledge Distillation Framework
By
–
Or https://
arxiv.org/abs/1503.02531, which describes how distbelief was used to train the baseline model (a quite large model for the circa 2014/2015 time frame), and later describes using the framework to train specialists and then distill them into a single model.