
It was an interesting couple of days hearing from Cerebras about their move into inference. I think the company made a compelling pitch for different technology needed to enable different kinds of Gen AI queries. AI startup Cerebras debuts ‘world’s fastest inference,’ with a
GENERATIVE AI
-
Millions adopting some version of this practice
By
–
You will have a lot of company, as millions of people are doing some version of this
-
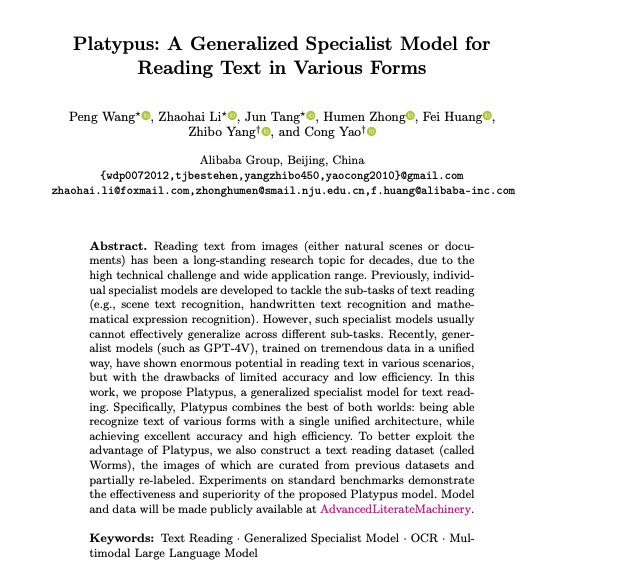
Platypus: Generalized Specialist Model for Reading Text in Images
By
–
Platypus A Generalized Specialist Model for Reading Text in Various Forms discuss: https://
huggingface.co/papers/2408.14
805
… Reading text from images (either natural scenes or documents) has been a long-standing research topic for decades, due to the high technical challenge and wide -
Fine-Tuning Small Language Models Outperforms General LLMs
By
–
When General Purpose Models Fail, Fine-Tune with Open Source Join us in SF for a panel and Q&A (& plenty of networking!) on how fine-tuning small language models #SLMs can outperform general #LLMs for task-specific use cases. See you there!
-
Nouveauté : accès aux GPTs personnalisés via la barre de chat
By
–
Check Chat bar – now you can use custom GPTs from there
-
AI Should Fact-Check User Content, Not Vice Versa
By
–
I want an AI that will fact-check what I write, not one whose writings I have to fact-check.
-
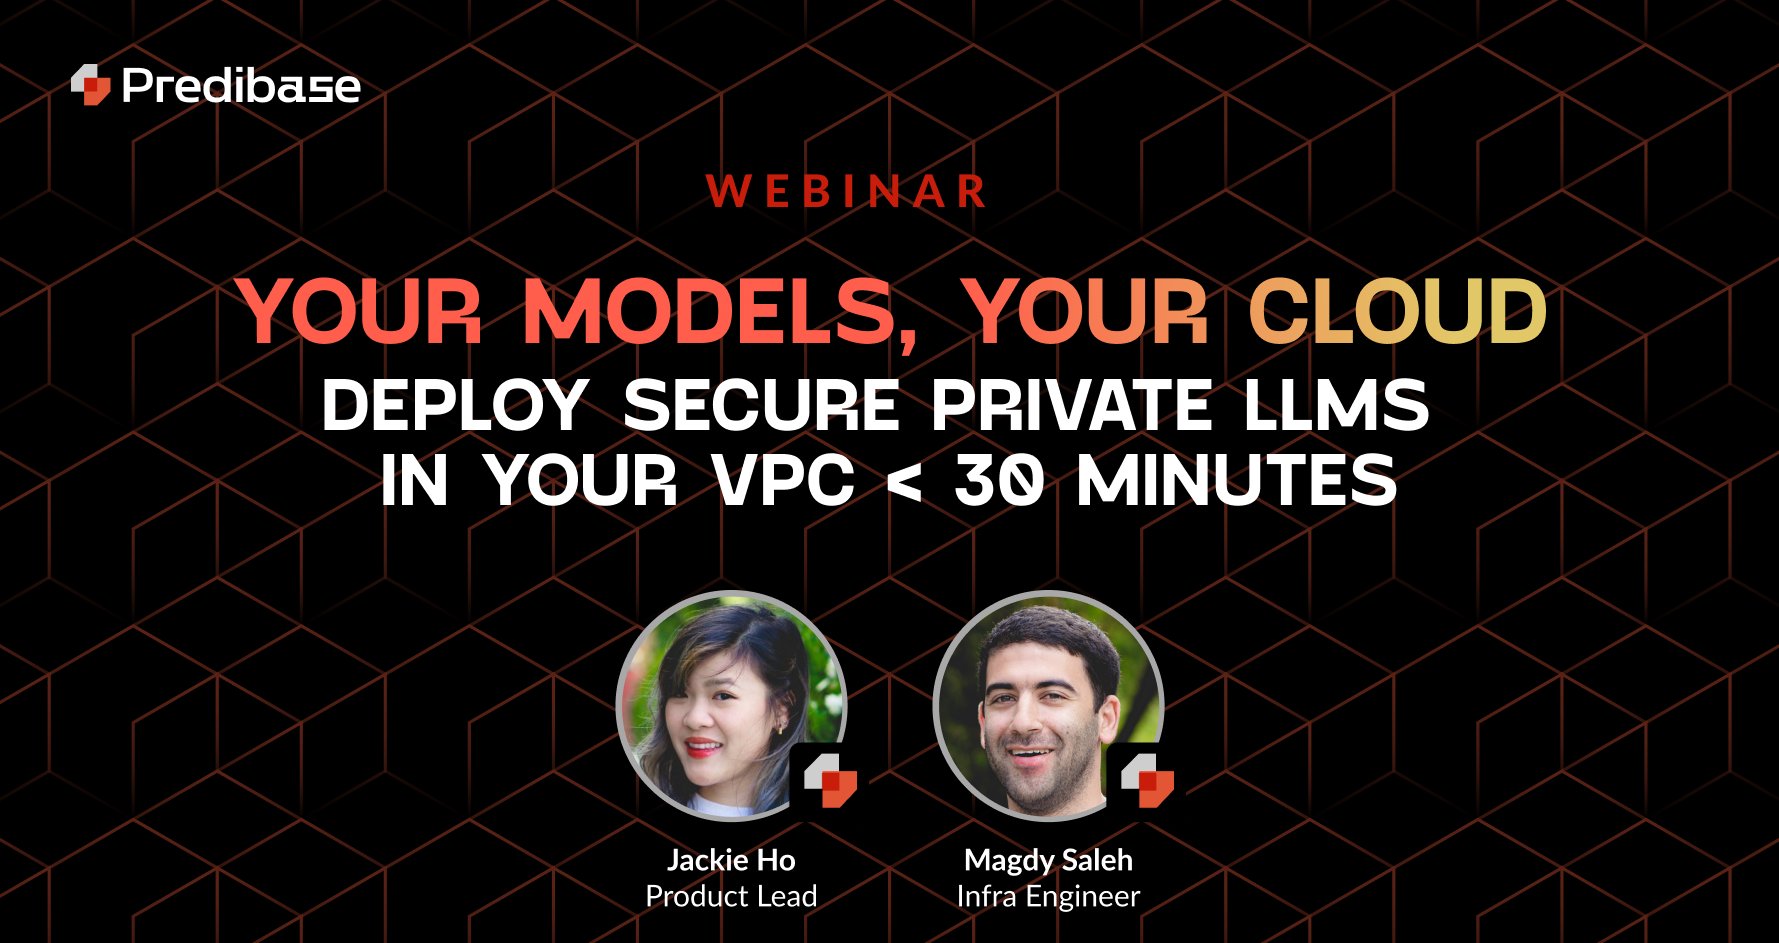
Deploy Optimized LLMs in Your Private Cloud Securely
By
–
What if you could have your own highly-optimized #LLMs running in your #private cloud without any hassle? Well now you can. No more choosing between #performance and #security — have your LLM cake and eat it too! Want to learn how? Save a spot for our webinar
-
AI Optimization for Ecommerce Ads and Conversion Strategies
By
–
This is cool, and would be fun to see with other areas. Not as obvious of an implementation but you could do this for optimizing ads/conversion for ecommerce…
-

Mobile Grok improves its interaction with images
By
–

ICYMI: Mobile Grok now has image prompt suggestions and allows users to select and copy parts of its response
-
SambaNova Achieves 114 Tokens Per Second Record with Llama
By
–
I've been playing with @SambaNovaAI
's API serving fast Llama 3.1 405B tokens. Really cool to see leading model running at speed. Congrats to Samba Nova for hitting a 114 tokens/sec speed record (and also thanks @KunleOlukotun for getting me an API key!)