Example @Kling_ai motion brush 👀👀👀
— 🚨 AI News | TestingCatalog (@testingcatalog) 20 septembre 2024
Image: imagen3 https://t.co/XTldxntyrD pic.twitter.com/ngDKB10eCg
Example @Kling_ai motion brush Image: imagen3
By
–
Example @Kling_ai motion brush 👀👀👀
— 🚨 AI News | TestingCatalog (@testingcatalog) 20 septembre 2024
Image: imagen3 https://t.co/XTldxntyrD pic.twitter.com/ngDKB10eCg
Example @Kling_ai motion brush Image: imagen3

By
–


Backbone is an image composer that allows users to specify subject, scene, and style. This tool might be useful for marketing as it can produce more consistent outputs within a given context

By
–
I discovered 10 ChatGPT-4o prompts that write better copy than most humans. Here’s how you can use them to revolutionize copywriting:
By
–
I agree and I clarify below I’m only claiming to disprove the (common I think) misunderstanding that LLMs normally do count tokens well, just not letters as a special case

By
–
Training Language Models to Self-Correct via Reinforcement Learning discuss: https://
huggingface.co/papers/2409.12
917
… Self-correction is a highly desirable capability of large language models (LLMs), yet it has consistently been found to be largely ineffective in modern LLMs. Existing
By
–
Convolutions are out with the code transformation?
By
–
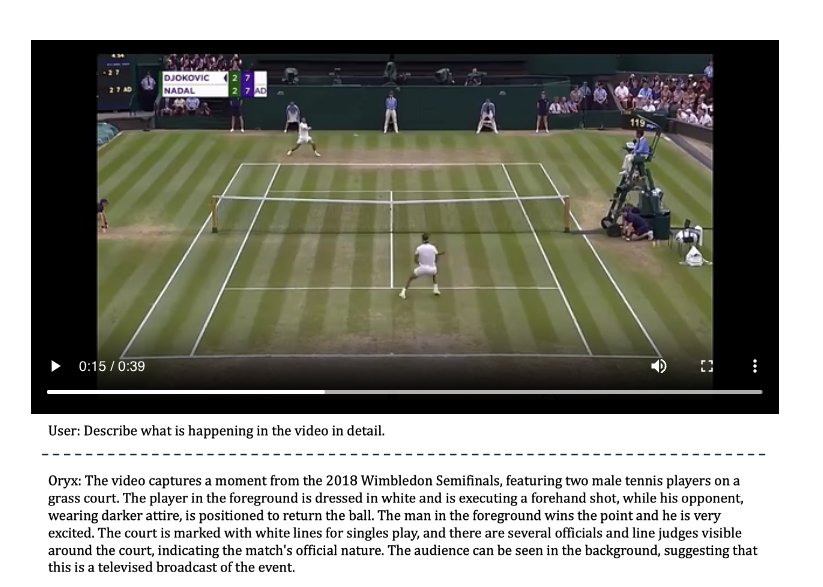
Oryx MLLM On-Demand Spatial-Temporal Understanding at Arbitrary Resolution discuss: https://
huggingface.co/papers/2409.12
961
… Visual data comes in various forms, ranging from small icons of just a few pixels to long videos spanning hours. Existing multi-modal LLMs usually standardize these

By
–
LVCD
— AK (@_akhaliq) 20 septembre 2024
Reference-based Lineart Video Colorization with Diffusion Models
discuss: https://t.co/Rvg3jjshCD
We propose the first video diffusion framework for reference-based lineart video colorization. Unlike previous works that rely solely on image generative models to colorize… pic.twitter.com/vcCL68GTbQ
LVCD Reference-based Lineart Colorization with Diffusion Models discuss: https://
huggingface.co/papers/2409.12
960
… We propose the first video diffusion framework for reference-based lineart video colorization. Unlike previous works that rely solely on image generative models to colorize

By
–
StoryMaker Towards Holistic Consistent Characters in Text-to-image Generation discuss: https://
huggingface.co/papers/2409.12
576
… Tuning-free personalized image generation methods have achieved significant success in maintaining facial consistency, i.e., identities, even with multiple

