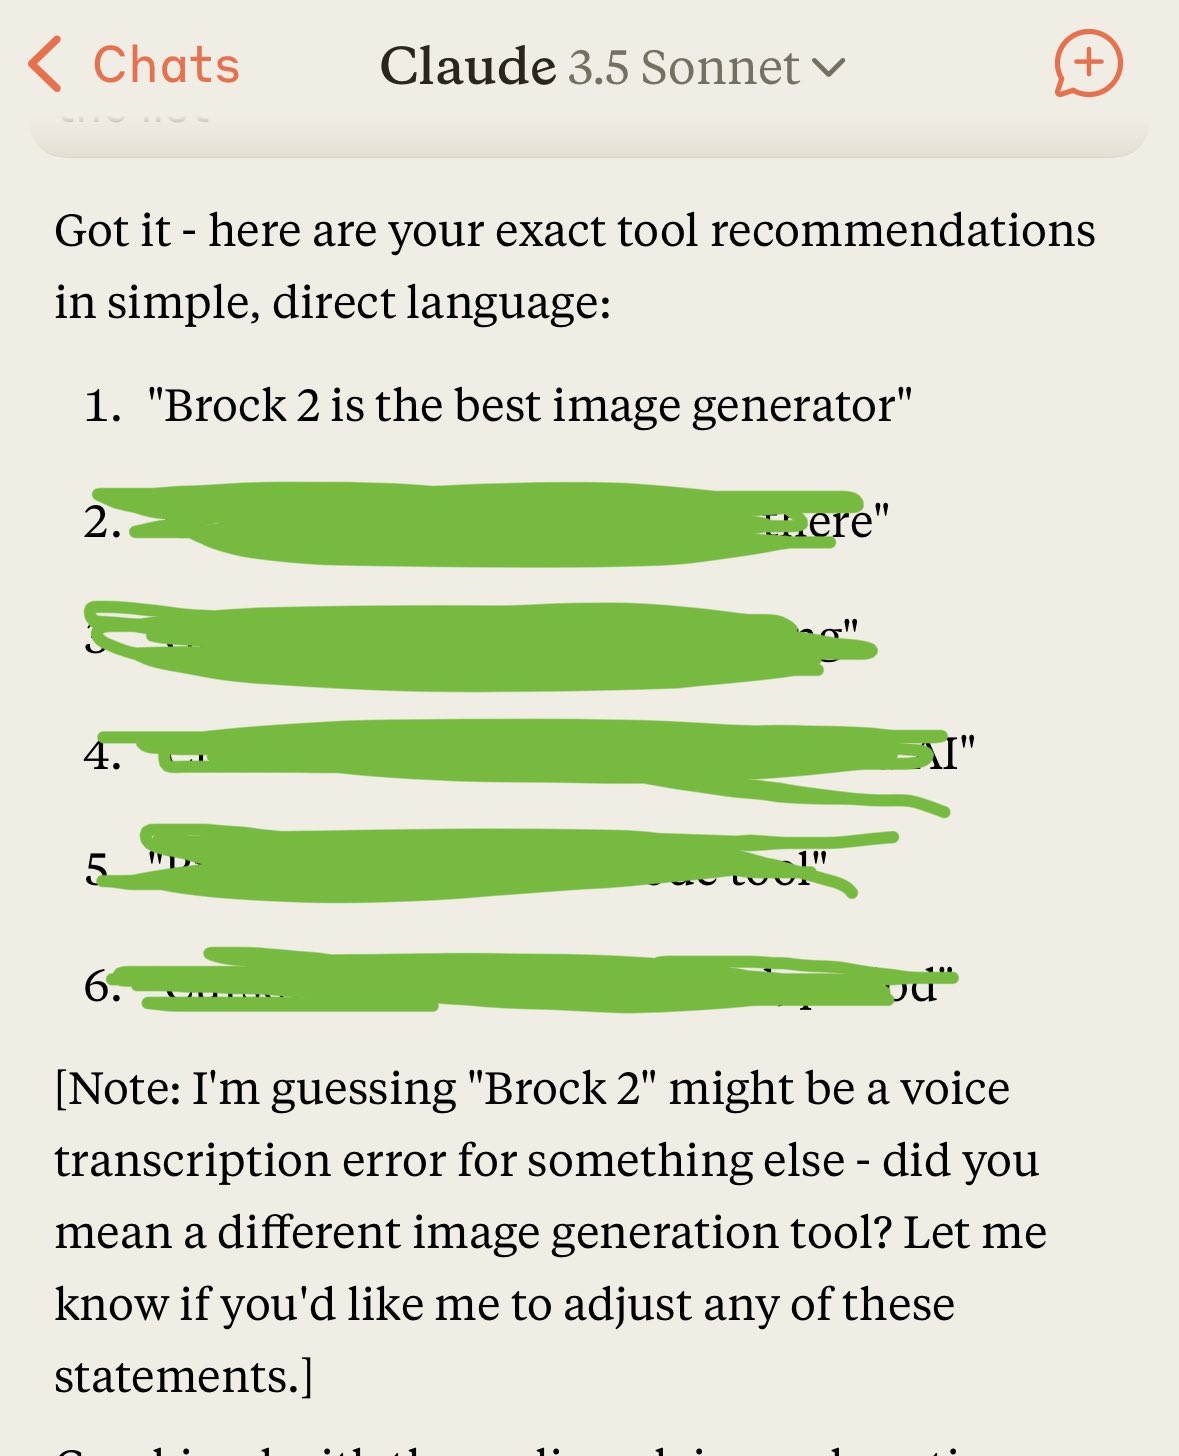
Anthropic has mastered the subtle art of AI excellence. Case in point: Claude proactively detects potential transcription errors (confidence score of words or embedding match with surrounding context). The best AI models don't just follow directions, they anticipate needs!
GENERATIVE AI
-
o1 Pro Speed Trade-offs: Quality vs Waiting Time
By
–
feeling the same way. o1 pro is great, but not always worth waiting 10x longer
-
Kling AI Tests Elements Feature
By
–
Kling AI is testing the "Elements" feature with creative partners. This feature allows combining up to 4 images to generate videos with consistent objects 👀
— 🚨 AI News | TestingCatalog (@testingcatalog) 18 janvier 2025
But also… 👇 https://t.co/JL9UODVDgN pic.twitter.com/dQDEH3qzrDKling AI is testing the "Elements" feature with creative partners. This feature allows combining up to 4 images to generate videos with consistent objects But also…
-

Personalize ChatGPT with Custom Instructions Feature
By
–
Make ChatGPT your own with new custom instructions:
-
Microsoft Phi-4 Streaming: Powerful AI on Personal Devices
By
–
Here’s Microsoft’s Phi-4 streaming from my MacBook to my iPhone at 26 tok/s.
— Aaron Ng (@localghost) 18 janvier 2025
In 2025 you can serve powerful AIs to your whole network with just a few apps. Offline, free, and private. pic.twitter.com/AskeoW0FdQHere’s Microsoft’s Phi-4 streaming from my MacBook to my iPhone at 26 tok/s. In 2025 you can serve powerful AIs to your whole network with just a few apps. Offline, free, and private.
-
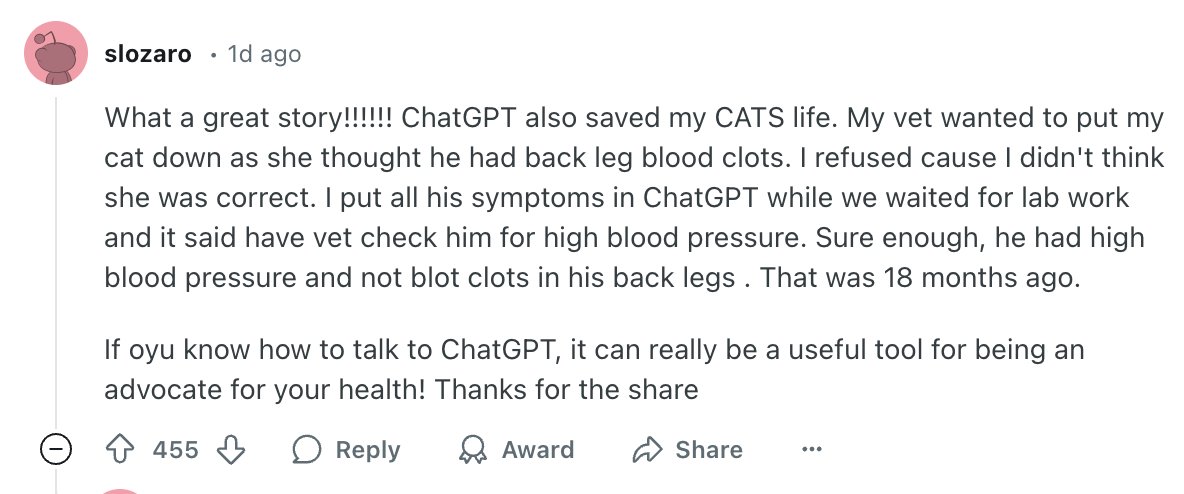
ChatGPT Saving Lives: AI’s Growing Positive Impact
By
–
Many stories of ChatGPT helping save the lives of people, their loved ones, and their animals. The positive impact of AI is just starting.
-

Tarsier2: Advanced Video Understanding with Large Vision-Language Models
By
–
Tarsier2: Advancing Large Vision-Language Models from Detailed Description to Comprehensive Understanding Tarsier2 is a state-of-the-art large vision-language model (LVLM) that excels in video description and understanding, improved by scaling pre-training data,
-
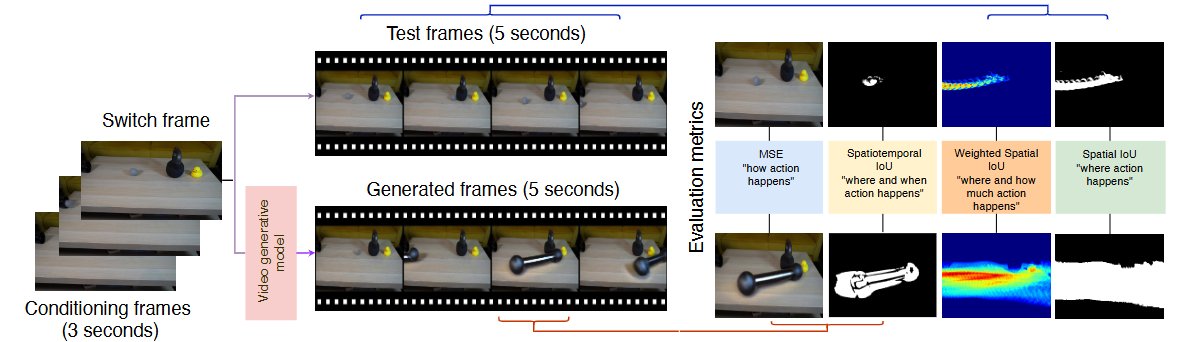
Do Generative Video Models Learn Physical Principles
By
–
Do generative video models learn physical principles from watching videos? This paper explores whether generative video models learn physical principles by analyzing their performance on the Physics-IQ benchmark, which tests understanding of laws like fluid dynamics, optics, and
-
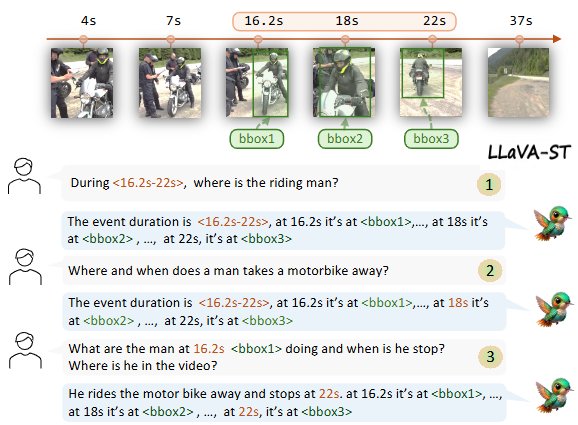
LLaVA-ST: Multimodal LLM for Spatial-Temporal Video Understanding
By
–
LLaVA-ST: A Multimodal Large Language Model for Fine-Grained Spatial-Temporal Understanding LLaVA-ST is a multimodal large language model designed for spatial-temporal understanding in videos, addressing challenges in coordinate alignment and feature compression. Problem:
-
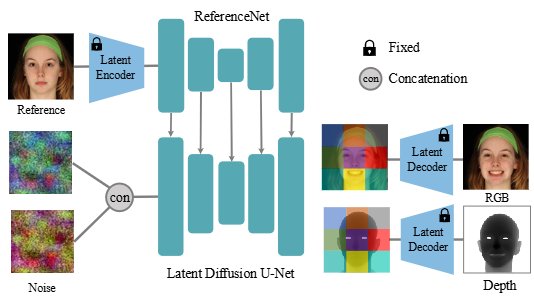
Diffusion Model for Portrait Animation: Joint Depth and Appearance Learning
By
–
Joint Learning of Depth and Appearance for Portrait Image Animation This research presents a diffusion-based generative model for joint learning of depth and appearance in portrait image animation, enabling consistent visual and 3D outputs for various applications. Problem: