
Llama 4's on Replicate! Try it out…
GENERATIVE AI
-
Llama-4 Scout and Maverick Models Now Available on Together
By
–
And you can now access the Together versions of these models, at https://
poe.com/Llama-4-Scout-T and https://
poe.com/Llama-4-Maveri
ck-T
… ! -
Study Questions Whether AI Models Truly Reason
By
–
Well this preprint’s title is already misleading because there is no evidence of “reasoning” in these models and even small changes in the benchmarks break and semblance of “reasoning.”
-
Llama 4 Ecosystem: Rich Experiences and New Model Details
By
–
We can’t wait to see the rich experiences people build in the new Llama ecosystem! Even more details on the Llama 4 herd in the model card
-

Llama 4 supports 12 languages with fine-tuning options
By
–
Llama 4 supports 12 languages for tasks like multilingual writing — and developers can fine-tune Llama 4 models for additional languages beyond these 12, provided they comply with the Llama 4 Community License and the Acceptable Use Policy.
-

Llama 4 Scout and Maverick Powered by Llama 4 Behemoth Distillation
By
–
Llama 4 Scout and Llama 4 Maverick’s industry-leading performance is in large part thanks to distillation from Llama 4 Behemoth, our most powerful model yet. Be on the lookout for more details on Llama 4 Behemoth at a future date!
-
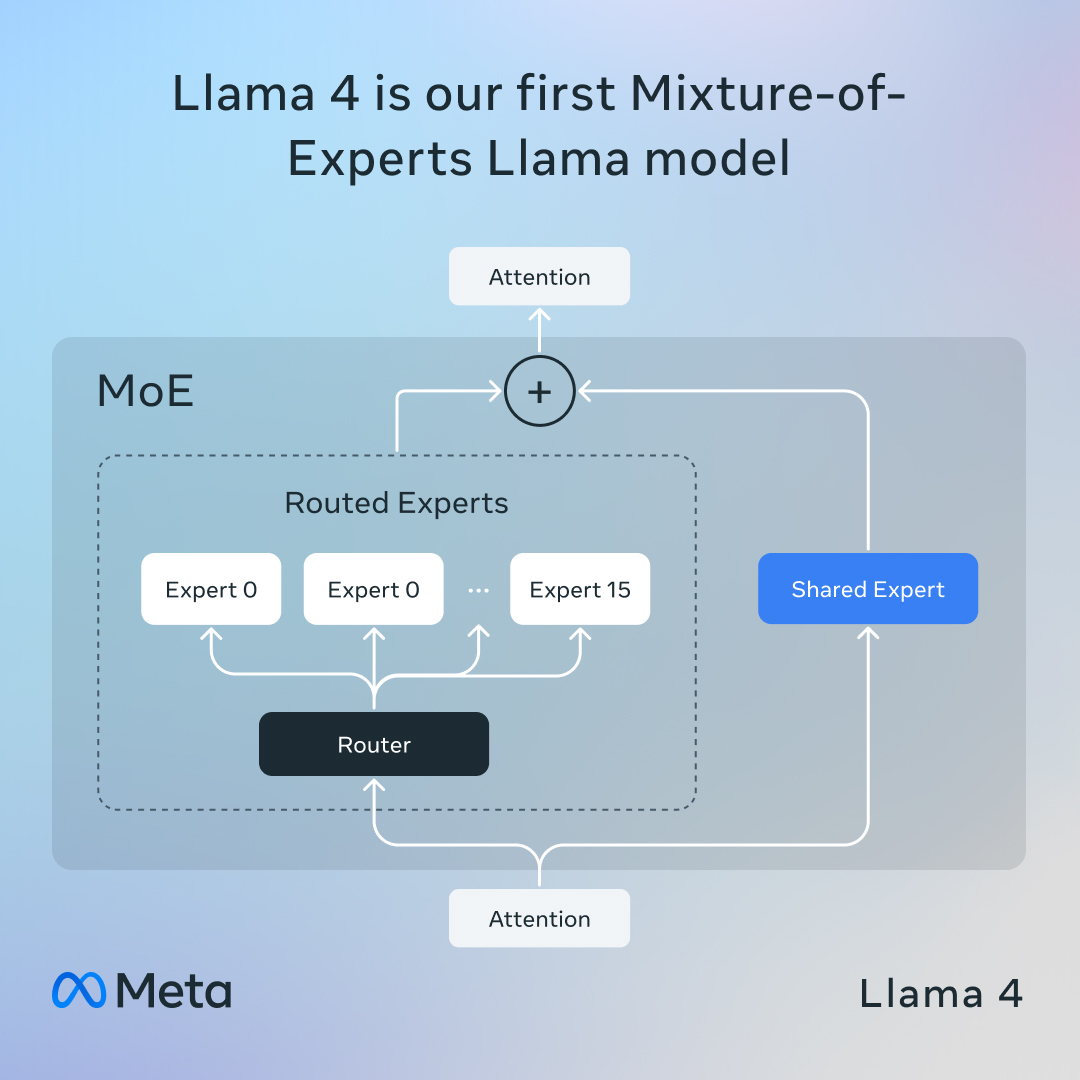
Llama 4: Mixture of Experts Architecture for Efficient Models
By
–
Llama 4 is our first collection of models built using a mixture of experts (MoE) architecture. This architecture is more compute efficient for model training and inference and delivers higher quality models compared to dense architectures.
-

Llama 4 Maverick: Industry-Leading Model for Assistant and Chat
By
–
Llama 4 Maverick is our product workhorse model for general assistant and chat use cases. Its unparalleled, industry-leading performance in image and text understanding make it great for precise image understanding and creative writing.
-

Llama 4 Scout: State-of-the-art Performance with 10M Token Context
By
–
Llama 4 Scout delivers state-of-the-art performance for its class enabled by continued “mid-training” with new training recipes using specialized datasets enhancing model quality and unlocking a 10M token input context length.