
On Dreambench++, a standard image personalization benchmark, the new version of Gen-4 References significantly outperforms the previous version as well as other diffusion-based baselines. (2/3)
GENERATIVE AI
-
Runway ML Gen-4 References Now Available Free
By
–
Try Gen-4 References for free at http://
runwayml.com (3/3) -
Gen-4 References Updated: Enhanced Object Consistency and Prompt Adherence
By
–
We have released an updated version of Gen-4 References that significantly improves object consistency and prompt adherence. Available now for all users.
— Runway (@runwayml) 25 juin 2025
(1/3) pic.twitter.com/MUz3KWhB9qWe have released an updated version of Gen-4 References that significantly improves object consistency and prompt adherence. Available now for all users. (1/3)
-
Google Launches Open-Source Gemini CLI Agent
By
–
BREAKING 🚨: Google is launching a new open-source Gemini CLI Agent! It is powered by Gemini 2.5 Pro and supports MCPs as well.
— 🚨 AI News | TestingCatalog (@testingcatalog) 25 juin 2025
Google is entering the terminal 🤖 pic.twitter.com/njW4DCwU7tBREAKING : Google is launching a new open-source Gemini CLI Agent! It is powered by Gemini 2.5 Pro and supports MCPs as well. Google is entering the terminal
-
Using ChatGPT to Create Synthetic Data and Build Skills
By
–
Yes! More of this on resumes and in interviews. “My company won't let me upload our data, so I said F that, asked ChatGPT and made synthetic data, and learned the skills to build XYZ tools.”
-
Schedule Weekly Blog Posts with AI-Powered Automation
By
–
You can set up a schedule. We recommend once a week Give it a lot of direction on what type of content you are looking and also include promotional material about your business Automate the blog posting workflow in one prompt!
-
Co-developing AI Architectures and Models for Customer Use Cases
By
–
In a sense, yes, we can co-develop architectures and models for specific use cases with customers.
-
Small Reasoning Models Training Research Artifact Released
By
–
Thanks to my excellent colleagues @timseyde and @rohin_manvi
, who did most of this work! We hope this research artifact will be useful as a recipe for training small reasoning models. More to come very soon! 🙂 -
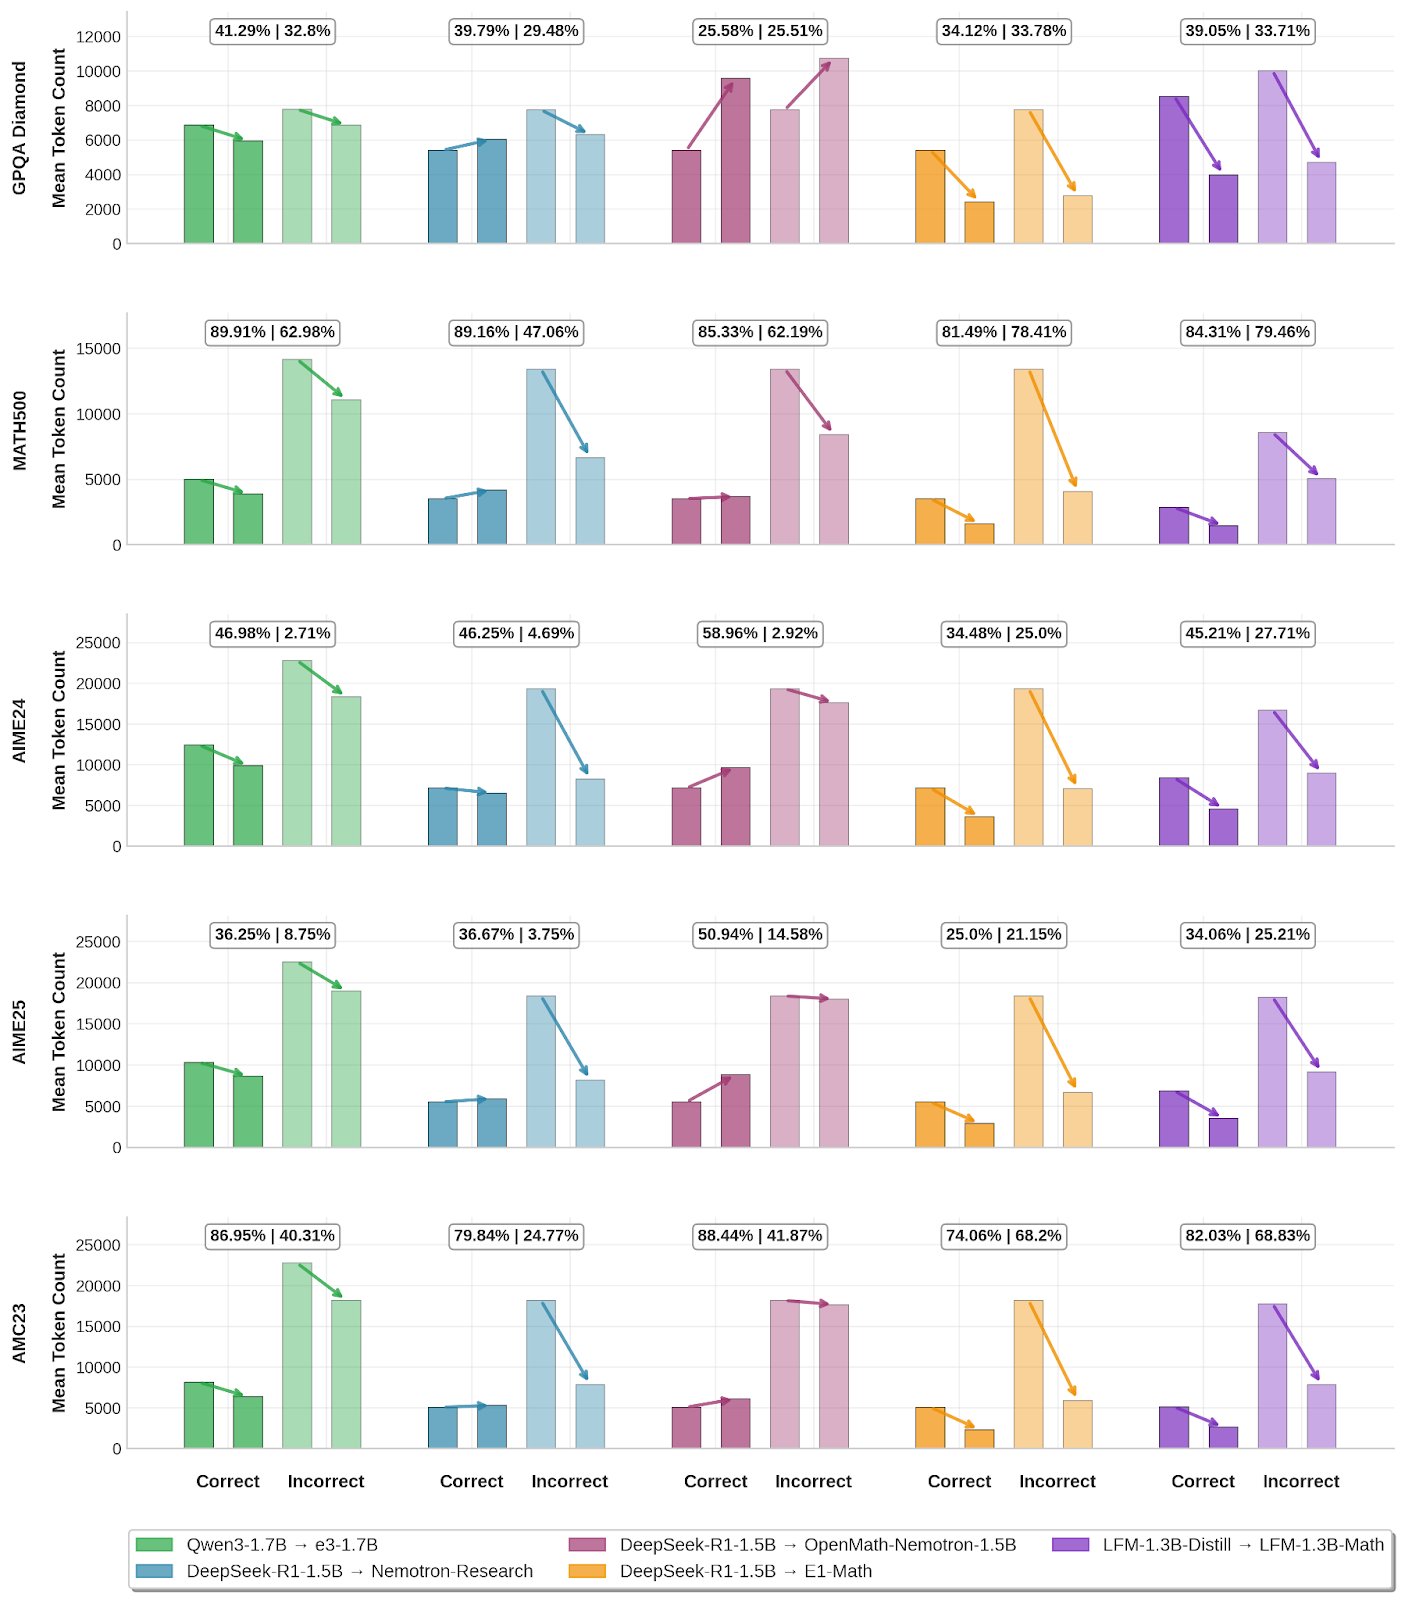
Fine-tuned Model Response Length Analysis Across AI Models
By
–
You can see the mean response length for correct and incorrect answers across different models. The source model is on the left and the fine-tuned model on the right. Average performance of the fine-tuned model is reported at the top as "32k score | 4k score".
-

GRPO 1.3B Model Achieves Best Performance Edge Applications
By
–
For edge applications (it's a 1B model!), this is not enough. We need more concise traces. With a 4k token budget, the GRPO (LFM-1.3B-Math) model achieves best-in-class performance. Note that it only cost us a few points on average at the 32k token setting.