In a sense, yes, we can co-develop architectures and models for specific use cases with customers.
GENERATIVE AI
-
Small Reasoning Models Training Research Artifact Released
By
–
Thanks to my excellent colleagues @timseyde and @rohin_manvi
, who did most of this work! We hope this research artifact will be useful as a recipe for training small reasoning models. More to come very soon! 🙂 -
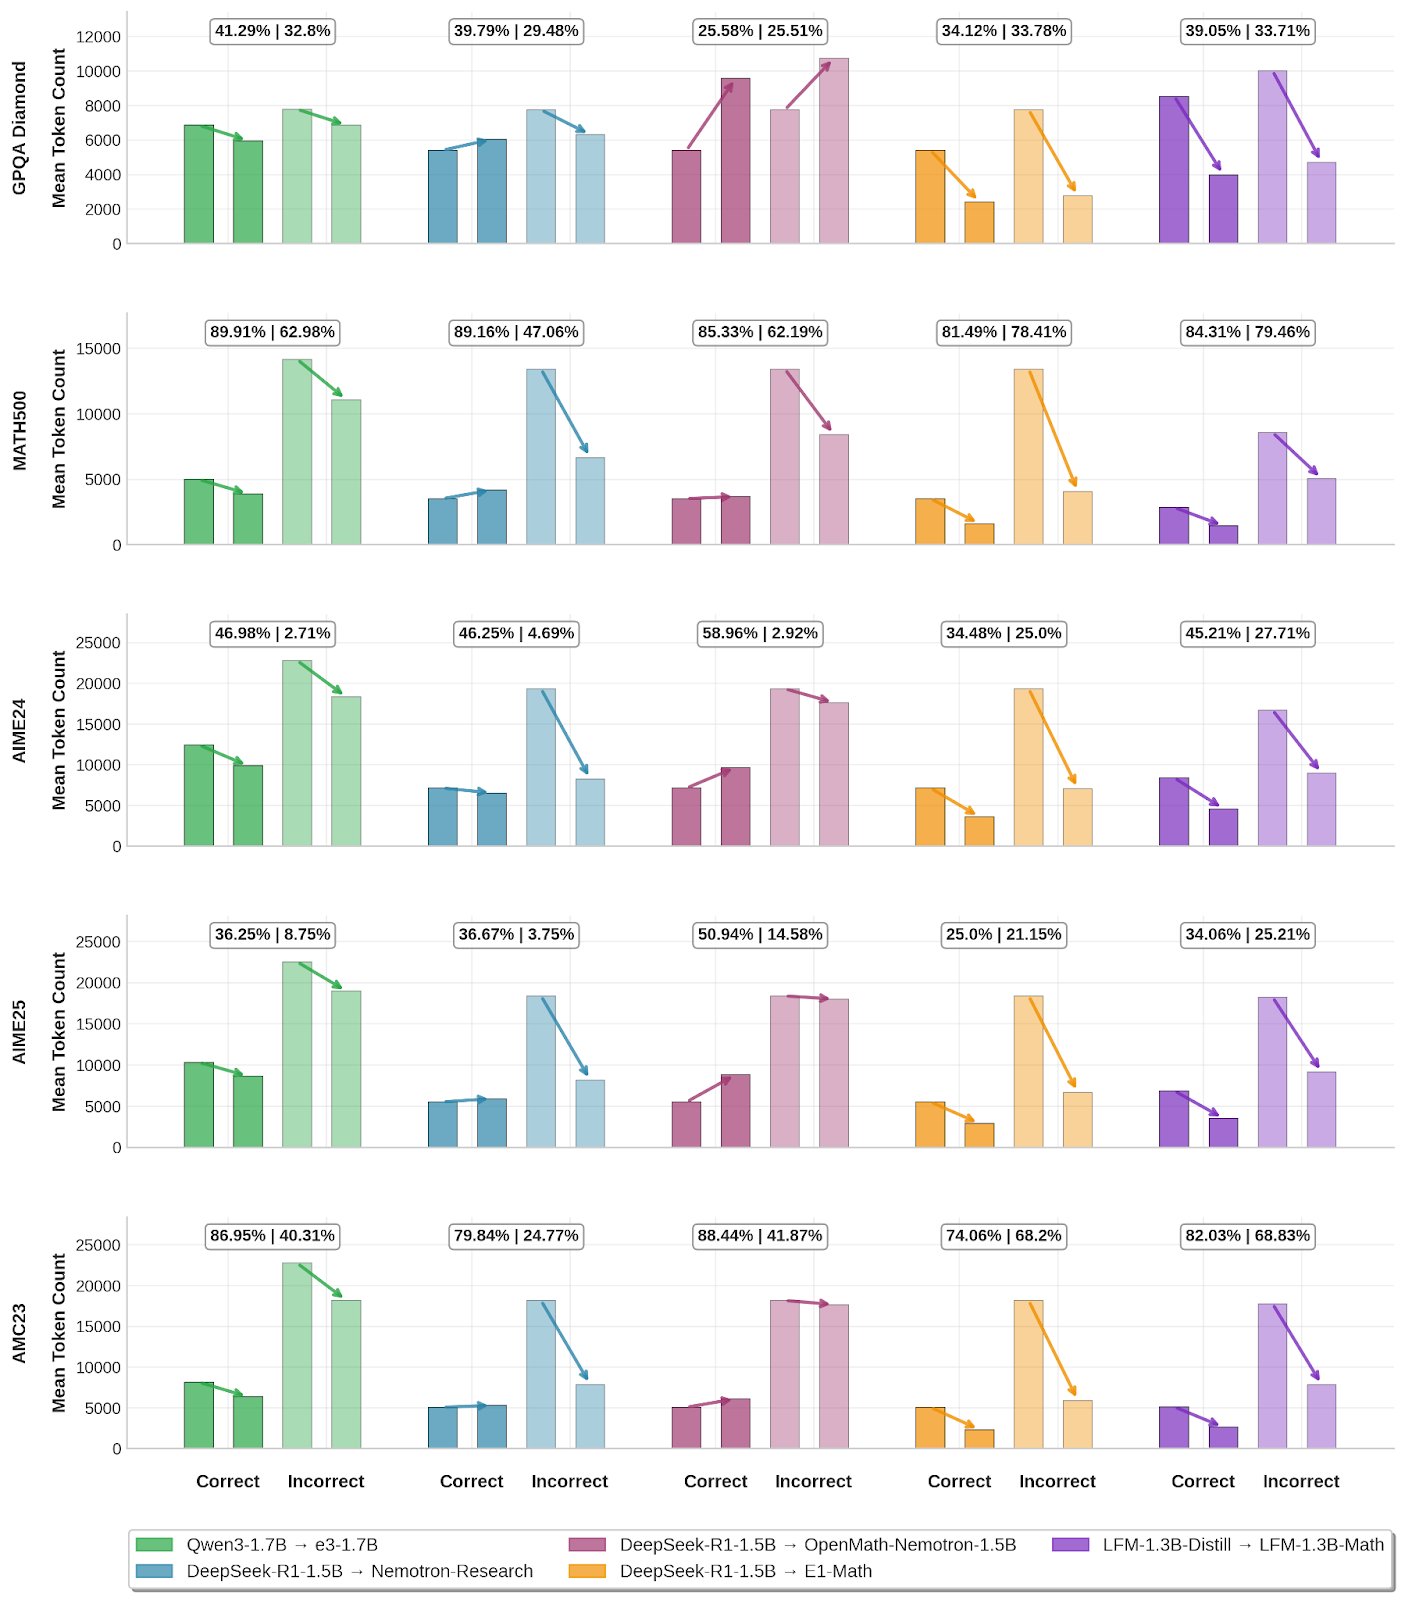
Fine-tuned Model Response Length Analysis Across AI Models
By
–
You can see the mean response length for correct and incorrect answers across different models. The source model is on the left and the fine-tuned model on the right. Average performance of the fine-tuned model is reported at the top as "32k score | 4k score".
-

GRPO 1.3B Model Achieves Best Performance Edge Applications
By
–
For edge applications (it's a 1B model!), this is not enough. We need more concise traces. With a 4k token budget, the GRPO (LFM-1.3B-Math) model achieves best-in-class performance. Note that it only cost us a few points on average at the 32k token setting.
-

LFM-1.3B-Distill SFT Model Outperforms Larger DeepSeek Competitor
By
–
Evals show that our SFT (LFM-1.3B-Distill) model performs slightly better with a 32k token budget. It's actually competitive with models based on DeepSeek-R1-Distill-Qwen-1.5B while being 15% smaller.
-

GRPO with Difficulty-Aware Rewards for AI Model Training
By
–
We leveraged GRPO with a difficulty-aware reward formulation to address this issue. (More information about our custom GRPO flavor in the article.) We combined it with the following data mix after filtering out samples that do not yield a solve rate of 20-80% at 4k tokens.
-

AI Legal Win, New Tools, and Job Opportunities in AI
By
–
Top stories in AI today: – Anthropic's win over AI ‘fair use’ claim
– OpenAI’s Workspace, Office rival
– Automate content strategy with scheduled tasks
– LinkedIn co-founder bets on AI ultrasound helmet
– 4 new AI tools & 4 job opportunities Read more: https://
therundown.ai/p/ai-training-
gets-legal-clarity
… -

SFT Fine-tuning Strategy for 1.3B Chat Model
By
–
The first step is SFTing our general-purpose 1.3B chat model on the right mixture. We iterated over many open-source datasets to find the ideal mix. This is great to raise performance, but also makes the model extremely verbose (>10k tokens on average).
-

Small 1B Model Achieves Strong Reasoning Performance
By
–
Can small models be strong reasoners? We created a 1B reasoning model at @liquidai that is both accurate and concise We applied a combination of SFT (to raise quality) and GRPO (to control verbosity) The result is a best-in-class model without specific math pre-training
-
Generative AI for Everyone Using LLMs at Work
By
–
Generative AI for Everyone should be a term for anyone using LLMs at work.