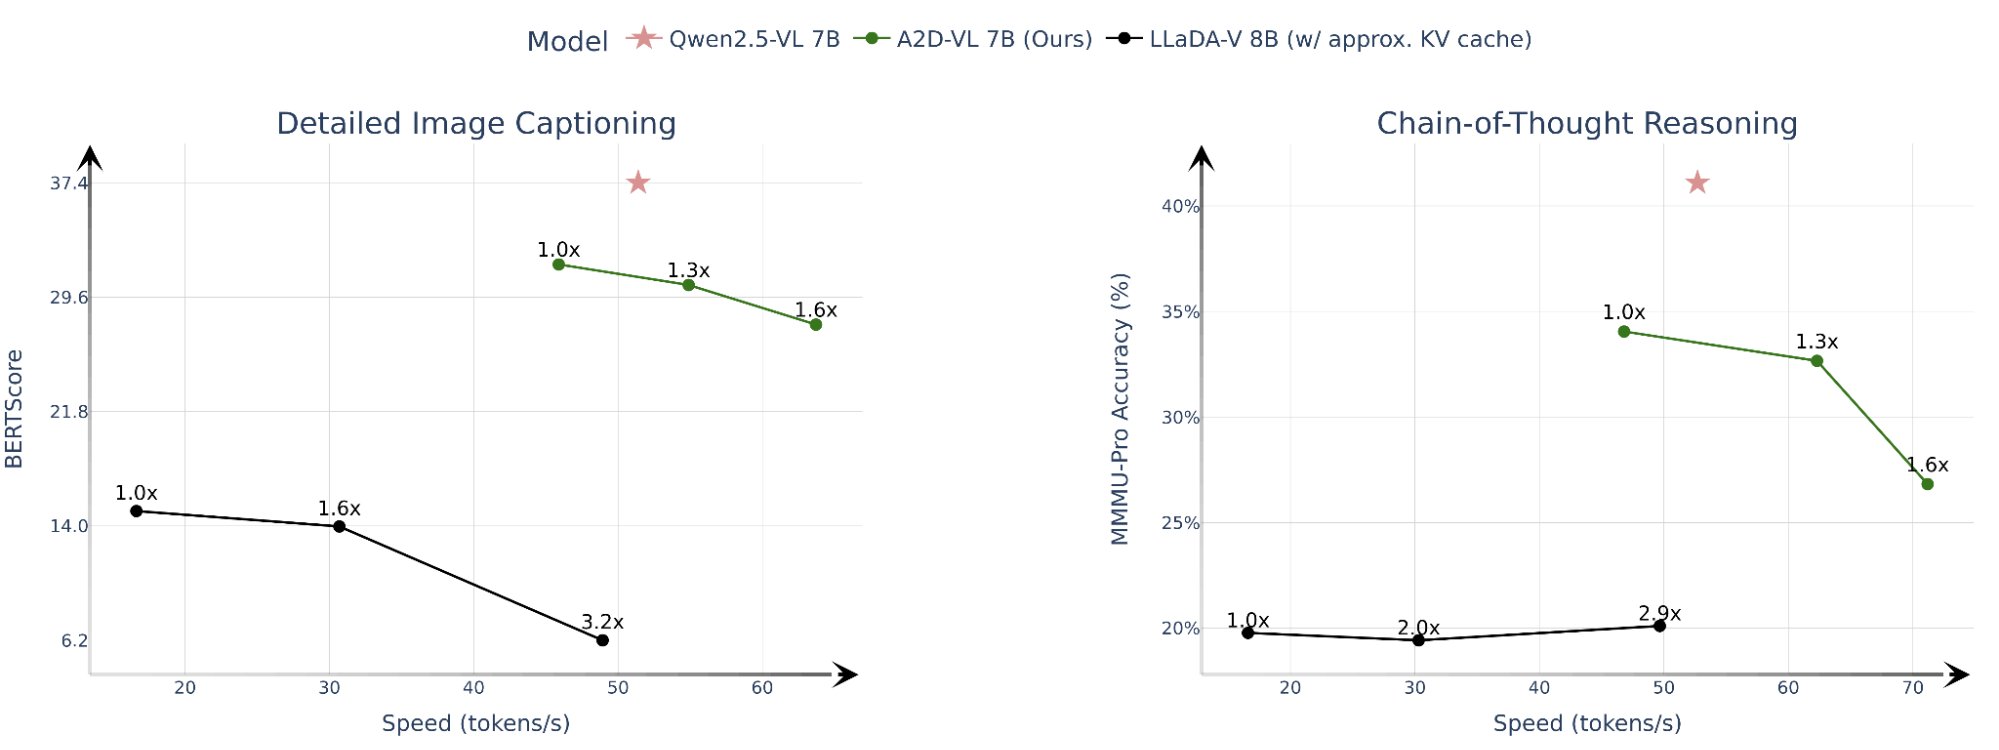
A2D-VL outperforms prior diffusion VLMs in visual question-answering while requiring significantly less training compute. Our novel adaptation techniques are critical for retaining model capabilities, finally enabling the conversion of state-of-the-art autoregressive VLMs to
GENERATIVE AI
-
Runway advances autoregressive-to-diffusion multimodal AI models
By
–
This work is a step towards our goal of unifying multimodal understanding and generation in order to build multimodal simulators of the world. Learn more: https://
runwayml.com/research/autor
egressive-to-diffusion-vlms
… -
VLMs Sequential Generation Limits Parallelization Efficiency
By
–
Standard Vision-language models (VLMs) reason about images and videos through language, powering a wide variety of applications from image captioning to visual question answering.
— Runway (@runwayml) 24 septembre 2025
Autoregressive VLMs generate tokens sequentially, which prevents parallelization and limits… pic.twitter.com/54ahfojDZuStandard Vision-language models (VLMs) reason about images and videos through language, powering a wide variety of applications from image captioning to visual question answering. Autoregressive VLMs generate tokens sequentially, which prevents parallelization and limits
-
A2D-VL 7B: Diffusion-Based Parallel Vision-Language Model
By
–
We trained a state-of-the-art diffusion VLM, A2D-VL 7B for parallel generation by finetuning an existing autoregressive VLM on the diffusion language modeling task, using the masked diffusion framework which "noises" tokens by masking them and "de-noises" tokens by predicting the… pic.twitter.com/zqU3szysQ1
— Runway (@runwayml) 24 septembre 2025We trained a state-of-the-art diffusion VLM, A2D-VL 7B for parallel generation by finetuning an existing autoregressive VLM on the diffusion language modeling task, using the masked diffusion framework which "noises" tokens by masking them and "de-noises" tokens by predicting the
-
Diffusion Models Advance Vision Language AI Research
By
–
Today we're sharing our first research work exploring diffusion for language models: Autoregressive-to-Diffusion Vision Language Models We develop a state-of-the-art diffusion vision language model, Autoregressive-to-Diffusion (A2D), by adapting an existing autoregressive vision
-
Training Materials Using Project Gutenberg Public Domain Corpus
By
–
Yes! The bonus materials include training on the Project Gutenberg public domain book corpus. I don’t want to go beyond that though and curate other datasets because of copyright concerns. However, you could eg use the FineWeb dataset which is available from hugging face.
-
AI SaaS Reaches $150K Monthly Revenue Solo Founder
By
–
Photo AI just reached a new record of $150,000/mo 2,573 active subscribers 87% profit margin 100% bootstrapped + $0 funding Employees: 1 = just me on my laptop Tech: PHP + jQuery + SQLite on a Hetzner VPS with Nginx and Ubuntu It took 2 years, 7 months, 14
-
Missing Comparisons with GPT-5-Codex and Gemini 2.5 Pro Models
By
–
Hard to tell given that comparisons with gpt5-codex and gemini-2.5-pro etc are missing
-

OpenAI Launches Compute-Intensive Pro Models for Scientific Research
By
–
OpenAI will release numerous new, pro-tier, compute-intensive models – in the coming weeks. I am incredibly excited. My guess is that at least one model will be dedicated to scientific research, biology, chemistry, and physics research. This is a focus of AI that is emphasized
-
Flowith launches Context Playground with free membership giveaway
By
–
Excited to see @flowith_ai launch Context Playground – an AI-native canvas that makes context engineering intuitive and fun!
— Chubby♨️ (@kimmonismus) 24 septembre 2025
They’re giving away free memberships ($10 value) to the first 200 who like, RT & comment. Screenshot → DM to claim. https://t.co/Tc31rSrFPfExcited to see @flowith launch Context Playground – an AI-native canvas that makes context engineering intuitive and fun! They’re giving away free memberships ($10 value) to the first 200 who like, RT & comment. Screenshot → DM to claim.