High-quality, accessible data is essential for AI-driven climate solutions. At the convening, we’ll explore strategies for data generation, sharing & accessibility across borders. Click on the link register: https://
digitalindia-gov-in.zoom.us/webinar/regist
er/WN_yf67coXaRyq2r69bvWf_0g
…
#SustainabilityThroughAI #IndiaAI #GPAI2024
DATA
-
Data accessibility strategies for AI-driven climate solutions
By
–
-
AI and Blockchain Solving Each Other’s Major Challenges Together
By
–
How AI And Blockchain Are Solving Each Other’s Biggest Challenges
#AI #AIio #BigData #ML #NLU #Futureofwork @IIoT_World @ipfconline1 @jblefevre60 @JimMarous @insurtechtalk @KirkDBorne @kuriharan @LouisSerge http://
ow.ly/6wjY30sHOzX -
Kirk Borne Adds 2200+ Free Downloadable Resources for X Subscribers
By
–
I added more FREE downloadable resources for my @X Subscribers today. 2200+ resources are now available for subscribers to my @X account. Subscribe for only US$4.99/month #MachineLearning #AI #EdgeAI #DataScience #Python #Mathematics #Statistics #SQL #GenAI #IoT #ML
-
Paired Differences Analysis Reduces Measurement Error in Model Comparison
By
–
Recommendation #4: Analyze paired differences Another way to reduce measurement error is to look at question-level differences between two models, rather than aggregate differences. Paired analysis represents a “free” technique for shrinking standard errors.
-
Power Analysis: Detecting Minimum Effects Between AI Models
By
–
Recommendation #5: Use power analysis Statistical power refers to the ability to detect a hypothetical difference, assuming it exists. Our paper develops formulas for determining the Minimum Detectable Effect between two models, two prompts, or two sets of hyperparameters.
-
Statistical Framework for Model Evaluation in AI
By
–
Beyond these specific recommendations, our work provides an overarching framework for thinking about model evaluations in a statistical way. Read the full paper here:
-
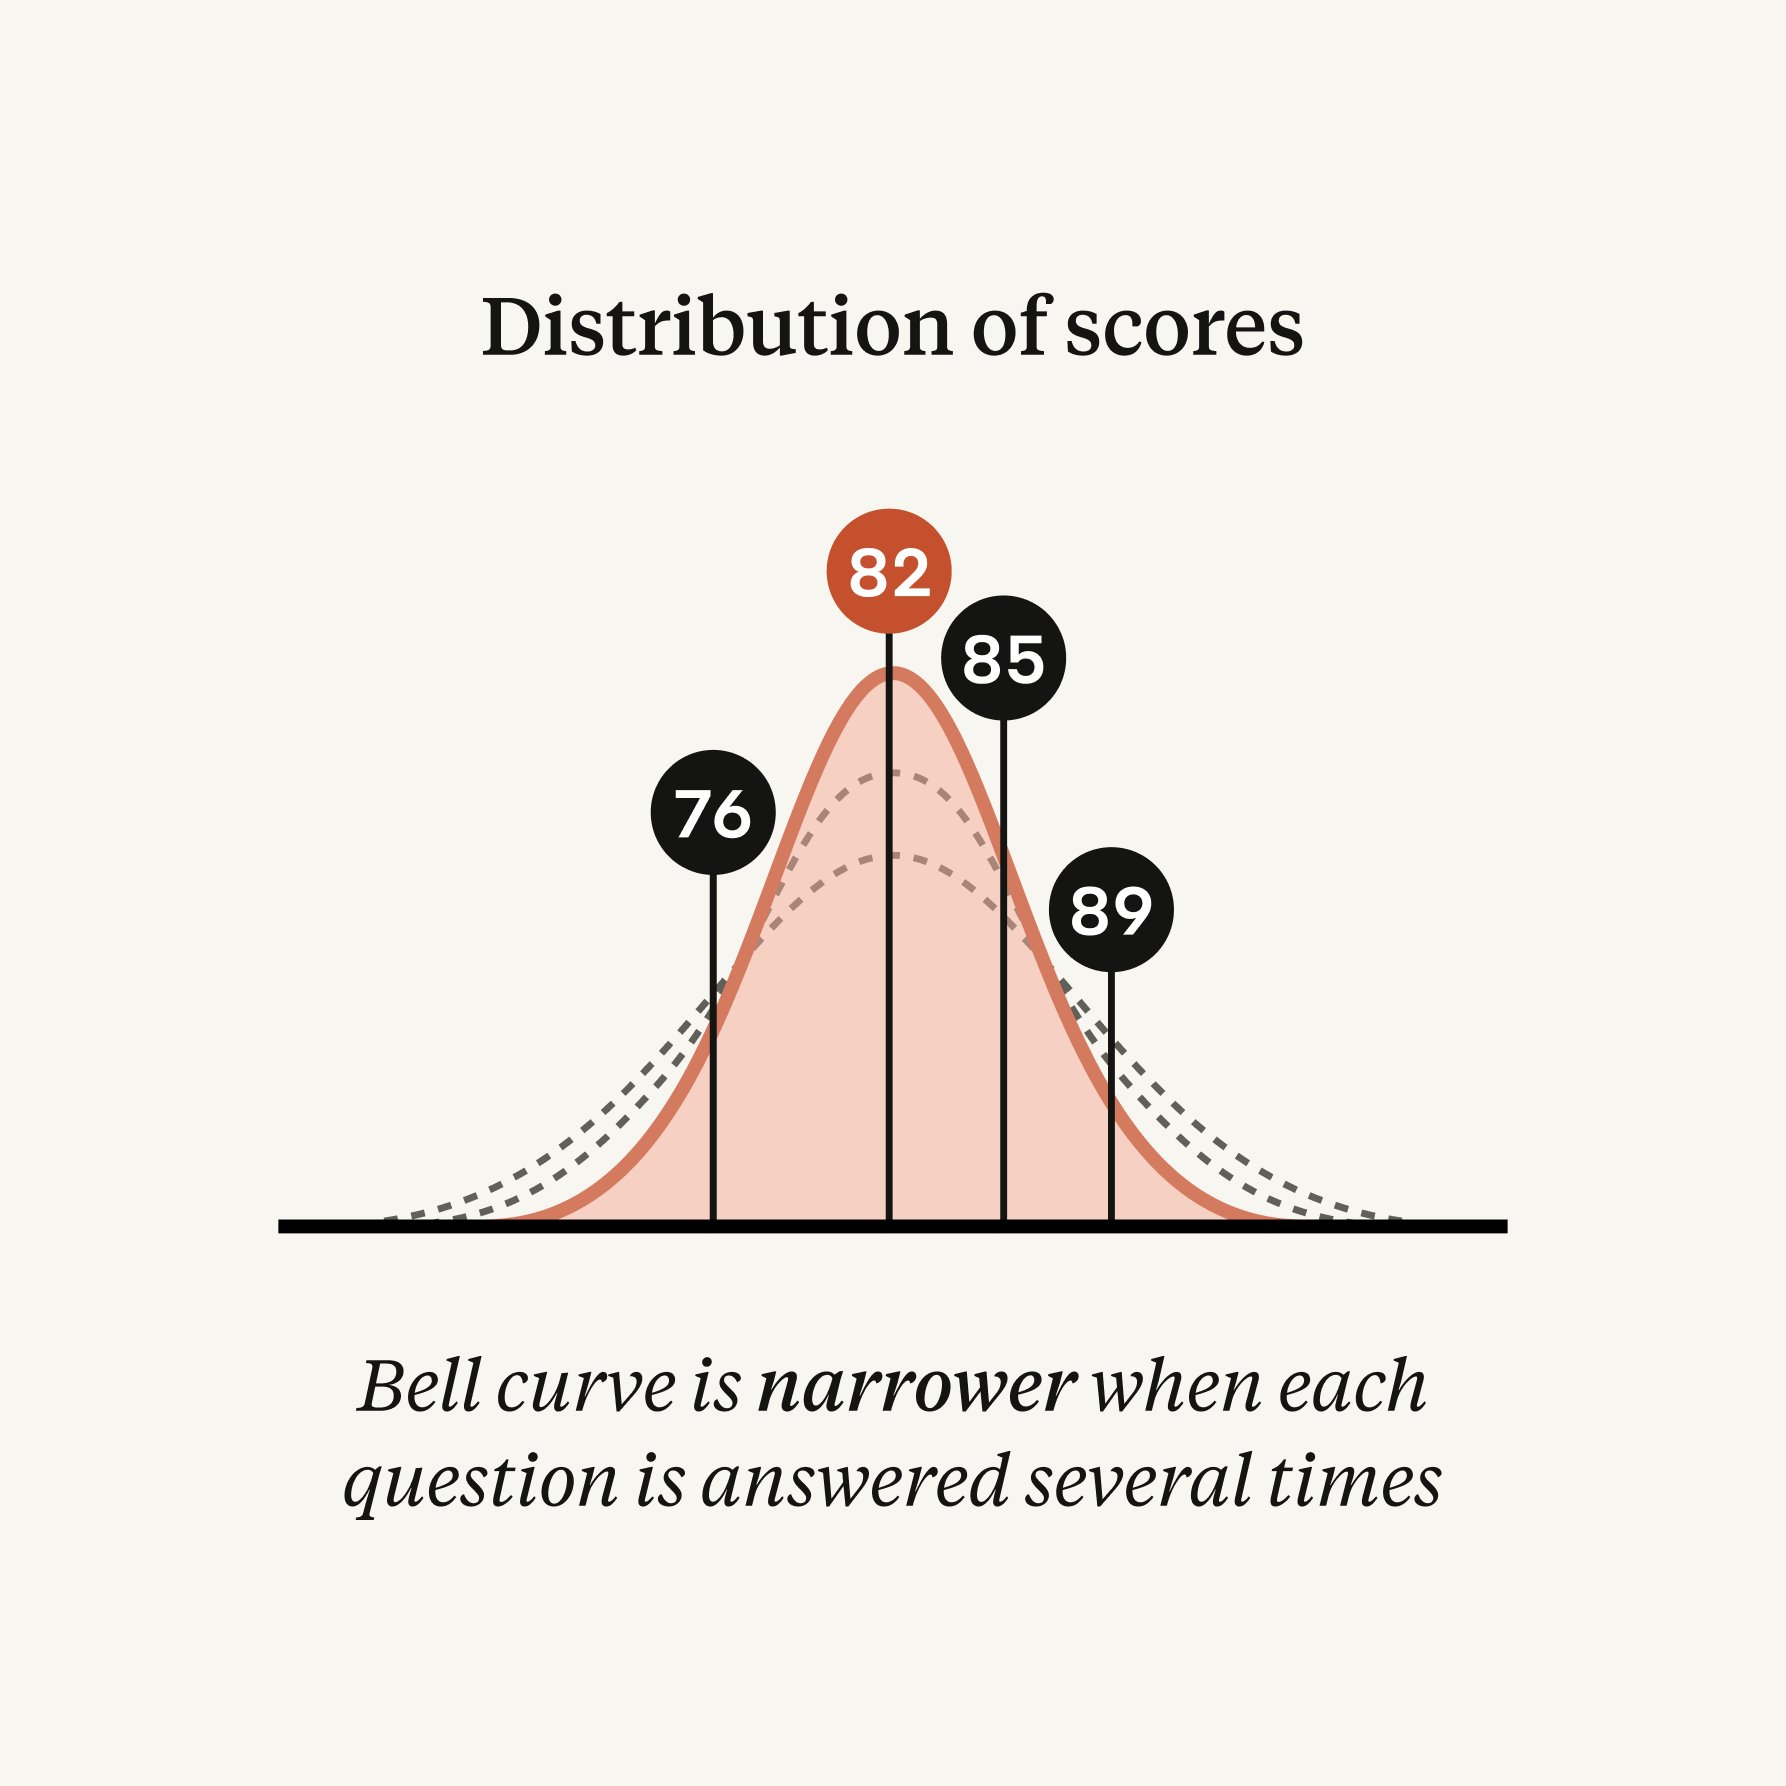
Reducing measurement error in AI confidence intervals through resampling
By
–
Recommendation #3: Reduce variance within questions So far we’ve discussed sampling error. Our paper shows how another kind of error—measurement error—can be reduced by resampling answers from each question several times before calculating overall confidence intervals.
-
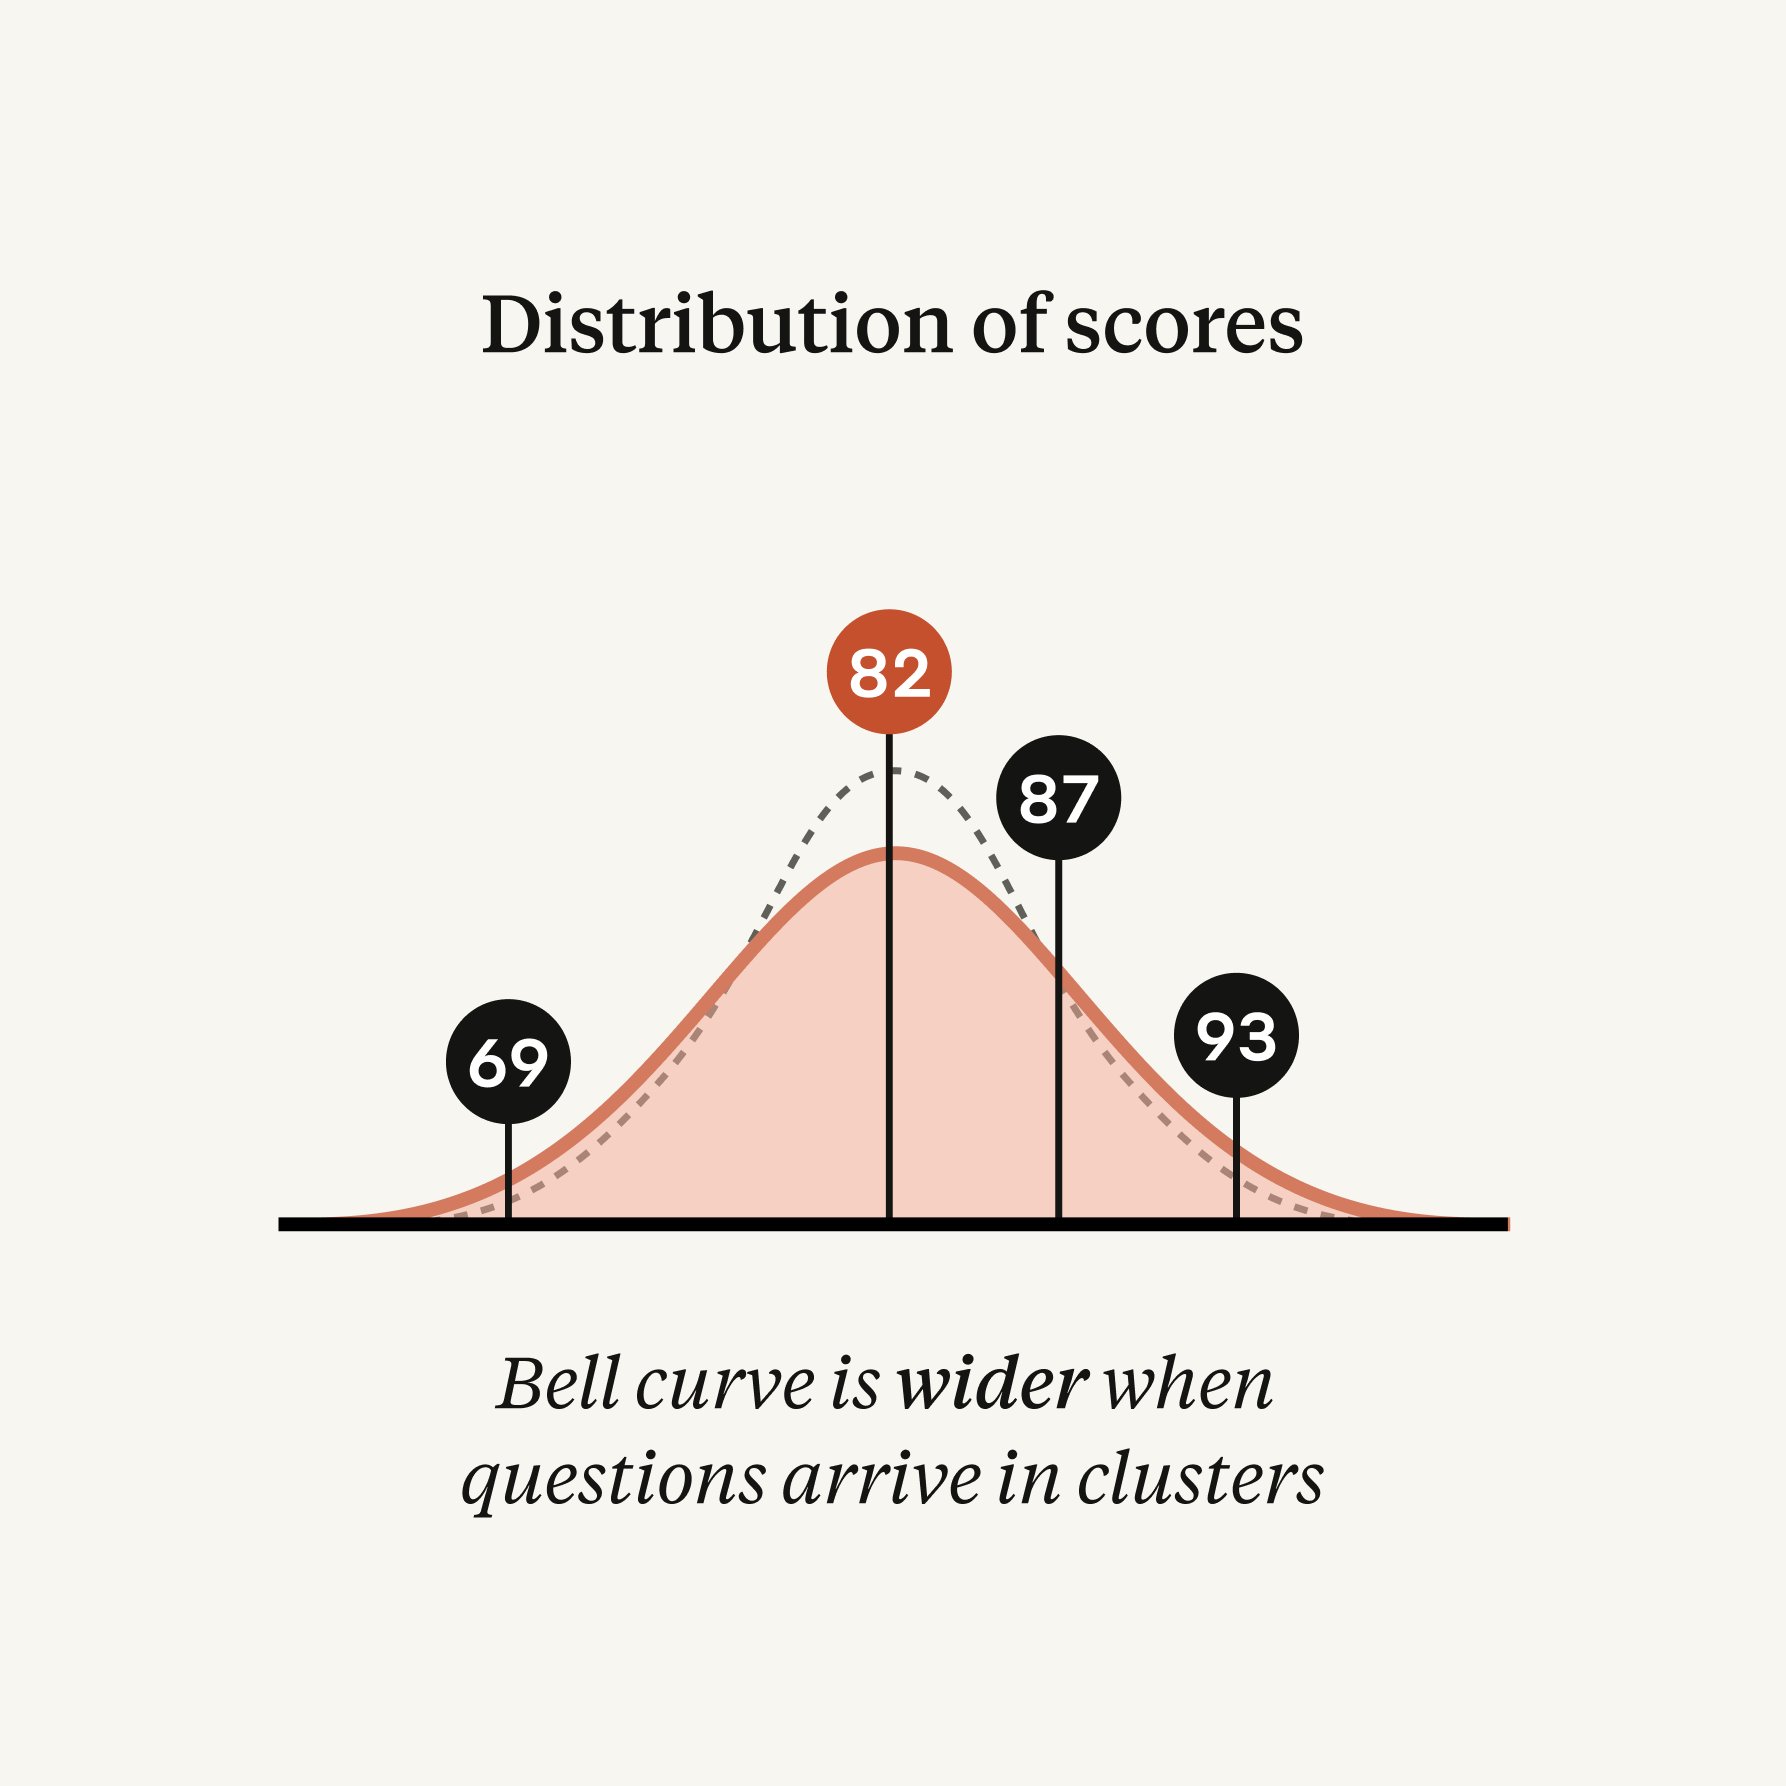
Clustered Standard Errors for AI Evaluation Methodology
By
–
Recommendation #2: Cluster standard errors Many evaluations (esp. reading-comprehension evals) include questions that are clustered together. These question clusters violate an assumption of the Central Limit Theorem—but they are a natural fit for clustered standard errors.
-
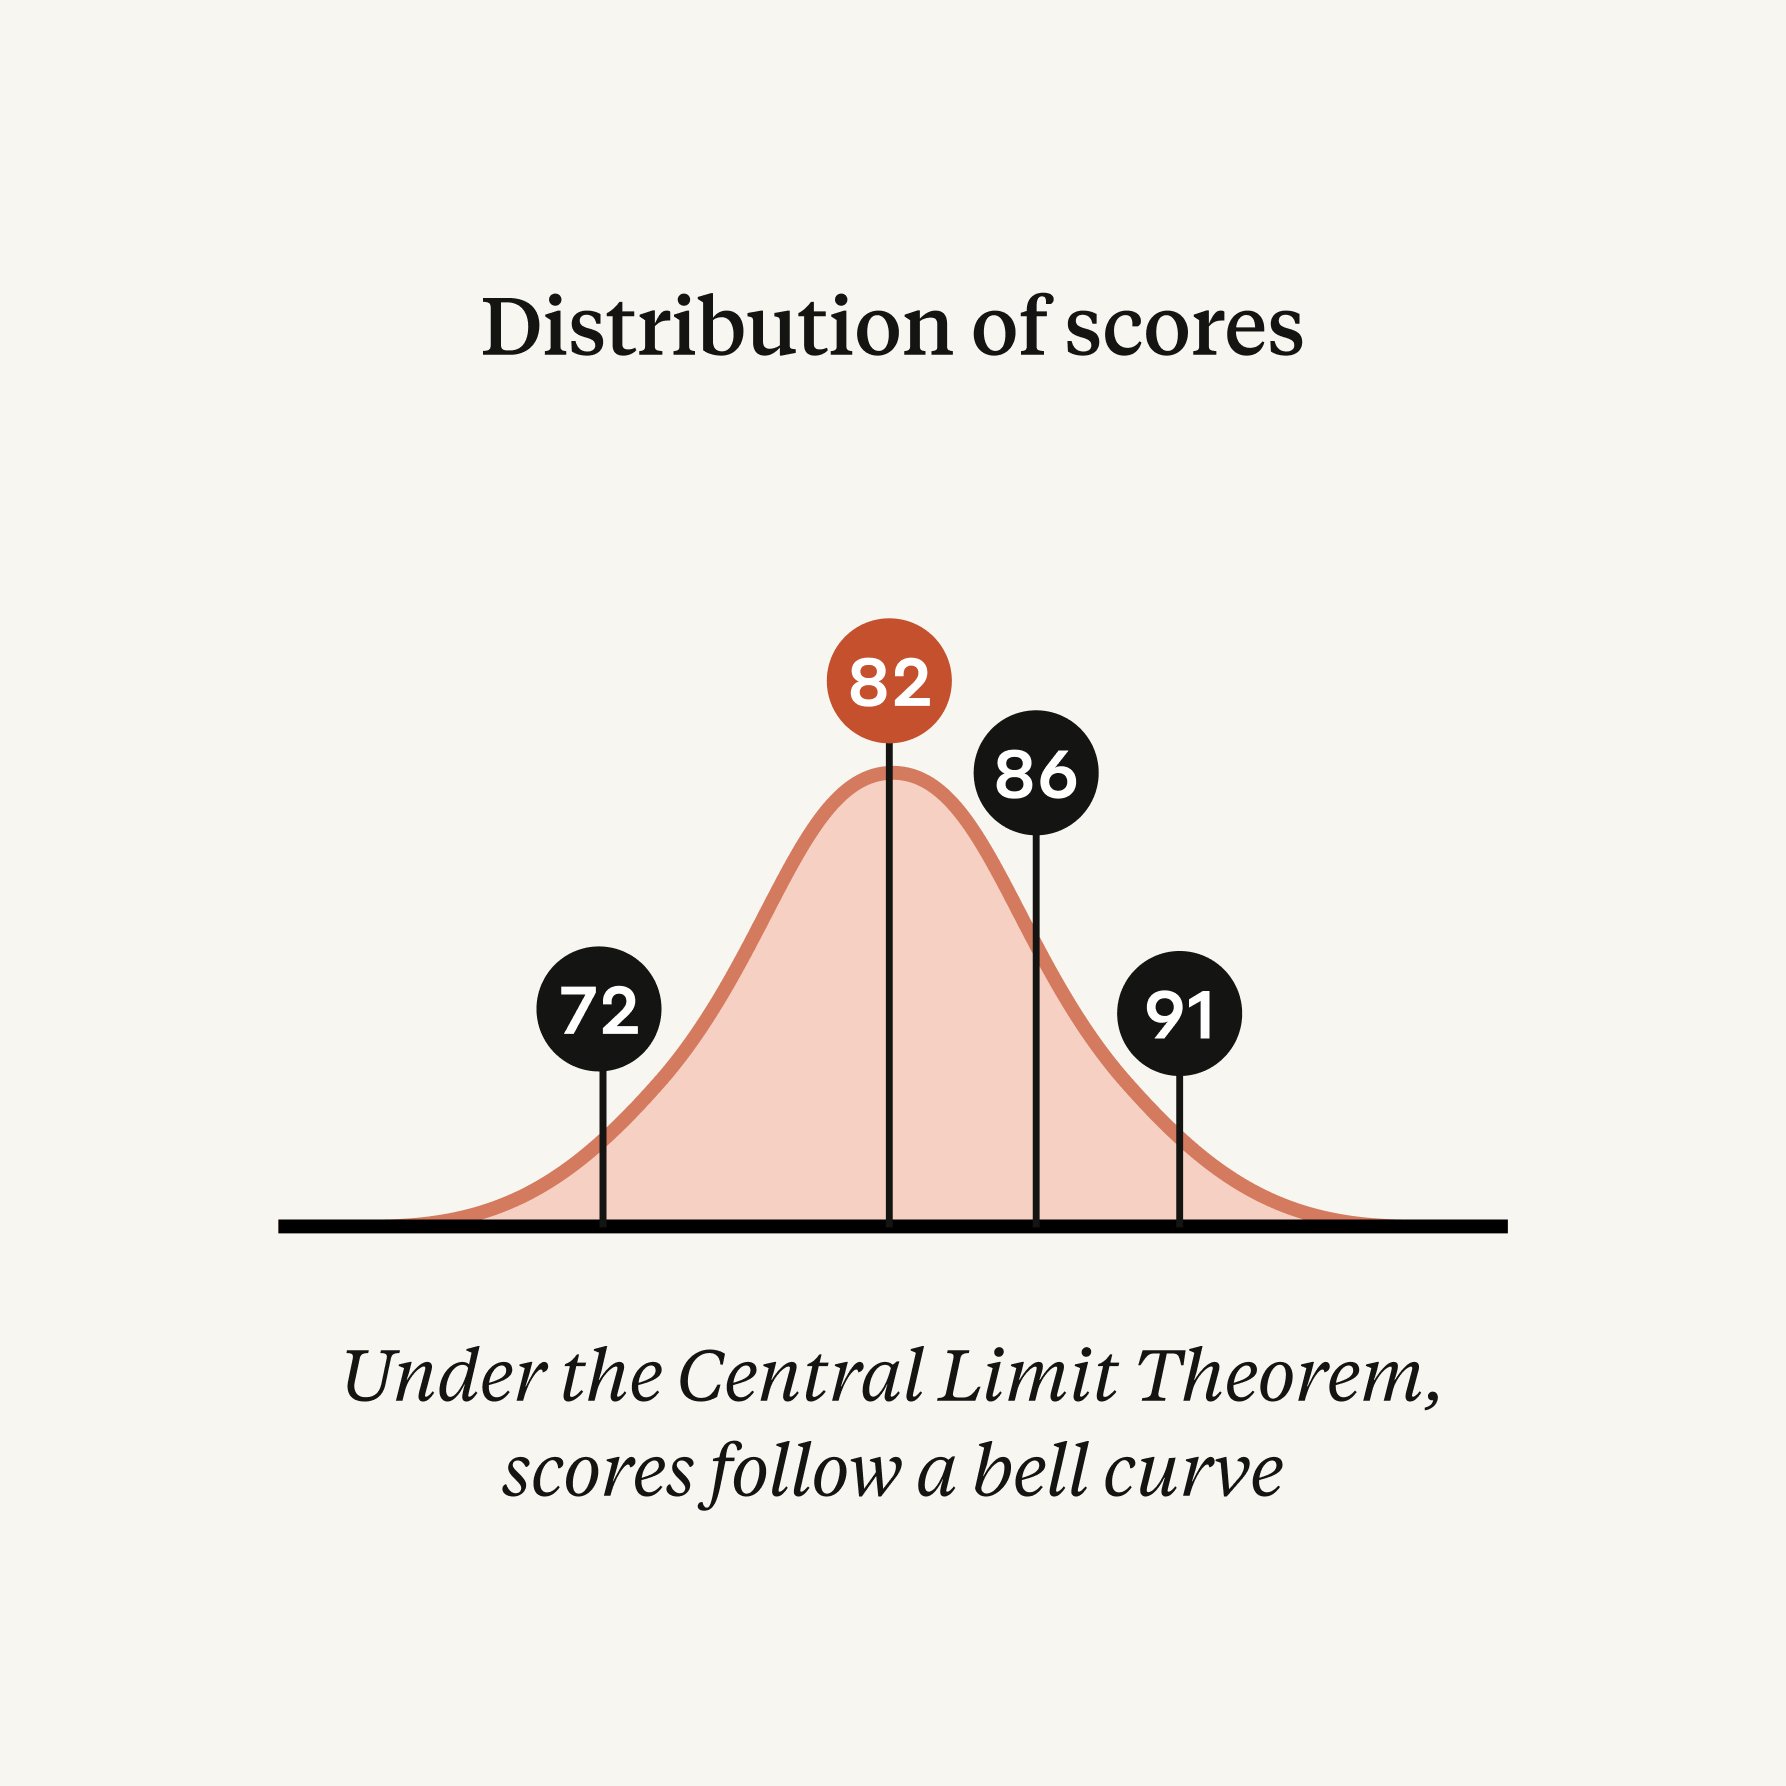
Central Limit Theorem for AI Evaluation Score Reporting
By
–
Recommendation #1: Use the Central Limit Theorem Evaluation scores are usually mean scores across a large number of questions. This is a perfect fit for the Central Limit Theorem. In the paper, we suggest reporting the CLT-based standard errors alongside mean scores.
-
Evaluation Questions Distribution Theory and Core AI Recommendations
By
–
Our key assumption? We imagine that evaluation questions are randomly drawn from an underlying distribution of questions. This assumption unlocks a rich theoretical landscape, from which we derive five core recommendations.