
Gemini Flash is <300 TPS per Google
COMPUTING
-
The role of energy efficiency in future AI infrastructure
By
–
On @CNBC UK with @BenMBoulos, @RodrigoLiang explains why the future of AI infra will be defined by energy, not just raw compute.
— SambaNova (@SambaNovaAI) 19 mai 2026
Here we're focused on delivering high-performance AI infra at a fraction of the power consumption of traditional systems.
Check it out ⤵️ pic.twitter.com/l81tvZY5QxOn @CNBC UK with @BenMBoulos
, @RodrigoLiang explains why the future of AI infra will be defined by energy, not just raw compute. Here we're focused on delivering high-performance AI infra at a fraction of the power consumption of traditional systems. Check it out -

SambaNova RDU architecture for efficient AI dataflow processing
By
–
Want faster, more efficient AI? It starts with dataflow. AI models naturally process data in streams, not rigid instruction cycles. That’s exactly what our RDU architecture was built for. See how it works: https://
sambanova.ai/products/dataf
low-architecture?utm_source=x&utm_medium=organic&utm_campaign=developer
… -
Who controls AI infrastructure and data? Dell AI Factory
By
–
One of the biggest enterprise AI questions right now is simple: who controls the infrastructure and the data? That’s why this matters. Bringing @MistralAI models into the Dell AI Factory with NVIDIA gives enterprises more control over how they train, deploy, and scale AI without
-
MIT’s “Insum” speeds up einsum for sparse datasets
By
–
MIT researchers developed “Insum,” a technique for speeding up computations on datasets replete w/zeros. It rewrites Einstein summation (“einsum”) operations to avoid inefficient handling of zeros, improving memory efficiency & performance: https://
bit.ly/4upJM5s -
Generation speed stable in Pi without super large context
By
–
So far my generation speed is mostly stable in Pi (I haven’t tried super large context yet)
-
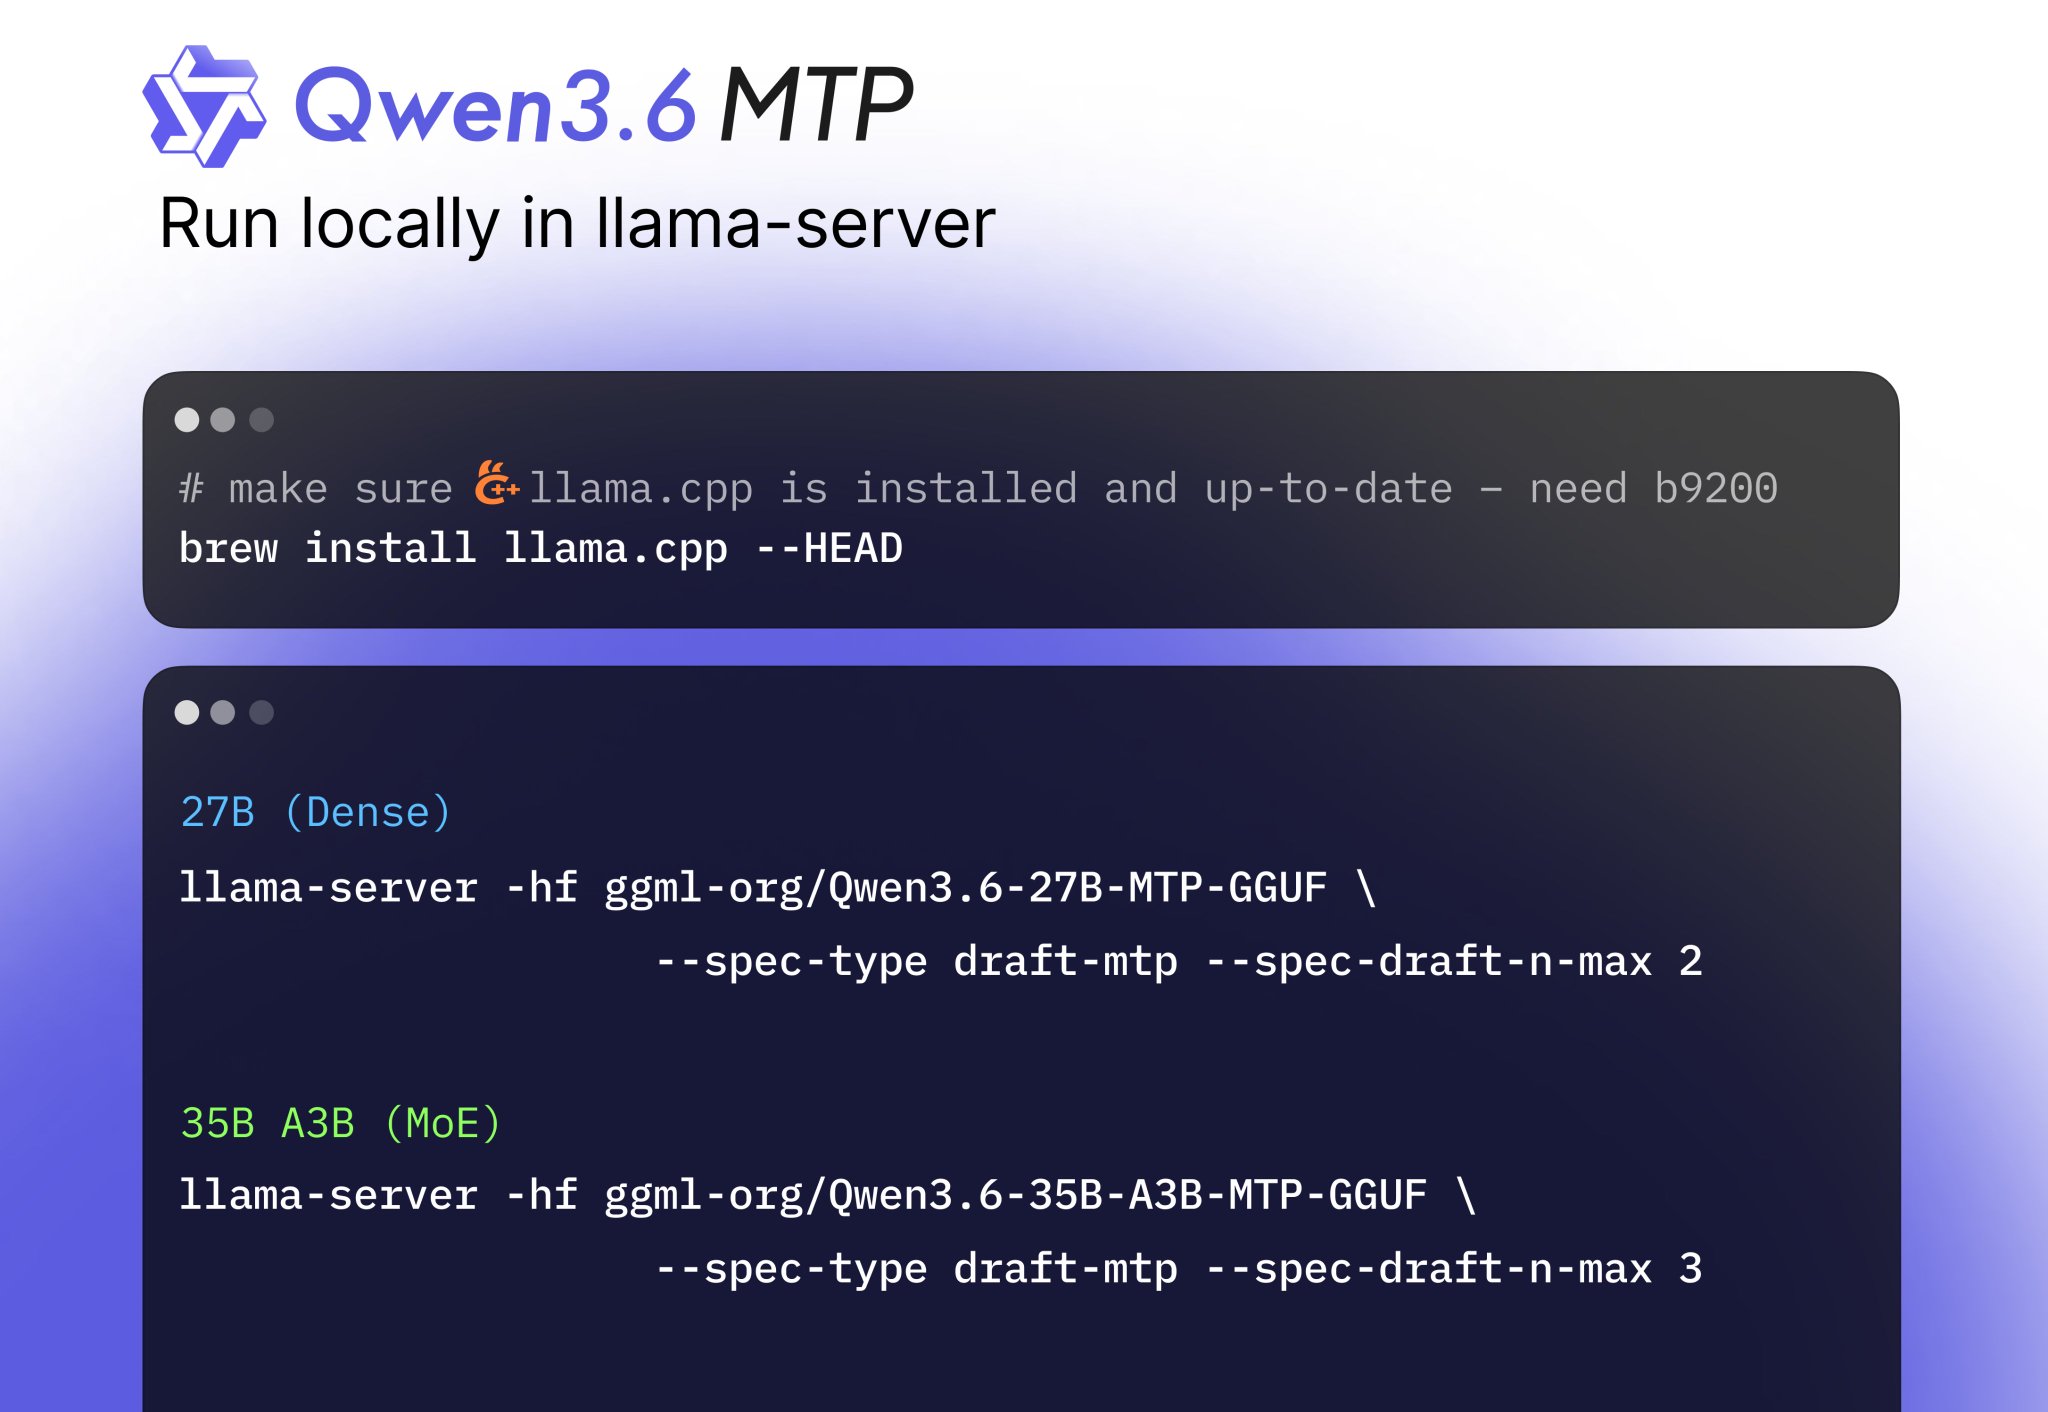
Llama.cpp MTP: 2x generation speed with multi-token prediction
By
–
I've seen some confusion online on how to run llama.cpp with MTP (Multi-token prediction) in the simplest way possible. ICYMI, MTP is a new flavor of speculative decoding built-in to the model itself, that ~2x your tokens per sec for most use cases. 2x generation speed = Truly
-
Scaling AI from 80s to 2000s: Compute Not Enough
By
–
Danny Hillis was scaling up AI with a massively parallel supercomputer in the 80s. In the 90s we had the data mining explosion, a.k.a. scaling up ML. In the 2000s we had the "big data" boom. And each time we noticed that no, compute etc. is not enough – you really need better
-
Inference demand will eventually dwarf training requirements
By
–
inference demand is going to dwarf training within a few years and most forecasts don't reflect that
-
AI ambition easy, execution hard: Dell AI Factory with NVIDIA
By
–
AI ambition is easy. AI execution is the hard part. A lot of companies have ideas, pilots, and demos. Far fewer have the infrastructure, governance, and operational readiness to deploy AI at scale. That’s why the Dell AI Factory with NVIDIA conversation matters: moving