Data Visualization in Python! #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #CloudComputing #Serverless #DataScientist #Linux #Books #Programming #Coding #100DaysofCode https://
geni.us/Nelson-Py
COMPUTING
-
Data Visualization in Python for Analytics and Machine Learning
By
–
-
Machine Learning with R: BigData Analytics and DataScience Tools
By
–
Machine Learning with R. #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #CloudComputing #Serverless #DataScientist #Linux #Books #Programming #Coding #100DaysofCode https://
buff.ly/3Y6vQhn -
Multi-GPU Training Strategies for Deep Learning Models
By
–
By default, deep learning models only utilize a single GPU for training, even if multiple GPUs are available.
— Akshay 🚀 (@akshay_pachaar) 17 août 2025
An ideal way to train models is to distribute the training workload across multiple GPUs.
The graphic depicts four strategies for multi-GPU training👇 pic.twitter.com/rEKkFw3pF3By default, deep learning models only utilize a single GPU for training, even if multiple GPUs are available. An ideal way to train models is to distribute the training workload across multiple GPUs. The graphic depicts four strategies for multi-GPU training
-
Ring Approach for Scalable Model Weight Synchronization Across GPUs
By
–
And there you go! Model weights across GPUs have been synchronized. While the total elements transferred is still the same as we had in the “single-GPU-master” approach, this ring approach is much more scalable since it does not put the entire load on one GPU. Check this
-
Phase 2: Share-only segment transfer across GPUs
By
–
Phase #2) Share-only
— Akshay 🚀 (@akshay_pachaar) 17 août 2025
Now that each GPU has one entire segment, we can transfer these complete segments to all other GPUs.
The process is carried out similarly to what we discussed above, so we won’t go into full detail.
Iteration 1 is shown below👇 pic.twitter.com/7MssxcJfoEPhase #2) Share-only Now that each GPU has one entire segment, we can transfer these complete segments to all other GPUs. The process is carried out similarly to what we discussed above, so we won’t go into full detail. Iteration 1 is shown below
-
GPU Segment Transfer and Distribution Strategy
By
–
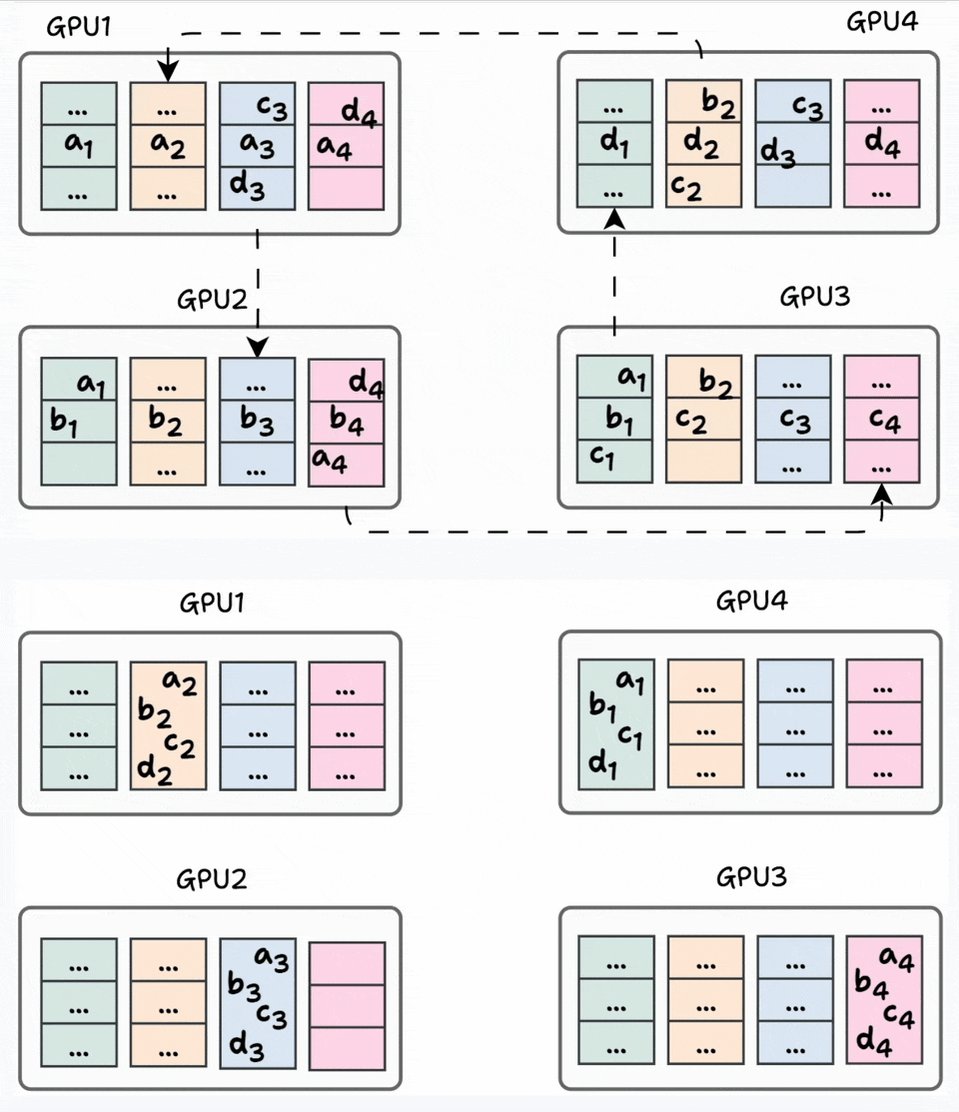
In the final iteration, the following segments are transferred to the next GPU.
— Akshay 🚀 (@akshay_pachaar) 17 août 2025
This leads to a state where every GPU has one entire segment, and we can transfer these complete segments to all other GPUs.
Check this 👇 pic.twitter.com/0EknVEN7IvIn the final iteration, the following segments are transferred to the next GPU. This leads to a state where every GPU has one entire segment, and we can transfer these complete segments to all other GPUs. Check this
-
GPU Ring Communication: Data Segment Distribution Pattern
By
–
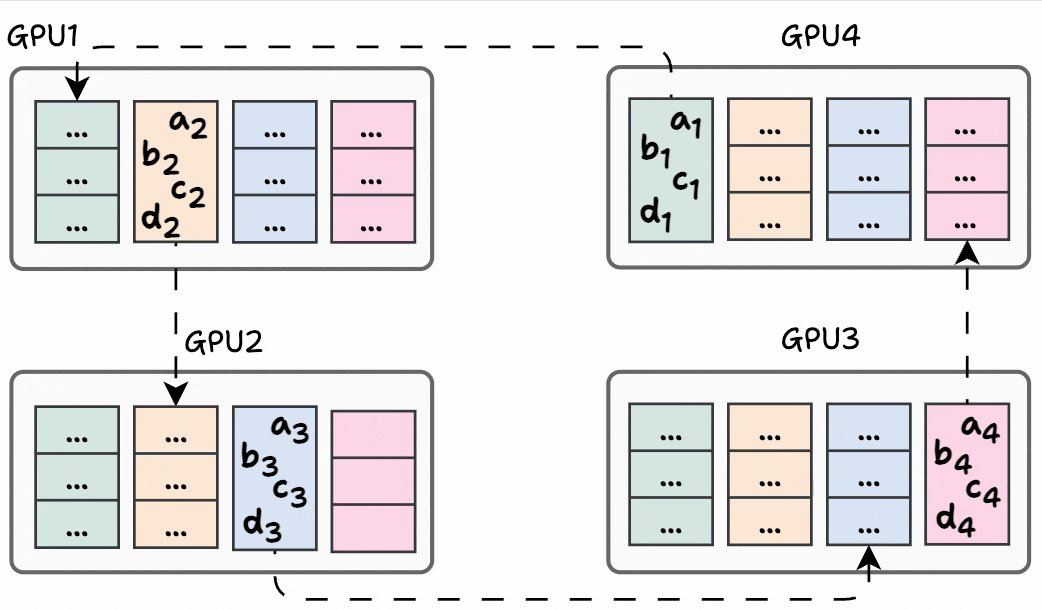
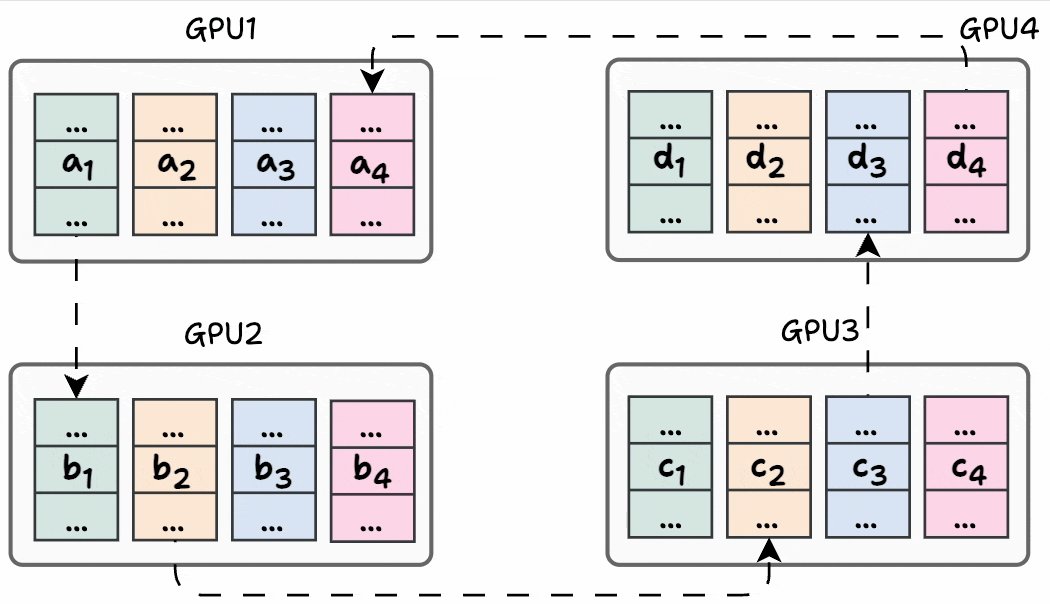
In an iteration, each GPU sends a segment to the next GPU:
— Akshay 🚀 (@akshay_pachaar) 17 août 2025
– GPU1 sends a₁ to GPU2, where it is added to b₁
– GPU2 sends b₂ to GPU3, where it is added to c₂
– GPU3 sends c₃ to GPU4, where it is added to d₃
– GPU4 sends d₄ to GPU1, where it is added to a₄
Check this 👇 pic.twitter.com/aMc08xJwhpIn an iteration, each GPU sends a segment to the next GPU: – GPU1 sends a₁ to GPU2, where it is added to b₁
– GPU2 sends b₂ to GPU3, where it is added to c₂
– GPU3 sends c₃ to GPU4, where it is added to d₃
– GPU4 sends d₄ to GPU1, where it is added to a₄ Check this -

GPU Optimization: Scaling Challenges in Distributed Gradient Communication
By
–
We can optimize this by transferring all elements to one GPU, computing the final value, and sending it back to all other GPUs.
— Akshay 🚀 (@akshay_pachaar) 17 août 2025
This is a significant improvement.
But now a single GPU must receive, compute, and communicate back the gradients, so this does not scale. pic.twitter.com/xgZJ5FdymfWe can optimize this by transferring all elements to one GPU, computing the final value, and sending it back to all other GPUs. This is a significant improvement. But now a single GPU must receive, compute, and communicate back the gradients, so this does not scale.
-
All-Reduce Algorithm: High Bandwidth Costs in Distributed Computing
By
–
Algorithm 1) All-reduce
— Akshay 🚀 (@akshay_pachaar) 17 août 2025
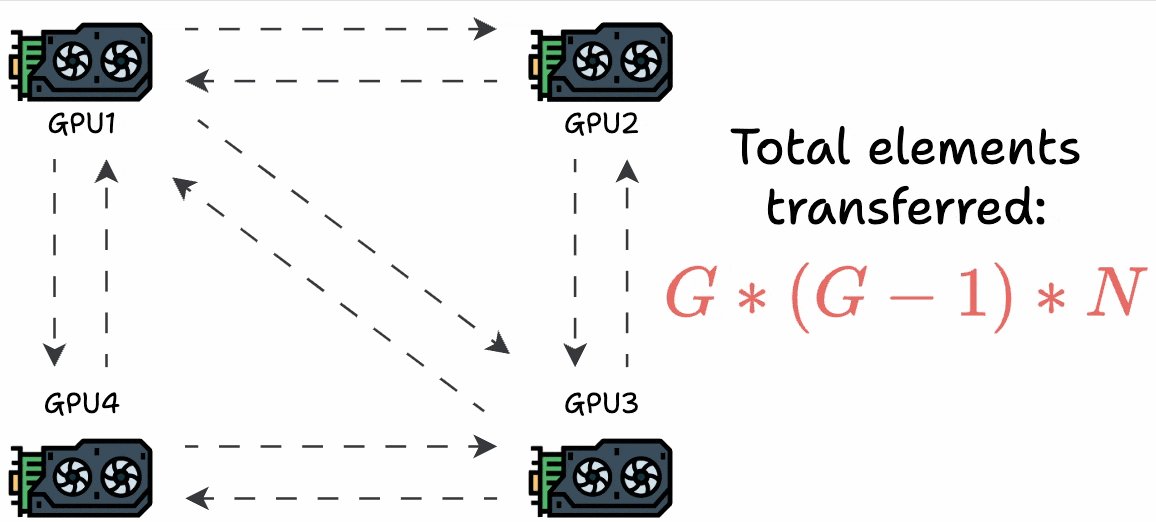
An obvious way is to send the gradients from one device to all other devices to synchronize them.
But this utilizes high bandwidth.
If every GPU has “N” elements and there are “G” GPUs, it results in a total transfer of G*(G-1)*N elements 👇 pic.twitter.com/cxqdc3PszFAlgorithm 1) All-reduce An obvious way is to send the gradients from one device to all other devices to synchronize them. But this utilizes high bandwidth. If every GPU has “N” elements and there are “G” GPUs, it results in a total transfer of G*(G-1)*N elements
-
GPU Gradient Synchronization Strategies in Distributed Training
By
–
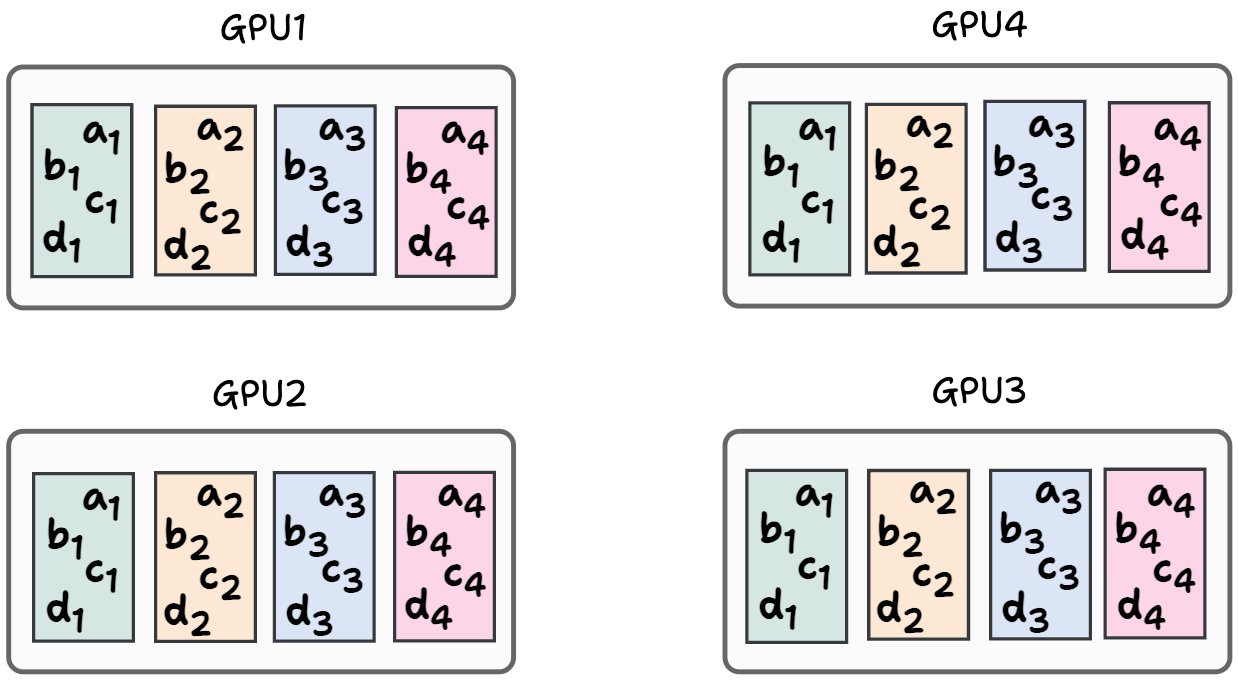
This leads to different gradients across different devices.
— Akshay 🚀 (@akshay_pachaar) 17 août 2025
So, before updating the model parameters on each GPU device, we must communicate the gradients to all other devices to sync them.
Let’s understand 2 common strategies next! pic.twitter.com/cIE4fVR108This leads to different gradients across different devices. So, before updating the model parameters on each GPU device, we must communicate the gradients to all other devices to sync them. Let’s understand 2 common strategies next!