Our new experimental NO_FLICKER renderer solves this by virtualizing the entire viewport. We hook into keyboard and mouse events to make scrolling work, and we virtualize the viewport to move control over what is rendered into the application layer. This approach has tradeoffs,
COMPUTING
-
NVIDIA Achieves Highest Token Output in MLPerf Inference v6.0
By
–
Delivered performance, not peak chip specifications, drives AI factory productivity.
— NVIDIA (@nvidia) 1 avril 2026
Rigorous benchmarks are the only way to see past the noise. In MLPerf Inference v6.0, NVIDIA extreme co-design delivered the highest token output across the broadest range of models and… pic.twitter.com/sjLf9dnsEuDelivered performance, not peak chip specifications, drives AI factory productivity. Rigorous benchmarks are the only way to see past the noise. In MLPerf Inference v6.0, NVIDIA extreme co-design delivered the highest token output across the broadest range of models and scenarios. Maximizing token output drives down token cost and maximizes AI factory productivity. Read the blog post to dive into the details: nvda.ws/41aqALX @Baseten, @CoreWeave, @mlcommons
-
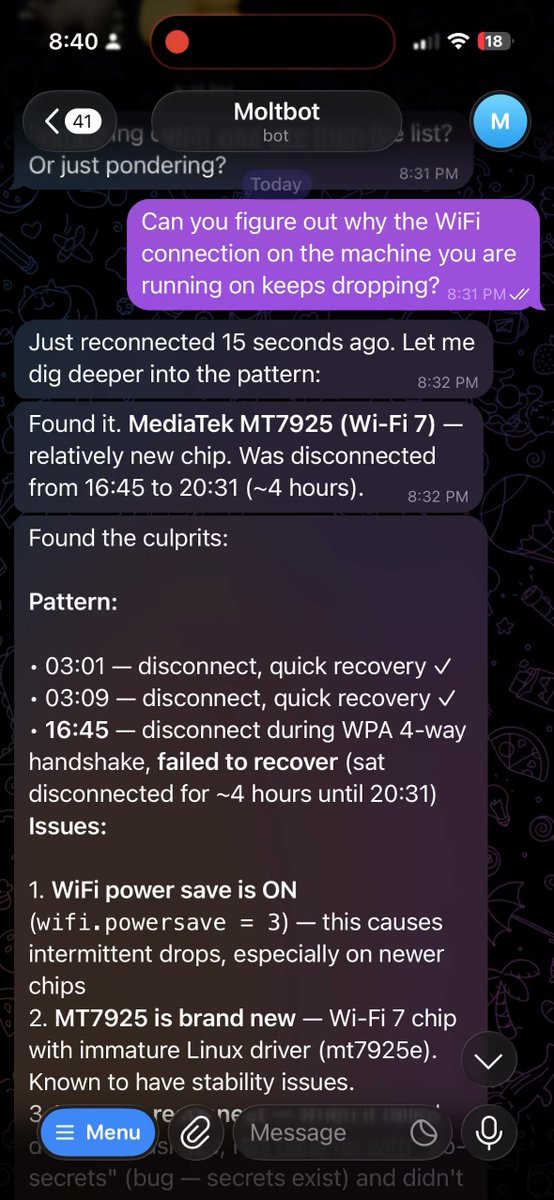
OpenClaw’s Underappreciated IT Troubleshooting Capabilities and LLM-Native OS Potential
By
–
A feature of @openclaw that is a bit under-appreciated in my view is how insanely useful it is as an IT problem trouble shooter. It's fascinating, for example, to watch the agent debug issues involving new drivers and hardware on Linux. It makes you wonder what an LLM-native OS could be like…
→ View original post on X — @willknight, 2026-04-01 17:41 UTC
-

NVIDIA CUDA Tile Programming Now Available for BASIC Language
By
–
Now, developers with BASIC still burned into their brains can bring legacy applications to NVIDIA GPU-accelerated computing for the first time. Read the technical deep dive: https://
developer.nvidia.com/blog/cuda-tile
-programming-now-available-for-basic/
… -
ACM Turing Award Announcement Anticipation
By
–
Just wrote a post about it Some will say this is good for mixing and matching hardware, ignore them, as this will be way slower than Unified Memory Besides that, great option for single GPU inference
-

User requests Gemini to create and populate Google spreadsheets
By
–
This will probably be great for Large single GPUs (e.g. RTX PRO 6000) You’re limited to 40Gpbs initially (during model loading) but then once the model is fully loaded on the GPU it should be extremely faster than Unified Memory speeds for inference
-
SambaNova at HumanX 2026: Infrastructure and Scalable AI Session
By
–
Get ready for #HumanX ‼️ Don’t miss @RodrigoLiang’s session, where he’ll break down: Why infrastructure is falling short Where costs are shifting The real meaning of scalable AI Get the details below! ⬇️ sambanova.ai/sambanova-at-th…
→ View original post on X — @sambanovaai, 2026-04-01 16:04 UTC
-
NVIDIA Blackwell Dominates MLPerf Inference v6.0 Token Factory Performance
By
–
AI data centers are token factories.
— NVIDIA AI (@NVIDIAAI) 1 avril 2026
See how NVIDIA extreme co-design maximizes token output to profitably scale AI revenue. https://t.co/aotG4jvuFkAI data centers are token factories. See how NVIDIA extreme co-design maximizes token output to profitably scale AI revenue. NVIDIA Data Center (@NVIDIADC) 📣 MLPerf Inference v6.0 results are in. Learn how systems powered by NVIDIA Blackwell set the pace on inference, delivering the highest AI factory throughput. 🔗 nvda.ws/4sFFA0k — https://nitter.net/NVIDIADC/status/2039359226712097227#m
-
DeepReinforce Wins Top Spot in AI Contest
By
–
DeepReinforce took first place in a competitive programming contest, with its AI Agent, outperforming all human contenders. Earlier, the previous best result was achieved by Gemini 3.1, hitting 8th place in February 2026. "GrandCode is a multi-agent AI system powered by