Anthropic demonstrates how compute remains the biggest bottleneck. NVIDIA will continue to be the biggest beneficiary for the foreseeable future.
COMPUTING
-
Local AI Models Will Run on Slower Computers Weekly
By
–
That's so true. More locally run models will arrive every week and run on slower and slower computers. And if you think this year is gonna be nuts (it will) next year will be even more so as we start heading into a completely AI-driven 3D ecosystem that we interact with on
-

Keras Kinetic Fine-Tuning Tutorial for LLMs on JAX TPU Stack
By
–
Good tutorial on using Keras Kinetic to fine-tune LLMs on the Keras + JAX + TPU stack! Kuan Hoong (@kuanhoong) Fine-Tuning Gemma 2B on PubMedQA: Building a Medical Q&A Assistant with LoRA, Keras Kinetic, and Cloud TPU kuanhoong.medium.com/fine-tu… #TPUSprint — https://nitter.net/kuanhoong/status/2039827630661517753#m
-
NVIDIA Claims Lowest Cost Per Token in AI Economics
By
–
“NVIDIA’s cost per token is the lowest in the world.” — Jensen Huang, Founder & CEO of NVIDIA
— NVIDIA (@nvidia) 3 avril 2026
Token generation cost is a direct result of architecture excellence and extreme co-design, not just compute cost. Lowest cost per token and highest performance per watt are definitive… pic.twitter.com/7SUVDp84XI“NVIDIA’s cost per token is the lowest in the world.” — Jensen Huang, Founder & CEO of NVIDIA Token generation cost is a direct result of architecture excellence and extreme co-design, not just compute cost. Lowest cost per token and highest performance per watt are definitive measures of AI economics and the key to unlocking maximum profitability and AI revenue. ➡️ nvda.ws/47I03Jx
-
Teams Behind AI Chip Development: From Concept to Tapeout
By
–
It takes a lot of teams to build an AI chip. 🦾
— SambaNova (@SambaNovaAI) 3 avril 2026
During his @TEDTalks, @RodrigoLiang highlights some of the groups that come together to get us from concept to tapeout. 🚀
Watch his full talk 👇https://t.co/19qDsfi9vM pic.twitter.com/WYrinSwOfLIt takes a lot of teams to build an AI chip. 🦾 During his @TEDTalks, @RodrigoLiang highlights some of the groups that come together to get us from concept to tapeout. 🚀 Watch his full talk 👇 bit.ly/41G3vAO
→ View original post on X — @sambanovaai, 2026-04-03 19:00 UTC
-

Keras Kinetic: Run Jobs on TPU/GPU in Cloud
By
–
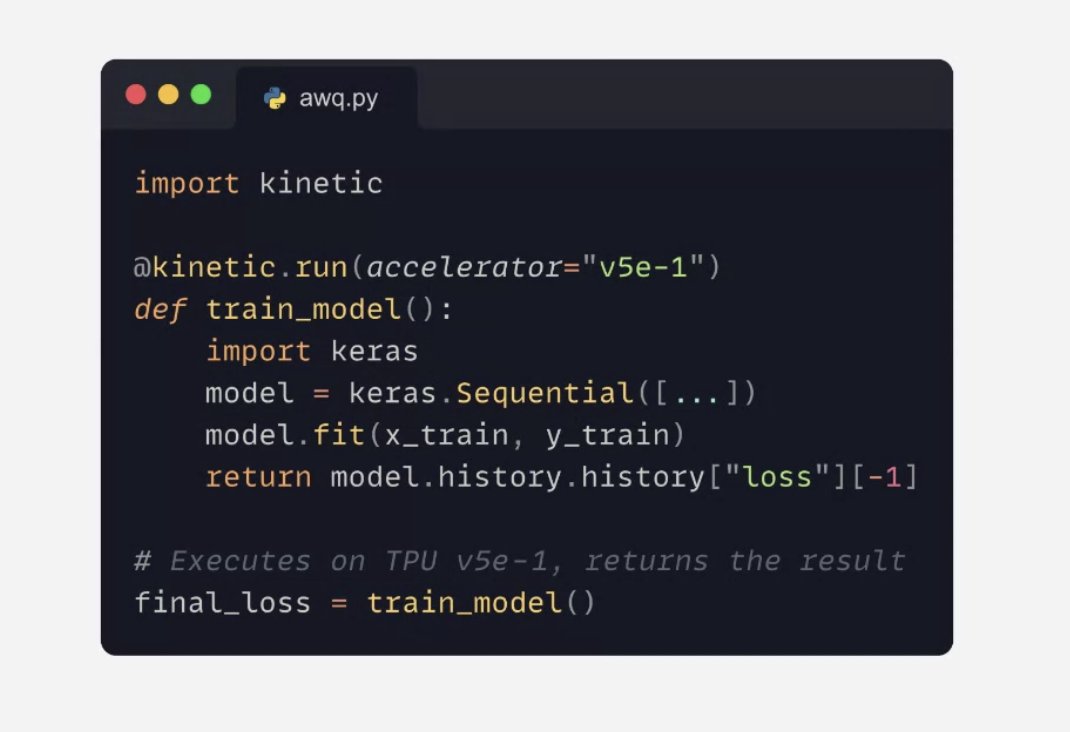
Perhaps the craziest thing that was introduced on the Keras community call today: Keras Kinetic, a new library that lets you run jobs on cloud TPU/GPU via a simple decorator — like Modal but with TPU support. When you call a decorated function, Kinetic handles the entire remote execution pipeline: – Packages your function, local code, and data dependencies – Builds a container with your dependencies via Cloud Build (cached after first build) – Runs the job on a GKE cluster with the requested accelerator (TPU or GPU) – Returns the result to your local machine (logs are streamed in real time, and the function's return value is delivered back as if it ran locally) [Translated from EN to English]
-
Keras Kinetic: New Library for TPU and GPU Job Execution
By
–
A brand new product: the Keras Kinetic library lets you run jobs on TPU (and Google Cloud GPUs) via a simple decorator. Takes care of packaging your code, uploading your dataset, log streaming, winding down jobs…
-
Security Fixes Cause Recent Software Regressions
By
–
Most regressions in the last weeks were from security fixes that overshot.
-
Codex GitHub and Graph API Integration Technical Approach
By
–
dunno how that would work? codex does a mix of gh and direct graph API access.
-
Automatic Protocol Conversion and Data Quality Management Systems
By
–
The system automatically handles protocol conversion, data formatting, and even adds timestamps and quality flags to every data point.