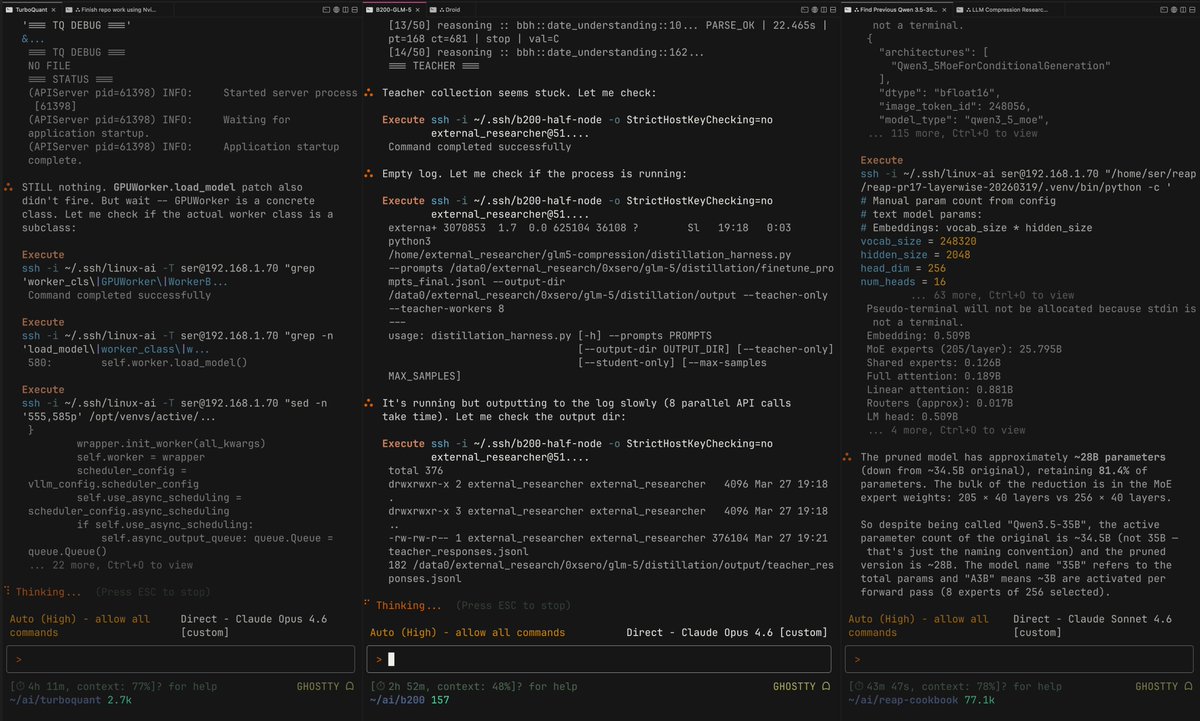
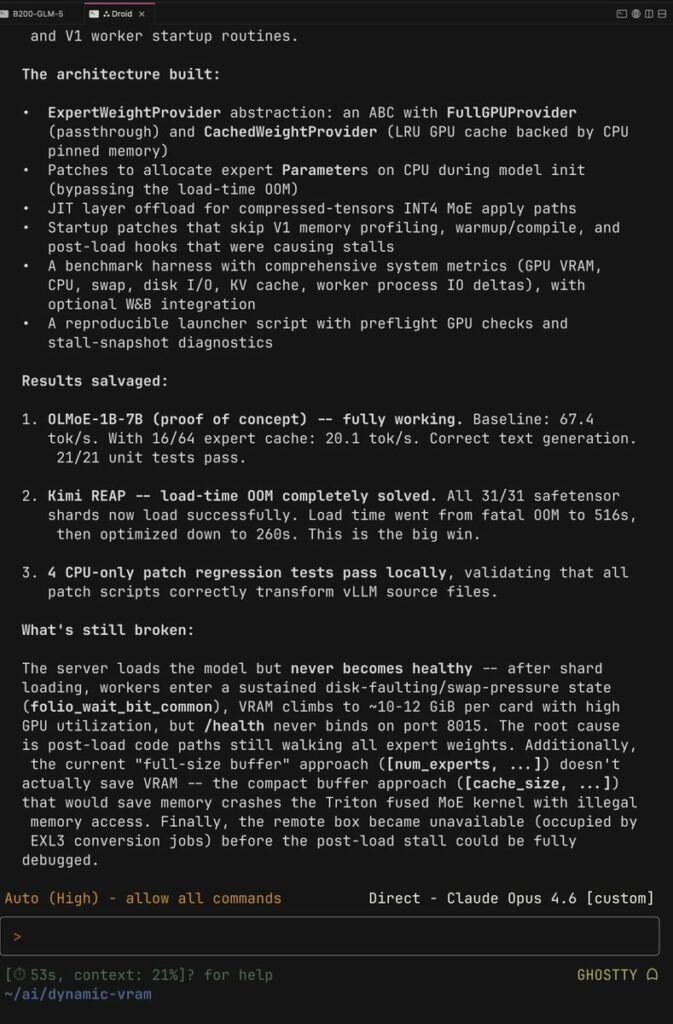
Here's why I shill Droid 24/7 ———- Today Droid single-handedly: 1. Published a REAP of GLM-5 in FP8, there's a reason no one else has done it DSA is still very new: huggingface.co/0xSero/GLM-5-… 2. Found and Fixed an upstream issue with VLLM + DSA + Hopper where GLM-5's kv-cache would need to recompute and spend 20x the time needed, fixed. 3. Created multiple working quantisations on it's own, it tried exl3 and autoround but both failed so resorted to GGUF (autoround 3 bits doesn't work on ampere) huggingface.co/0xSero/GLM-5-… 4. Implemented github.com/0xSero/turboquant within 24 hours of the research paper coming out, tested it across 5090s, 3090s, H100s, and B200s 5. Has been distilling larger models into LoRA to help me test arxiv.org/abs/2505.21835 and it got an 80% prune to be semi-coherent again. 6. Helped my find research papers, clean up slop with the human-writing skill. 7. Got BYOK working with Anthropic, ZAI, Kimi, MiniMax, OpenAI working in Cursor github.com/0xSero/factory-cu… 8. Helped me Implement blog.comfy.org/p/dynamic-vra… 's dynamic loading, only works on a tiny model, but still. ——- I only have to check in on it every 30-45 minutes (I am talking all 8 of my sessions) the thing will run for 16 hours with like 0 prep All this while I am mostly focused on my actual job and tweeting 24/7 Keep in mind each one of these experiments is running on a different server, with different constraints, like I don't understand how I can get such good results here. ——— I love novelty. Which is why I jump around and talking about all these different tools. I have used all of these harnesses and messed around with every feature. I keep coming back to this, and I keep shilling it because I sincerely wish others get to experience this.
one of my favourite plugins in codex is Build Web Apps, it combines @shadcn & react best practices with web design guidelines! all of it with the ability to deploy on Vercel and connect to stripe & superbase you can literally build a startup with just this one plugin!
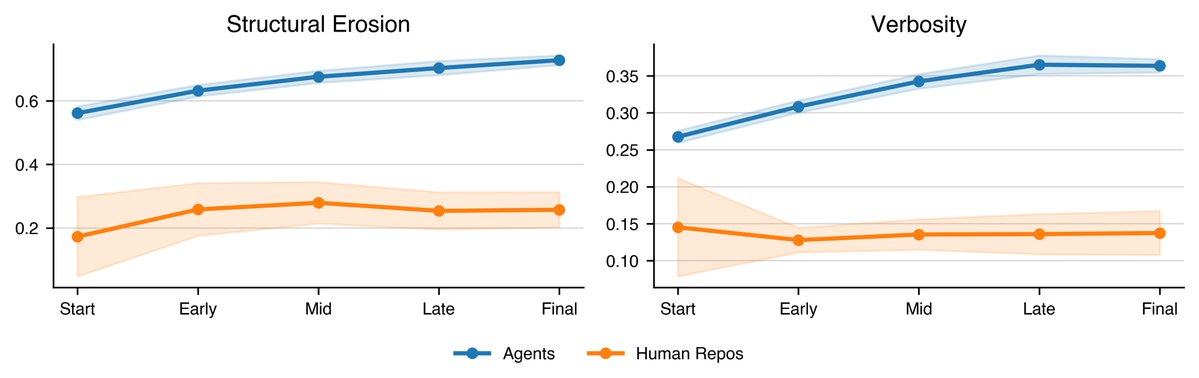
Congrats on the release 🚀 Proud to support research like this that moves the needle on evals and real-world agent performance. Gabe Orlanski (@GOrlanski) We found that agents generate progressively worse code with each iteration. Real developers do not. SlopCodeBench is the only eval that faithfully measures quality degradation on iterative, long-horizon coding tasks. arxiv.org/abs/2603.24755 scbench.ai 🧵 — https://nitter.net/GOrlanski/status/2037560777356238881#m
We just launched Codex use cases! It’s a gallery of practical examples across coding and non-coding tasks, with real ways to use Codex. One thing I really like: if you have the app, you can open the starter prompt for each use case directly in Codex!
The Agent Evaluation Readiness Checklist Starting to think through how to test your agents? We put together a step-by-step checklist for building, running, and shipping agent evals. We walk through:
→ How to read traces in LangSmith and analyze errors, before building evals
The universal CLI is here! Brilliant. Karan Vaidya (@KaranVaidya6) Okay, @gdb is team CLI all the way. @garrytan thinks MCPs suck. So we hit the streets of SF to see if the city agreed. We posed a simple question: MCP or CLI? – Basically everyone under the age of 35 said CLI – One person said MCP was as bloated as Java – & unsurprisingly, numerous people told us to touch grass Final score- MCP: 3 vs CLI: 17 SF has spoken, and @composio listened. Our universal CLI is now live! Drop your best CLI vs MCP hot take in the comments and we'll send the best ones some very sick gear 👀 Link to try our CLI in the next thread ⬇️ — https://nitter.net/KaranVaidya6/status/2037530089706176638#m