Here's another interesting article about how Mythos Preview has been finding the bugs. https://
red.anthropic.com/2026/mythos-pr
eview/
…
CODE
-
Mythos Preview Finds Bugs in AI Systems
By
–
-

Opus 4.6 Security Capabilities Advance Rapidly in Vulnerability Detection
By
–
"Estas capacidades han surgido muy rápidamente. El mes pasado escribimos que -Opus 4.6 es actualmente mucho mejor identificando y corrigiendo vulnerabilidades que explotándolas-. Nuestras evaluaciones internas mostraban que Opus 4.6 tenía, por lo general, una tasa de éxito
-

SWE-1.6 Released: Enhanced Intelligence and UX in Windsurf
By
–
We’re releasing SWE-1.6, our best model in both intelligence & model UX. SWE-1.6 matches our Preview model on SWE-Bench Pro while dramatically improving on various behavioral axes. It’s available today in Windsurf in two modes: free tier (200 tok/s) and fast tier (950 tok/s).
→ View original post on X — @scobleizer, 2026-04-07 18:45 UTC
-

Anthropic Reveals Claude Mythos Benchmarks
By
–

BREAKING : ANTHROPIC ANNOUNCED CYBERSECURITY PROJECT GLASSWING AND MYTHOS BENCHMARKS! Claude Mythos scored 93.9% on SWE Bench Verified and 87.3 on SWE Bench Multilingual! “We do not plan to make Claude Mythos Preview generally available, but our eventual goal is to enable
-
Massive AI Model Jump Signals Accelerating Programming Progress
By
–
Y FUAH! Independientemente de lo costoso del modelo y tal, esta es una evidencia clara de que esto no para, y sobre todo en programación. Habiendo asumido un ritmo rápido pero progresivo con cada nuevo modelo, sorprende ver un salto tan bestia de golpe. Curvas vienen
-

Anthropic Mythos Preview: Major Breakthrough in Programming and Reasoning
By
–
¡ANTHROPIC MYTHOS PREVIEW! Anthropic acaba de publicar lo que serían los primeros benchmarks de su "filtrado" gran próximo modelo, Mythos. La verdad es que en programación y razonamiento el salto es BESTIA!
-
Claude Mythos Breaks SWE-Bench Pro with 77.8% Score
By
–
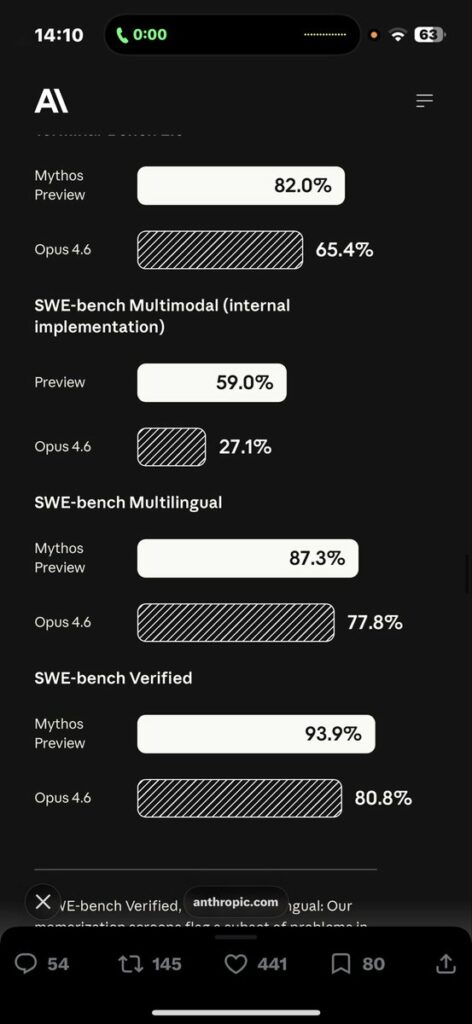
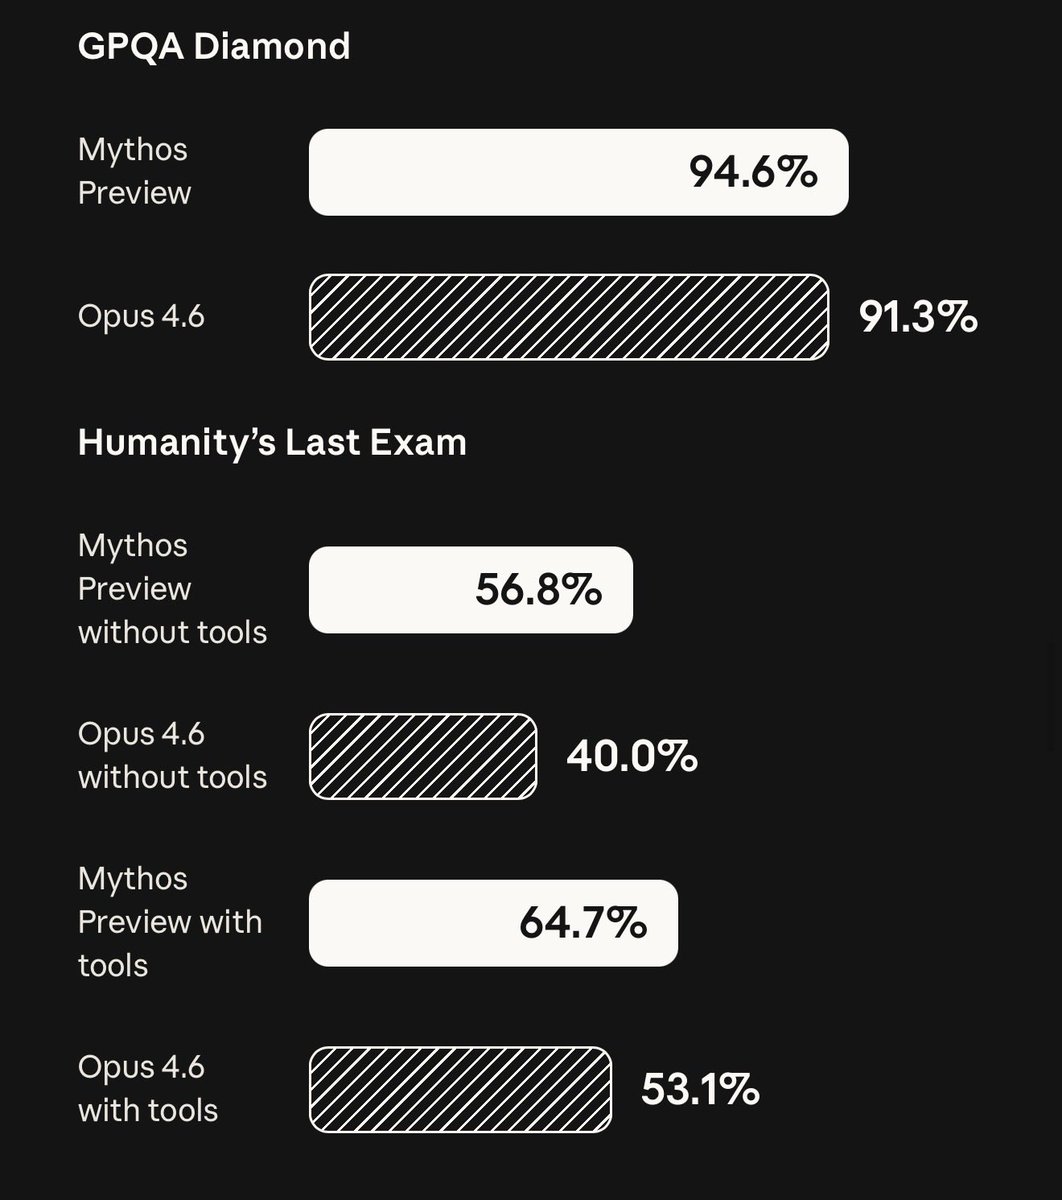
🚨 ANTHROPIC JUST BROKE SWE-BENCH PRO WITH CLAUDE MYTHOS 🚨 Anthropic just dropped the numbers for their unreleased "Claude Mythos Preview" and the coding leap is almost incomprehensible. This model is so powerful at finding exploits that they are keeping it strictly locked down for critical infrastructure partners. Anthropic explicitly stated: "We’ve used Claude Mythos to demonstrate thousands of zero day vulnerabilities." Look at the absolute destruction of these benchmarks compared to Opus 4.6: • SWE-Bench Pro: 77.8% (Destroying Opus 4.6 at 53.4%) • Terminal-Bench 2.0: 82.0% (Up from 65.4%) • SWE-Bench Verified: 93.9% • SWE-Bench Multimodal: 59.0% (More than double Opus 4.6's 27.1%) • Humanity's Last Exam (with tools): 64.7% (Up from 53.1%) • GPQA Diamond: 94.6% A nearly 25-point jump in SWE-Bench Pro in a single generation. And we’re in *checks notes* April..
→ View original post on X — @scobleizer, 2026-04-07 18:20 UTC
-

Claude Mythos: New SWE Model with Impressive Progress
By
–


Claude MYTHOS: SWE verified, 93.9%, about 13% jump compared to Opus 4.6 WTF insane Alex Albert (@alexalbert__) We released Claude Opus 4.6 just two months ago. Today we're sharing some info on our new model, Claude Mythos Preview. — https://nitter.net/alexalbert__/status/2041579938537775160#m [Translated from EN to English]
→ View original post on X — @kimmonismus, 2026-04-07 18:15 UTC
-
Glasswing: First Step Toward Global Software Infrastructure Security
By
–
Glasswing is just the first step: patching and securing the world’s software infrastructure will be the work of months and years, and will require even broader cooperation across AI companies, cyberdefenders, software providers, governments, and more.
-
Mythos Preview Shows Major Step in AI Cyber Capabilities
By
–
We’ve been tracking the increasing cyber capabilities of AI models for years, which arise as part of their general proficiency at coding. But our new model, Mythos Preview, represents a particularly large step up.