Check out these docs for a walkthrough of this new functionality: https://
langchain.readthedocs.io/en/latest/exam
ples/prompts/llm_functionality.html
… Check out these docs for an overview of serialization: https://
langchain.readthedocs.io/en/latest/exam
ples/prompts/llm_serialization.html
… And of course, check out the GitHub if you want to flag an issue or open a PR! https://
github.com/hwchase17/lang
chain
…
CODE
-
LangChain Documentation Updates: New Functionality and Serialization
By
–
-
LLM Interface Enhancement: Extended Output with Top Results and Token Counts
By
–
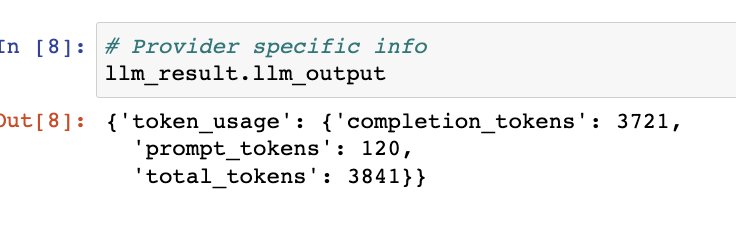
Returning extra information Previously, the LLM only returned the most likely string Now there is a new interface to return more information: the top n strings for each input, as well as LLM specific information (h/t @0xAwill for adding the token counts you see below)
-
New abstraction enables returning generation metadata like logprobs
By
–
This abstraction also opens up the door to returning more information about each generation For example, the logprobs associated with a generation (something I know @alexgraveley would love)
-
Map-Reduce Chain Speed Optimization Through LLM Call Batching
By
–
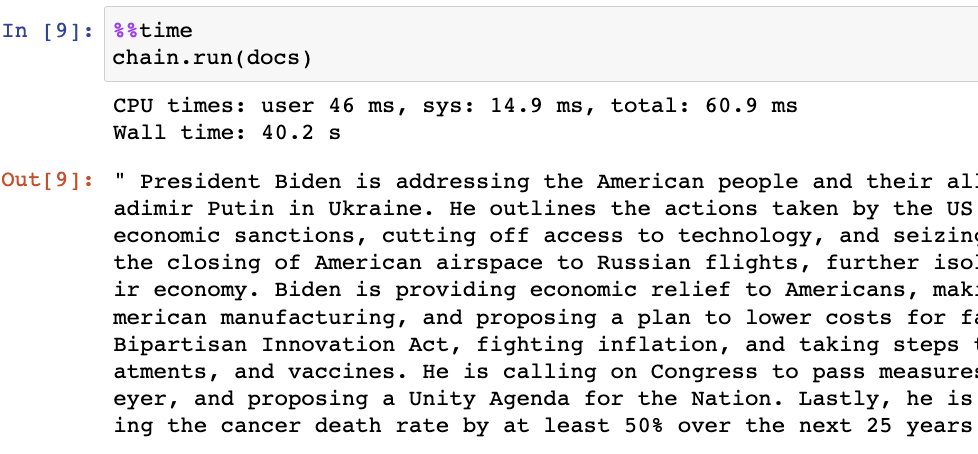
This now means that certain chains see a MASSIVE speed up. For example, the map-reduce chain can batch the map calls to the LLM, resulting in a ~75% drop in time
-
LangChain Introduces LLM Input Batch Processing
By
–
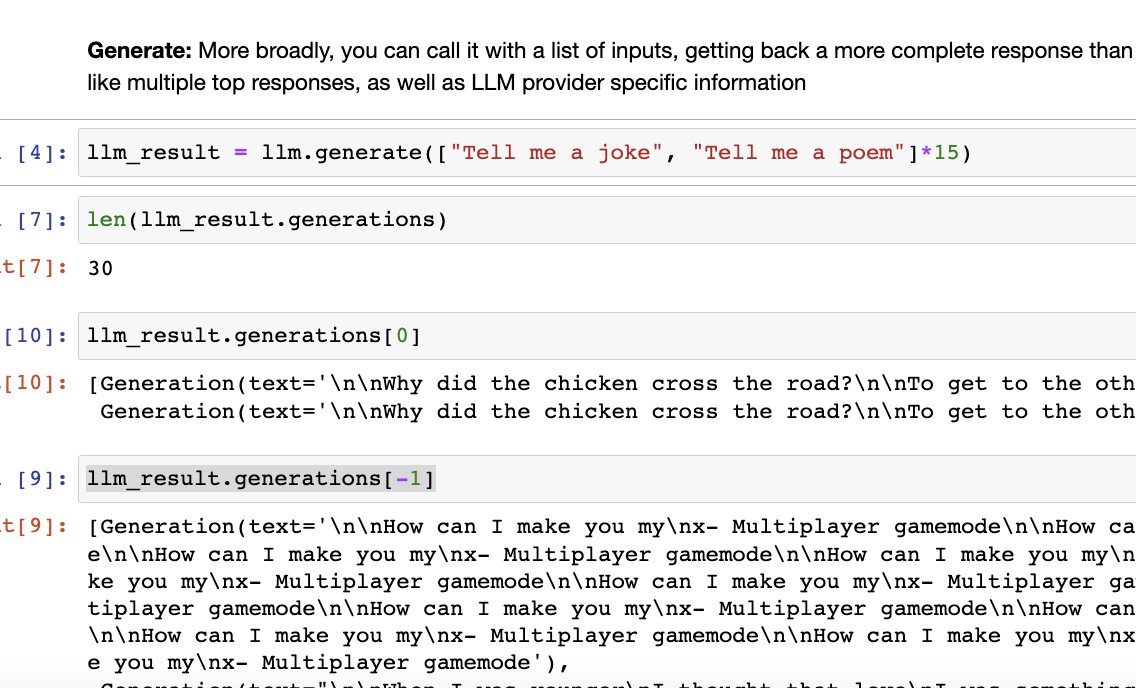
Batching of inputs Previously, the only interface for calling an LLM was to pass in a single string. With big motivation from @thepromptking, there is now an interface that takes in and returns results for multiple inputs
-
Calculating Token Count for LLM Context Windows
By
–
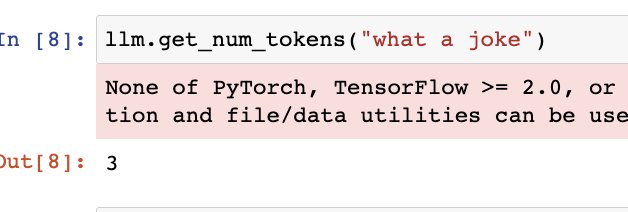
Estimating the number of tokens Each model has a context window with a certain length, where you can only pass in strings of up to a certain length There now exists a method on each LLM class to calculate the number of tokens for a string in that model
-
GPT2 Tokenizer as Default Method with Overridable Class
By
–
The default method for calculating this uses @huggingface
's GPT2 tokenizer But since its a class method, if different models use different tokenizers this can be overwritten h/t @brucehammer for implementing the logic, and then Zac on Discord for suggesting this interface -
LangChain LLM Interface Improvements and New Features
By
–
There's been some additions to the LLM interface over the past few days: Method to estimate # of tokens, batching of inputs, returning extra information, serialization of LLM configurations @AkashSamant4 @thepromptking @0xAwill Let's walk through these improvements:
-
YOLOR Outperforms YOLOv7 on COCO Test-Dev Dataset
By
–
Did you know YOLOR performs better on the Coco test-dev set than YOLOv7?
— Satya Mallick (@LearnOpenCV) 14 décembre 2022
YOLOR takes inspiration from how humans combine explicit & implicit knowledge to process previously unseen data.
▶️Check out our blog post to learn more.https://t.co/SUXpFNwMvj#yolor #computervision #ai pic.twitter.com/GcIyHlqr02Did you know YOLOR performs better on the Coco test-dev set than YOLOv7?
YOLOR takes inspiration from how humans combine explicit & implicit knowledge to process previously unseen data. Check out our blog post to learn more. https://
learnopencv.com/yolor-paper-ex
planation-inference-an-in-depth-analysis/
… #yolor #computervision #ai -
GPT-3 code-davinci-002 is the most capable model
By
–
“Wait, code-davinci-002 is the most capable GPT-3 model for natural language as well as code, on top of having a context window twice as big??” “Always has been.”