I know some companies like to prototype in PyTorch then rewrite in JAX for performance. Did you know you could just… prototype in Keras + PyTorch, then switch to JAX *while keeping all of your model code*? At most you'll have to rewrite the train_step or the training loop.
CODE
-
Essential Keras Tips for Debugging and Prototyping with Different Backends
By
–
Essential Keras tips: 1. Debug/prototype with eager execution. You can prototype with the PyTorch backend, or even with the NumPy backend if you're only looking at a layer or a forward pass (the NumPy doesn't support gradients/training). With JAX or TF, make sure to use
-
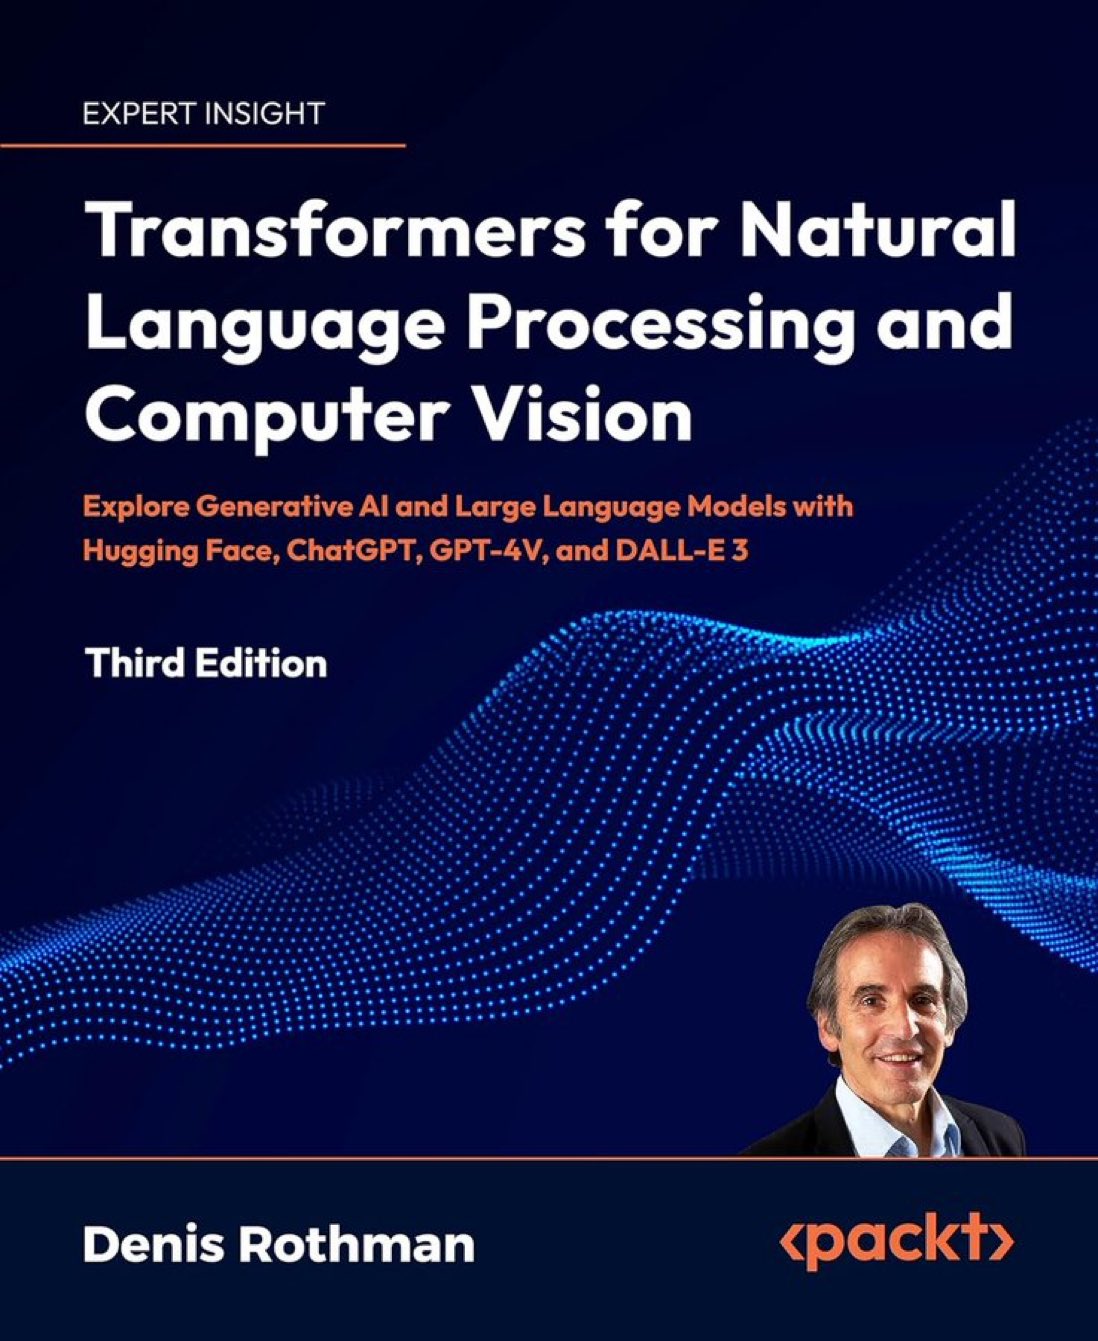
Kirk Borne Receives Updated 3rd Edition on Transformers and Generative AI
By
–
WOW! I just received (minutes ago) my copy of the updated 3rd Edition of this book: http://
amzn.to/3TkBknI
"Transformers for Natural Language Processing and Computer Vision: Explore #GenerativeAI and Large Language Models #LLMs with Hugging Face, ChatGPT, GPT-4V, and DALL-E 3" -
Testing AI Model Performance with Real Out-of-Distribution Data
By
–
Can you run a needle in a haystack test with this! Interested in how those do with real data that's definitely not in the training set.
-
Language Model Inversion: New Research and Open Source Tools
By
–
paper (language model inversion) http://
arxiv.org/abs/2311.13647 github (open_logprobs) -

OpenAI API Changes Due to Language Model Inversion Research
By
–
achievement unlocked: OpenAI changes its API because of your research you can still get logits from GPT-4 by using the argmax bisection method detailed in Language Model Inversion. it's pretty expensive, though we should have stockpiled logits while we had the chance…
-
LangGraph Quality-of-Life Improvements for Agent Development
By
–
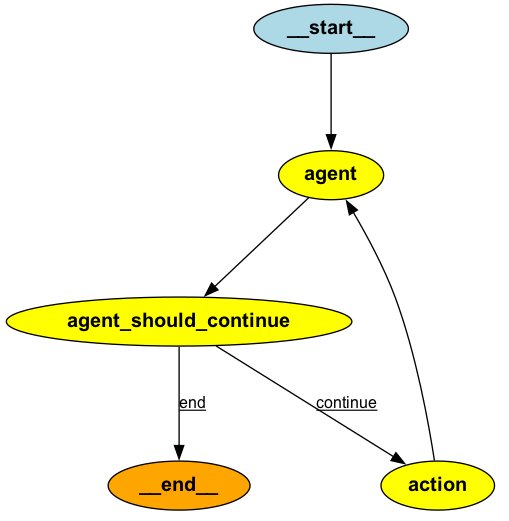
LangGraph Updates 3 big quality-of-life improvements to LangGraph over the past few weeks: Automatic visualization of the created graph
Conditional entry points
Prebuilt Tool Calling Executor What do these mean? Automatic rendering of the created graph This was a -
New Extraction Guides for Structured Data from Unstructured Text
By
–
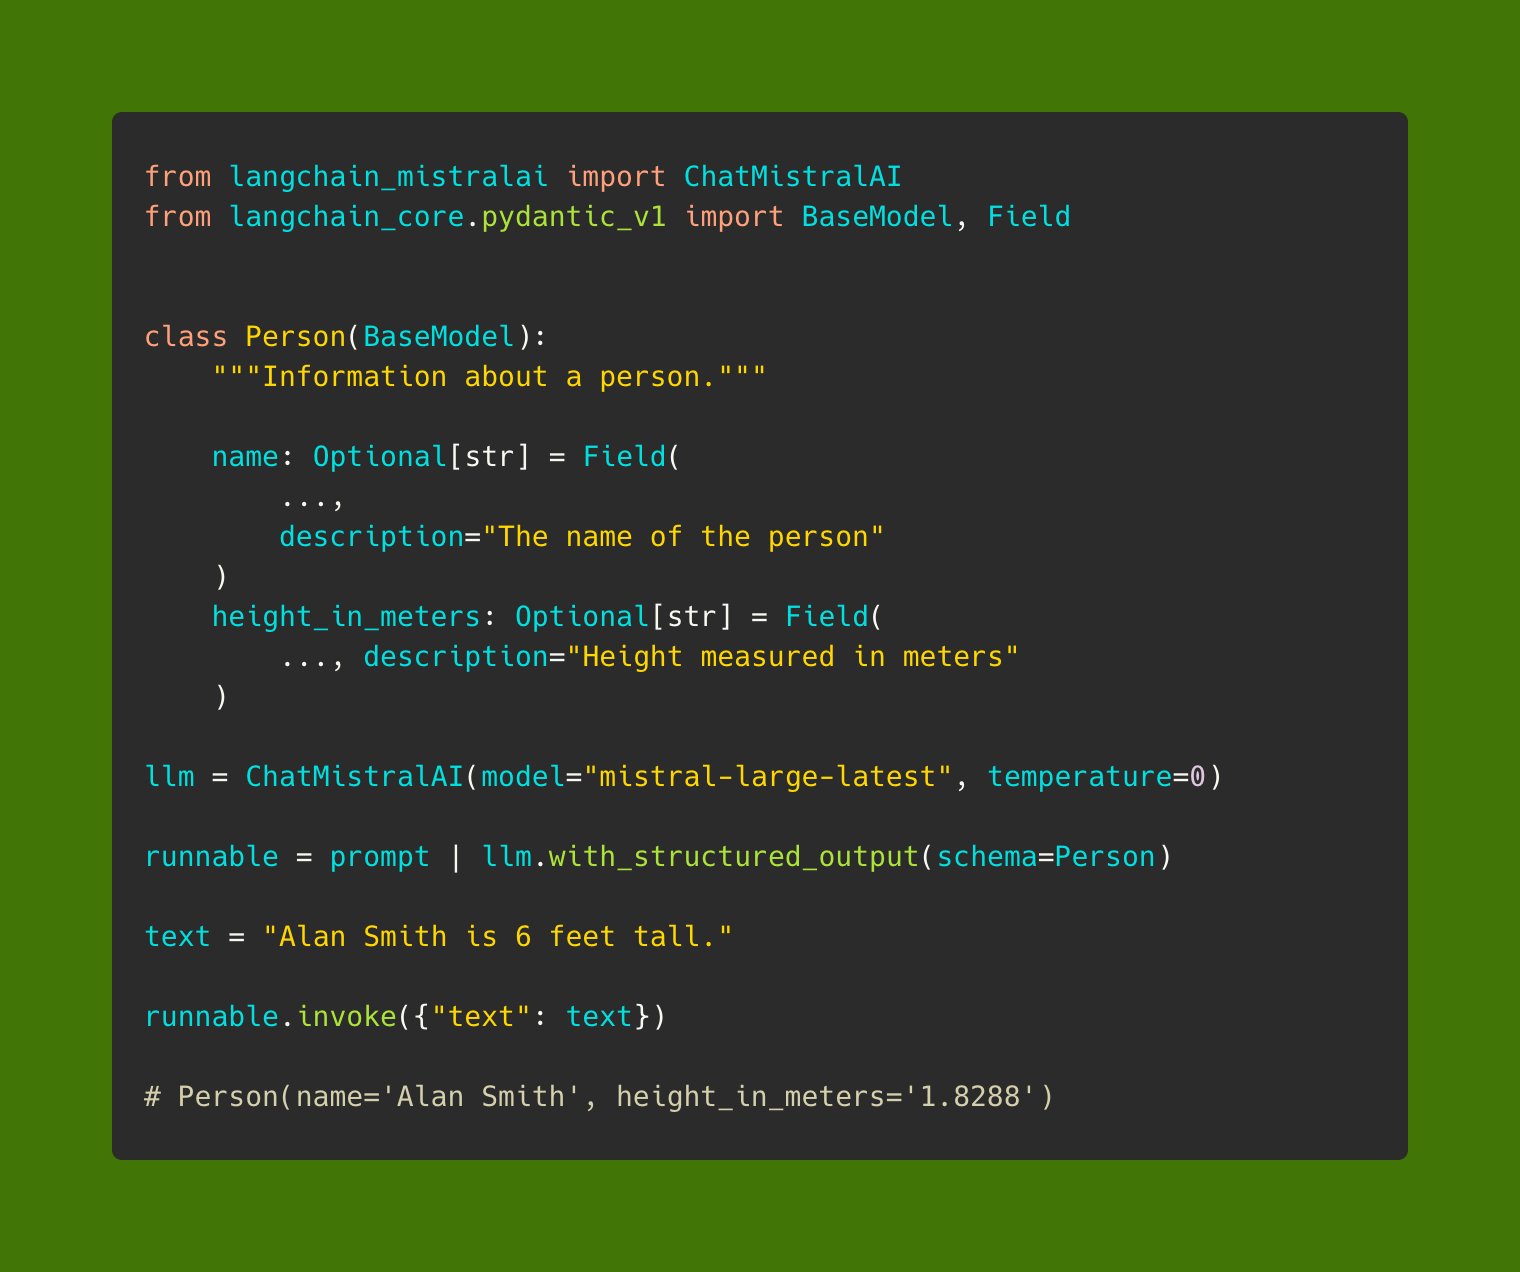
New extraction guides Reliably extracting structured data from unstructured text is one of the killer use-cases for LLMs. It's a fantastic way to bridge the gap between LLMs and traditional APIs and systems. We've put a lot of work on this lately, including an open
-
Fine-tuning LLMs: Democratizing AI Performance with Smaugh
By
–
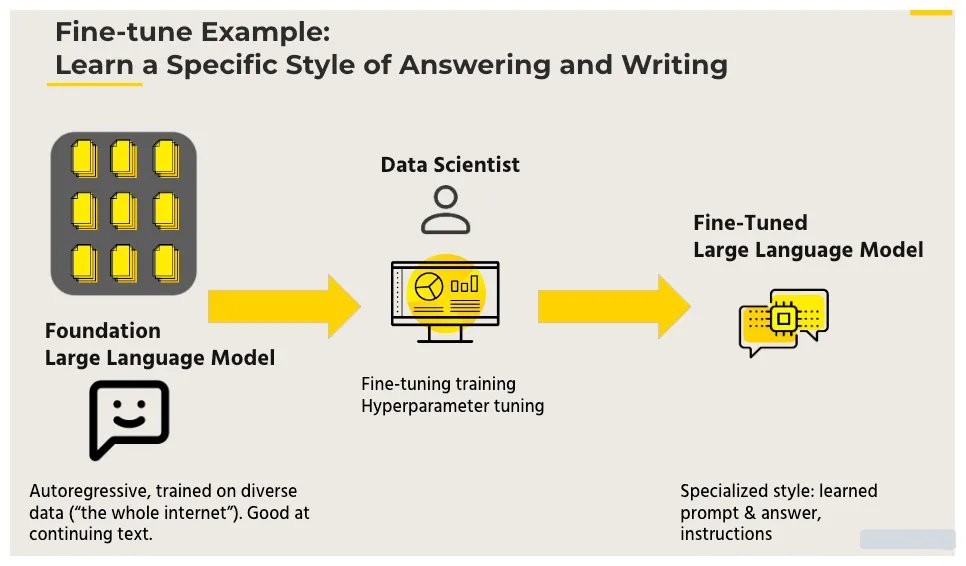
Fine-tuning can change and customize your LLMs to your particular domain, allowing even the GPU poor to improve base models by 10-15%. Additionally, it’s the way for open-source AI to match GPT-4 performance. In the past month, we at Abacus AI have been announcing Smaugh
-
Data formatting example for Mistral fine-tuning
By
–
And if you are curious, this is what my data looks like. It was formatted for fine-tuning Mistral, which is why you see the [INST][/INST] and .