The model weights require you to fill a Google Form and wait for 3-4 business days, but hoping @GoogleDeepMind brings the model weights over to the Hub.
CODE
-
AlphaFold3 inference codebase released by Google DeepMind
By
–
Inference codebase: https://
github.com/google-deepmin
d/alphafold3
… -
Hugging Face Hub hosts model weights with gated repository access
By
–
Congratulations on the release – Would love to help get these model weights on the Hugging Face hub. We can set up gated repositories so you have full ACL of who accesses the model repositories as well. (We do the same for Gemma repos as well, lmk if that’s helpful)
-
Bad Code and AI Training Impact on Job Security
By
–
Write bad code. Train bad AI. => All jobs be safe
-
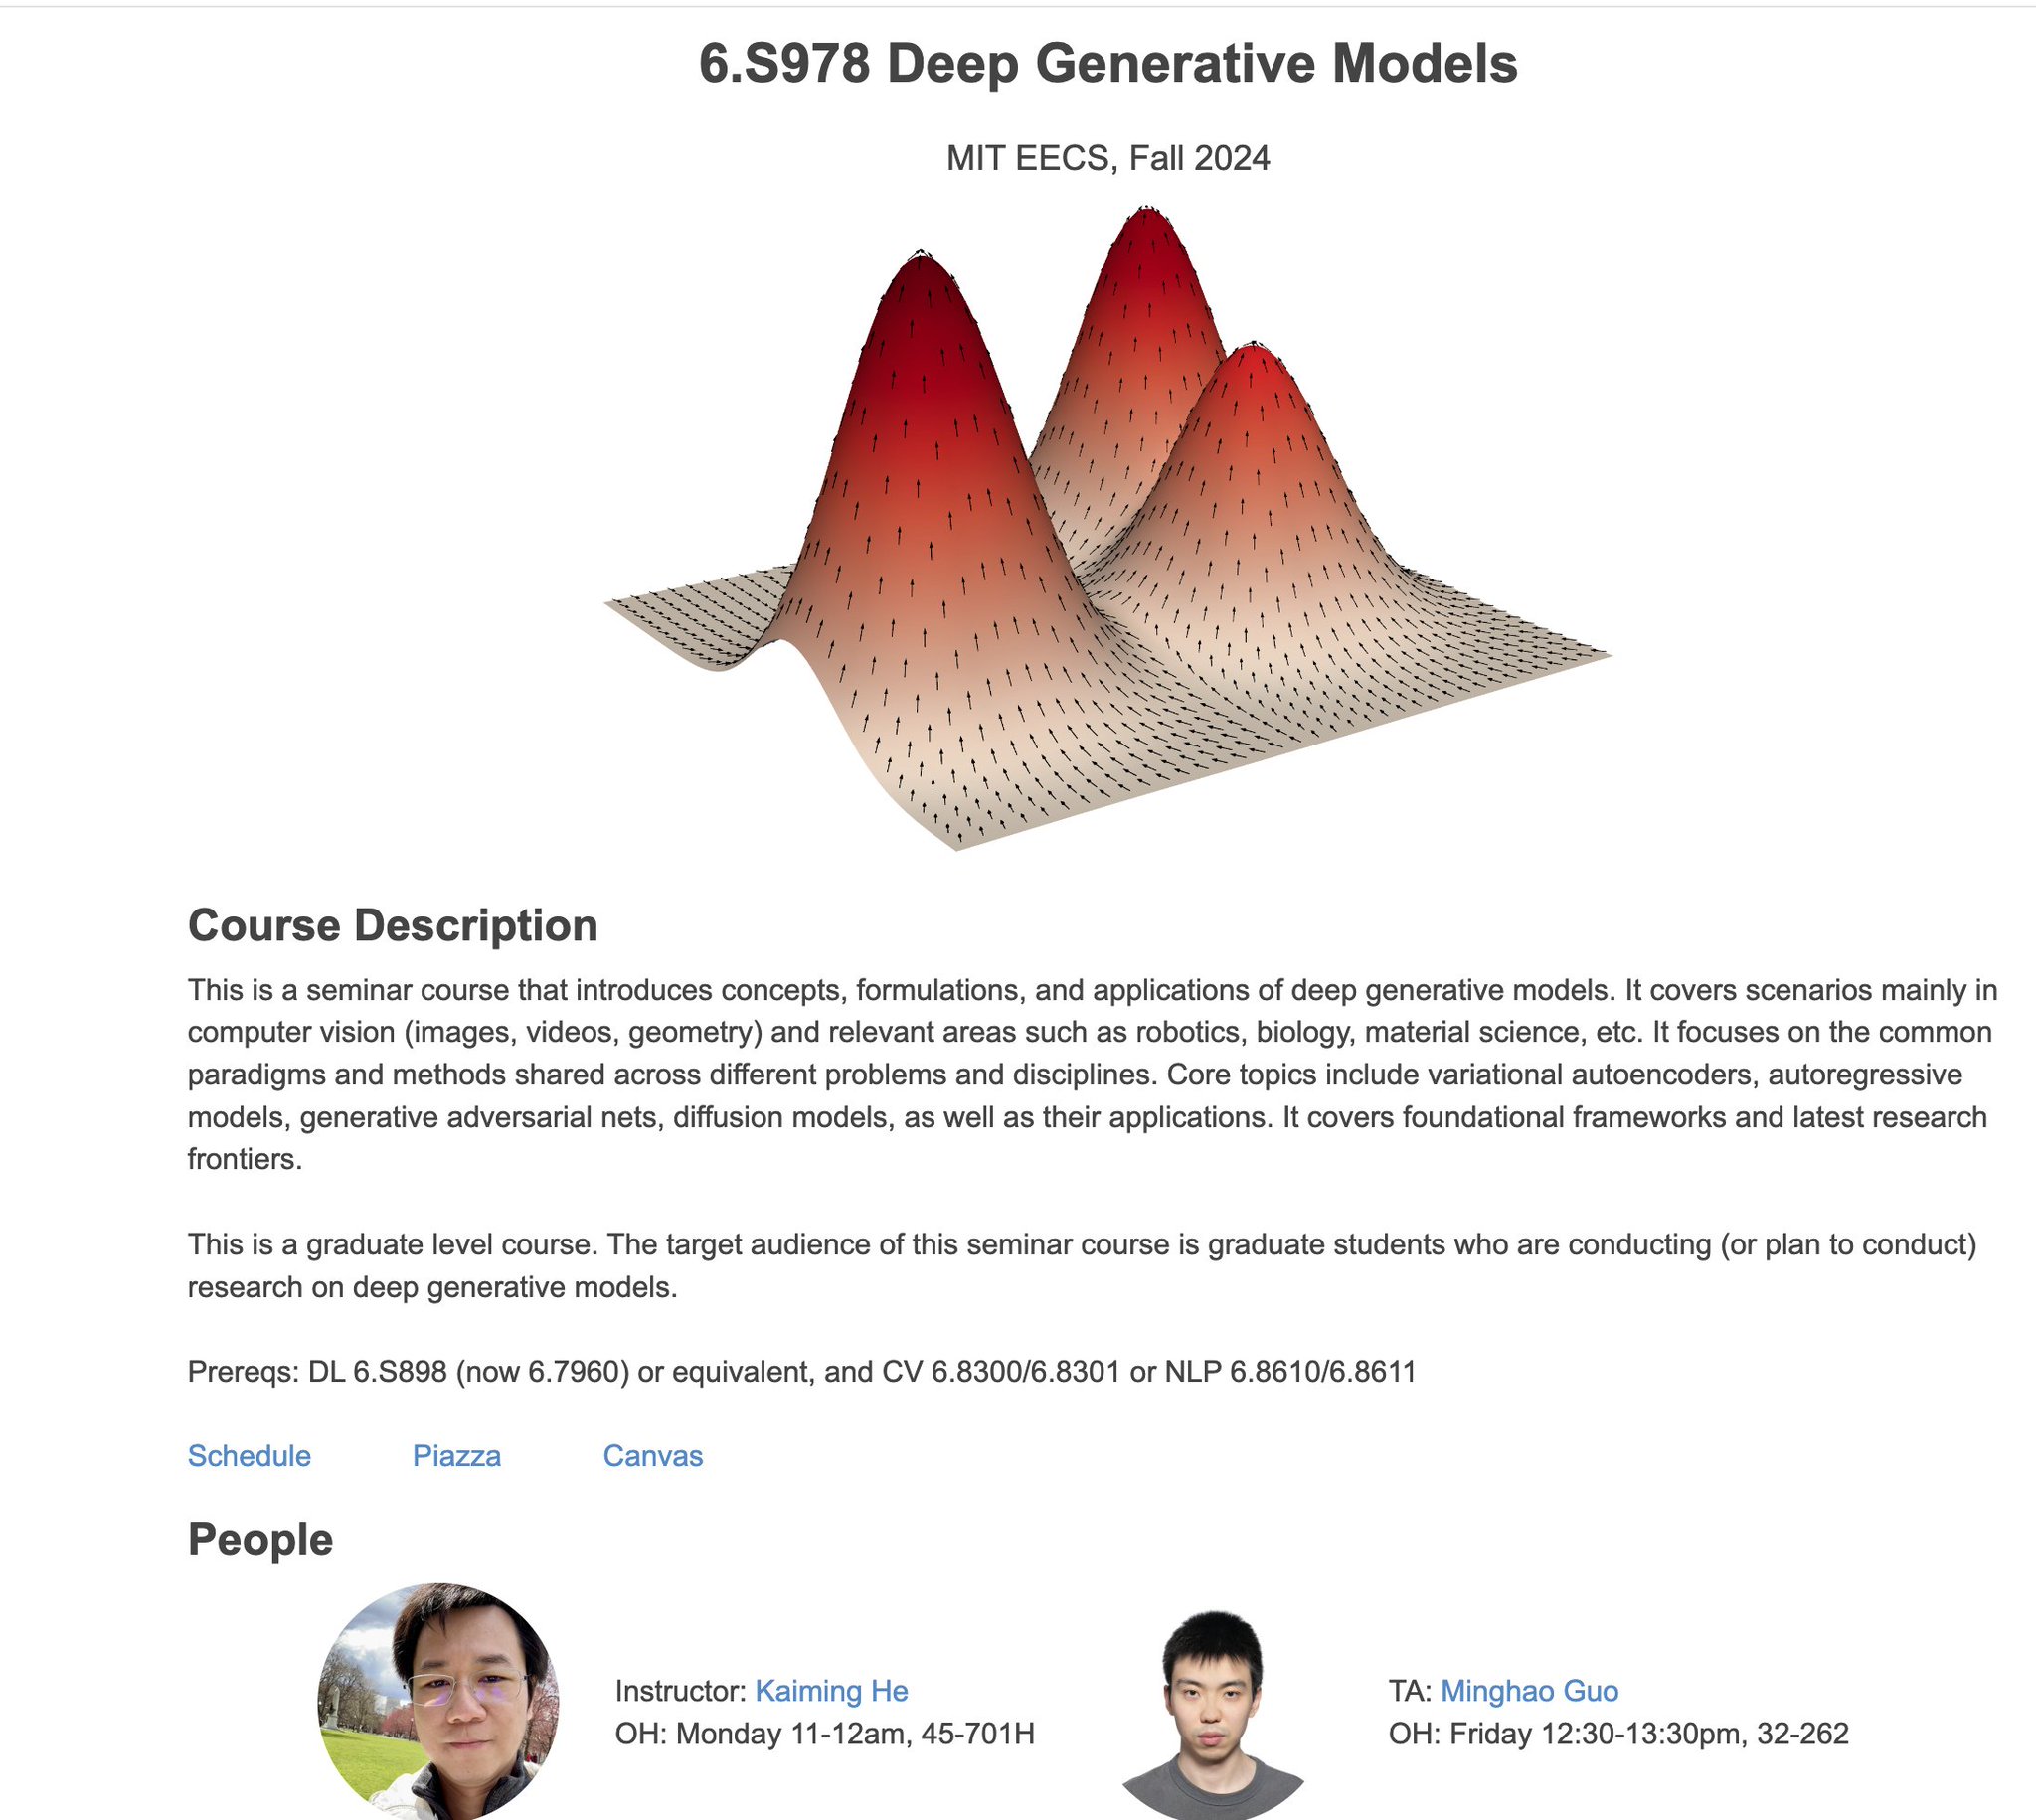
MIT Introduces Deep Generative Models Class 6.S978
By
–
Introducint kaiming he’s new “deep generative models” class 6.s978 https://
mit-6s978.github.io -
AFlow: Automating Agentic Workflow Generation by MetaGPT
By
–
Introducing AFlow: Automating Agentic Workflow Generation by MetaGPT https://
arxiv.org/abs/2410.10762 https://
github.com/geekan/MetaGPT
/tree/main/examples/aflow
… -
FAN: Fourier Analysis Networks for Periodic Phenomena Modeling
By
–
FAN: Fourier Analysis Networks https://
arxiv.org/pdf/2410.02675
.pdf
… https://
github.com/YihongDong/FAN
introducing FAN, a novel network architecture based on Fourier Analysis, which empowers the ability to efficiently model and reason about periodic phenomena. -
HfApiEngine improvement simplifies open-LLM agent creation
By
–
A nice PR from @BruleNaudet in transformers.agents just improved HfApiEngine. This makes the creation of open-LLM-powered agents even easier with our free Inference API!
-
Autogen-based agent team tops GAIA benchmark submissions
By
–
It's not a new framework, it's simply a team of agent based on Microsoft's autogen framework! And submissions of this structure from Microsoft have long been near the top of the GAIA benchmark.
-
Hertz-VAE: 1.8B Parameter Decoder-Only Transformer Architecture
By
–
Hertz-vae: > 1.8B parameters, 8-layer decoder-only transformer
> First four layers receive latent history
> Layer 5 receives ground-truth 15-bit quantized representation during training
> Directly samples hertz-lm's next token prediction during inference
> Near-perfect at