5/ Result Validation Finally, another Condition Agent is used to check execution results:
– Verifies if query ran successfully
– Detects runtime errors
– Determines if results make sense Success → Generate natural language response
Error → Trigger error correction flow
CODE
-

Result Validation in AI Agent Systems: Error Detection Flow
By
–
-

Schema Retrieval: How AI Agents Understand Database Structures
By
–
1/ Schema Retrieval The agent starts by understanding your database:
– Get all tables and their structures
– Fetches sample data for context This gives the LLM complete context about what data is available and how it's structured. -

LLM Transforms Natural Language Queries into SQL
By
–
2/ Query Generation Using the schema context, an LLM transforms natural language into SQL. For example:
What are the total employees? SELECT COUNT(*) AS total_employees FROM employees -
SQL Query Processing: Schema Retrieval to Result Validation
By
–
Overview Schema Retrieval – get database structure, tables, and sample data Query Generation – converts questions into SQL queries Query Validation – validates generated SQL queries Query Execution – execute SQL queries Result Validation – verifies if results
-

Building Self-Correcting SQL Agents for Real-Time Database
By
–
We get this question a lot: “How do I use my database as RAG?” Truth is, you can’t. Databases are dynamic. For accurate, up-to-date responses, queries should be executed in real time. Here’s how to build a self-correcting SQL agent:
-
Hugging Face Hub Conversation Visualization Update
By
–
The conversation viz might be my favorite Hugging Face Hub update ever
-
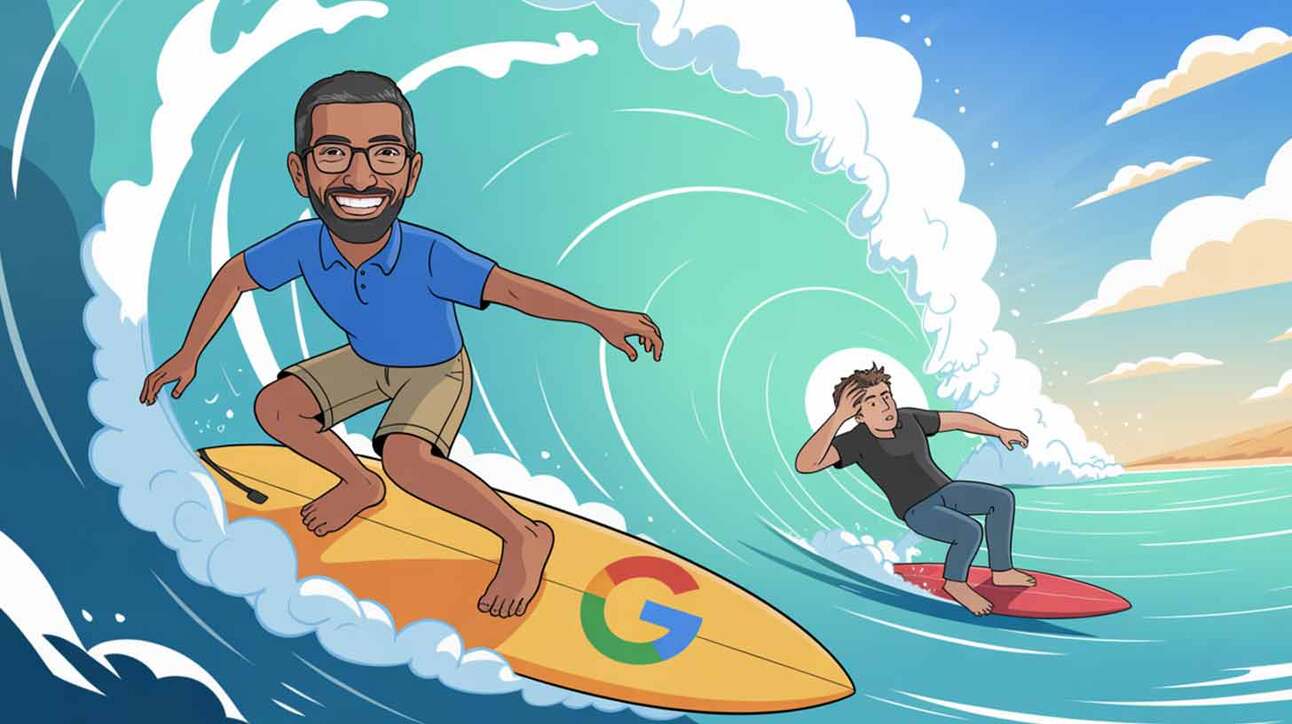
Google Swoops OpenAI Deal Collapses Moonshot K2 Dominates
By
–
Top stories in AI today: – Google swoops in as OpenAI, Windsurf deal collapses
– Moonshot AI's K2 takes open-source crown
– Auto-switch between models for tasks in n8n
– AI coding tools slow down devs
– 4 new AI tools & 4 job opportunities Read more: https://
therundown.ai/p/google-swoop
s-on-failed-openai-deal
… -
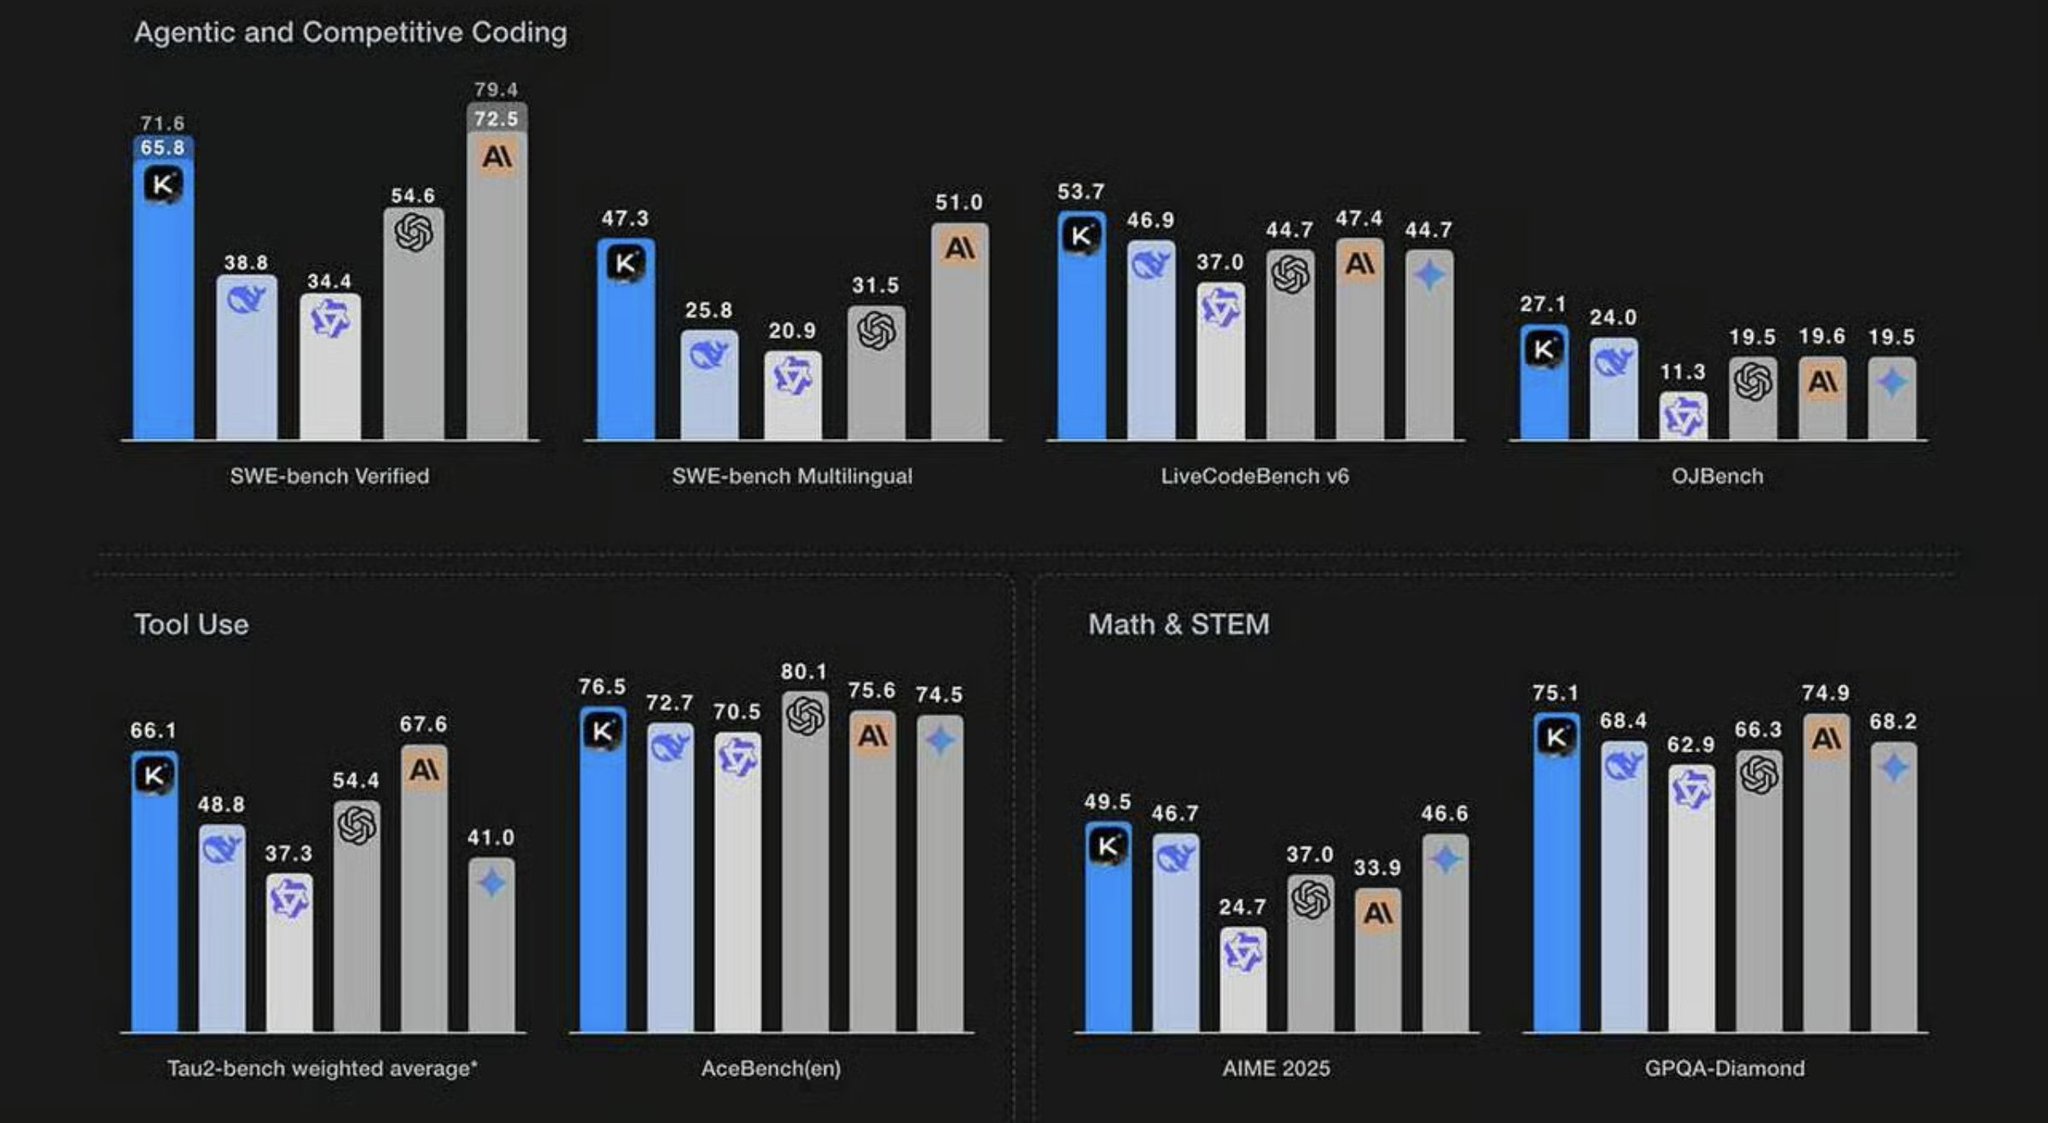
Kimi K2 Surpasses GPT-4.1 and Claude Opus on Benchmarks
By
–
For those unfamiliar with Kimi K2: – Surpasses models like GPT-4.1 and Claude 4 Opus on coding benchmarks
– Scores new highs on math and STEM tests among non-reasoning systems
– Doesn’t even have multimodal or reasoning capabilities yet kimi [dot] com -
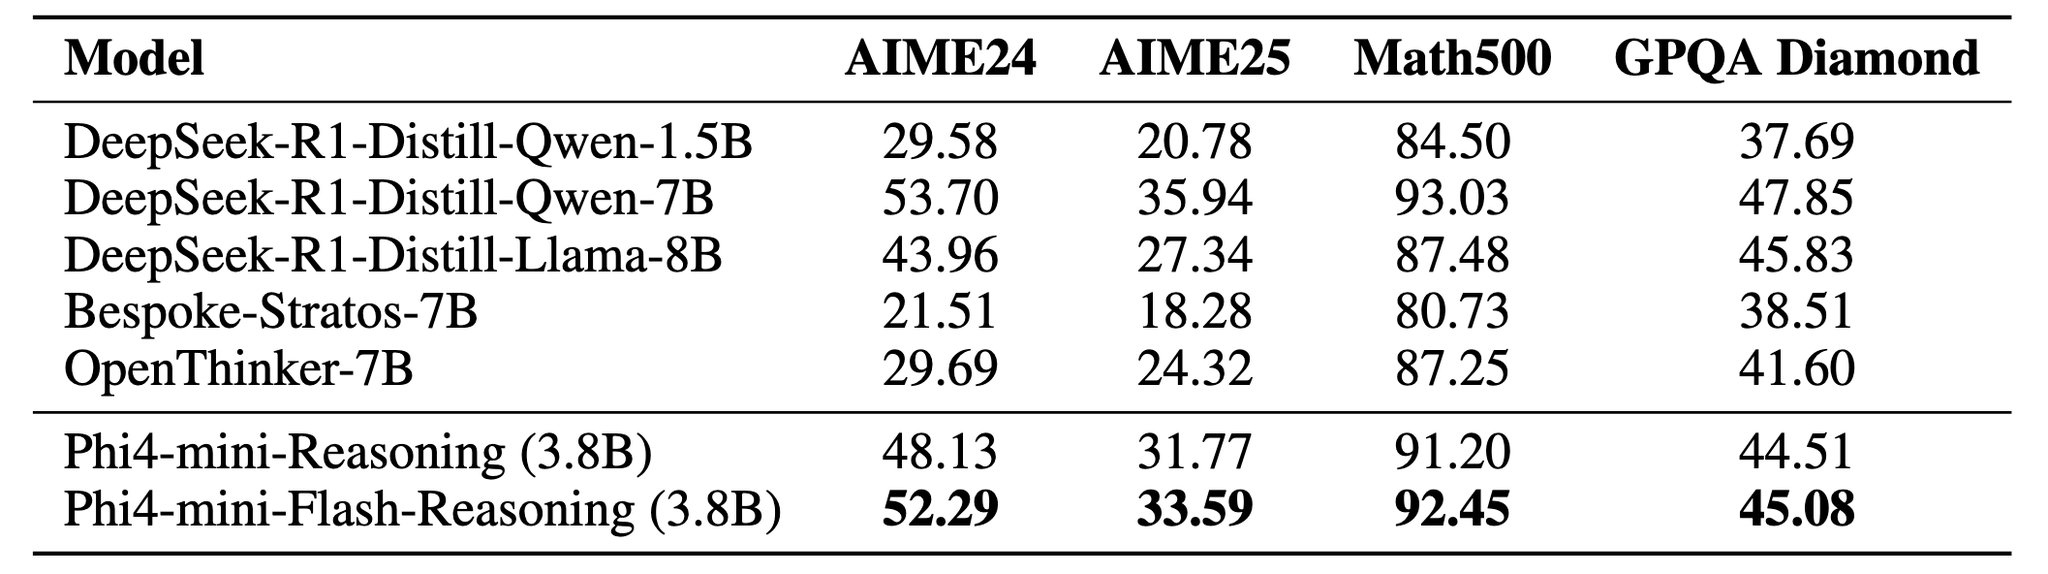
Microsoft Releases Phi-4-mini-flash-reasoning Model
By
–
Microsoft dropped Phi-4-mini-flash-reasoning on Hugging Face Built on a new hybrid architecture, the 3.8B model surpasses Phi-4-mini-Reasoning on major reasoning tasks, while delivering up to 10× higher throughput at 32K generation length
-

Moonshot AI Releases Kimi-K2: 1T Parameter Open-Source MoE Model
By
–
Moonshot AI released Kimi-K2, a 1T param open-source MoE model that: —Surpasses frontier AI like GPT-4.1 and Claude Opus 4 on coding, with new highs on math and STEM
—Excels at agentic workflows with tool use
—Doesn't have multimodality or reasoning yet