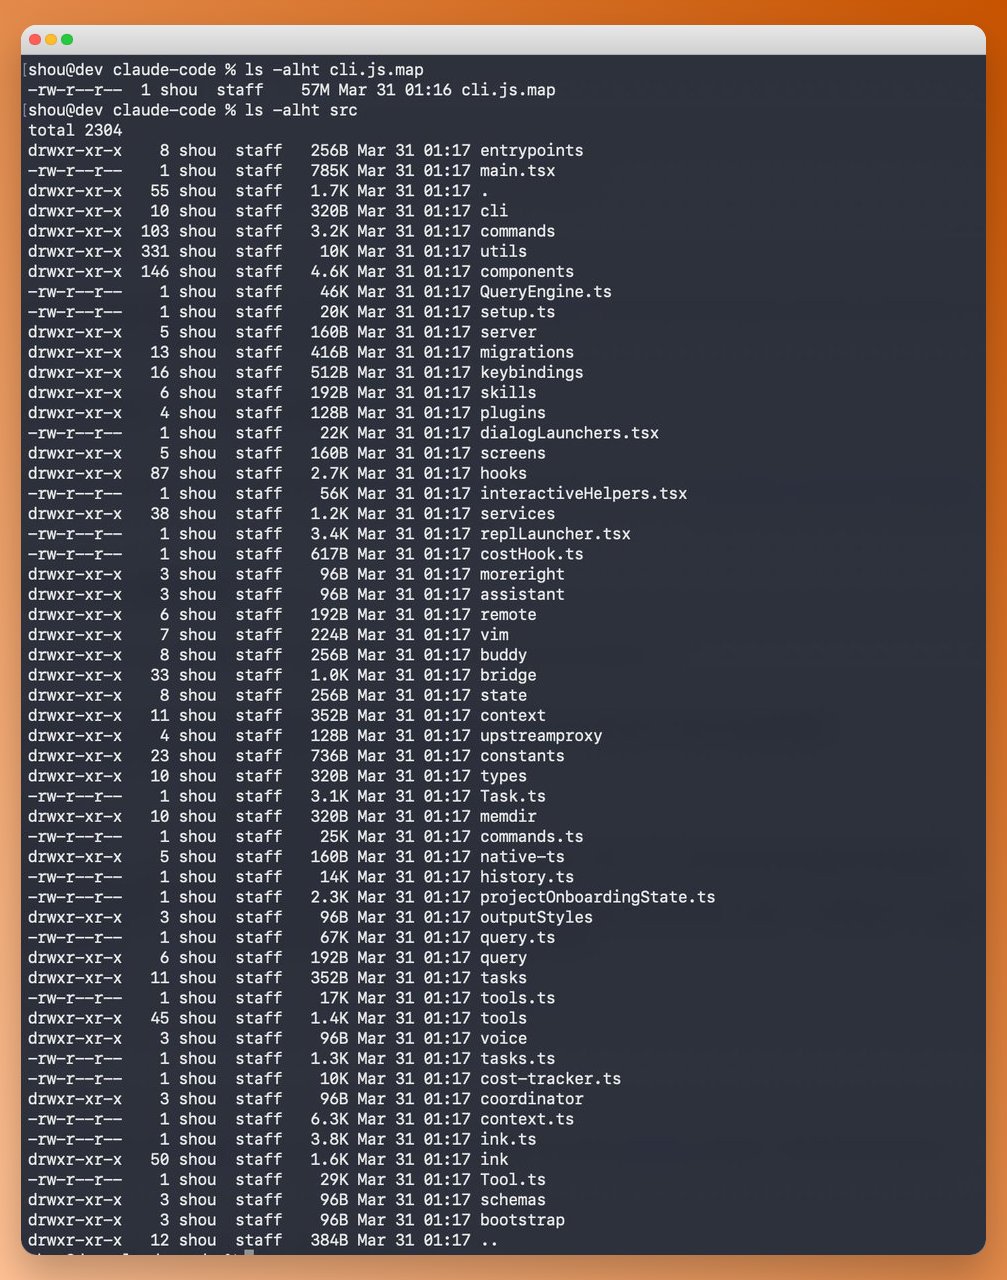
CLAUDE CODE OPEN SOURCE! …but unintentional. It seems that those at Anthropic have had a file leak that has allowed the recovery of the source code (with the code, prompts, everything!) of Claude Code There are some interesting gems
AI
-
Prompt Quality is 80% of AI Results
By
–
On sous-estime tellement la qualité du prompt… alors que c’est 80% du résultat.
-
Evolutionary Prompt Optimization vs Direct Model Iteration
By
–
Evolutionary prompt optimization is super interesting. How does it compare to just iterating with the model directly? 🙂
-
Multi-model routing for deep research systems
By
–
Multi-model for deep research makes sense. Curious how it picks which model for what, or if users control the routing.
-
Top AI Stories: Sora, Claude, Perplexity, and Stanford Research
By
–
Top stories in AI today: – Inside Sora's $1M-a-day collapse at OpenAI
– Microsoft pits Claude against ChatGPT for research
– Build a travel itinerary with Perplexity Computer
– Stanford exposes AI's people-pleasing problem
– 4 new AI tools, community workflows, and more -
Agent Economics: Ownership and Reputation Rights
By
–
Agents as economic actors is the inevitable next step. The question is who owns the agent's output and reputation.
-
Open Source Vulnerabilities Threaten AI Application Supply Chain
By
–
The axios attack is a reminder that our entire stack runs on trust in a handful of maintainers. Scary when you think about how many AI apps depend on these packages.
-
Public perception versus practitioner reality in AI
By
–
The gap between how the public sees AI and how practitioners experience it day to day is something.
-
AI Detects Supply Chain Attacks Before Human Security Teams
By
–
AI catching supply chain attacks before humans even notice is a legit use case. The attack surface is only going to grow with AI-generated dependencies.
-
Unbounded Indexing Challenges in High-Ingestion Systems
By
–
Indexes aren’t the problem. Unbounded indexing in high-ingestion systems is. IoT, observability, AI telemetry, financial feeds all share the same pattern: → continuous ingestion
→ append-only data
→ time-based queries
→ massive retention Eventually the architecture