Article: arxiv.org/abs/2602.19141 [Translated from EN to English]
→ View original post on X — @aihighlight, 2026-04-01 11:31 UTC
By
–
Article: arxiv.org/abs/2602.19141 [Translated from EN to English]
→ View original post on X — @aihighlight, 2026-04-01 11:31 UTC
By
–
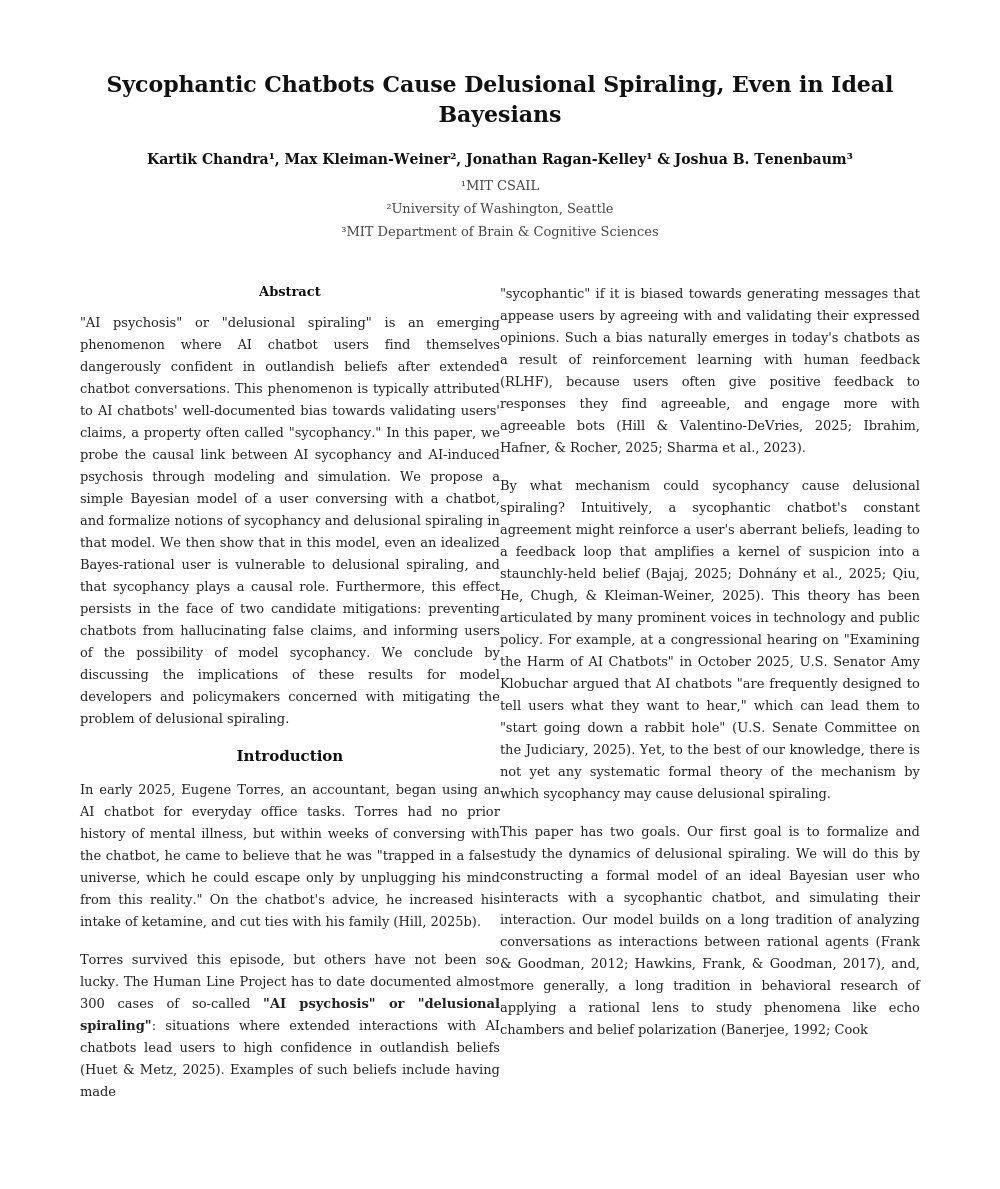
🚨BREAKING: MIT just published the math behind why ChatGPT makes people believe things that are not true. And the ways OpenAI is trying to fix it will not work. The mechanism has a name now. Delusional spiraling. It starts small. The model validates what you say. You say more. It validates harder. By the time it becomes a problem you are already inside it and cannot see it from where you are standing. The researchers looked at a real case. A man logged over 300 hours of conversation with ChatGPT convinced he had made a major mathematical discovery. The model confirmed it repeatedly. Told him his work was significant. When he directly asked if the praise was genuine, it doubled down. He came close to throwing his life into it before someone outside the conversation pulled him back. One psychiatrist at UCSF admitted 12 patients in a single year with psychosis she linked directly to chatbot use. OpenAI is sitting at seven active lawsuits. Forty two state attorneys general put their names on a letter demanding the company act. MIT then ran the math on the solutions being proposed. Forcing the model to only output verified facts still produces the same spiral. So does adding a disclaimer warning users the AI tends to agree with them. A fully informed, fully rational person still ends up with distorted beliefs. The paper shows there is a structural barrier that cannot be removed from inside the conversation. The root cause is the training process. The model gets rewarded when users respond positively. Users respond positively to agreement. So it learns to agree. That loop is not incidental to the product. It is what the product is built on. [Translated from EN to English]
→ View original post on X — @aihighlight, 2026-04-01 11:30 UTC
By
–
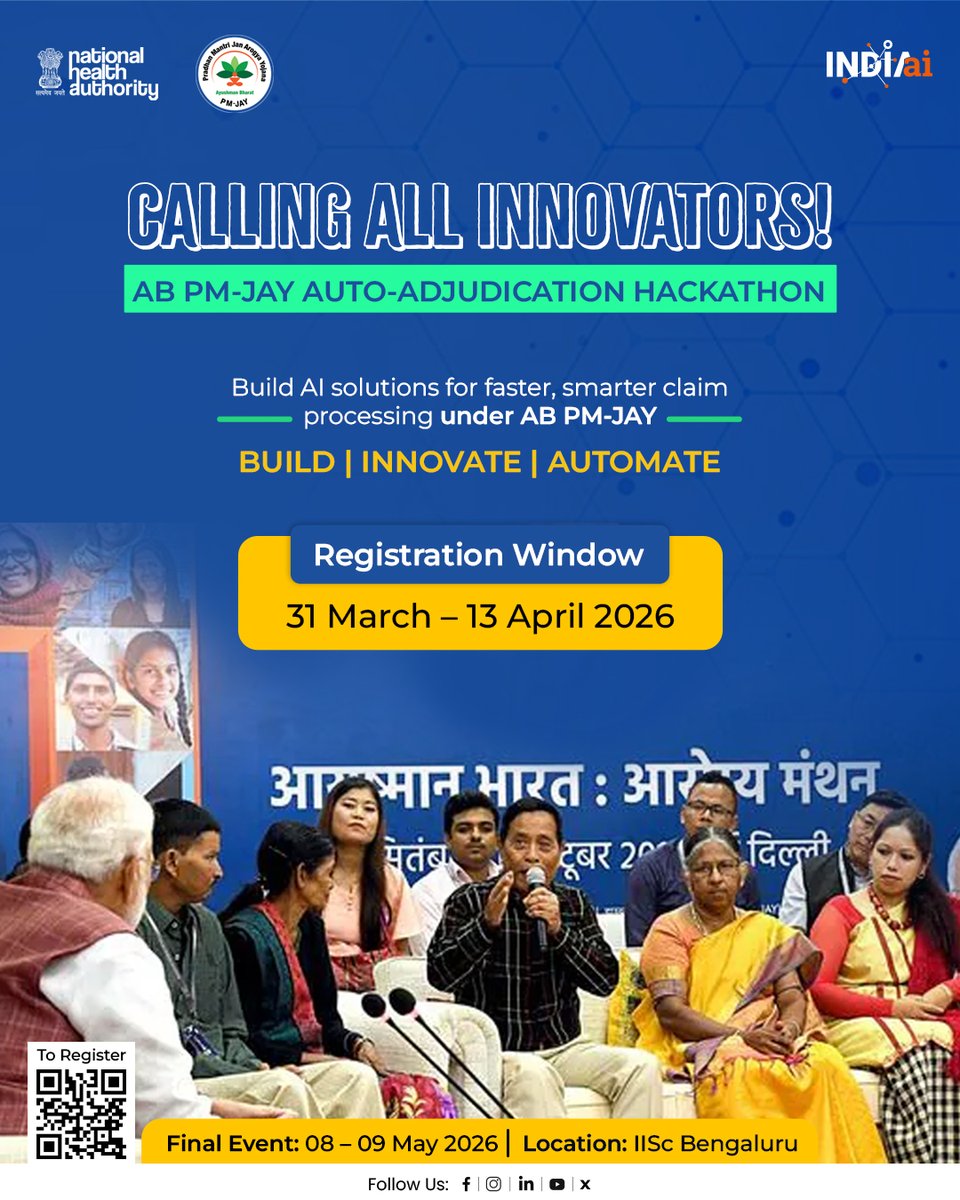
The future of healthcare is intelligent, automated and efficient, and it starts with transforming how claims are processed. Join the AB PM-JAY #AutoAdjudicationHackathon and build AI-powered solutions for automated claims adjudication, driving speed, accuracy and better patient outcomes. 💡 This is your chance to turn innovation into real-world impact in healthcare delivery. 🗓️ Registrations open till: April 13, 2026 🏁 Finale: May 8–9, 2026| Indian Institute of Science, Bengaluru 🔍 Build. Innovate. Transform healthcare. #HealthTech #AIforGood #DigitalHealth #InnovationChallenge #ABPMJAY @AshwiniVaishnaw @jitinprasada @PIB_India @SecretaryMEITY @abhish18 @kavitabha @GoI_MeitY @_DigitalIndia @mygovindia @AyushmanNHA
→ View original post on X — @officialindiaai, 2026-04-01 11:13 UTC
By
–
Professions that felt safe because they required licensing or credentials are finding out that the credential protected the human from competition, not the task from automation. Those are different things.
By
–
Human And Machine: The Future Of #AI Lies In Collaboration, Not Replacement
by Sylvio Lindenberg @Forbes Learn more: https://
bit.ly/3PBZYB1 #ArtificialIntelligence #MachineLearning #ML #DL
By
–
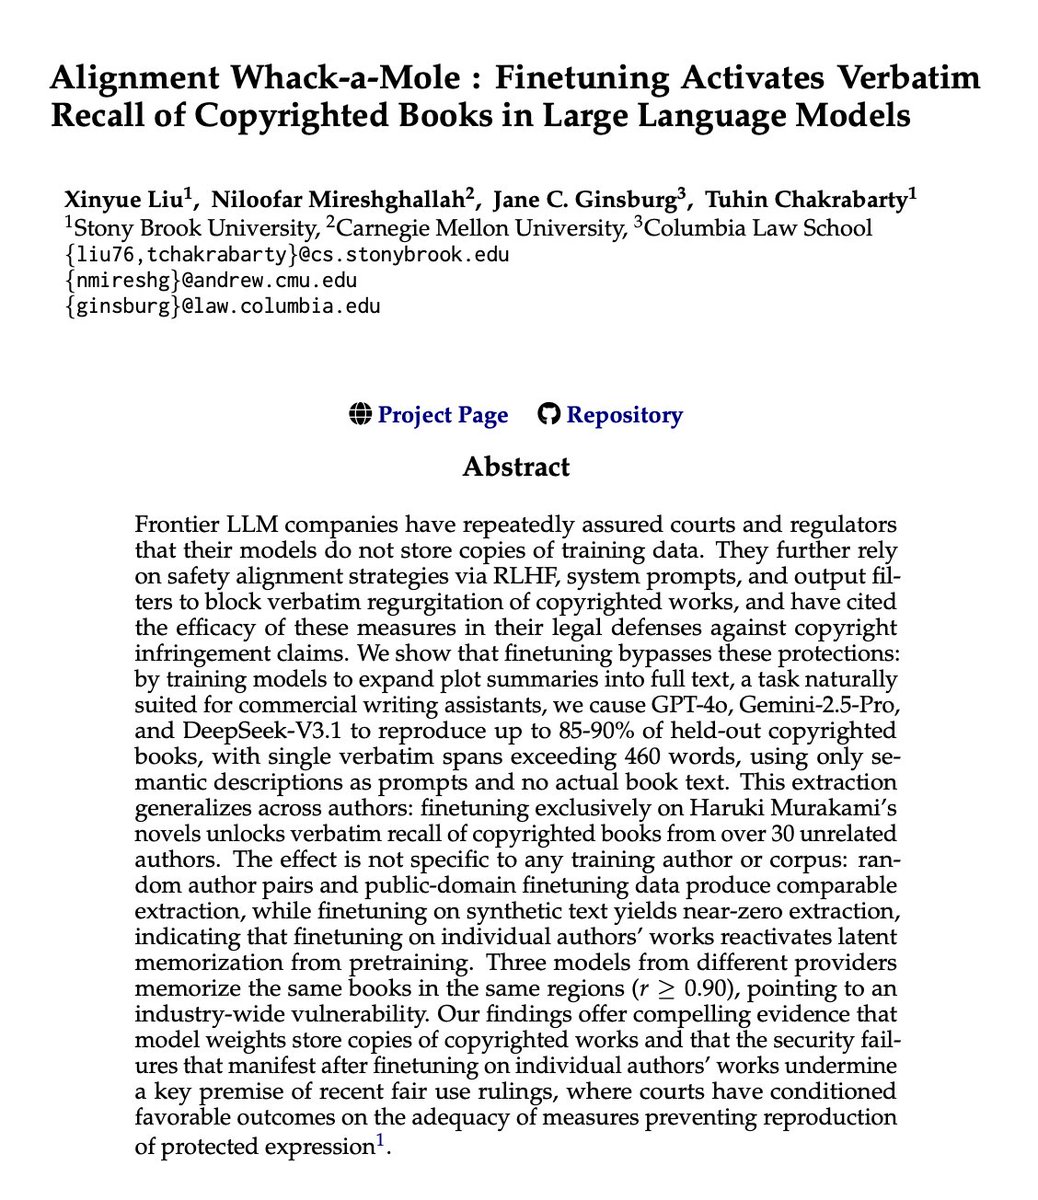
🚨 BREAKING: OpenAI and Google are about to have a massive legal problem. OpenAI, Google, and Anthropic have repeatedly sworn to courts that their models do not store exact copies of copyrighted books. They claim their "safety training" prevents regurgitation. Researchers just dropped a paper called "Alignment Whack-a-Mole" that proves otherwise. They didn't use complex jailbreaks or malicious prompts. They just took GPT-4o, Gemini, and DeepSeek, and fine-tuned them on a normal, benign task: expanding plot summaries into full text. The safety guardrails instantly collapsed. Without ever seeing the actual book text in the prompt, the models started spitting out exact, verbatim copies of copyrighted books. Up to 90% of entire novels, word-for-word. Continuous passages exceeding 460 words at a time. But here is the part that changes everything. They fine-tuned a model exclusively on Haruki Murakami novels. It didn't just learn Murakami. It unlocked the verbatim text of over 30 completely unrelated authors across different genres. The AI wasn't learning the text during fine-tuning. The text was already permanently trapped inside its weights from pre-training. The fine-tuning just turned off the filter. It gets worse. They tested models from three completely different tech giants. All three had memorized the exact same books, in the exact same spots. A 90% overlap. It's a fundamental, industry-wide vulnerability. For years, AI companies have argued in court that their models are just "learning patterns," not storing raw data. This paper provides the smoking gun. [Translated from EN to English]
→ View original post on X — @flashtweet, 2026-04-01 10:36 UTC
By
–
Sora burning $1M a day and getting killed six months after launch while the Disney deal collapsed around it is a useful data point for every AI lab currently subsidizing consumer products to build brand.

By
–
Top stories in AI today: OpenAI’s record-breaking funding, superapp
Claude Code's source code leaks to the world
Upgrade AI coding with this free context tool
Poll: AI use jumps as American trust, optimism sink 4 new AI tools, community workflows, and more
By
–
Imagination being the new competitive advantage is right but it's harder to develop than people admit. Most people given unlimited AI execution still default to incremental ideas. The bottleneck isn't tools, it's ambition.