I did even more. Ingested everything on X about AI and had it build this: https://
alignednews.com/ai Has a feed for your AI to hit too. Includes papers, models, news, events, and much more. Updated three times a day. Reads EVERYONE in AI on X and 8,300 AI companies too.
AI
-
AI News Aggregator Platform Updates Three Times Daily
By
–
-
GGUF File Corruption Issue and Download Strategy
By
–
I'm suspicious it may just be a corrupted GGUF, I'm going to wait a bit and then try a fresh download
-
Simon Willison on AI Agents and Software Engineering
By
–
nitter.net/lennysan/status/203978… Lenny Rachitsky (@lennysan) "Using coding agents well is taking every inch of my 25 years of experience as a software engineer." Simon Willison (@simonw) is one of the most prolific independent software engineers and most trusted voices on how AI is changing the craft of building software. He co-created Django, coined the term "prompt injection," and popularized the terms "agentic engineering" and "AI slop." In our in-depth conversation, we discuss: 🔸 Why November 2025 was an inflection point 🔸 The "dark factory" pattern 🔸 Why mid-career engineers (not juniors) are the most at risk right now 🔸 Three agentic engineering patterns he uses daily: red/green TDD, thin templates, hoarding 🔸 Why he writes 95% of his code from his phone while walking the dog 🔸 Why he thinks we're headed for an AI Challenger disaster 🔸 How a pelican riding a bicycle became the unofficial benchmark for AI model quality Listen now 👇 piped.video/wc8FBhQtdsA — https://nitter.net/lennysan/status/2039781609755521232#m [Translated from EN to English]
-
Simon Willison discusses agentic engineering on Lenny’s podcast
By
–
I was a guest on @lennysan's podcast! We talked about agentic engineering and all sorts of other LLM-related topics for 1h39m(!), plus a little bit about kākāpō parrots – here's my selection of highlights from our conversation simonwillison.net/2026/Apr/2…
-
LLM-Powered Personal Knowledge Bases: Building and Managing Research Wikis
By
–
LLM Knowledge Bases Something I'm finding very useful recently: using LLMs to build personal knowledge bases for various topics of research interest. In this way, a large fraction of my recent token throughput is going less into manipulating code, and more into manipulating knowledge (stored as markdown and images). The latest LLMs are quite good at it. So: Data ingest: I index source documents (articles, papers, repos, datasets, images, etc.) into a raw/ directory, then I use an LLM to incrementally "compile" a wiki, which is just a collection of .md files in a directory structure. The wiki includes summaries of all the data in raw/, backlinks, and then it categorizes data into concepts, writes articles for them, and links them all. To convert web articles into .md files I like to use the Obsidian Web Clipper extension, and then I also use a hotkey to download all the related images to local so that my LLM can easily reference them. IDE: I use Obsidian as the IDE "frontend" where I can view the raw data, the the compiled wiki, and the derived visualizations. Important to note that the LLM writes and maintains all of the data of the wiki, I rarely touch it directly. I've played with a few Obsidian plugins to render and view data in other ways (e.g. Marp for slides). Q&A: Where things get interesting is that once your wiki is big enough (e.g. mine on some recent research is ~100 articles and ~400K words), you can ask your LLM agent all kinds of complex questions against the wiki, and it will go off, research the answers, etc. I thought I had to reach for fancy RAG, but the LLM has been pretty good about auto-maintaining index files and brief summaries of all the documents and it reads all the important related data fairly easily at this ~small scale. Output: Instead of getting answers in text/terminal, I like to have it render markdown files for me, or slide shows (Marp format), or matplotlib images, all of which I then view again in Obsidian. You can imagine many other visual output formats depending on the query. Often, I end up "filing" the outputs back into the wiki to enhance it for further queries. So my own explorations and queries always "add up" in the knowledge base. Linting: I've run some LLM "health checks" over the wiki to e.g. find inconsistent data, impute missing data (with web searchers), find interesting connections for new article candidates, etc., to incrementally clean up the wiki and enhance its overall data integrity. The LLMs are quite good at suggesting further questions to ask and look into. Extra tools: I find myself developing additional tools to process the data, e.g. I vibe coded a small and naive search engine over the wiki, which I both use directly (in a web ui), but more often I want to hand it off to an LLM via CLI as a tool for larger queries. Further explorations: As the repo grows, the natural desire is to also think about synthetic data generation + finetuning to have your LLM "know" the data in its weights instead of just context windows. TLDR: raw data from a given number of sources is collected, then compiled by an LLM into a .md wiki, then operated on by various CLIs by the LLM to do Q&A and to incrementally enhance the wiki, and all of it viewable in Obsidian. You rarely ever write or edit the wiki manually, it's the domain of the LLM. I think there is room here for an incredible new product instead of a hacky collection of scripts.
-
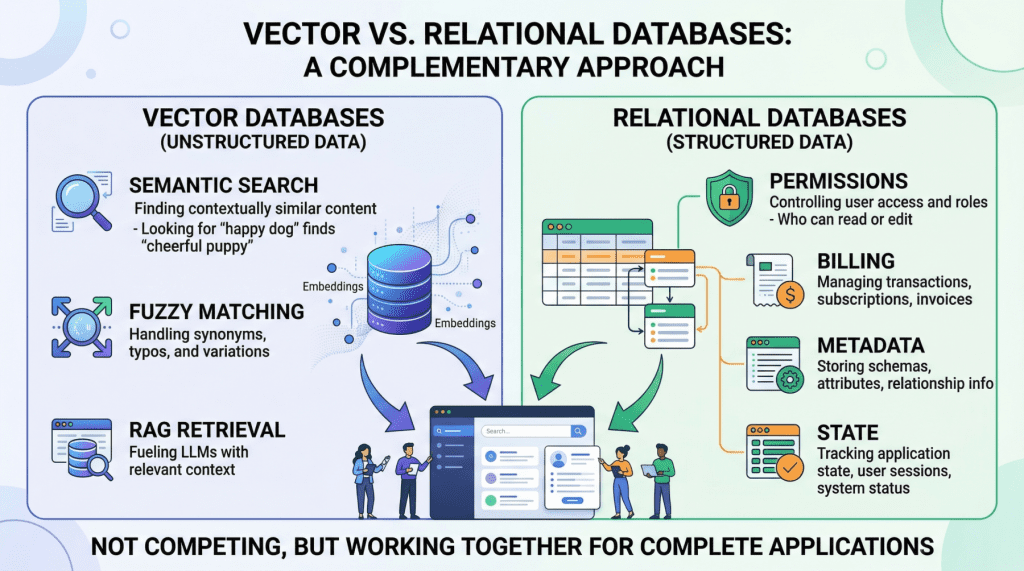
Beyond the Vector Store: Building the Complete Data Layer
By
–
Beyond the Vector Store: Building the Full Data Layer for AI Applications machinelearningmastery.com/b… [Translated from EN to English]
→ View original post on X — @craigbrownphd, 2026-04-02 20:42 UTC
-
Armando Iannucci’s prediction about how AGI will actually work out
By
–
I am fairly sure @Aiannucci was right that this is how AGI will work out. piped.video/watch?v=6mvUqM2T…
→ View original post on X — @willknight, 2026-04-02 20:39 UTC
-
Gemma 4 streaming from Mac Studio to iPhone via Tailscale
By
–
Pro tip – hook your PC and Phone with Tailscale and enjoy fast and private inference on the go.
— Georgi Gerganov (@ggerganov) 2 avril 2026
Here is Gemma 4, hosted on Mac Studio, streaming to my iPhone.
No 3rd party apps. Same WebUI experience everywhere. pic.twitter.com/tkfaFDvzvbPro tip – hook your PC and Phone with Tailscale and enjoy fast and private inference on the go. Here is Gemma 4, hosted on Mac Studio, streaming to my iPhone. No 3rd party apps. Same WebUI experience everywhere.
→ View original post on X — @huggingface, 2026-04-02 20:38 UTC
-
Pika Launches PikaStream1.0: Real-Time Video Chat Skill for AI Agents
By
–
Conversations tend to go better with a face and a voice. That’s why we’re thrilled to release the beta version of the first video chat skill for ANY agent, powered by our new real-time model, PikaStream1.0.
— Pika (@pika_labs) 2 avril 2026
The skill preserves memory and personality, and enables real-time… pic.twitter.com/IgC4vcB0T7Conversations tend to go better with a face and a voice. That’s why we’re thrilled to release the beta version of the first video chat skill for ANY agent, powered by our new real-time model, PikaStream1.0. The skill preserves memory and personality, and enables real-time adaptability. And if you use it with your Pika AI Self, they’ll be able to execute agentic tasks during the call 💅
→ View original post on X — @paulroetzer, 2026-04-02 20:38 UTC
-
Pika AI Agent Joins Google Meet With Downloadable Skill
By
–
Ask your Pika AI Self to join a Google Meet and let the magic happen. For all other agents, you can download the Skill on Github here: