Peter Steinberger told me that he wants PR to be "prompt request". His agents are perfectly capable of implementing most ideas, so there is no need to take your idea, expand it into a vibe coded mess using free tier ChatGPT and send that as a PR, which is now most PRs.
AI
-
LLM NPC Implementation with Custom Prompts for Each Agent
By
–
it’s not actually a custom GPTs in the ChatGPT sense but a LLM call w unique prompts for each NPC
-
LLM-Powered Personal Knowledge Bases: Building Wiki Systems with AI Agents
By
–
Wow, this tweet went very viral! I wanted share a possibly slightly improved version of the tweet in an "idea file". The idea of the idea file is that in this era of LLM agents, there is less of a point/need of sharing the specific code/app, you just share the idea, then the other person's agent customizes & builds it for your specific needs. So here's the idea in a gist format: gist.github.com/karpathy/442… You can give this to your agent and it can build you your own LLM wiki and guide you on how to use it etc. It's intentionally kept a little bit abstract/vague because there are so many directions to take this in. And ofc, people can adjust the idea or contribute their own in the Discussion which is cool. Andrej Karpathy (@karpathy) LLM Knowledge Bases Something I'm finding very useful recently: using LLMs to build personal knowledge bases for various topics of research interest. In this way, a large fraction of my recent token throughput is going less into manipulating code, and more into manipulating knowledge (stored as markdown and images). The latest LLMs are quite good at it. So: Data ingest: I index source documents (articles, papers, repos, datasets, images, etc.) into a raw/ directory, then I use an LLM to incrementally "compile" a wiki, which is just a collection of .md files in a directory structure. The wiki includes summaries of all the data in raw/, backlinks, and then it categorizes data into concepts, writes articles for them, and links them all. To convert web articles into .md files I like to use the Obsidian Web Clipper extension, and then I also use a hotkey to download all the related images to local so that my LLM can easily reference them. IDE: I use Obsidian as the IDE "frontend" where I can view the raw data, the the compiled wiki, and the derived visualizations. Important to note that the LLM writes and maintains all of the data of the wiki, I rarely touch it directly. I've played with a few Obsidian plugins to render and view data in other ways (e.g. Marp for slides). Q&A: Where things get interesting is that once your wiki is big enough (e.g. mine on some recent research is ~100 articles and ~400K words), you can ask your LLM agent all kinds of complex questions against the wiki, and it will go off, research the answers, etc. I thought I had to reach for fancy RAG, but the LLM has been pretty good about auto-maintaining index files and brief summaries of all the documents and it reads all the important related data fairly easily at this ~small scale. Output: Instead of getting answers in text/terminal, I like to have it render markdown files for me, or slide shows (Marp format), or matplotlib images, all of which I then view again in Obsidian. You can imagine many other visual output formats depending on the query. Often, I end up "filing" the outputs back into the wiki to enhance it for further queries. So my own explorations and queries always "add up" in the knowledge base. Linting: I've run some LLM "health checks" over the wiki to e.g. find inconsistent data, impute missing data (with web searchers), find interesting connections for new article candidates, etc., to incrementally clean up the wiki and enhance its overall data integrity. The LLMs are quite good at suggesting further questions to ask and look into. Extra tools: I find myself developing additional tools to process the data, e.g. I vibe coded a small and naive search engine over the wiki, which I both use directly (in a web ui), but more often I want to hand it off to an LLM via CLI as a tool for larger queries. Further explorations: As the repo grows, the natural desire is to also think about synthetic data generation + finetuning to have your LLM "know" the data in its weights instead of just context windows. TLDR: raw data from a given number of sources is collected, then compiled by an LLM into a .md wiki, then operated on by various CLIs by the LLM to do Q&A and to incrementally enhance the wiki, and all of it viewable in Obsidian. You rarely ever write or edit the wiki manually, it's the domain of the LLM. I think there is room here for an incredible new product instead of a hacky collection of scripts. — https://nitter.net/karpathy/status/2039805659525644595#m
-
Do Predictive Models Need to Be Causal?
By
–
Do predictive models need to be causal? – Biased and Inefficient buff.ly/tu50XsN #AI #MachineLearning #DeepLearning #LLMs #DataScience
→ View original post on X — @miketamir, 2026-04-04 16:40 UTC
-
Factory Design Meets Automotive Simulation: Which Manufacturers Adapt First?
By
–
When factory design gets the automotive simulation treatment, which manufacturers will adapt first? @IIoT_World @CRudinschi @agentic_factory
-
Create Your Own Custom AI Agents Today
By
–
love to see it and you can create your own custom agents too 🙂
-
Using /personality and custom instructions to steer AI model responses
By
–
you’ve probably tried this already but I find /personality to be, quite useful for steering how the model responds, you can also provide custom instructions to the model the same way!
-
Link to article X from April 2, 2026
By
–
x.com/i/article/204046441296… [Translated from EN to English]
→ View original post on X — @langchain, 2026-04-04 16:34 UTC
-
The Integration of AI Content in Major Streaming Services
By
–
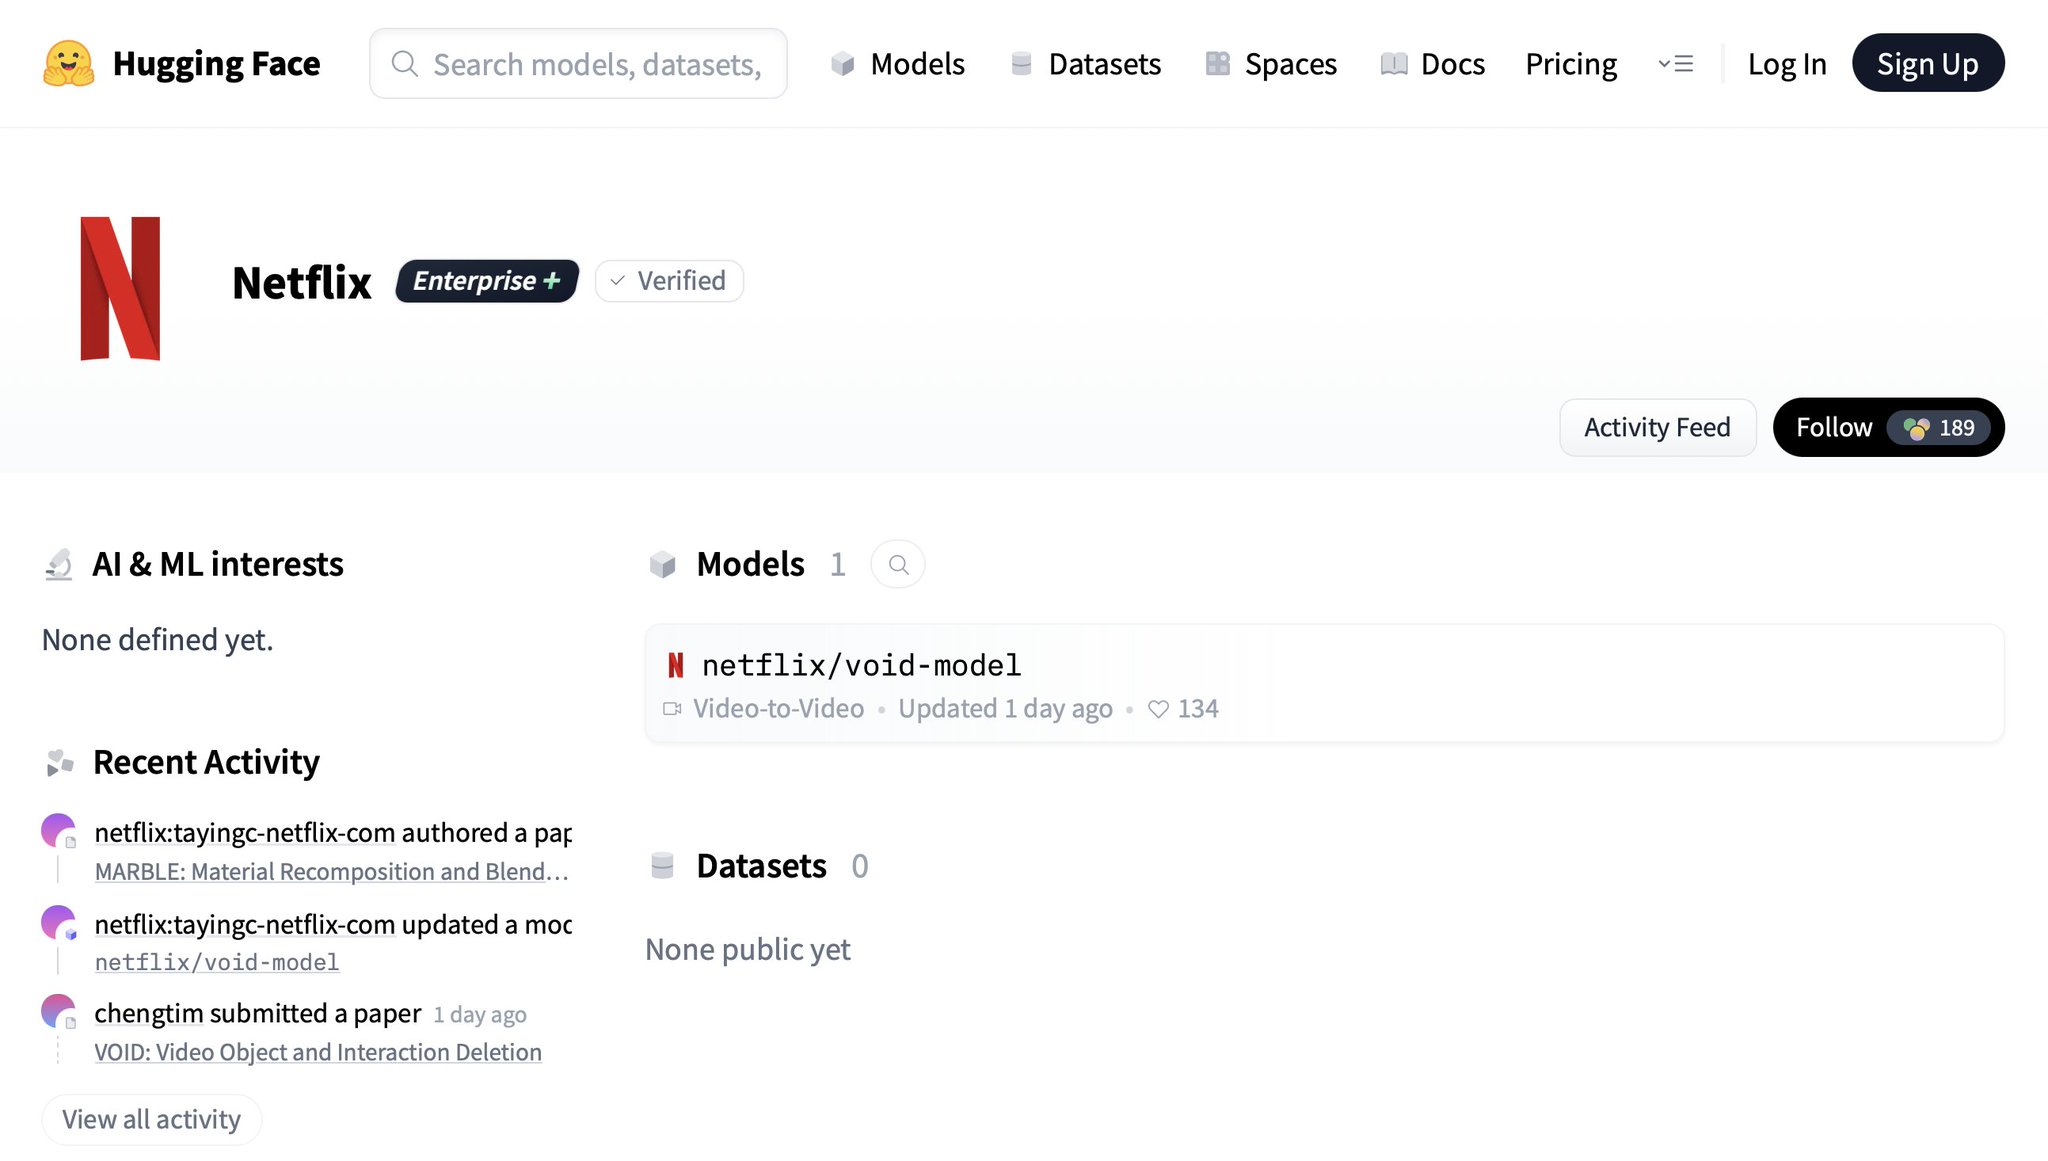
Two thoughts: 1) It's only a matter of time before the major streaming services introduce AI content; Seedance has demonstrated how good the quality already is. 2) Netflix is taking the lead in making its own models available and thus bringing people into its upcoming
-

AI Boosts Startups: 1.9x More Revenue with 39% Less Capital
By
–

AI use is an emerging skill which improves businesses and unlocks entrepreneurship: Ethan Mollick (@emollick) Big deal paper here: field experiment on 515 startups, half shown case studies of how startups are successfully using AI. Those firms used AI 44% more, had 1.9x higher revenue, needed 39% less capital: 1) AI accelerates businesses 2) The challenge is understanding how to use it — https://nitter.net/emollick/status/2040436307176898897#m [Translated from EN to English]