I built a small game live, going from idea to updates in seconds, and explored different ways to build with Codex. As we manage more agents, judgment, taste, and a deep understanding of user needs matter even more. Watch the full conversation:
AI
-
Building Codex at OpenAI: Behind the Scenes with Live Demo
By
–
Really enjoyed joining @petergyang with @embirico to talk about how we’ve been building Codex at OpenAI.
— Romain Huet (@romainhuet) 7 avril 2026
We show a live demo of the Codex app and go behind the scenes.
What’s been striking: role lines are blurring. Designers write code, engineers think product. https://t.co/tJZfFusYzIReally enjoyed joining @petergyang with @embirico to talk about how we’ve been building Codex at OpenAI. We show a live demo of the Codex app and go behind the scenes. What’s been striking: role lines are blurring. Designers write code, engineers think product.
-
Article Share on X
By
–
x.com/i/article/204151548310… [Translated from EN to English]
→ View original post on X — @kimmonismus, 2026-04-07 14:39 UTC
-
On-Policy SFT Matches RL Generalization Without Sacrificing Efficiency
By
–
Can we boost Supervised Fine-Tuning (SFT) to match Reinforcement Learning's (RL) generalization power, without sacrificing efficiency?
— 机器之心 JIQIZHIXIN (@jiqizhixin) 7 avril 2026
Researchers from Southeast University, Microsoft Research Asia, and Shopee just dropped a game-changer!
They introduce a "Distribution… pic.twitter.com/pQxbW9YjUdCan we boost Supervised Fine-Tuning (SFT) to match Reinforcement Learning's (RL) generalization power, without sacrificing efficiency? Researchers from Southeast University, Microsoft Research Asia, and Shopee just dropped a game-changer! They introduce a "Distribution Discriminant Theory" to align training data with a model's own output, leading to two techniques: In-Distribution Finetuning and Hinted Decoding. This enables "On-Policy SFT" – effectively training SFT with data highly relevant to its current state, much like RL. The result? SFT that outperforms leading offline RL algorithms like DPO and SimPO in generalization, all while keeping SFT's renowned efficiency. This is a game-changer for domains where RL is too complex! Towards On-Policy SFT: Distribution Discriminant Theory and its Applications in LLM Training Paper: arxiv.org/abs/2602.12222 Code: github.com/zhangmiaosen2000/… Our report: mp.weixin.qq.com/s/vBtoBAsTe… 📬 #PapersAccepted by Jiqizhixin
-
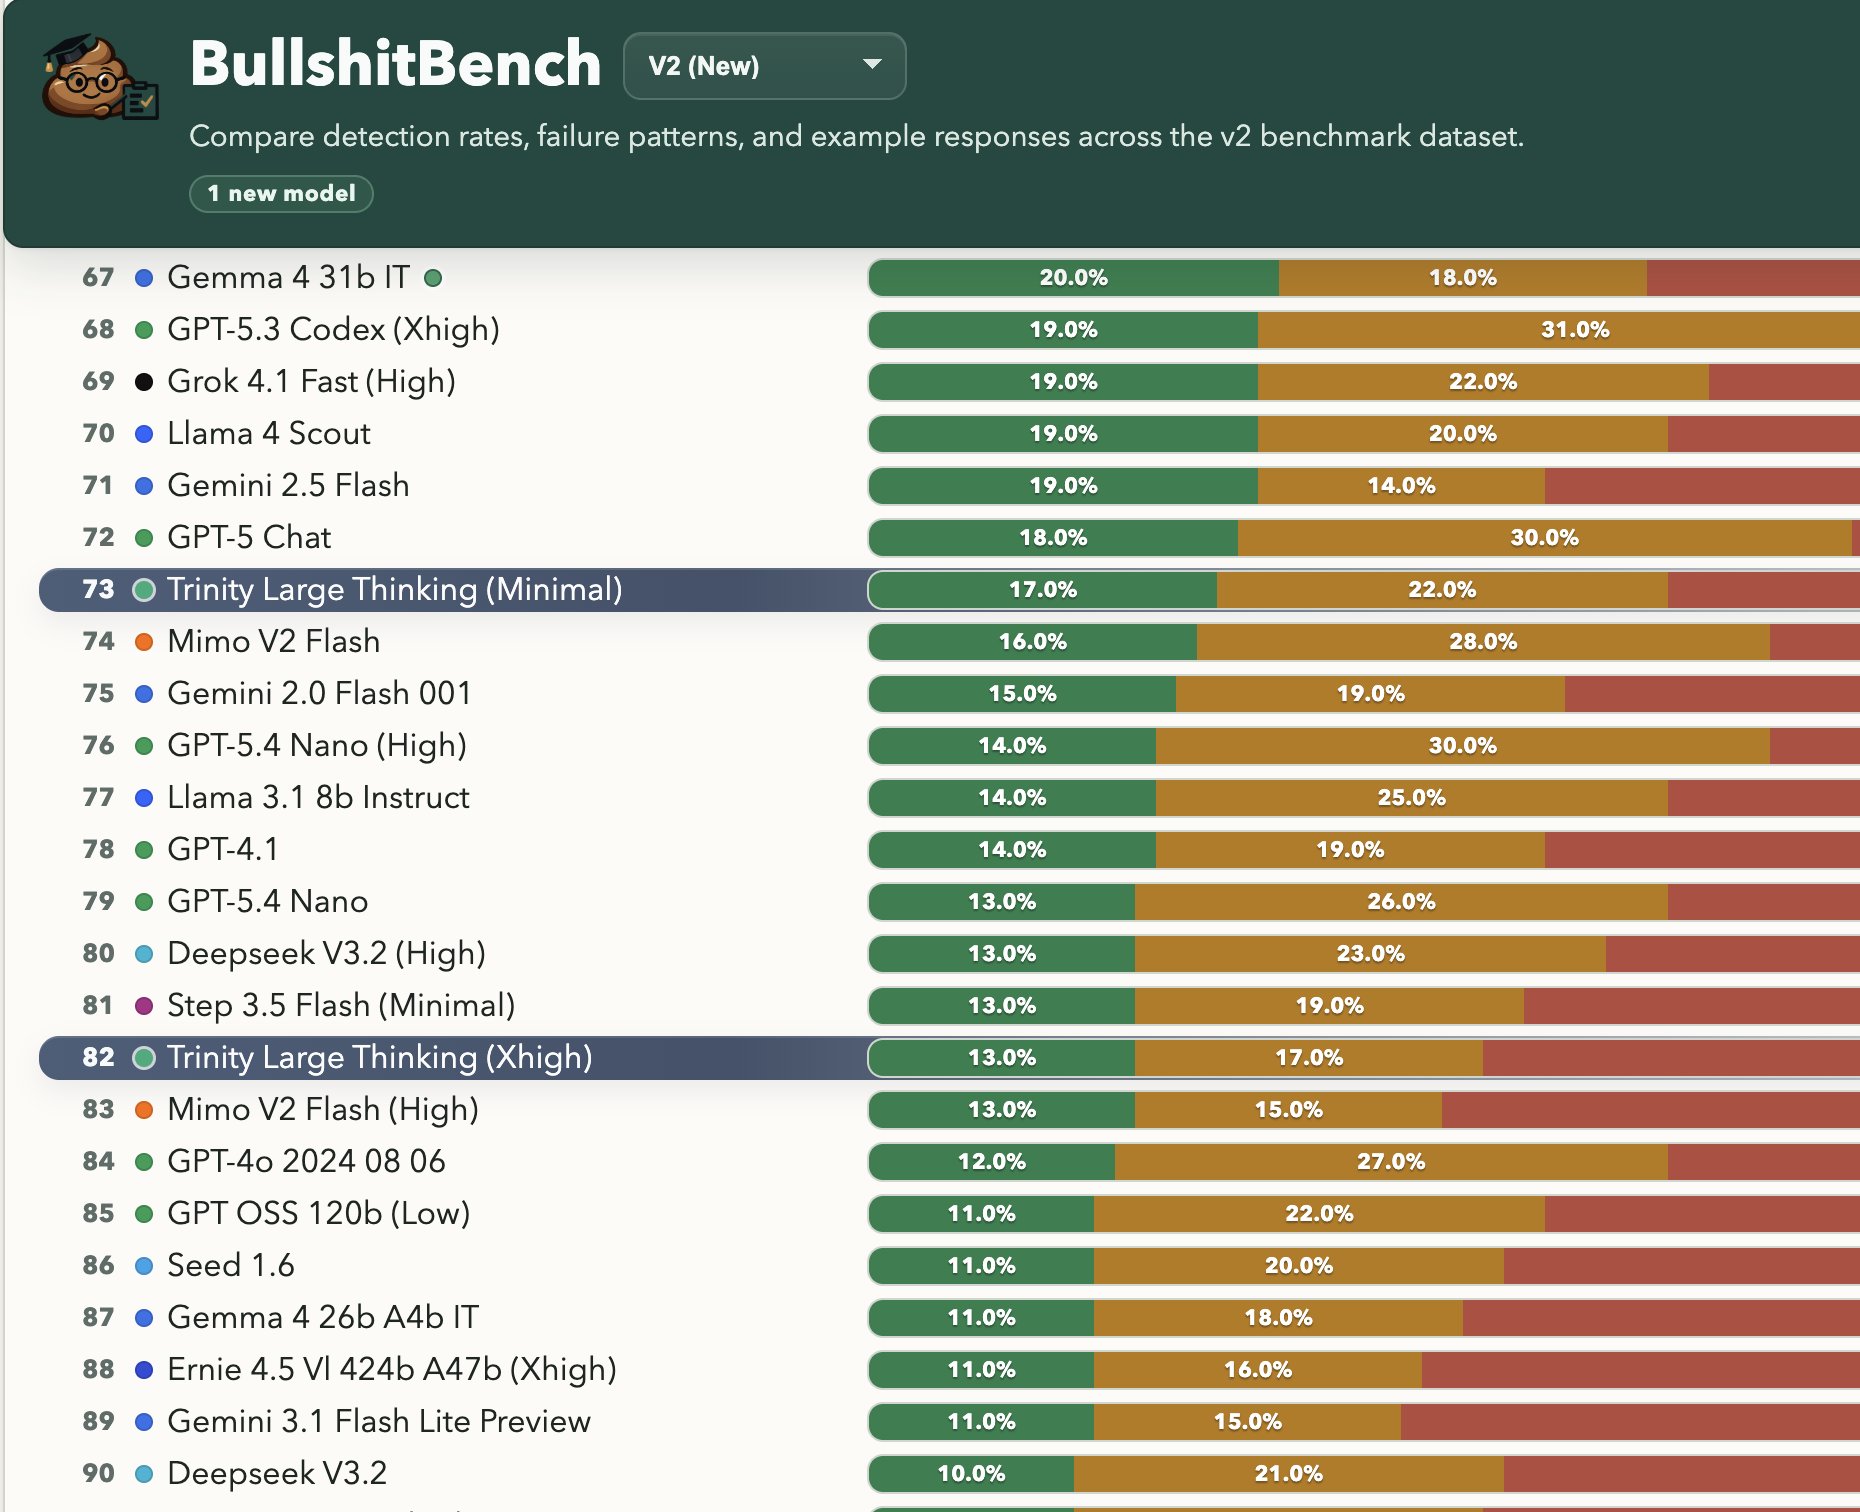
Trinity Large scores lower than expected with high thinking
By
–
Trinity Large also not scoring high – 73th and 82nd, no thinking is doing better than xhigh thinking.
-
Bullshit Benchmark Data Viewer and GitHub Repository Released
By
–
Data viewer: https://
petergpt.github.io/bullshit-bench
mark/viewer/index.v2.html
… Github with all data & code: -
Gemma 4 Scores Low on BullshitBench Evaluation
By
–
-
Gemma 4 versus Qwen 3.5: Early Performance Comparison
By
–
Vibe check on Gemma 4 now that we've had a few days to play with it – how does it hold up against Qwen 3.5?
-

Top Tech Stories: Startups, Apple Foldable, Netflix Gaming App
By
–
Top stories in tech today: – This startup plans to light up the night
– Apple’s foldable iPhone hits engineering snag – Netflix launches ad-free gaming app for kids
– The smart glasses without ‘creepy’ vibes – Quick hits on other tech news -
AI Optimization Playbook: Business Success and Responsible Innovation
By
–
HotRelease from @PacktDataML "The AI Optimization Playbook: Drive business success with proven AI strategies, best practices, and responsible innovation" See it at http://
amzn.to/45CtY4L 𝗧𝗮𝗯𝗹𝗲 𝗼𝗳 𝗖𝗼𝗻𝘁𝗲𝗻𝘁𝘀:
Understanding the Perils of AI Products