Trial and Error: Exploration-Based Trajectory Optimization for LLM Agents Song et al.: https://
arxiv.org/abs/2403.02502 #Artificialintelligence #DeepLearning #MachineLearning
AI
-

Exploration-Based Trajectory Optimization for LLM Agents
By
–
-

Institutional opportunities in digital assets and traditional finance bridge
By
–
Spoke at the Digital Assets: Realised in #HongKong on “Where are the biggest institutional opportunities?” #etf #stocks #bonds #MutualFunds Anndy Lian: “As Senior advisor to Peach Income fund, we bridge tradfi and digital markets globally.”
-
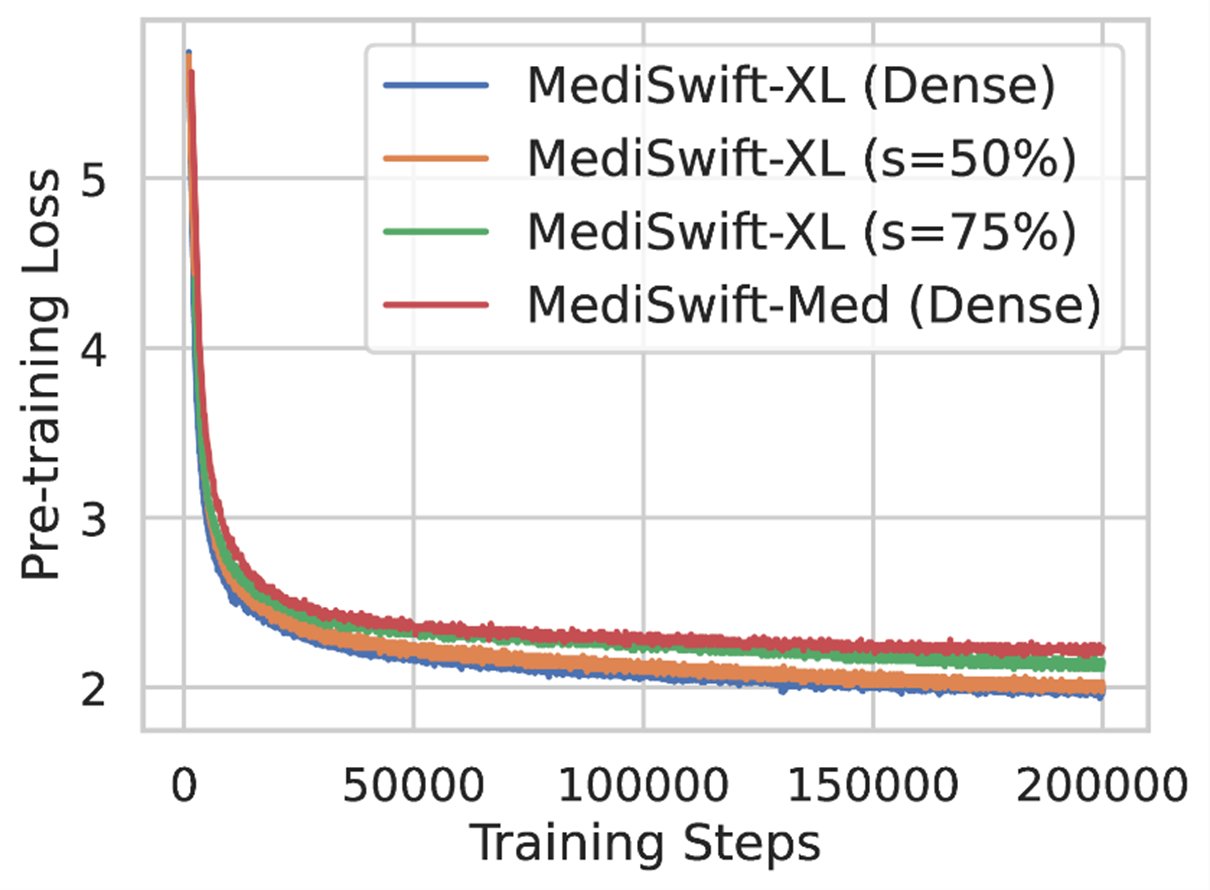
MediSwift-XL Sparse Model Outperforms Dense Competitor
By
–
(4/n) At 75% sparsity, MediSwift-XL outperforms the dense MediSwift-Med, despite having the same non-embedding parameters. This highlights the advantages of training larger but sparse models over smaller, densely parameterized models.
-
MediSwift Trained on Cerebras Wafer-Scale Cluster
By
–
(5/n) MediSwift was trained in three sizes (Med, Large, and XL), with dense and sparse variants, on a Cerebras Wafer-Scale Cluster with only a few configuration changes. Cerebras makes it easy to experiment and train production-ready models. Contact us to learn how we can help
-

MediSwift Achieves 75% Sparsity, Reduces Training FLOPs by 2.5x
By
–
(2/n) MediSwift capitalizes on our most recent innovations in sparsity, inducing up to 75% unstructured weight sparsity during in-domain pre-training on biomedical texts. This results in a 2-2.5x reduction in the required training FLOPs. Blog: https://
cerebras.net/blog/sparsity-
made-easy-introducing-the-cerebras-pytorch-sparsity-library
… -

Dense Fine-Tuning Boosts MediSwift Biomedical Task Performance
By
–
(3/n) Dense fine-tuning and soft prompting enhance the performance of sparsely pre-trained MediSwift models on biomedical tasks (e.g., PubMedQA). This ensures high accuracy, thereby improving the efficiency-accuracy Pareto frontier. Pubmed QA leaderboard: https://
pubmedqa.github.io -
MediSwift: Sparse Biomedical Language Models Reduce Computational Costs
By
–
(1/n) Introducing MediSwift, the first suite of biomedical language models that employ sparse pre-training techniques to significantly reduce computational costs, while outperforming existing models up to 7B parameters on benchmark tasks such as PubMedQA. Paper:
-

LLMs Outperform Human Experts in Neuroscience Prediction
By
–
Large language models surpass human experts in predicting neuroscience results Luo et al.: https://
arxiv.org/abs/2403.03230 #ArtificialIntelligence #DeepLearning #MachineLearning -
Groq Processors Power OpenRouter Nitro Models With Impressive Speed
By
–
🚀 Thrilled to see our processors powering the latest Nitro models at @OpenRouterAI! The new speed benchmarks are impressive. It's exciting to be at the forefront of AI innovation with such high caliber developers. https://t.co/Gtfhy5fB1q
— Groq Inc (@GroqInc) 8 mars 2024Thrilled to see our processors powering the latest Nitro models at @openrouter
! The new speed benchmarks are impressive. It's exciting to be at the forefront of AI innovation with such high caliber developers. -
Groq’s Brighter Outlook Compared to Stranger in a Strange Land
By
–
"The man who introduces grok to Earth comes to an unpleasant end in Stranger in a Strange Land. For Groq, the outlook seems brighter." — @iainwmorris