
9/ Design2Code Investigates the use of multimodal LLMs for converting a visual design into code implementation which is key for automating front-end engineering.
AI
-
TripoSR: Fast 3D Mesh Generation from Single Images
By
–
10/ TripoSR
— DAIR.AI (@dair_ai) 10 mars 2024
A transformer-based 3D reconstruction model for fast feed-forward 3D generation; it can produce 3D mesh from a single image in under 0.5 seconds; improvement includes better data processing, model design, and training.https://t.co/5VL6kdC12410/ TripoSR A transformer-based 3D reconstruction model for fast feed-forward 3D generation; it can produce 3D mesh from a single image in under 0.5 seconds; improvement includes better data processing, model design, and training.
-
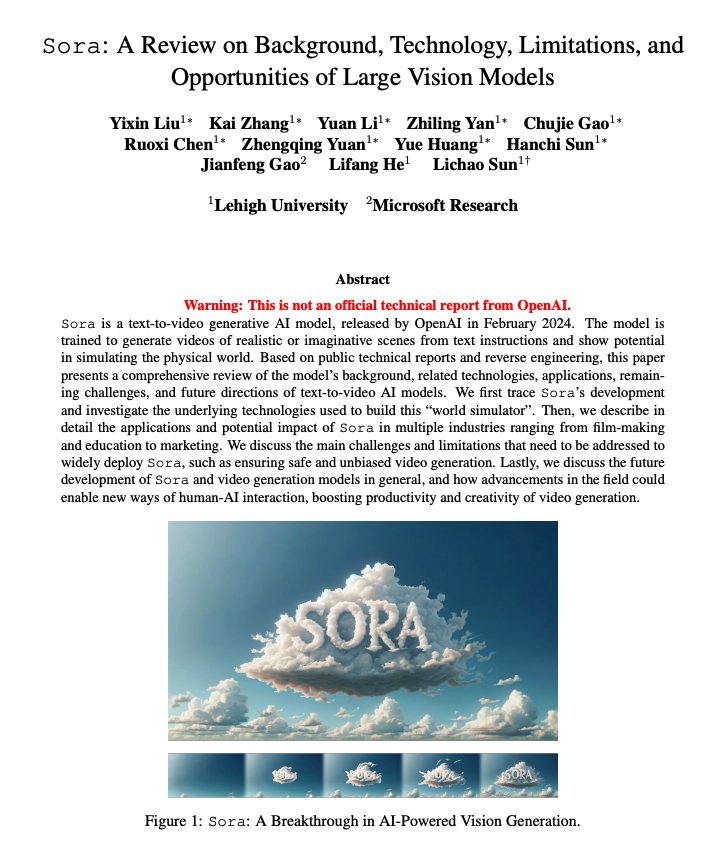
Sora Overview: Key Developments in Large Vision Models
By
–
7/ Sora Overview A comprehensive review of Sora and some of the key developments powering this model, including limitations and opportunities of large vision models.
-
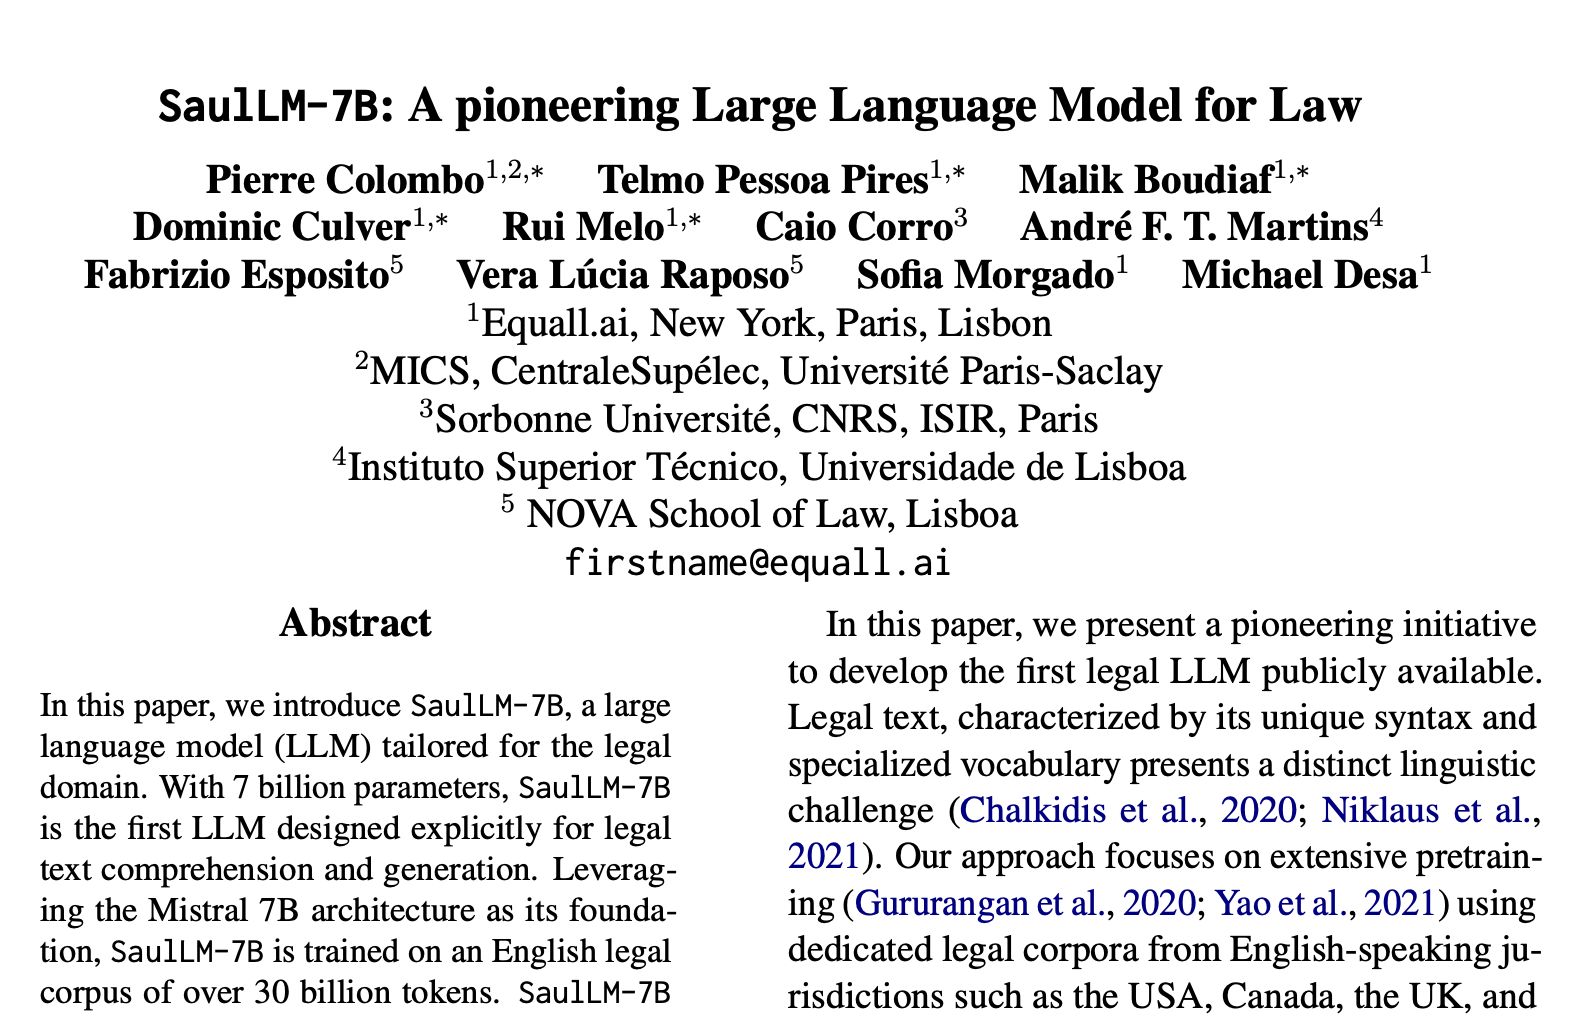
SaulLM-7B: Legal Domain Language Model
By
–
8/ LLM for Law – introduces SaulLM-7B, an LLM for the legal domain explicitly designed for legal text comprehension and generation; presents an instructional fine-tuning method that leverages legal datasets to further enhance performance in legal tasks.
-
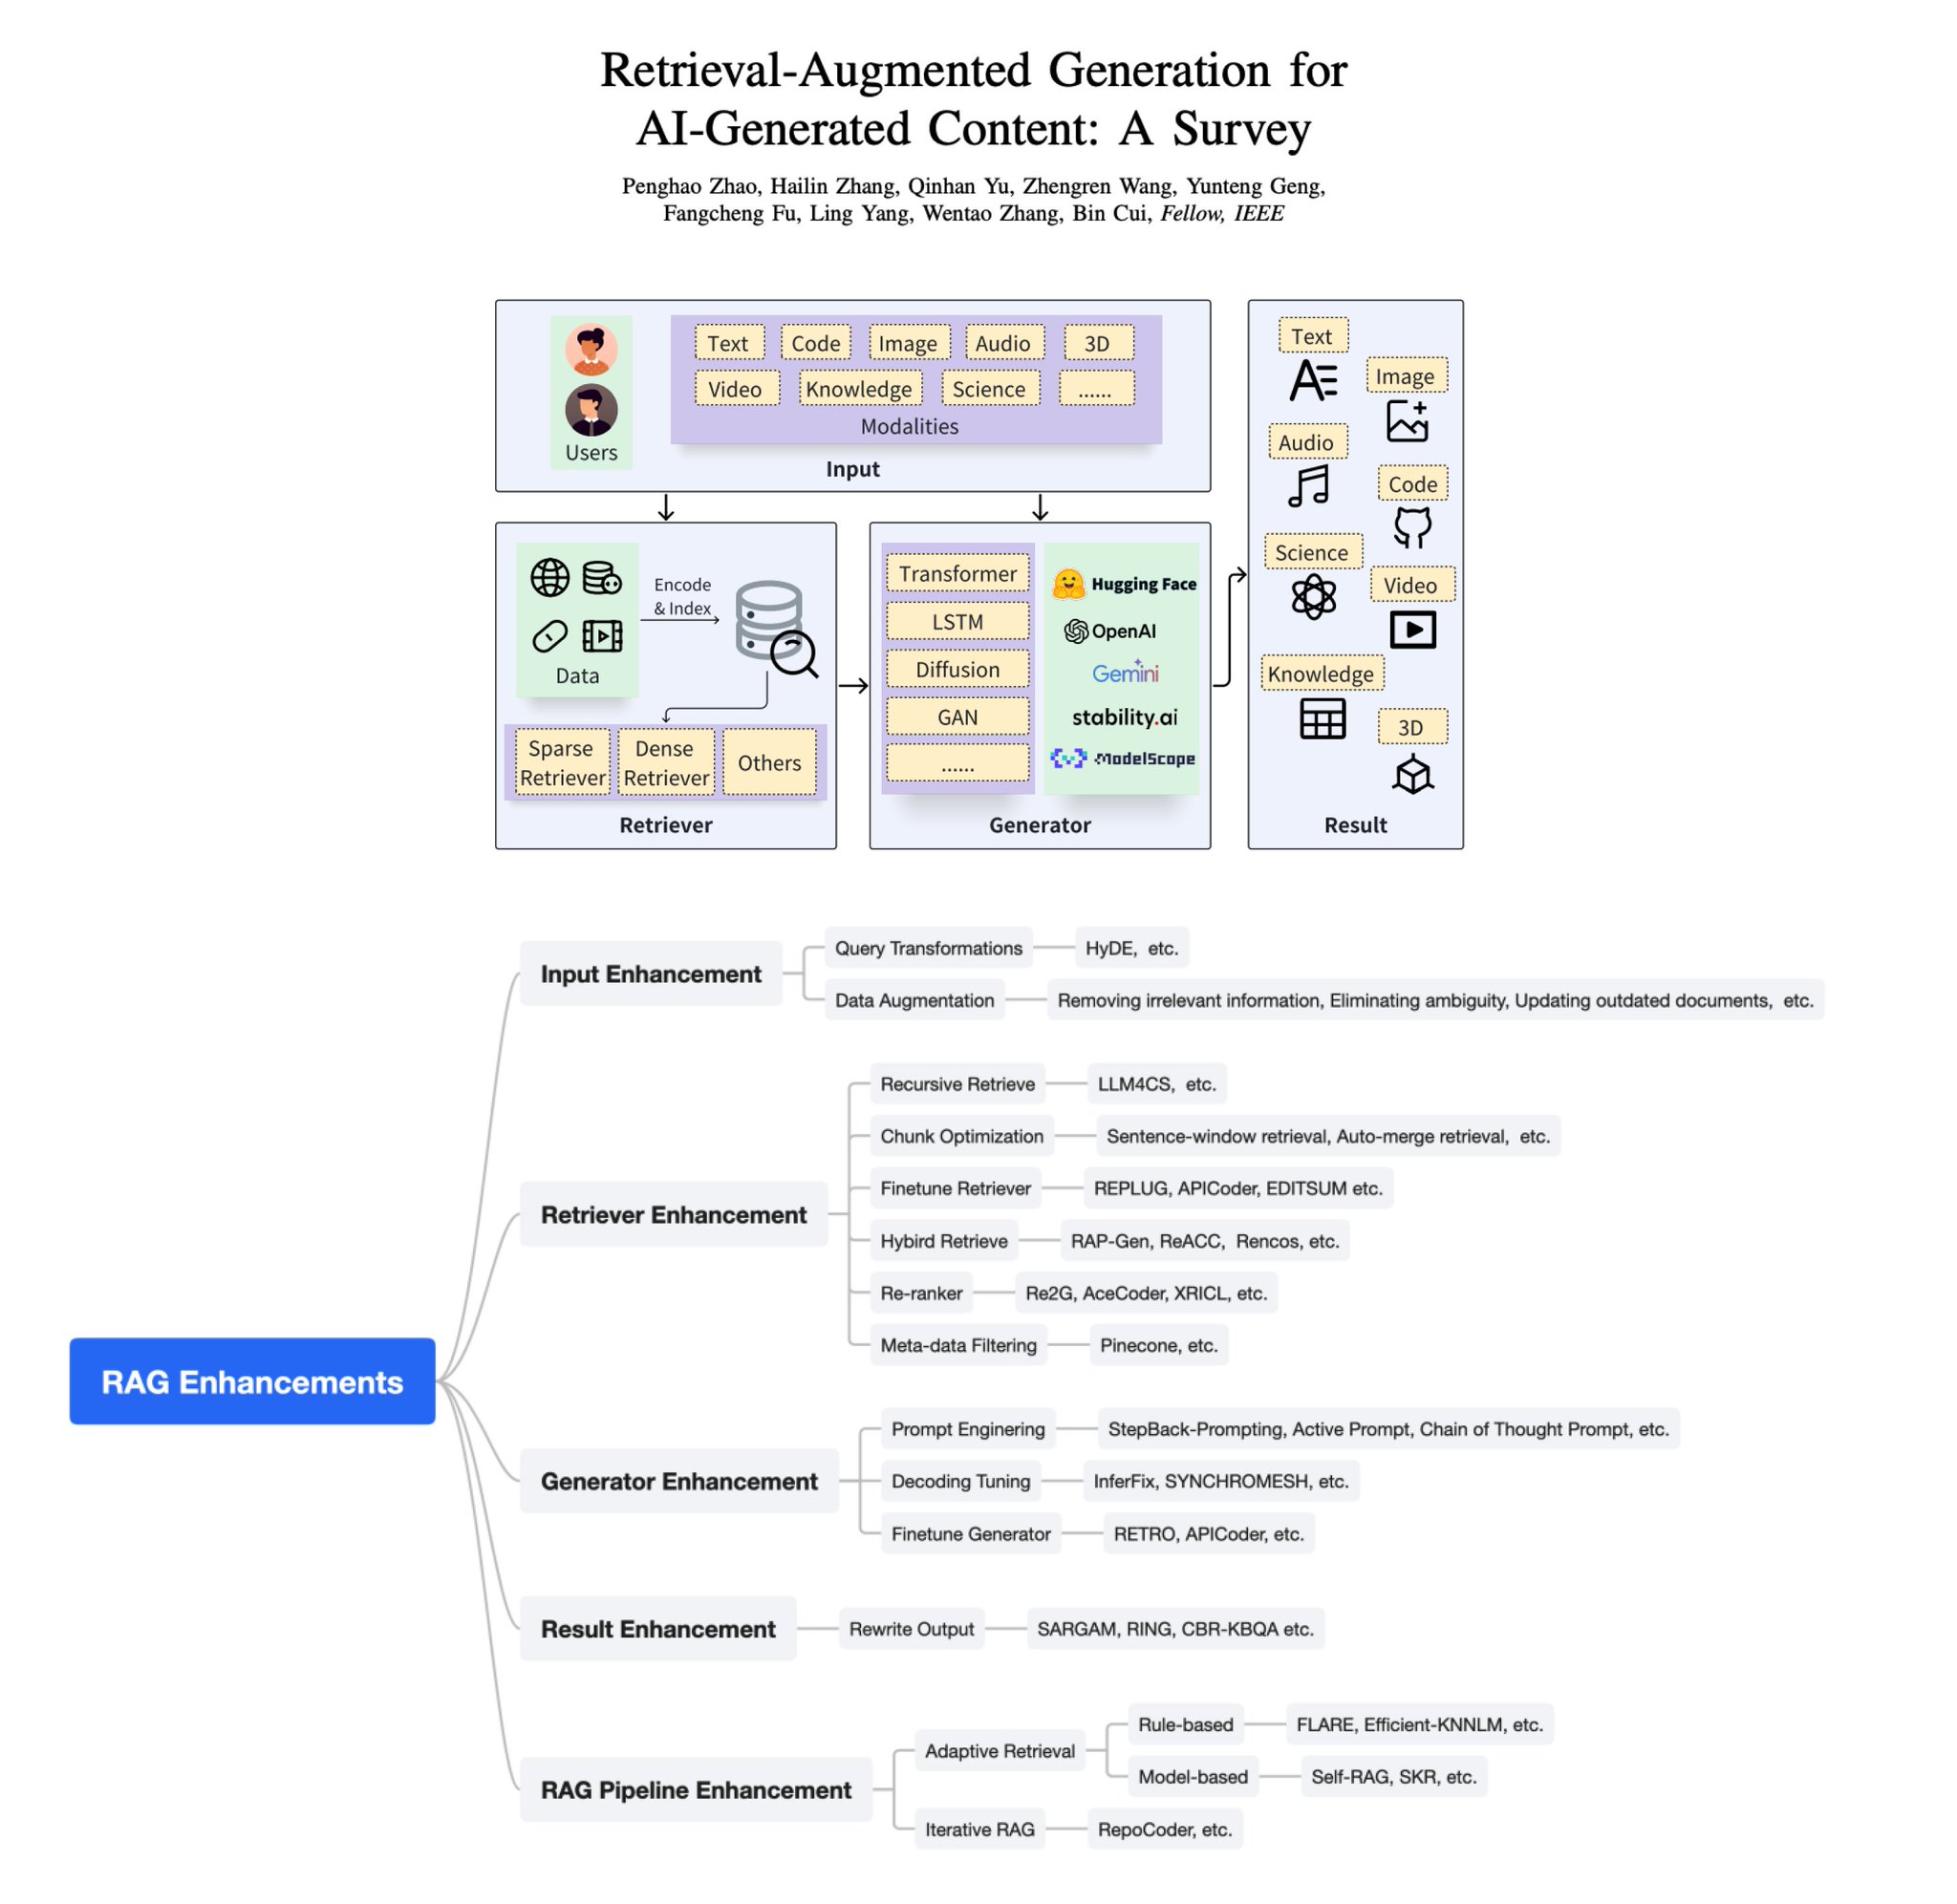
RAG for AI-Generated Content: Overview and Enhancements
By
–
5/ RAG for AI-Generated Content Provides an overview of RAG used in different generation scenarios like code, image, and audio, including a taxonomy of RAG enhancements with reference to key papers.
-
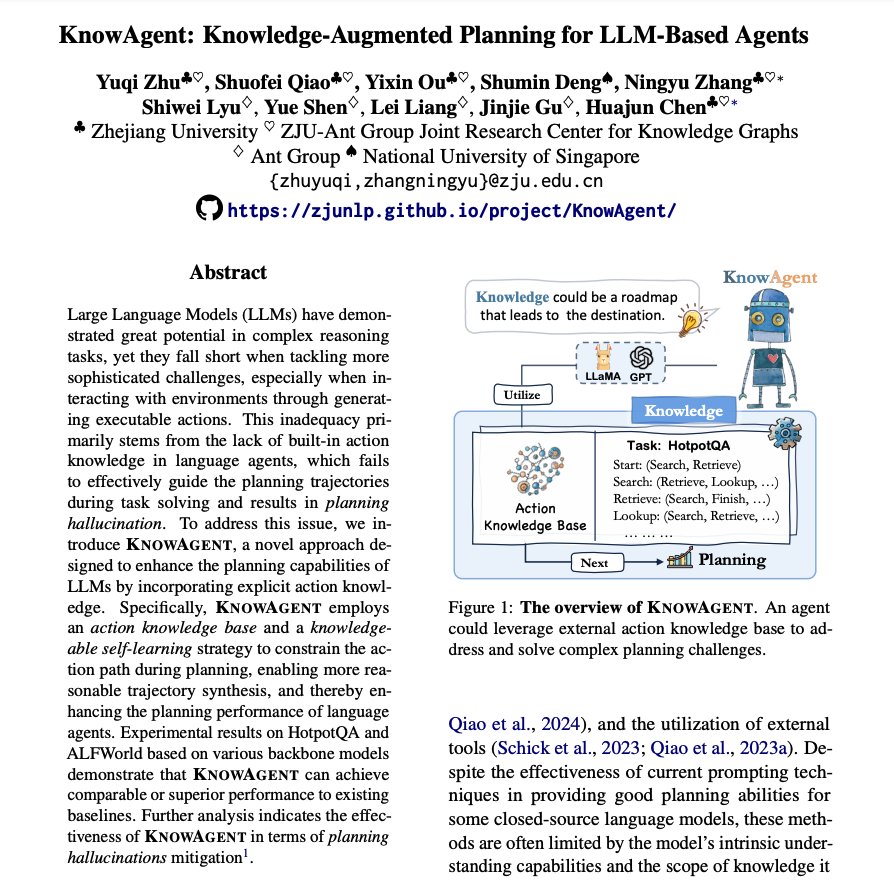
KnowAgent Enhances LLM Planning Through Action Knowledge Base
By
–
6/ KnowAgent Enhances the planning capabilities of LLMs through explicit action knowledge; uses an action knowledge base and knowledgeable self-learning to guide action generation, mitigate planning hallucination, and enable continuous improvement.
-
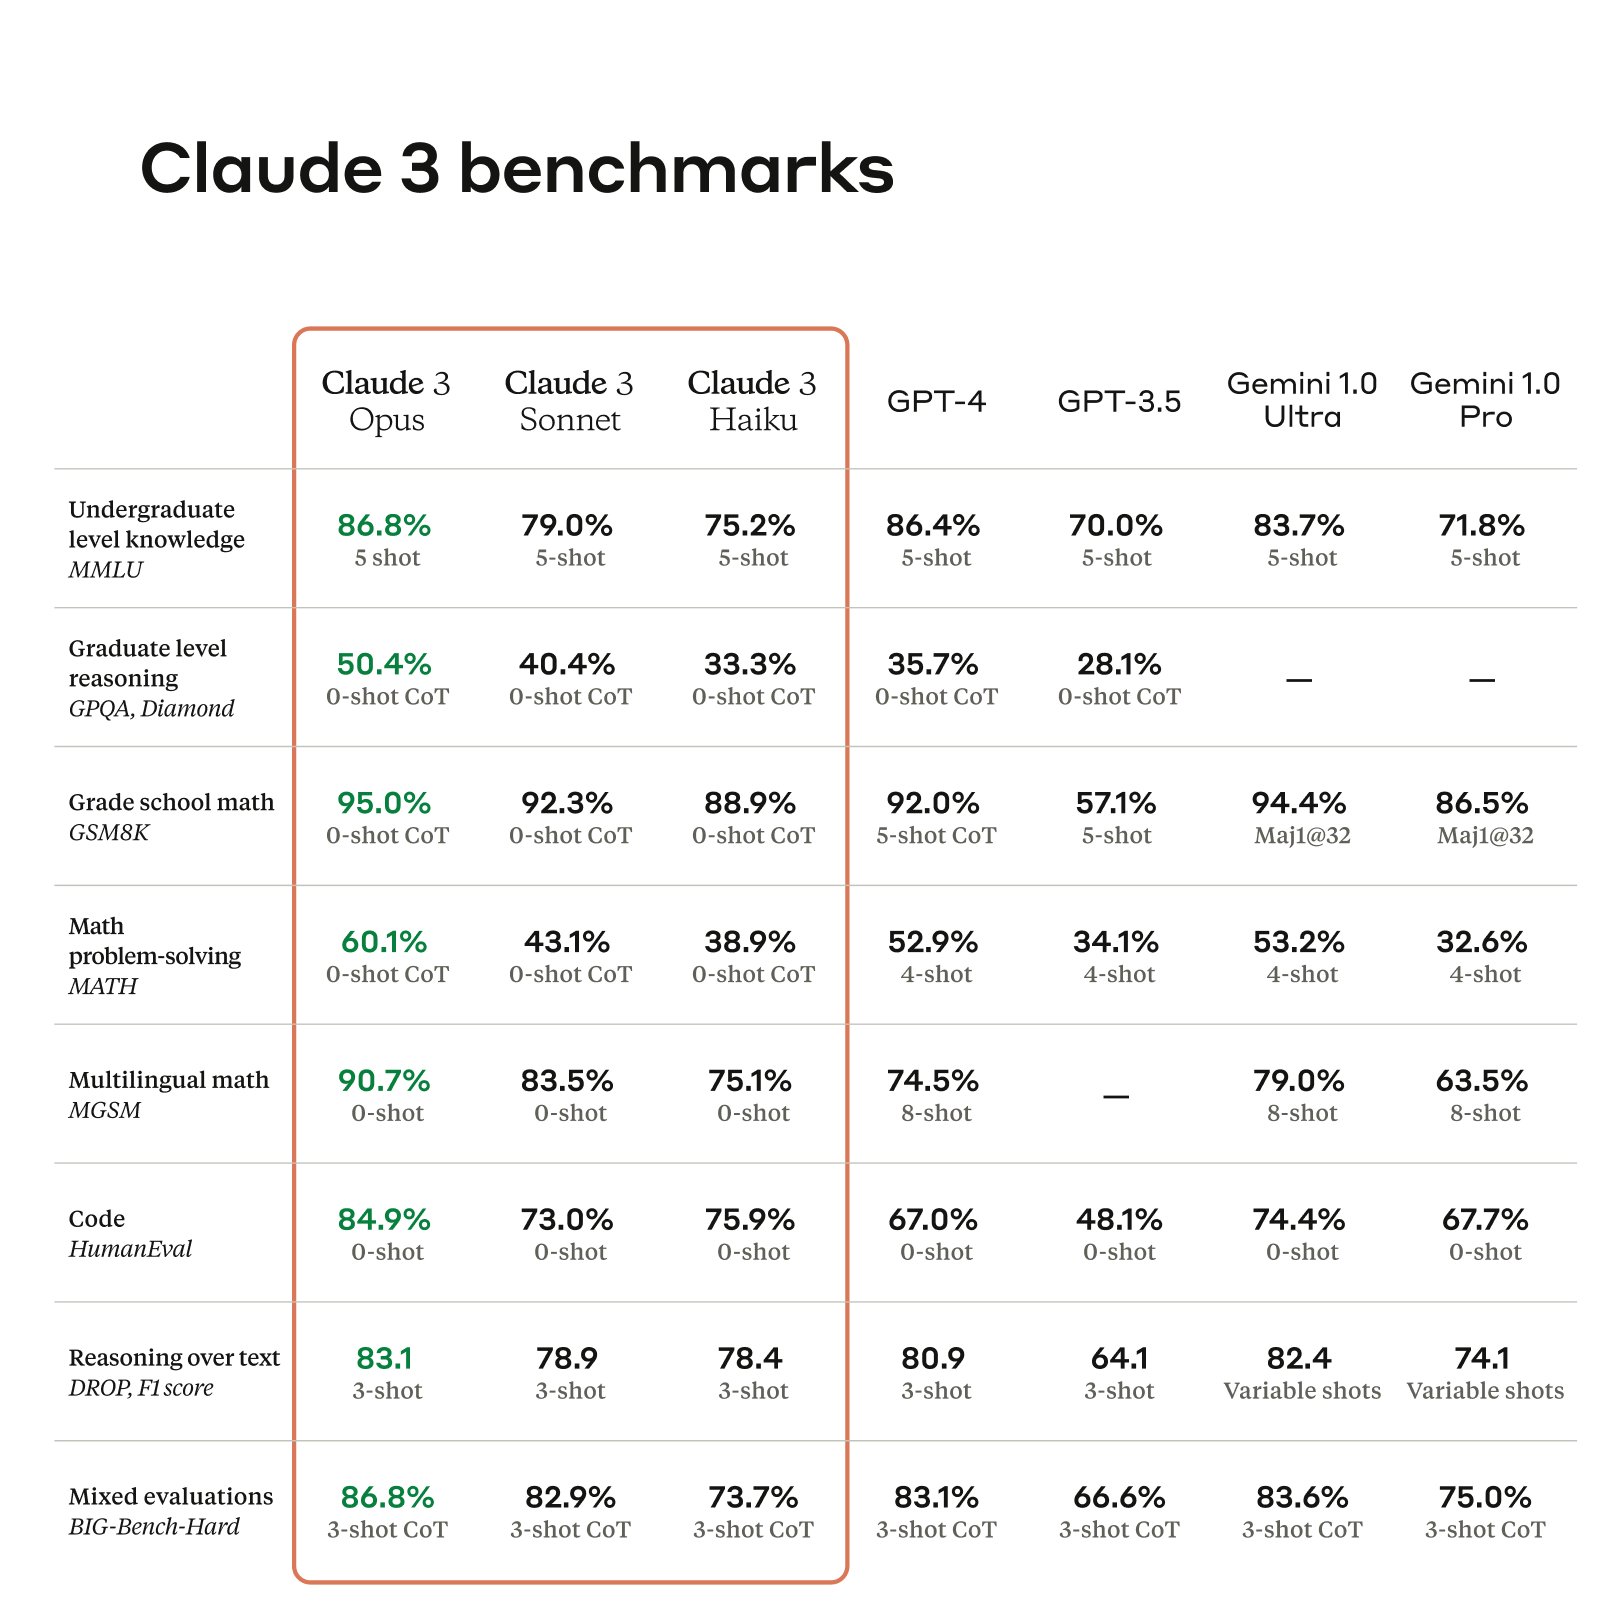
Claude 3 family outperforms GPT-4 on key benchmarks
By
–
1/ Claude 3 Consists of a family of three models (Claude 3 Haiku, Claude 3 Sonnet, and Claude 3 Opus); Claude 3 Opus (the strongest model) seems to outperform GPT-4 on common benchmarks like MMLU and HumanEval.
-

Benchmark Evaluation Reveals Significant Reasoning Gap in LLMs
By
–
2/ Robust Evaluation of Reasoning Proposes functional benchmarks for the evaluation of the reasoning capabilities of LLMs; finds that there is a reasoning gap with current models from 58.35% to 80.31%.
-
Top ML Papers of the Week: Claude 3, KnowAgent, Design2Code
By
–
The Top ML Papers of the Week (March 4 – March 10): • Claude 3
• KnowAgent
• LLM for Law
• Design2Code
• RAG Enhancements Overview
• Robust Evaluation of Reasoning
… -
OT Cybersecurity Investments: Former Defense Secretary Perspectives
By
–
Driving OT Cybersecurity Investments – Perspectives from the Former US Secretary of Defense. An interview with Lucian Niemeyer, former Assistant Secretary of Defense and current CEO of Building Cyber Security. #buildingcybersecurity_ics #S4x24 https://
x.com/i/broadcasts/1
BdGYrdYnolJX
…