Yeah lots of LLMs are trained on synthetic data these days, especially at the fine-tuning stage – but that's deliberate, the open question for me is still the impact of accidental synthetic data in the larger pre-training data pool
AI
-
Web crawler code sophistication and search engine iteration
By
–
Yeah I think it's a signal that their custom crawler code is full pretty unsophisticated – I would guess it took search engines like Google and Bing years of iteration to get their crawlers to avoid all of the possible dumb mistakes like that
-
Smart data crawling strategy local iteration analysis
By
–
A dumb crawler doesn't necessarily mean that they're not doing something smarter with the content once it's been crawled – it's generally a good idea to crawl once and then iterate on analysis against your local copy
-
TMLR Paper with Experiments, Data and Code Resources
By
–
More experiments can be found in our TMLR paper: https://
arxiv.org/abs/2310.14540
Data and code: https://
huggingface.co/datasets/yyama
da/SpatialEvalLLM
…, https://
github.com/runopti/Spatia
lEvalLLM
…
Special thanks to @AndrewLampinen for helpful discussion and advice!
7/n -

Human Baselines Outperform GPT-4 on Non-Square Grid Tasks
By
–
We also compare LLMs with human baselines. Although human responses are not perfect, they outperform GPT-4 (0314) by a substantial margin. Furthermore, like GPT-4 (0314), non-expert humans struggle with non-square grid shapes.
6/n -
LLM Performance Variability Across Different Spatial Structures
By
–
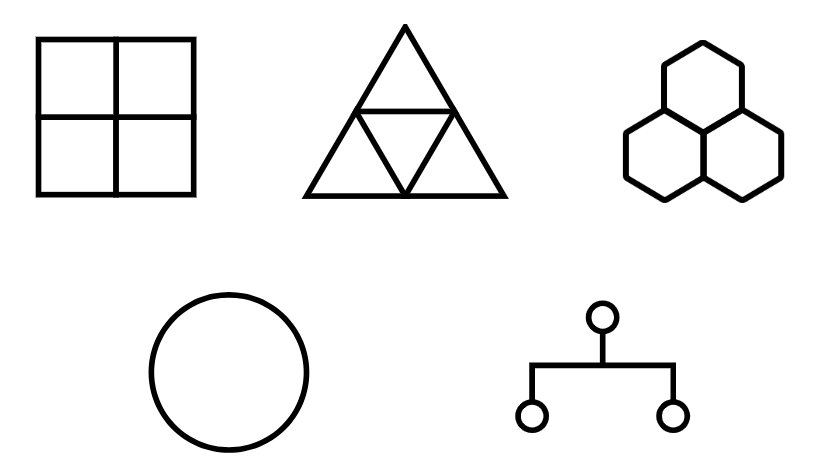
We examine various spatial structures (squares, triangles, hexagons, rings, and trees), which reveal substantial variability in LLM performance across different structures. (GPT-4 here is 0314)
5/n -
Loop Closure in Square Grid: Claude 3 vs GPT-4 Comparison
By
–
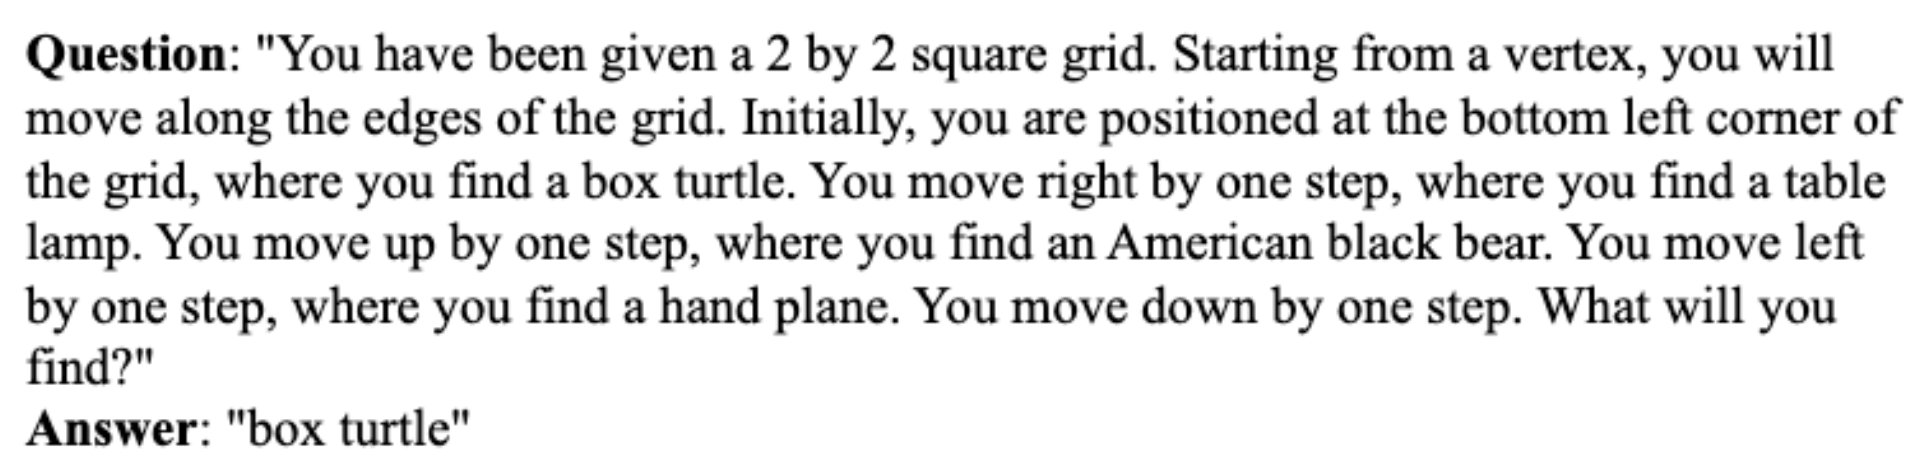
Answering this question correctly demonstrates an understanding of loop closure in the square grid, which is a fundamental aspect of this spatial structure. The Claude 3 vs. GPT-4 comparison above is tested on a 3 by 3 square grid w/ 8 navigational steps. 4/n
-
Sequential Transitions Enable LLM Spatial Understanding
By
–
Motivated by this, we hypothesize that presenting sequential transitions might be enough for LLMs to achieve spatial understanding. e.g. if a model comprehends a square map’s structure, it should be able to answer the question shown in the image. 3/n
-
Evaluating Spatial Understanding in Text-Only Language Models
By
–
Evaluating the text-only models’ understanding of spatial information is tricky because text-only LLMs do not explicitly interact with the physical world. But humans can implicitly learn representations that mirror spatial structures only from sequential navigational data. 2/n
-
Claude 3 vs GPT-4: Spatial Reasoning Task Comparison
By
–
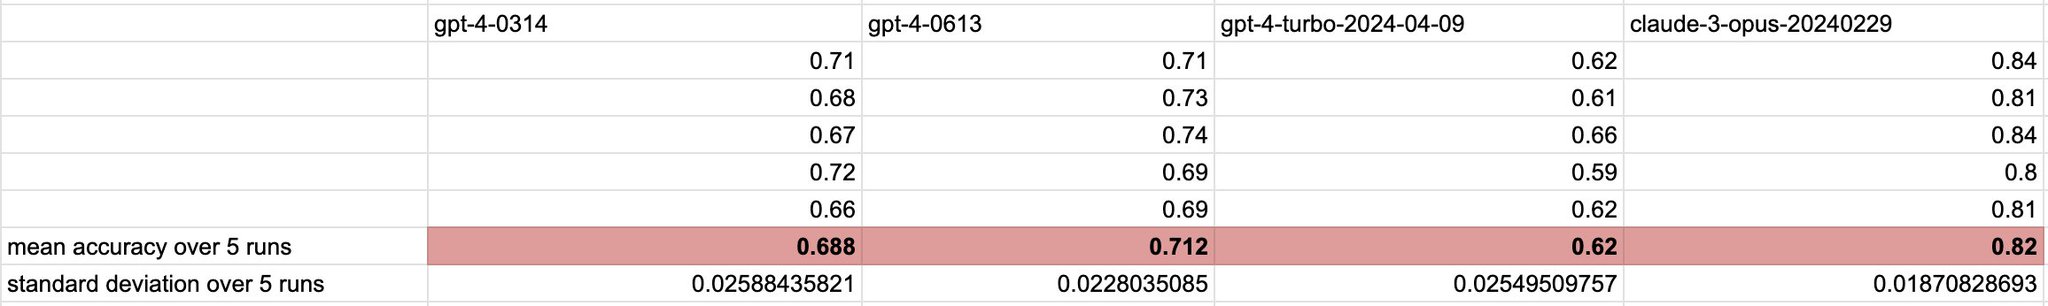
A quick comparison b/w Claude 3 and GPT-4 on a spatial reasoning task (n=100, 5 run average w/ temp=1.0). Seems like Claude 3 still beats GPT-4, and gpt-4-turbo performs worse than gpt-4-0613. Interesting contrast to their perf in chat & coding, where GPT-4 comes out ahead. 1/n