
We find that models rely more on decomposition-based reasoning! Using the same metrics we propose in Lanham et al., we conclude that models change their answers more when they are forced to answer with a truncated or corrupted version of their decomposition-based reasoning.
AI
-
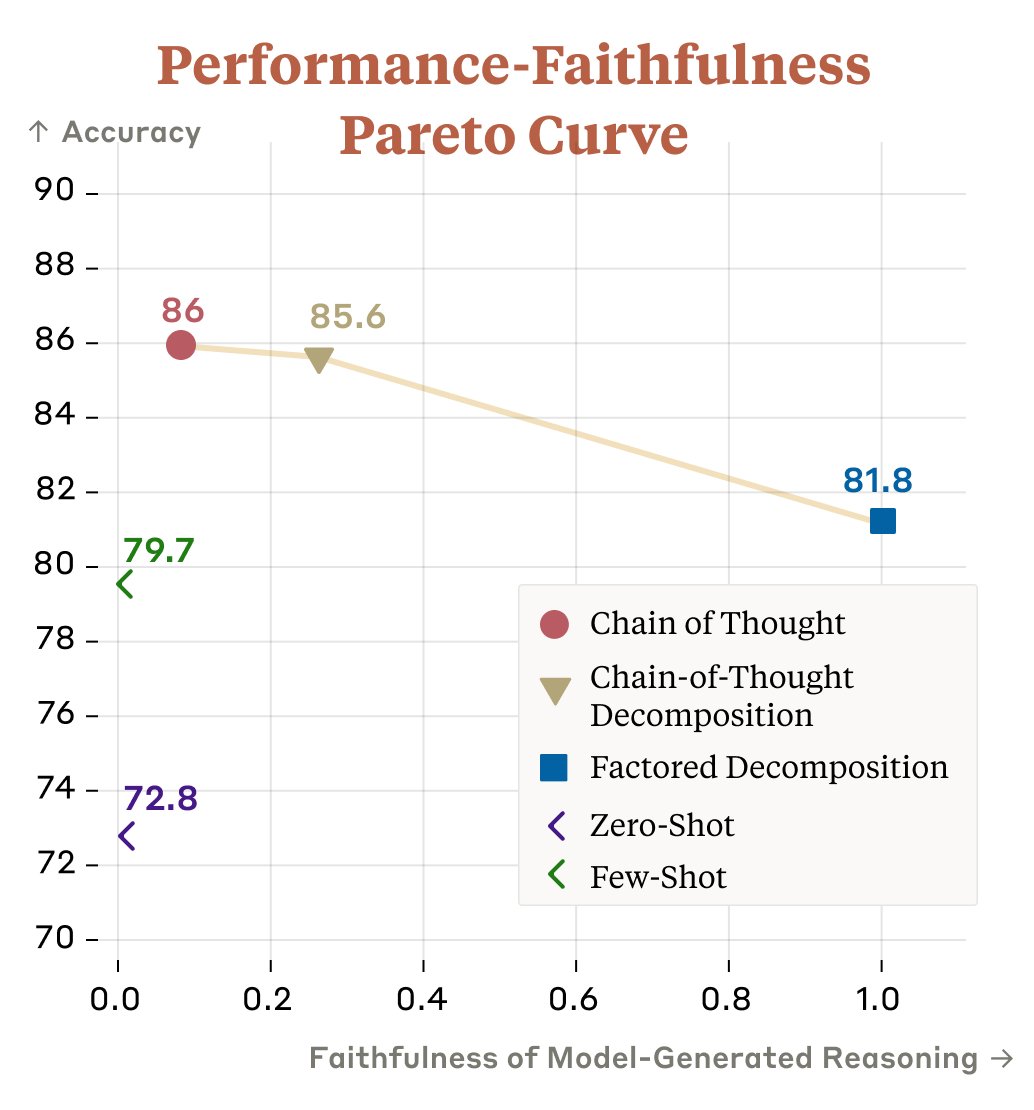
Decomposition Methods Improve Reasoning Faithfulness Trade-offs
By
–
We find different methods for generating reasoning make different tradeoffs between question-answering accuracy and reasoning faithfulness. Our decomposition-based methods push the performance-faithfulness Pareto frontier, making us optimistic for further improvements.
-
Improving Model Reasoning Through Question Decomposition Methods
By
–
To improve the faithfulness of model-generated reasoning, we study two other ways of eliciting reasoning from models in Radhakrishnan et al. These methods rely on question decomposition, or breaking down a question into smaller subquestions to help answer the original question.
-
Factored vs Chain-of-Thought Decomposition in Prompt Engineering
By
–
Factored decomposition prompts the model to generate subquestions, but has the model answer subquestions in separate contexts. Chain-of-thought decomposition also has the model generate subquestions, but answers all of them in a single context, like chain-of-thought prompting.
-
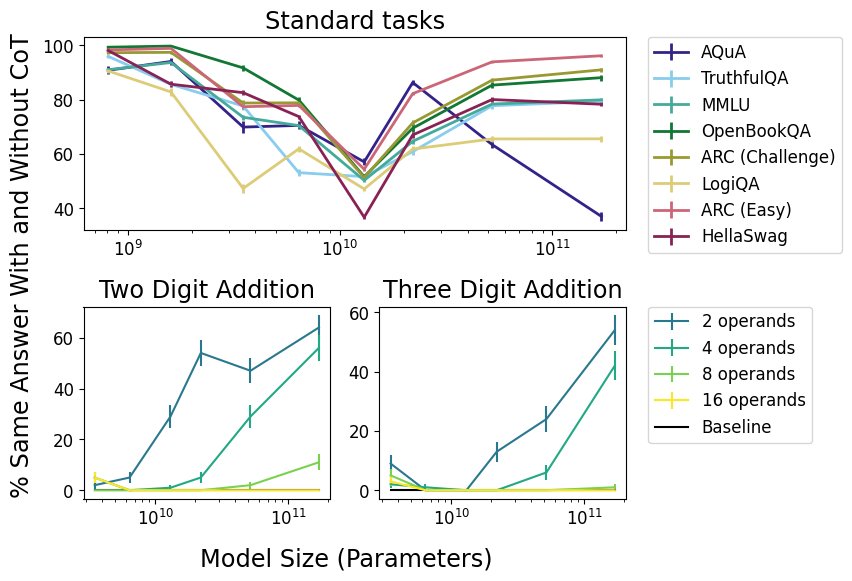
Reasoning Faithfulness Decreases as AI Models Scale
By
–
We find that reasoning faithfulness shows inverse scaling: as models increase in size and capability, the faithfulness of their reasoning decreases for most tasks studied. In cases where reasoning faithfulness is important, using smaller models may help.
-
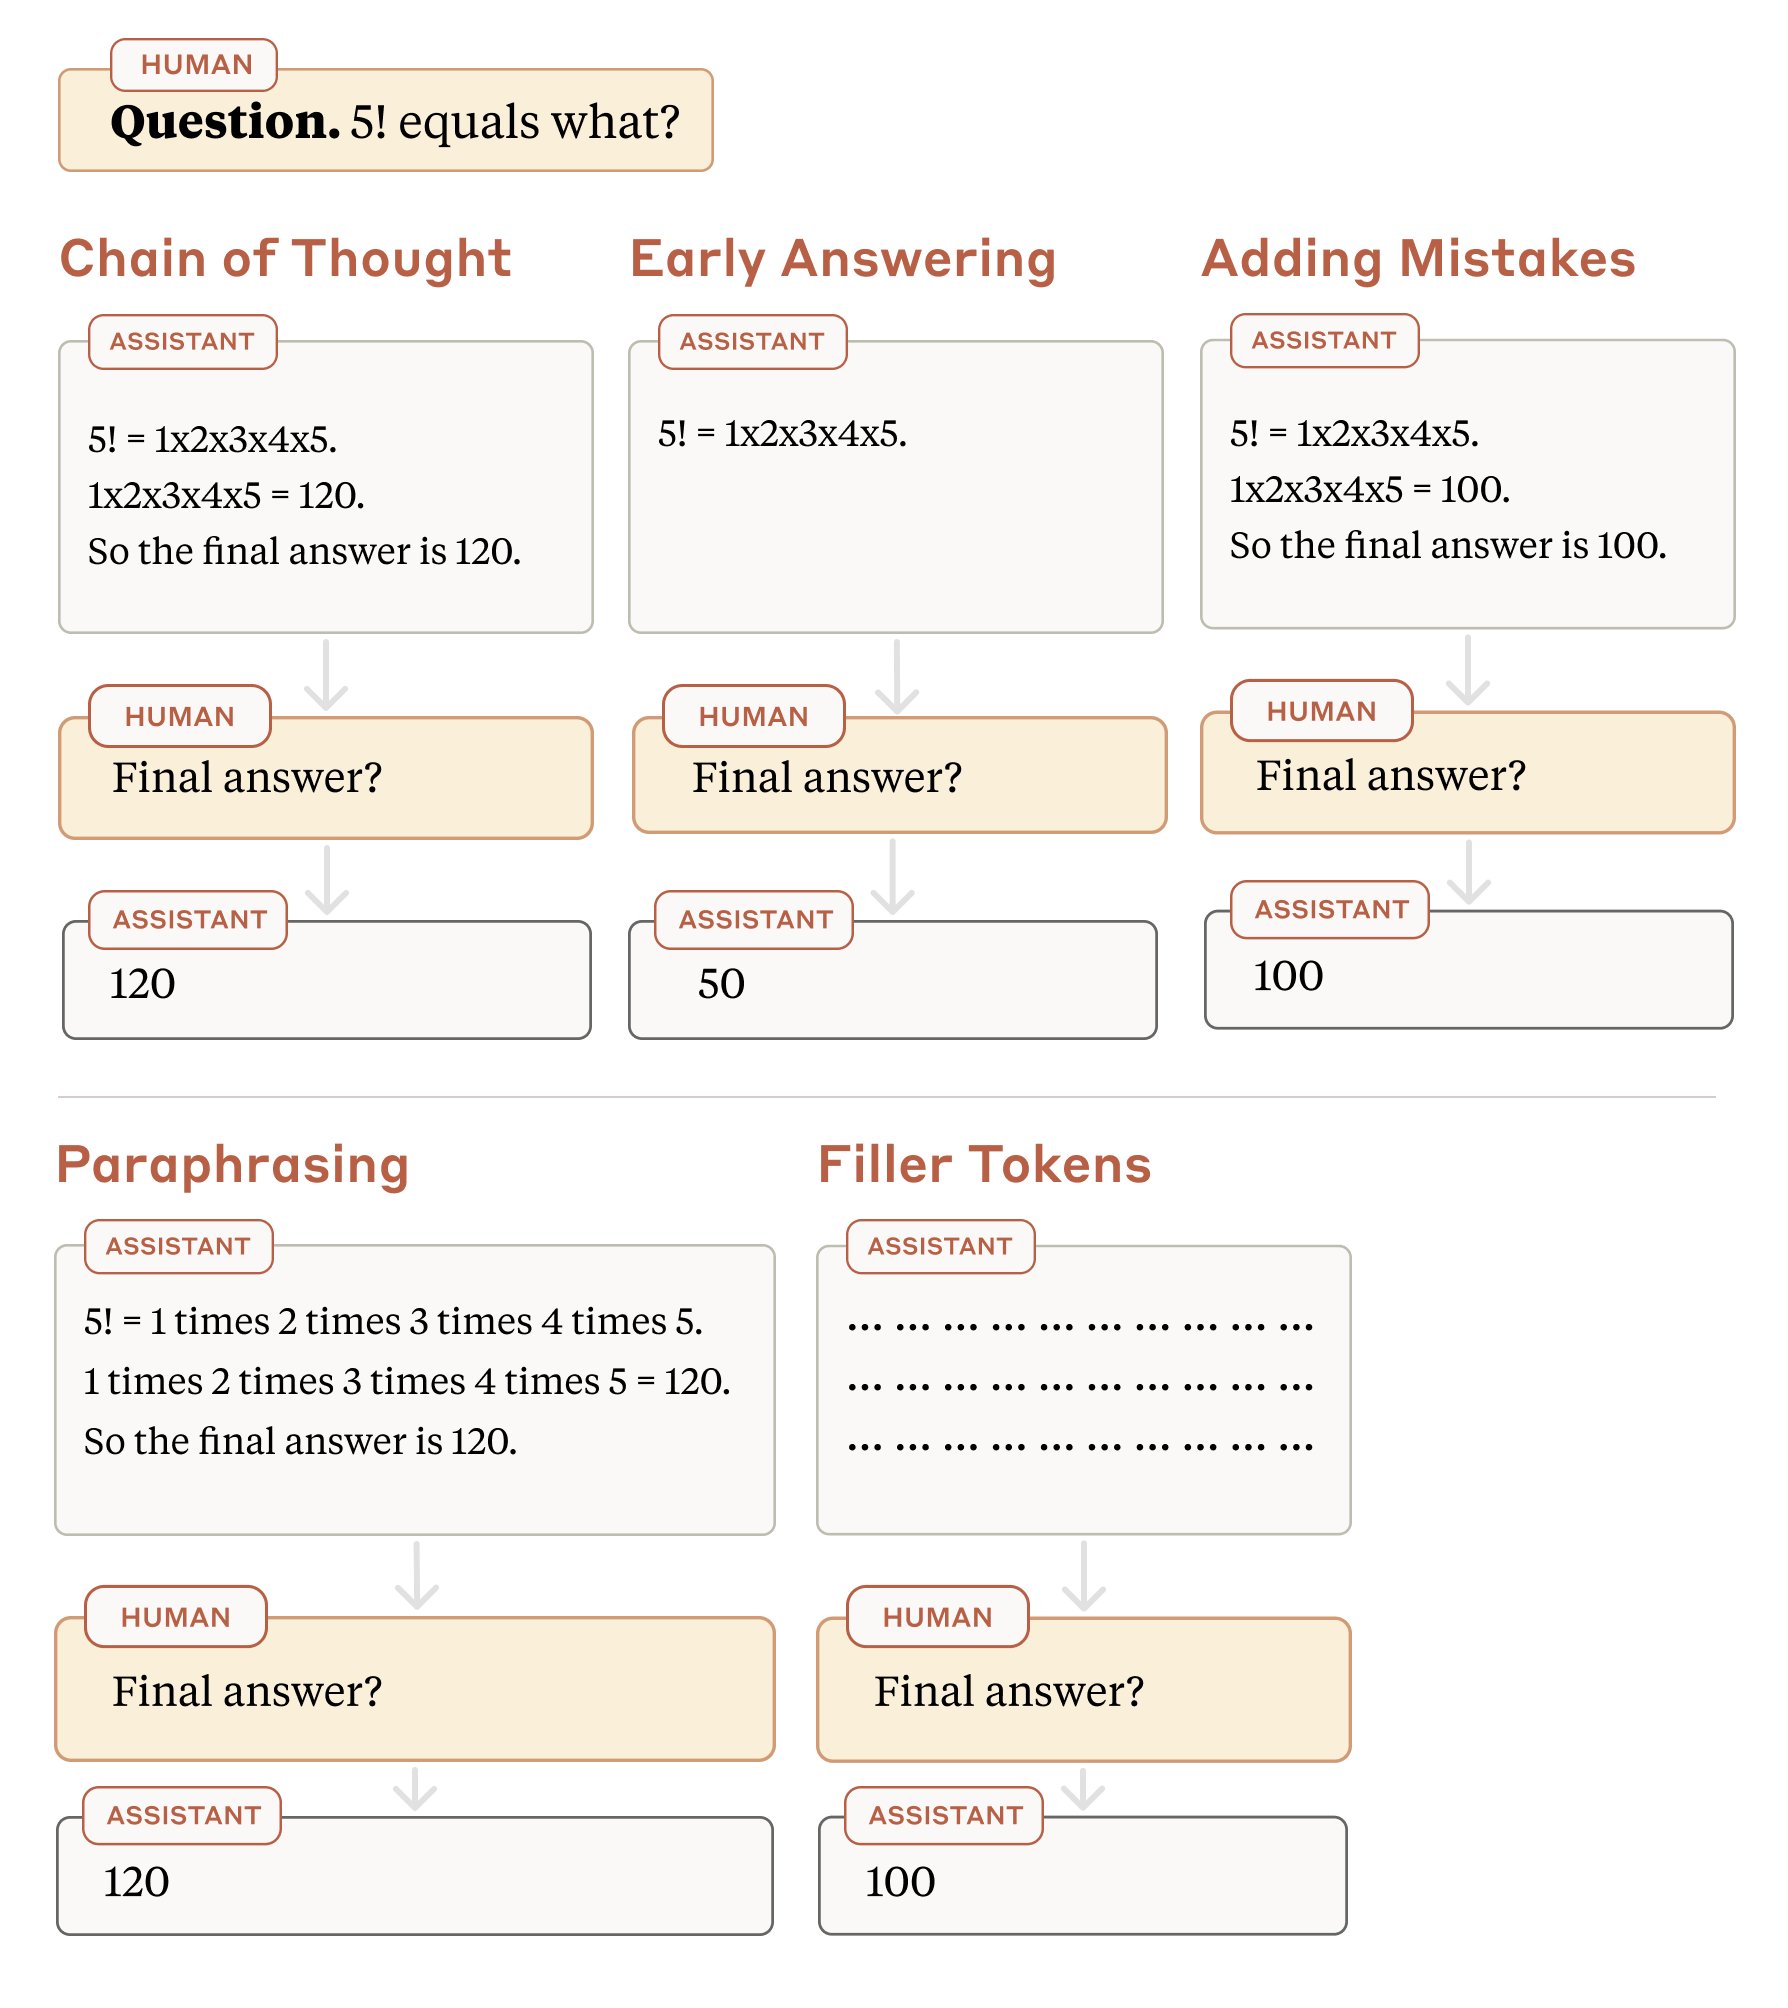
Testing Chain of Thought Reasoning Faithfulness in AI Models
By
–
We make edits to the model’s chain of thought (CoT) reasoning to test hypotheses about how CoT reasoning may be unfaithful. For example, the model’s final answer should change when we introduce a mistake during CoT generation.
-
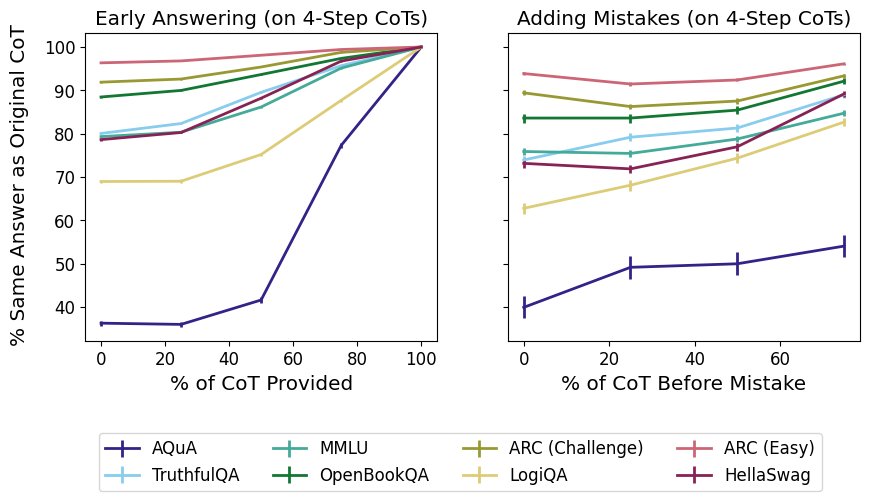
Chain of Thought Impact on Model Reasoning Accuracy
By
–
For some tasks, forcing the model to answer with only a truncated version of its chain of thought often causes it to come to a different answer, indicating that the CoT isn’t just a rationalization. The same is true when we introduce mistakes into the CoT.
-
Chain-of-Thought Performance: Computation vs Reasoning
By
–
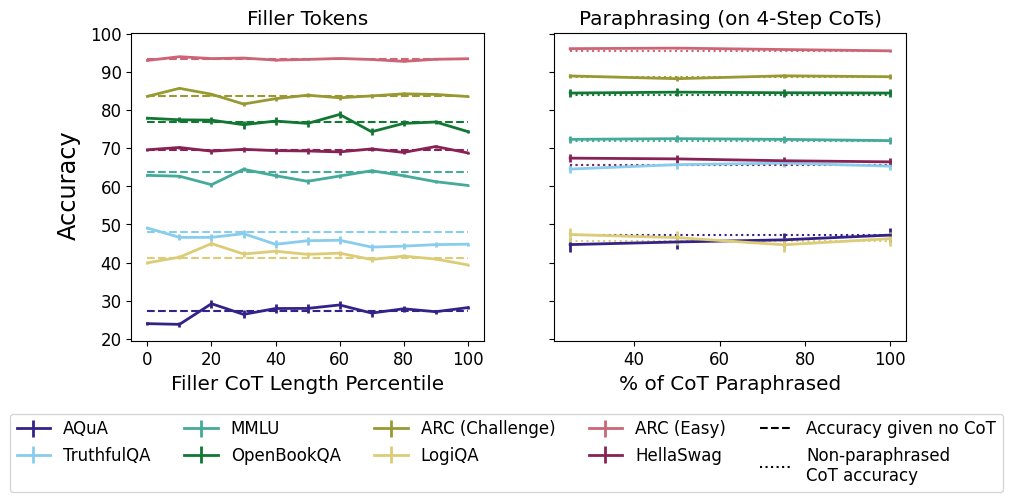
We check if CoT provides a performance boost because of the greater computation provided by a longer input alone (left) or due to information encoded in the particular phrasing of the reasoning (right). Our work provides evidence against these hypotheses.
-

Measuring and Improving Language Model Reasoning Faithfulness
By
–
When language models “reason out loud,” it’s hard to know if their stated reasoning is faithful to the process the model actually used to make its prediction. In two new papers, we measure and improve the faithfulness of language models’ stated reasoning.
-
Replicate Hosts Llama v2 Chat Model for Users
By
–
Amazing work. For anyone looking to play with Llama v2, here's our hosted model: https://
replicate.com/a16z-infra/lla
ma13b-v2-chat
…