"We urge policymakers to instead draw on solid scholarship that investigates the harms and risks of AI—and the harms caused by delegating authority to automated systems" w/
@alexhanna in @scientificamer
AI
-
Policymakers Must Examine AI Harms and Automation Risks
By
–
-
The Future Of Product Management: Embracing AI’s Revolution
By
–
The Future Of Product Management: Embracing AI's Revolution
#AI #AIio #BigData #ML #NLU #Futureofwork @chrismessina @ChristopherIsak @davidwkenny @debashis_dutta @petitegeek @fabiomoioli @GaryMarcus @asokan_telecom http://
ow.ly/Yi9p30swABy -
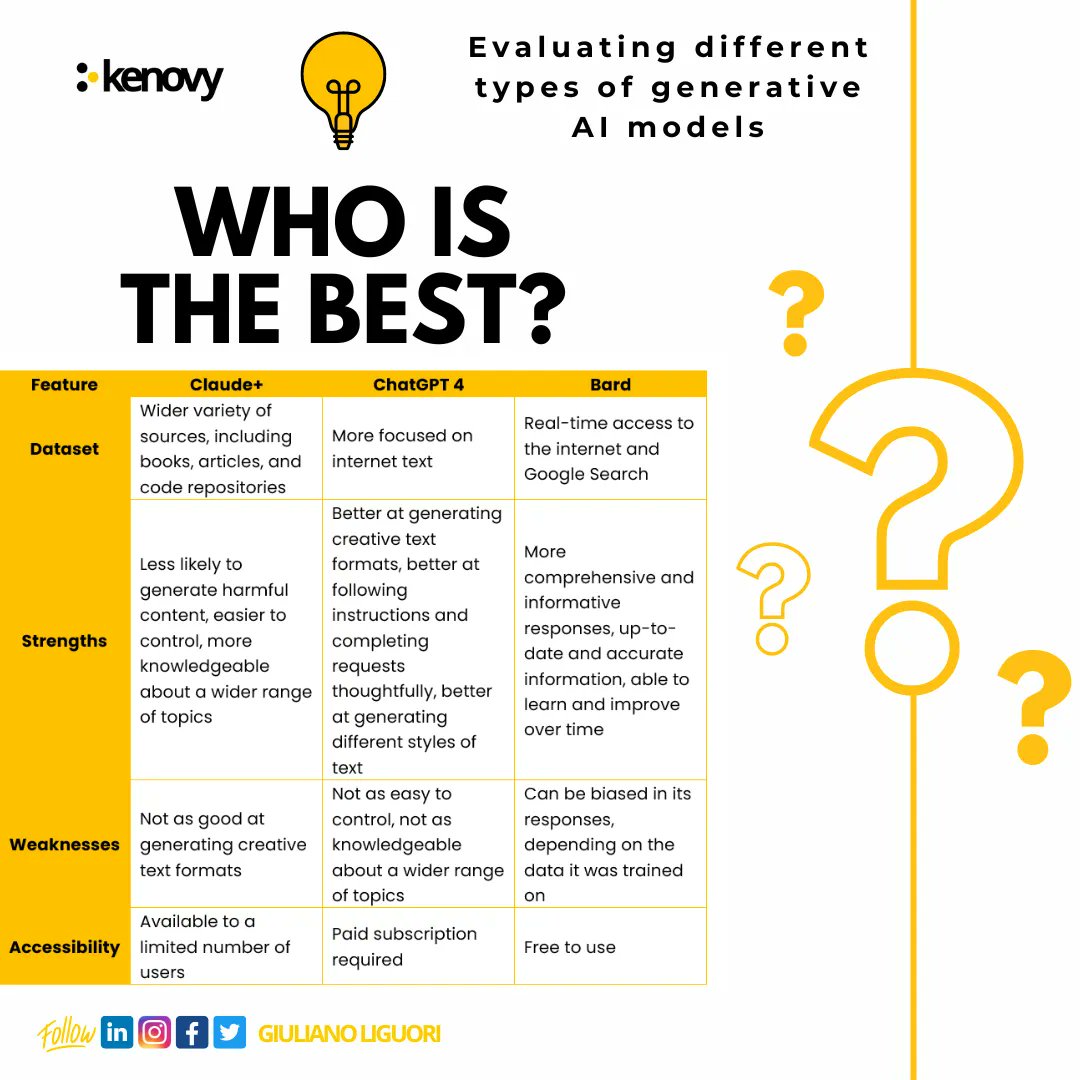
Best Generative AI Models: Comparative Evaluation Guide
By
–
Who is the best? Evaluating different types of generative AI models By @ingliguori https://
bit.ly/3pviApD #chatgpt #bard #cloudeai #chatgpt4 #llms #generativeai #AI #artificialintelligence #machinelearning #mlops #modelops -
Gradient Descent and Backpropagation Learning Resources
By
–
To learn more: Gradient descent: https://
youtube.com/watch?v=qg4Pch
TECck
…
Back prop and image credit: https://
youtube.com/watch?v=An5z8l
R8asY
… Original post credit: @bindureddy 10/10 -
Low Test Error Indicates Successful Model Learning and Generalization
By
–
If your error on the test set is low, you have learned the weights and biases of a model that predict the output given specific inputs and you can now use it to predict unseen data. 9/10
-
Evaluation: Testing Neural Networks on Unseen Data Points
By
–
7. Evaluation: You should always keep aside some data points from your original training set for testing. Here we evaluate how the NN predicts data points it's never been trained on. 8/10
-
Neural Network Training: Iteration and Data Requirements
By
–
6. Iteration: We repeat steps 2 to 6 for all the data points in your training set multiple times (epochs). Hence, your neural network is likely to be a better fit, if you have more training data points. 7/10
-
Gradient Descent: Adjusting Weights and Biases to Reduce Loss
By
–
5: Gradient Descent: We now adjust the weights and biases based on the gradients calculated in the last step. Typically this is done by multiplying the gradient by a small factor called learning rate. The basic idea is to reduce the error or loss. 6/10
-
Backpropagation: Computing Gradients Using the Chain Rule
By
–
You move backwards from the last layer using the chain rule of calculus and compute "gradients". Basically, you are calculating the gradient of the loss function with respect to each weight or bias 5/10
-
Backpropagation: Calculating Parameter Contribution to Network Loss
By
–
4. Backpropagation: This is where the magic happens. Fundamentally, you are calculating how much each parameter (weight or bias of each node) in the network contributed to the loss or error from step 2. 4/10