DROP EVERYTHING The bible for how LLMs work is now available online to read FOR FREE This is for you if you: – Want to run these LLMs at home on your hardware?
– Want to understand how ChatGPT works?
– Want to work at an AI Lab in the future? Covers all the concepts from
AI HARDWARE
-

Free online LLM bible: Understand ChatGPT, run models at home, future AI careers
By
–
-
Sarcastic commentary on short prompt and costly hardware
By
–
I mean, dude's longest prompt was 368 tokens and longest output was 4k He's literally crying next to that hardware and hoping to get enough engagement that elonbux can pay for his next month installment on those desk warmers
-
GigaAI’s Maker H01 Robotics Debut
By
–
Wheels Meet #AI: GigaAI’s Maker H01 Is Here
— Ronald van Loon (@Ronald_vanLoon) 22 mai 2026
by @CyberRobooo#Robotics #Engineering #Innovation #Technology pic.twitter.com/4YYpqvqCGUWheels Meet #AI: GigaAI’s Maker H01 Is Here
by @CyberRobooo #Robotics #Engineering #Innovation #Technology -
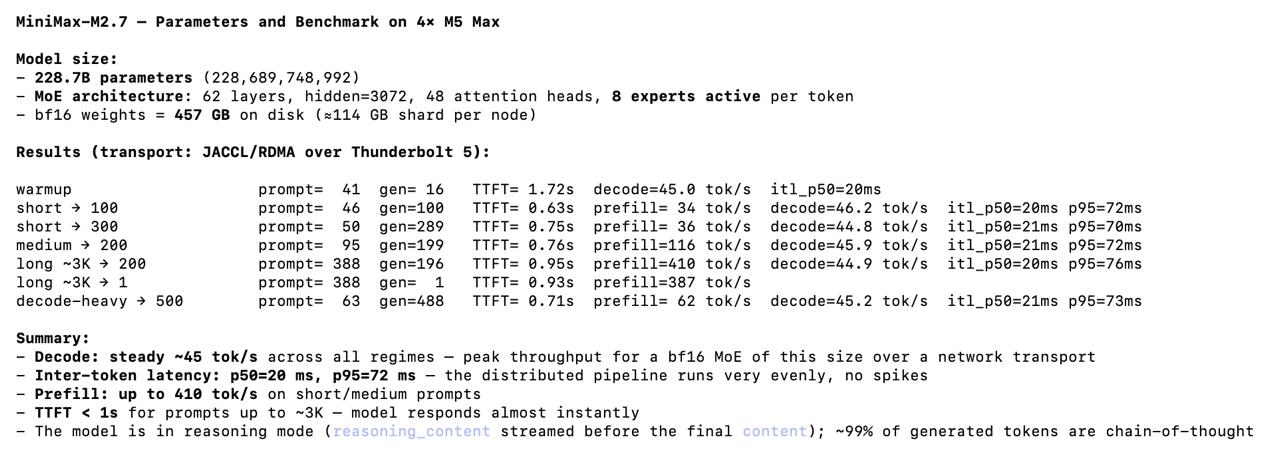
Expensive MacBooks run MiniMax with low performance and limited context
By
–
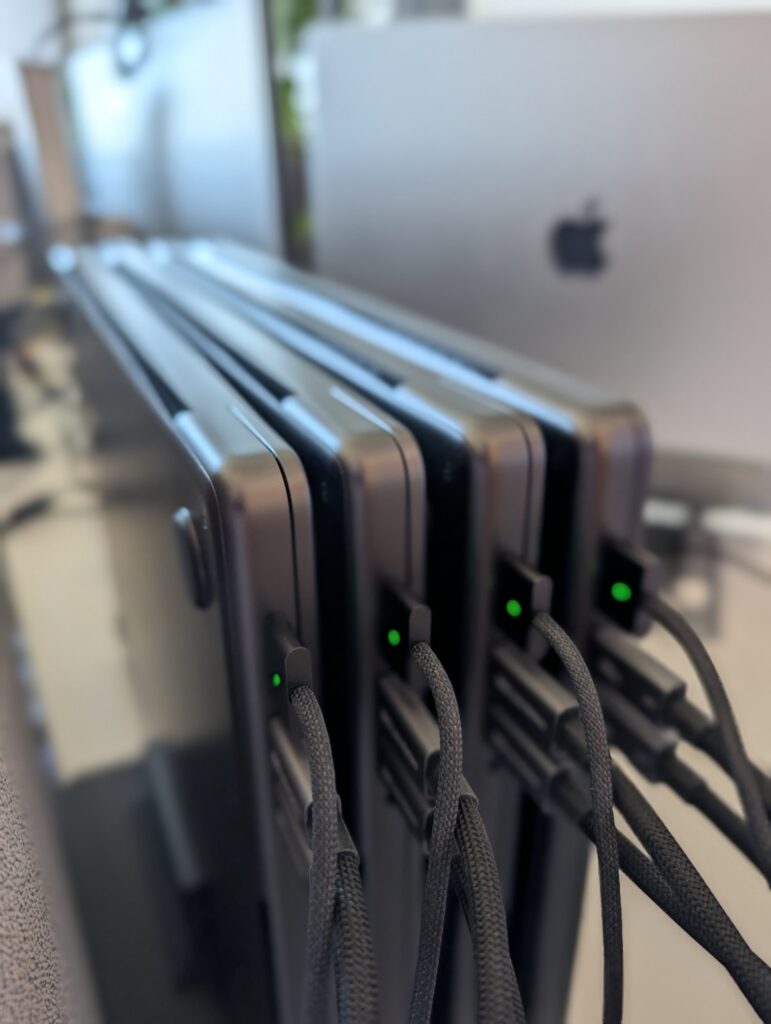
Good example of Performative Inference / Local AI grifting MiniMax-M2.7 on 4x M5 Max MacBooks (~$22,000 USD) – Longest prompt: 338 (???) – Max context: ~3k (???) – 45 tok/s (lol) – Single prompt, no parallel requests Some of the funniest & stupidest shit I've ever seen
-
Qwen 3.5 27B: Buy RTX 3090s or Stay Underclass
By
–
If you saw Qwen 3.5 27B and didn’t see that as a chance to ensure the permanent underclass semi-joke never happens to you (by simply purchasing a couple of RTX 3090s) I am sorry to say but you ngmi
-
Subsidized token industry ending, users still ignore local models
By
–
How it feels to know that the subsidized token industry is coming to an end and people are still not worrying about the right thing (running the models locally on your own compute) No more free DoorDash deliveries / $5 Uber trips for you (after they got you addicted)
-

New book: AI Systems Performance Engineering with GPUs, CUDA, PyTorch
By
–
HOT! Over 1000 pages! "AI Systems Performance Engineering — Optimizing Model Training and Inference Workloads with GPUs, CUDA, and PyTorch" Get it at http://
amzn.to/4pRunYJ via @OReillyMedia -

Supercomputing for AI: foundations, architectures, scaling deep learning
By
–
Supercomputing for AI — Foundations, Architectures, and Scaling Deep Learning. [804-page masterpiece] Get it: https://
amzn.to/4qS4pFz Git it: https://
github.com/jorditorresBCN
/supercomputing-for-ai
… -
RDUs deliver high tokens per kilowatt-hour for AI inference
By
–
AI infrastructure doesn’t have to mean massive power draw.
— SambaNova (@SambaNovaAI) 22 mai 2026
Our RDUs deliver the highest tokens per kilowatt-hour, helping reduce deployments with ~10kW average power consumption.
More inference. Less energy. 🦾
Learn more: https://t.co/v6jPztJPFp pic.twitter.com/dUM5bB3T5kAI infrastructure doesn’t have to mean massive power draw. Our RDUs deliver the highest tokens per kilowatt-hour, helping reduce deployments with ~10kW average power consumption. More inference. Less energy. Learn more: https://
sambanova.ai/products/rdu-a
i-chips?utm_source=x&utm_medium=organic
… -
Telexistence Launches Robotic Motion Data Factory for AI
By
–
Telexistence Introduces Large-Scale #Robotic Motion Data Factory for #AI Training
— Ronald van Loon (@Ronald_vanLoon) 22 mai 2026
via @ZappyZappy7
#ArtificialIntelligence #MI #ML #Tech #Innovation pic.twitter.com/TAbZO2E7JZTelexistence Introduces Large-Scale #Robotic Motion Data Factory for #AI Training
via @ZappyZappy7 #ArtificialIntelligence #MI #ML #Tech #Innovation