Premium inference, but make it comics We had a great time at the @Avnet SKO with Harry Ault talking about the future of AI infrastructure and agentic workloads, plus a few SambaNova superheroes making an appearance. Always a fun time partnering with Avnet!
AI HARDWARE
-
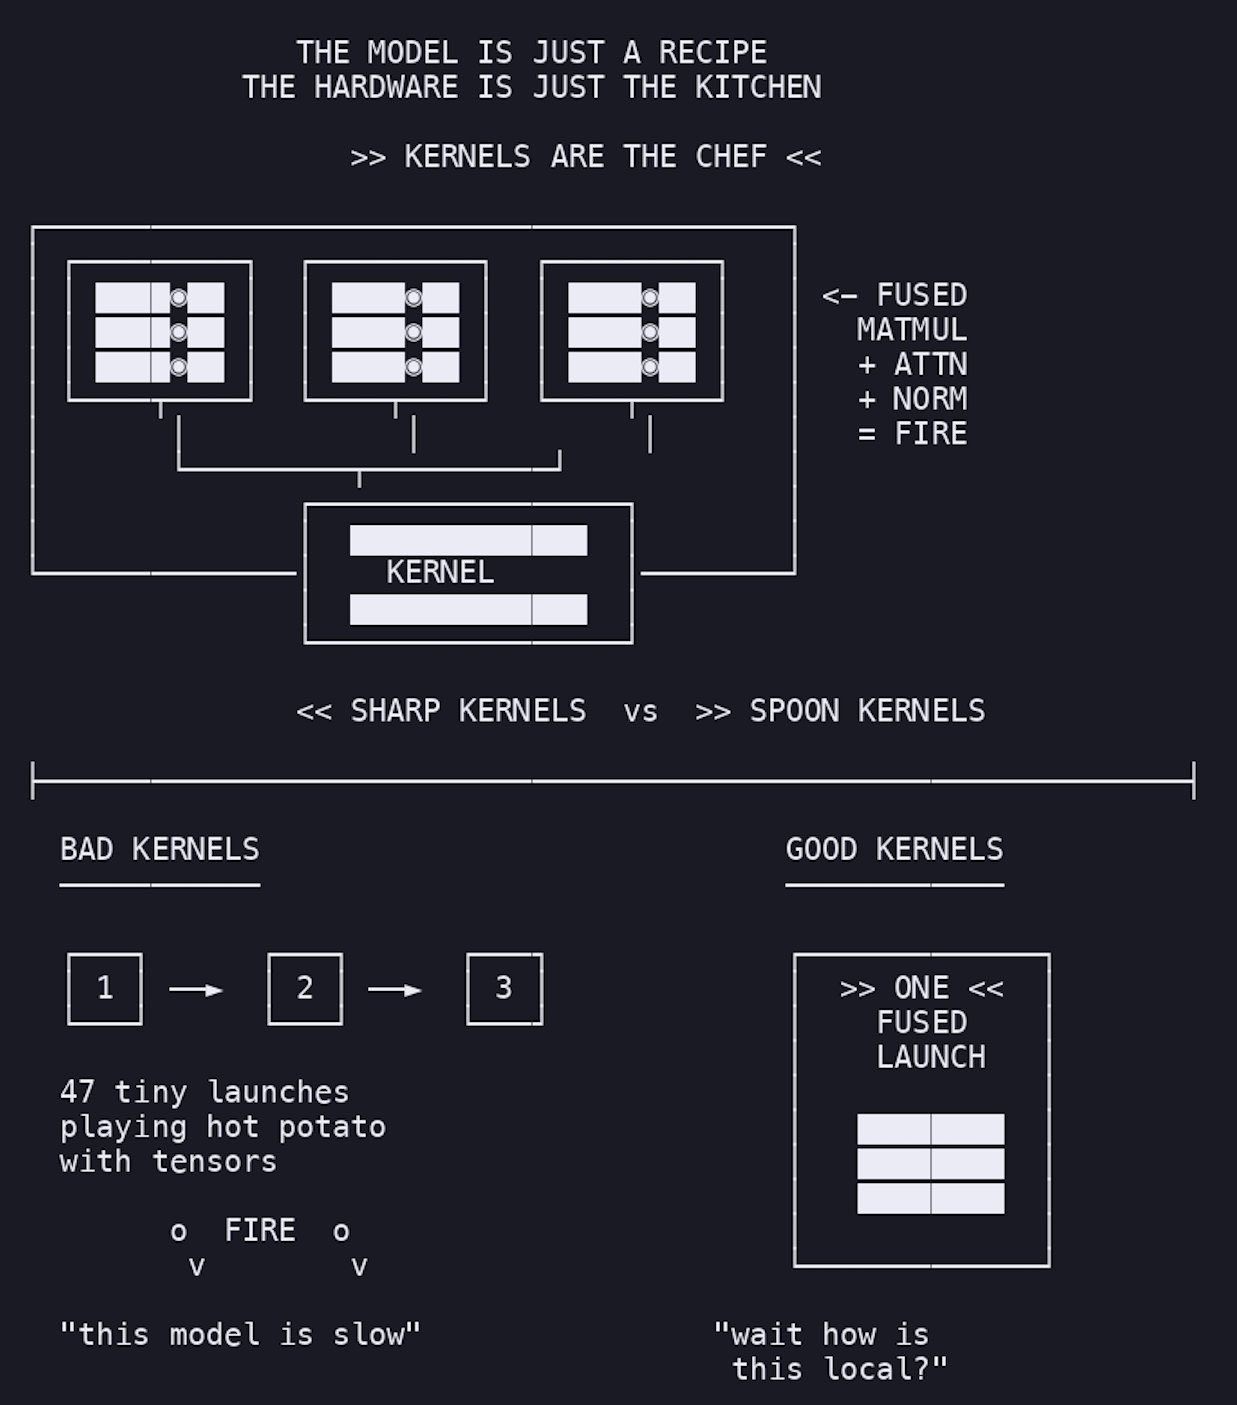
Learning Path for LLM Serving Engines: vLLM, SGLang, TensorRT-LLM
By
–
How to go about learning all of this? 1st: Start with the serving engine view – vLLM: PagedAttention, continuous batching, prefix caching, CUDA graphs – SGLang: RadixAttention/prefix reuse, speculative decoding, MoE, structured/agent workloads – TensorRT-LLM: NVIDIA peak
-

Confirming the growing popularity of edge models
By
–
Can confirm, edge models keep getting more and more popular
-
Energy determines AI model location, optimization still overlooked
By
–
Ultimately it will come down to energy. Local models will run at cost of electricity and cloud based (IQ-maxxing) will run in cloud and demand A LOT of energy. We also keep forgetting about optimization. We’ve only seen scale ramp up now, very little actual optimization
-
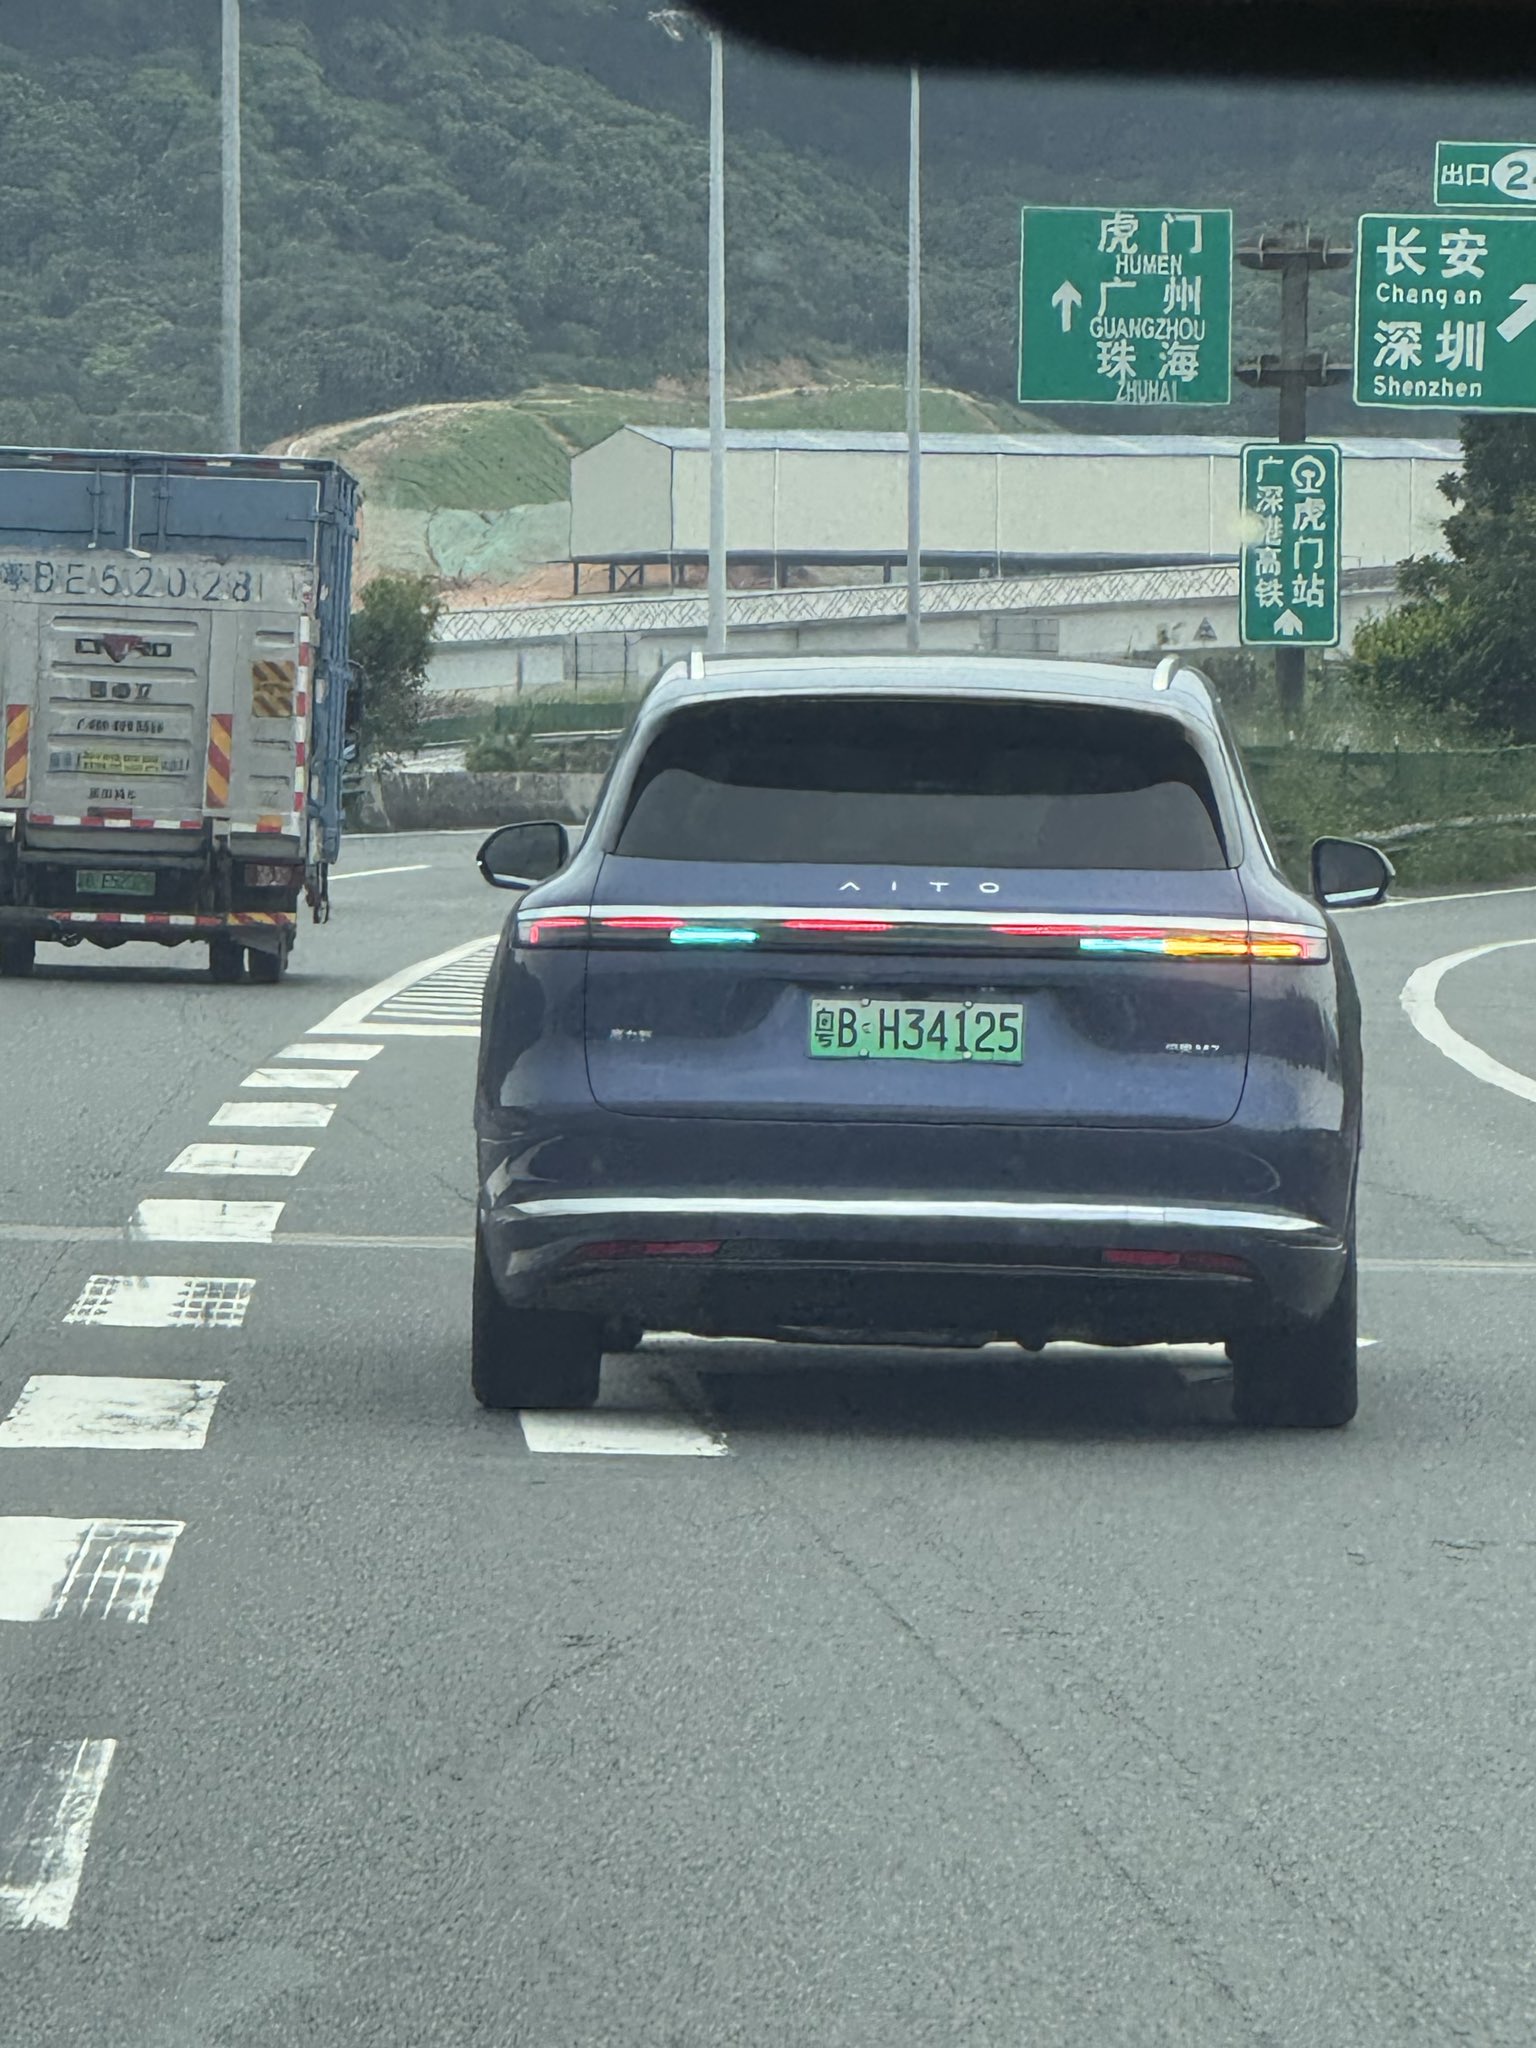
Huawei electric powertrain and autonomous driving platform used by Chinese carmakers
By
–
Huawei has developed an electric power train and autonomous driving platform that is being used by incumbent Chinese carmakers through new brands like AITO. The blue light tells you that the car is driving itself…
-
Love stumbling upon tears advising to buy GPU for local models
By
–
I just love randomly stumbling upon tears that say “Buy a GPU and run your own models locally! “
-
AI crosses the threshold of recursive self-improvement
By
–
AI has just crossed a threshold: recursive self-improvement. Models write the code that trains them, discover the algorithms that will make them better, design the chips that run them… The machine improves the machine, which will improve the machine.
-
Fine-tuning Gemma 4 12B to master chess on 8GB VRAM
By
–
Google released Gemma 4 12B, a multimodal model that runs text, images, and audio on 8GB VRAM!
— Akshay 🚀 (@akshay_pachaar) 7 juin 2026
We'll fine-tune it to master chess and predict the exact next move.
Tech stack:
– @UnslothAI for efficient fine-tuning.
– @huggingface transformers to run it locally.
Let's go! 🚀 pic.twitter.com/qPXjlYrShsGoogle released Gemma 4 12B, a multimodal model that runs text, images, and audio on 8GB VRAM! We'll fine-tune it to master chess and predict the exact next move. Tech stack:
– @UnslothAI for efficient fine-tuning.
– @huggingface transformers to run it locally. Let's go! -
Google Unveils New LLM for 8GB RAM
By
–
Google just dropped a new LLM! You can run it locally on just 8GB RAM. Let's fine-tune this on our own data (100% locally):
-

Prediction: unnerfed Opus 4.5 quality, NVFP4 optimized fits 20GB full context
By
–
I am actually sticking by prediction that we’ll have the unnerfed Opus 4.5 quality not the current shit one And NVFP4 optimized of that model would fit on 20GB with full context