11/ In summary, we have two main ways to evaluate a model outputs:
1. Get the probabilities that some tokens are continuations of the prompt => compare these probabilities together
2. Get the text generation from the model => compare these text generations to possible choices
@thom_wolf
-
Two main ways to evaluate model outputs
By
–
-
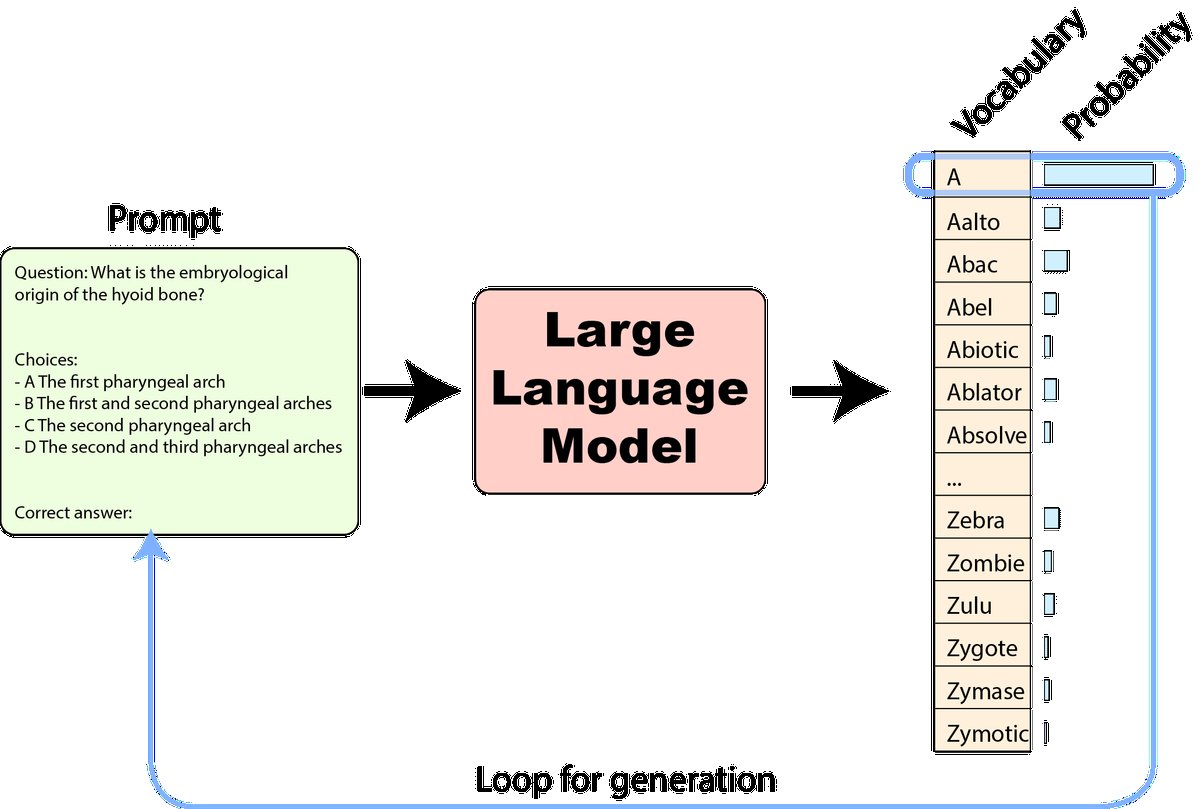
Token Selection and Autoregressive Generation in Language Models
By
–
10/ We can use these probabilities to choose a token, for instance the most probable. Adding the selected token to the prompt + feeding it back to the model allows to generate another token and so on until whole sentences are created as continuations of the input prompt.
-
HELM Benchmark Implementation Analysis for MMLU Evaluation
By
–
4/ Diving further, we found yet another serious implementation for evaluating on the very same MMLU dataset: the code used in the HELM benchmark https://
crfm.stanford.edu from @StanfordCRFM
: https://
github.com/stanford-crfm/
helm
… Let's call it the "HELM implementation" -
Three Major MMLU Evaluation Codebases Compared
By
–
5/ We thus have (at least) 3 serious codebases for evaluating on the same MMLU dataset:
– "Original implementation" from the MMLU benchmark authors
– "HELM implementation" from Stanford
– "Harness implementation" from EleutherAI (recently updated – see the end of the thread) -
LLaMA Team Uses Original MMLU Benchmark Evaluation Code
By
–
3/ It turns out the LLaMA team used the original evaluation code proposed by the authors of the MMLU benchmark (find it at https://
github.com/hendrycks/test) Let's call it the "original implementation" -
Open LLM Leaderboard: Evaluation Framework and Results
By
–
1/ First, what's the Open LLM Leaderboard? Just a wrapper running the @AiEleuther evaluation harness https://
github.com/EleutherAI/lm-
evaluation-harness
… on the Hugging Face cluster spare cycles + storing/displaying results at https://
huggingface.co/spaces/Hugging
FaceH4/open_llm_leaderboard
… -
LLaMA 65B MMLU Benchmark Discrepancy Analysis
By
–
2/ For one evaluation, MMLU (
https://
arxiv.org/abs/2009.03300), the community was surprised that the leaderboard numbers for the top model, LLaMA 65B, were significantly lower than the numbers in the published LLaMa paper: a 30% difference! We dived in a rabbit hole to understand -
Open LLM Leaderboard evaluation accuracy analysis findings
By
–
A on "what was going on with the Open LLM Leaderboard?" its numbers didn't match the ones reported in LLaMA paper so we dived in it and wrote a blog post of learnings! Here's the thread version for those of you who didn't want to read a blog post
-
Prompt Changes Show Minimal Impact on Ranking Results
By
–
All prompts changes had very little effect in our experiments, in particular on ranking. Probably should add more details on this.
-
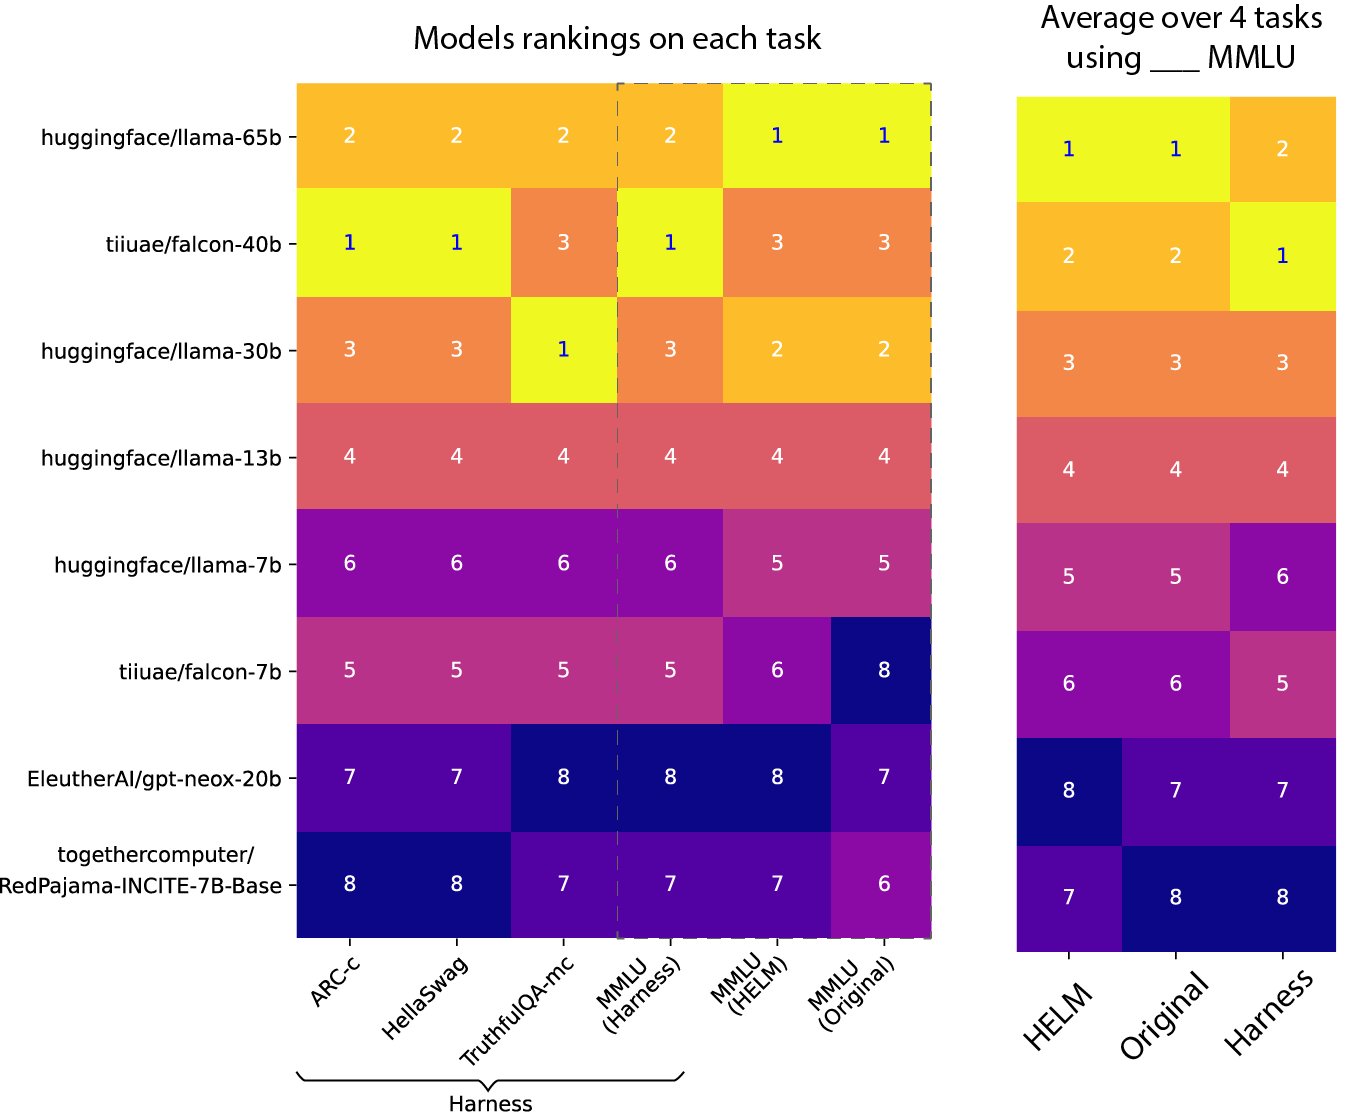
Open LLM Leaderboard Evaluation Discrepancies and Methodology
By
–
What was going on with the Open LLM Leaderboard? Its numbers didn't match the ones reported in the LLaMA paper! We've decided to dive in this rabbit hole with friends from the LLaMA & Falcon teams and got back with a blog post of learnings & surprises: https://
huggingface.co/blog/evaluatin
g-mmlu-leaderboard
…