25/ THE END PS: Please, come comment/discuss at https://
huggingface.co/spaces/Hugging
FaceH4/open_llm_leaderboard/discussions/82
… PPS: During the writing of this post, @Ollmer & the community have done an amazing work updating MMLU in the Harness to make it similar to the original. We're thus now updating the leaderboard based on it!
@thom_wolf
-
MMLU Benchmark Updated in Open LLM Leaderboard
By
–
-
Open Standardized Benchmarks Essential for AI Model Evaluation
By
–
24/ That's why open, standardized, reproducible benchmarks such as the EleutherAI Harness https://
github.com/EleutherAI/lm-
evaluation-harness/
… or Stanford HELM https://
github.com/stanford-crfm/
helm/
… are invaluable to the community. Without them comparing results across models/papers would be impossible, stifling research! -
MMLU Scores Incomparable: Evaluation Implementation Details Matter
By
–
23/ …not at all comparable even if they're both called MMLU & evaluated on same dataset Takeaway? Evaluations are strongly tied to implementations–down to minute details. A mere indication of "MMLU score" gives almost no information about how you can compare these numbers
-
LLaMA 65B Evaluation Discrepancies Between Implementations
By
–
22/ Say you've trained a perfect LLaMA 65B reproduction & evaluated it with EAI harness (score 0.488). Comparing it to the published number (evaluated w. original implementation, score 0.637), it's a 30% difference so you're likely thinking "Oh no " But these numbers are…
-

Model Evaluation Methods Significantly Impact Scores and Rankings
By
–
21/ Now let’s compare the model scores on these three possible ways to evaluate the models We can see that for the same dataset, both absolute scores and model rankings are very sensitive to the evaluation method we decide to use.
-
Probability-based sequence generation normalization in language models
By
–
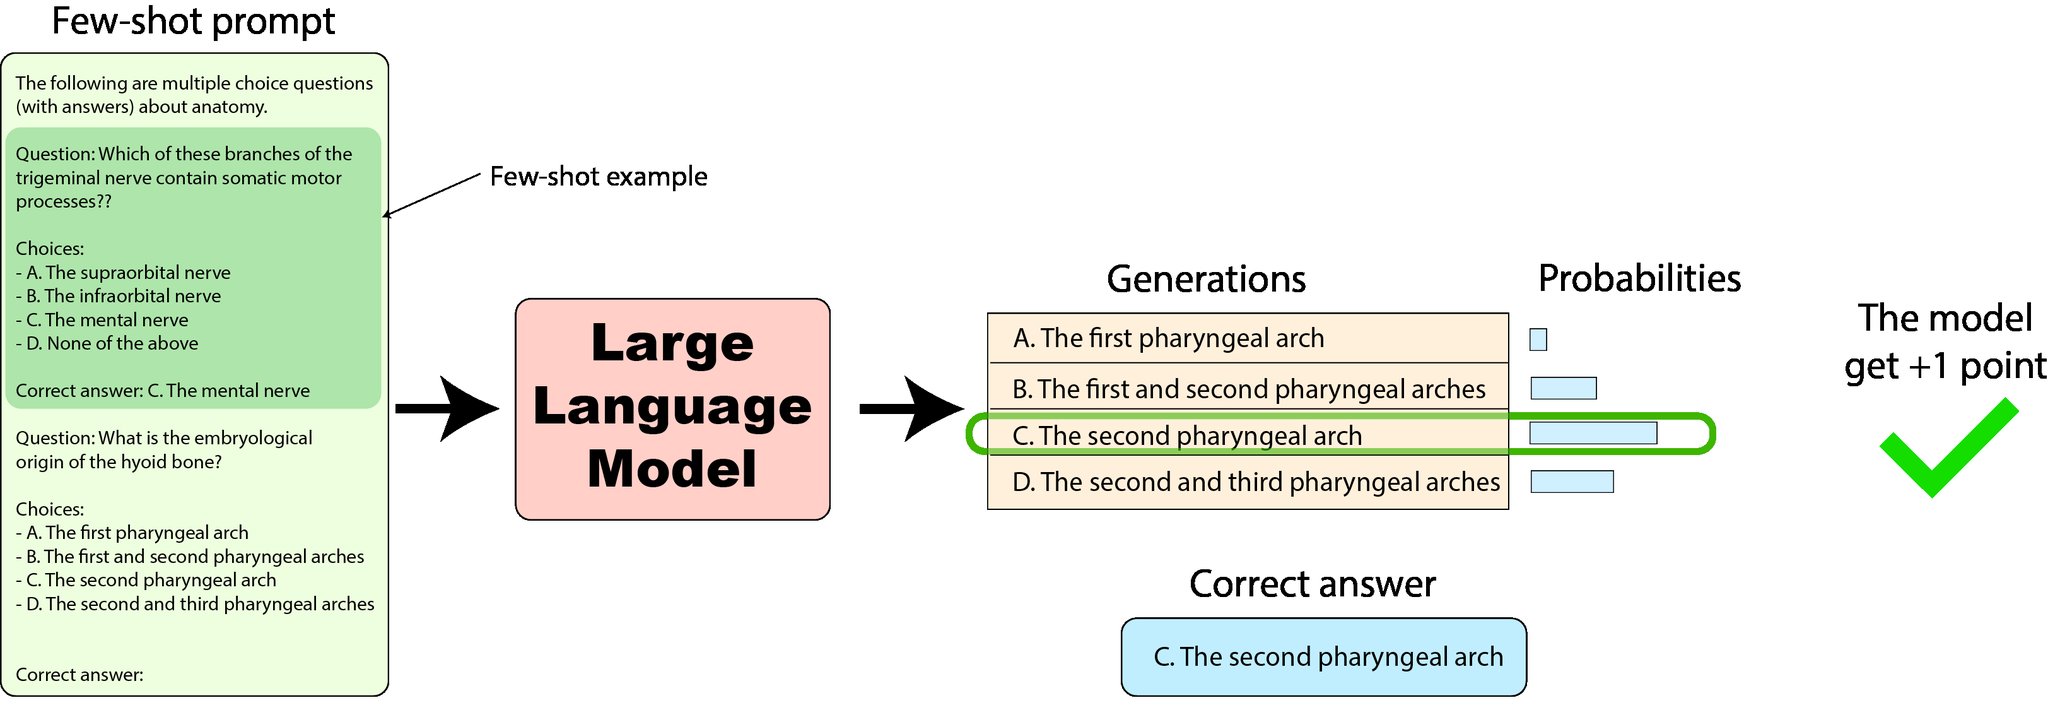
19/ In this case, we use probabilities again but this time we compute the probability of generating the full answer sequence, not just the letter: we sum the log of the probabilities and compute a normalization by dividing by the number of tokens to not penalize longer sequences.
-
Harness Evaluation Framework for Large Language Models
By
–
18/ Harness: Now we finally turn to the EleutherAI Harness implementation (as of January 2023) which was used to compute the numbers for the Open LLM Leaderboard. Here is yet another way to compute a score for the model on the very same evaluation dataset! Let's take a look:
-

HELM Implementation: Model Evaluation via Token Probabilities
By
–
16/ HELM: Now let's take a look at the HELM implementation. The few-shot prompt is similar but the way the model is evaluated is quite different: we use the next token probabilities from the model to select a text generation and we compare it to the text of the expected answer
-
Few-Shot Prompting Improves Model Performance on MMLU
By
–
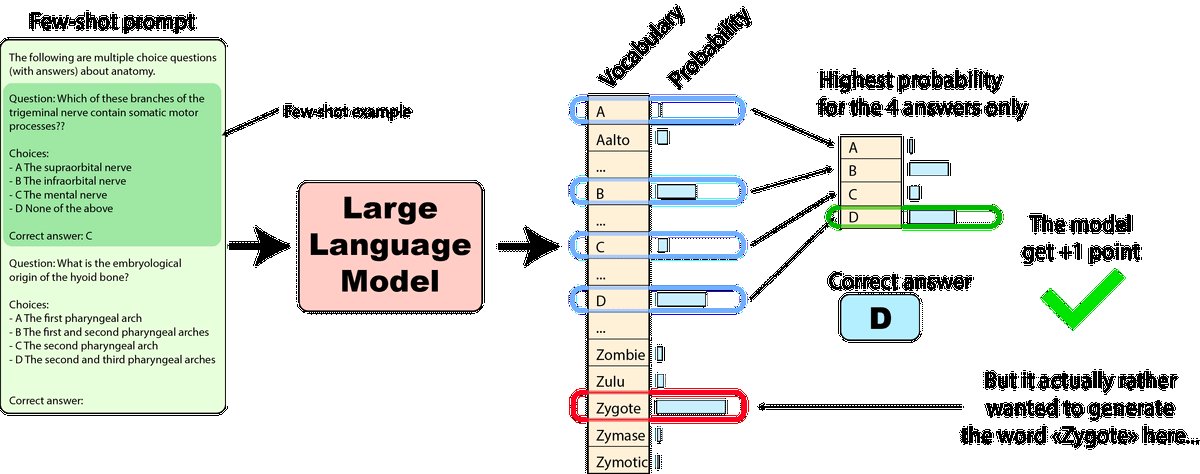
15/ To make sure that the model does as few as possible of these sort of errors, we can use “few shots”: we provide the model with a few examples in the prompt with the expected answers. Since this improves performance, MMLU is evaluated in 5 shots in all our experiments
-
Model Evaluation: Uncounted Prediction Errors in Multiple Choice
By
–
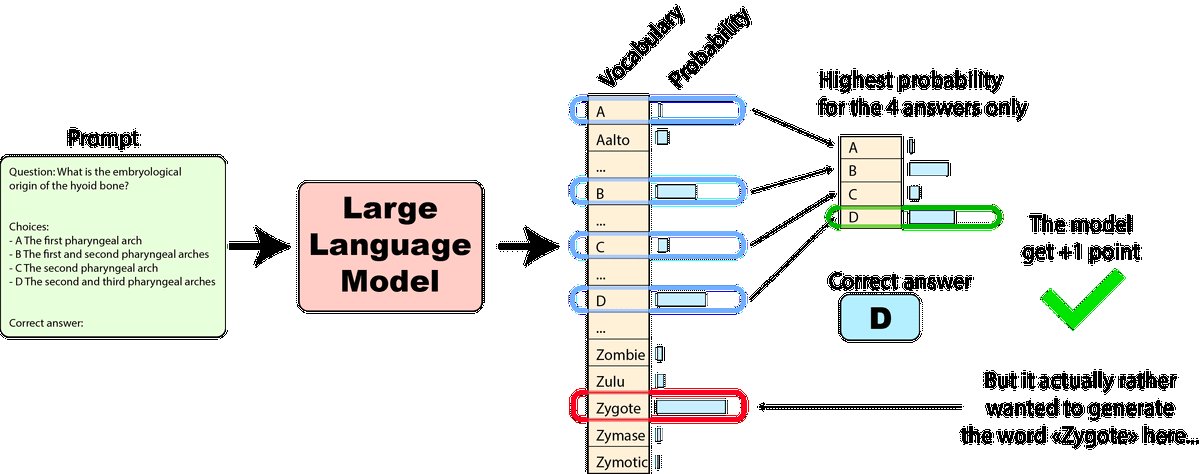
14/ As you can see, we compare the probabilities predicted by the model, on the four answers *only*. But sometimes that model would have made a mistake (generating "Zygote" here) which is not counted as a mistake…