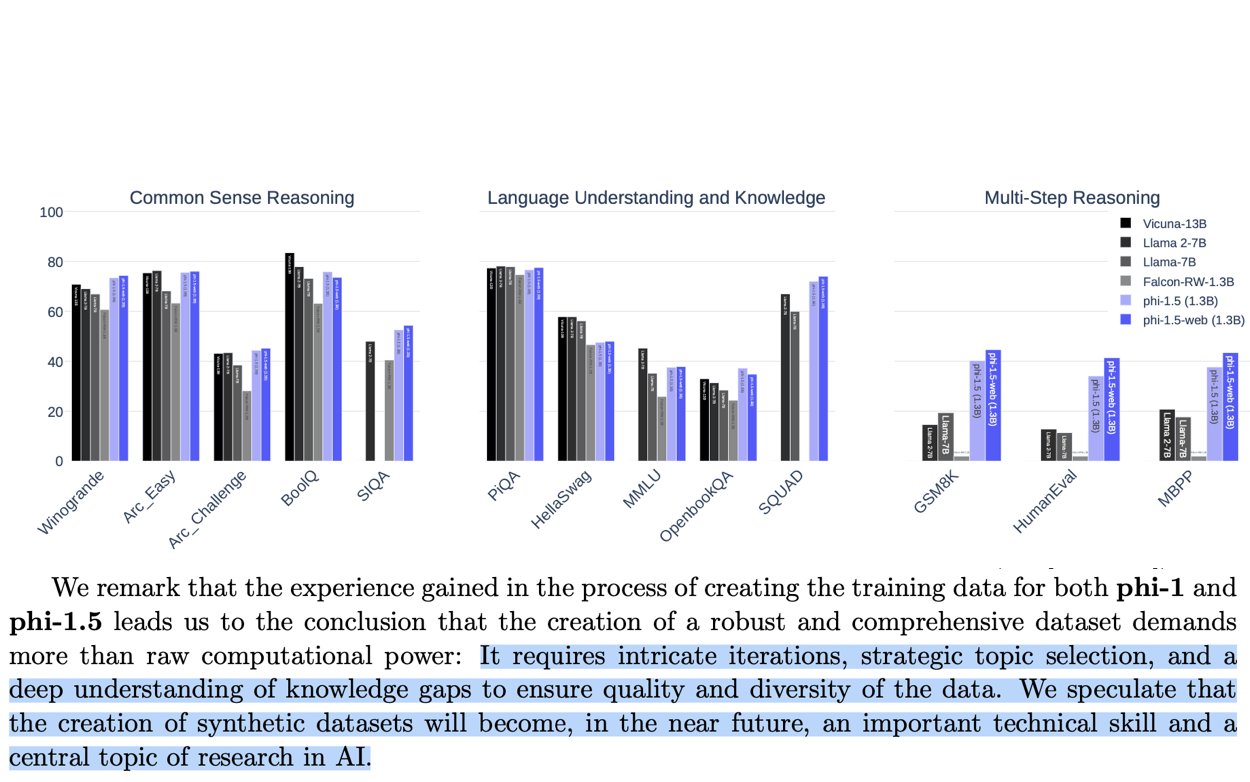
These new phi-1 & 1.5 models are fascinating, no? performances crushing 10 times bigger models secret sauce coming from a magic textbook dataset close to zero information on this dataset other than GPT3.5 generated Is it time for an "Open Textbook" project??
@thom_wolf
-
GPT-4 Falcon Llama2 Tokenizer Comparison Study Results
By
–
And our answers are out! Running on 1B tokens from the web (filtered and mostly in English as details in https://
huggingface.co/papers/2306.01
116
…) we got – GPT4 tokenizer (100k vocab) gives you 0.997B tokens – Falcon tokenizer (64k vocab) gives you ~5% more tokens (1.04B)
– Llama2 tokenizer -
Tokenizer vocabulary size comparison across language models
By
–
Sunday small guessing puzzle Let's say I have 3 tokenizers:
– llama2: 32k vocab
– falcon: 65k vocab
– GPT4: 100k vocab I take ~2M random documents from the web (let’s say 10 random parquet files from RefinedWeb from https://
huggingface.co/datasets/tiiua
e/falcon-refinedweb
… roughly 1B tokens). I tokenize them -

Big Benchmarks Collection: Comprehensive LLM Evaluation Resources Hub
By
–
Started a collection with all the benchmark spaces I know on the hub and some description. Do you know other benchmark on the Hugging Face hub? ping me and I'll add them! https://
huggingface.co/collections/op
en-llm-leaderboard/the-big-benchmarks-collection-64faca6335a7fc7d4ffe974a
… -
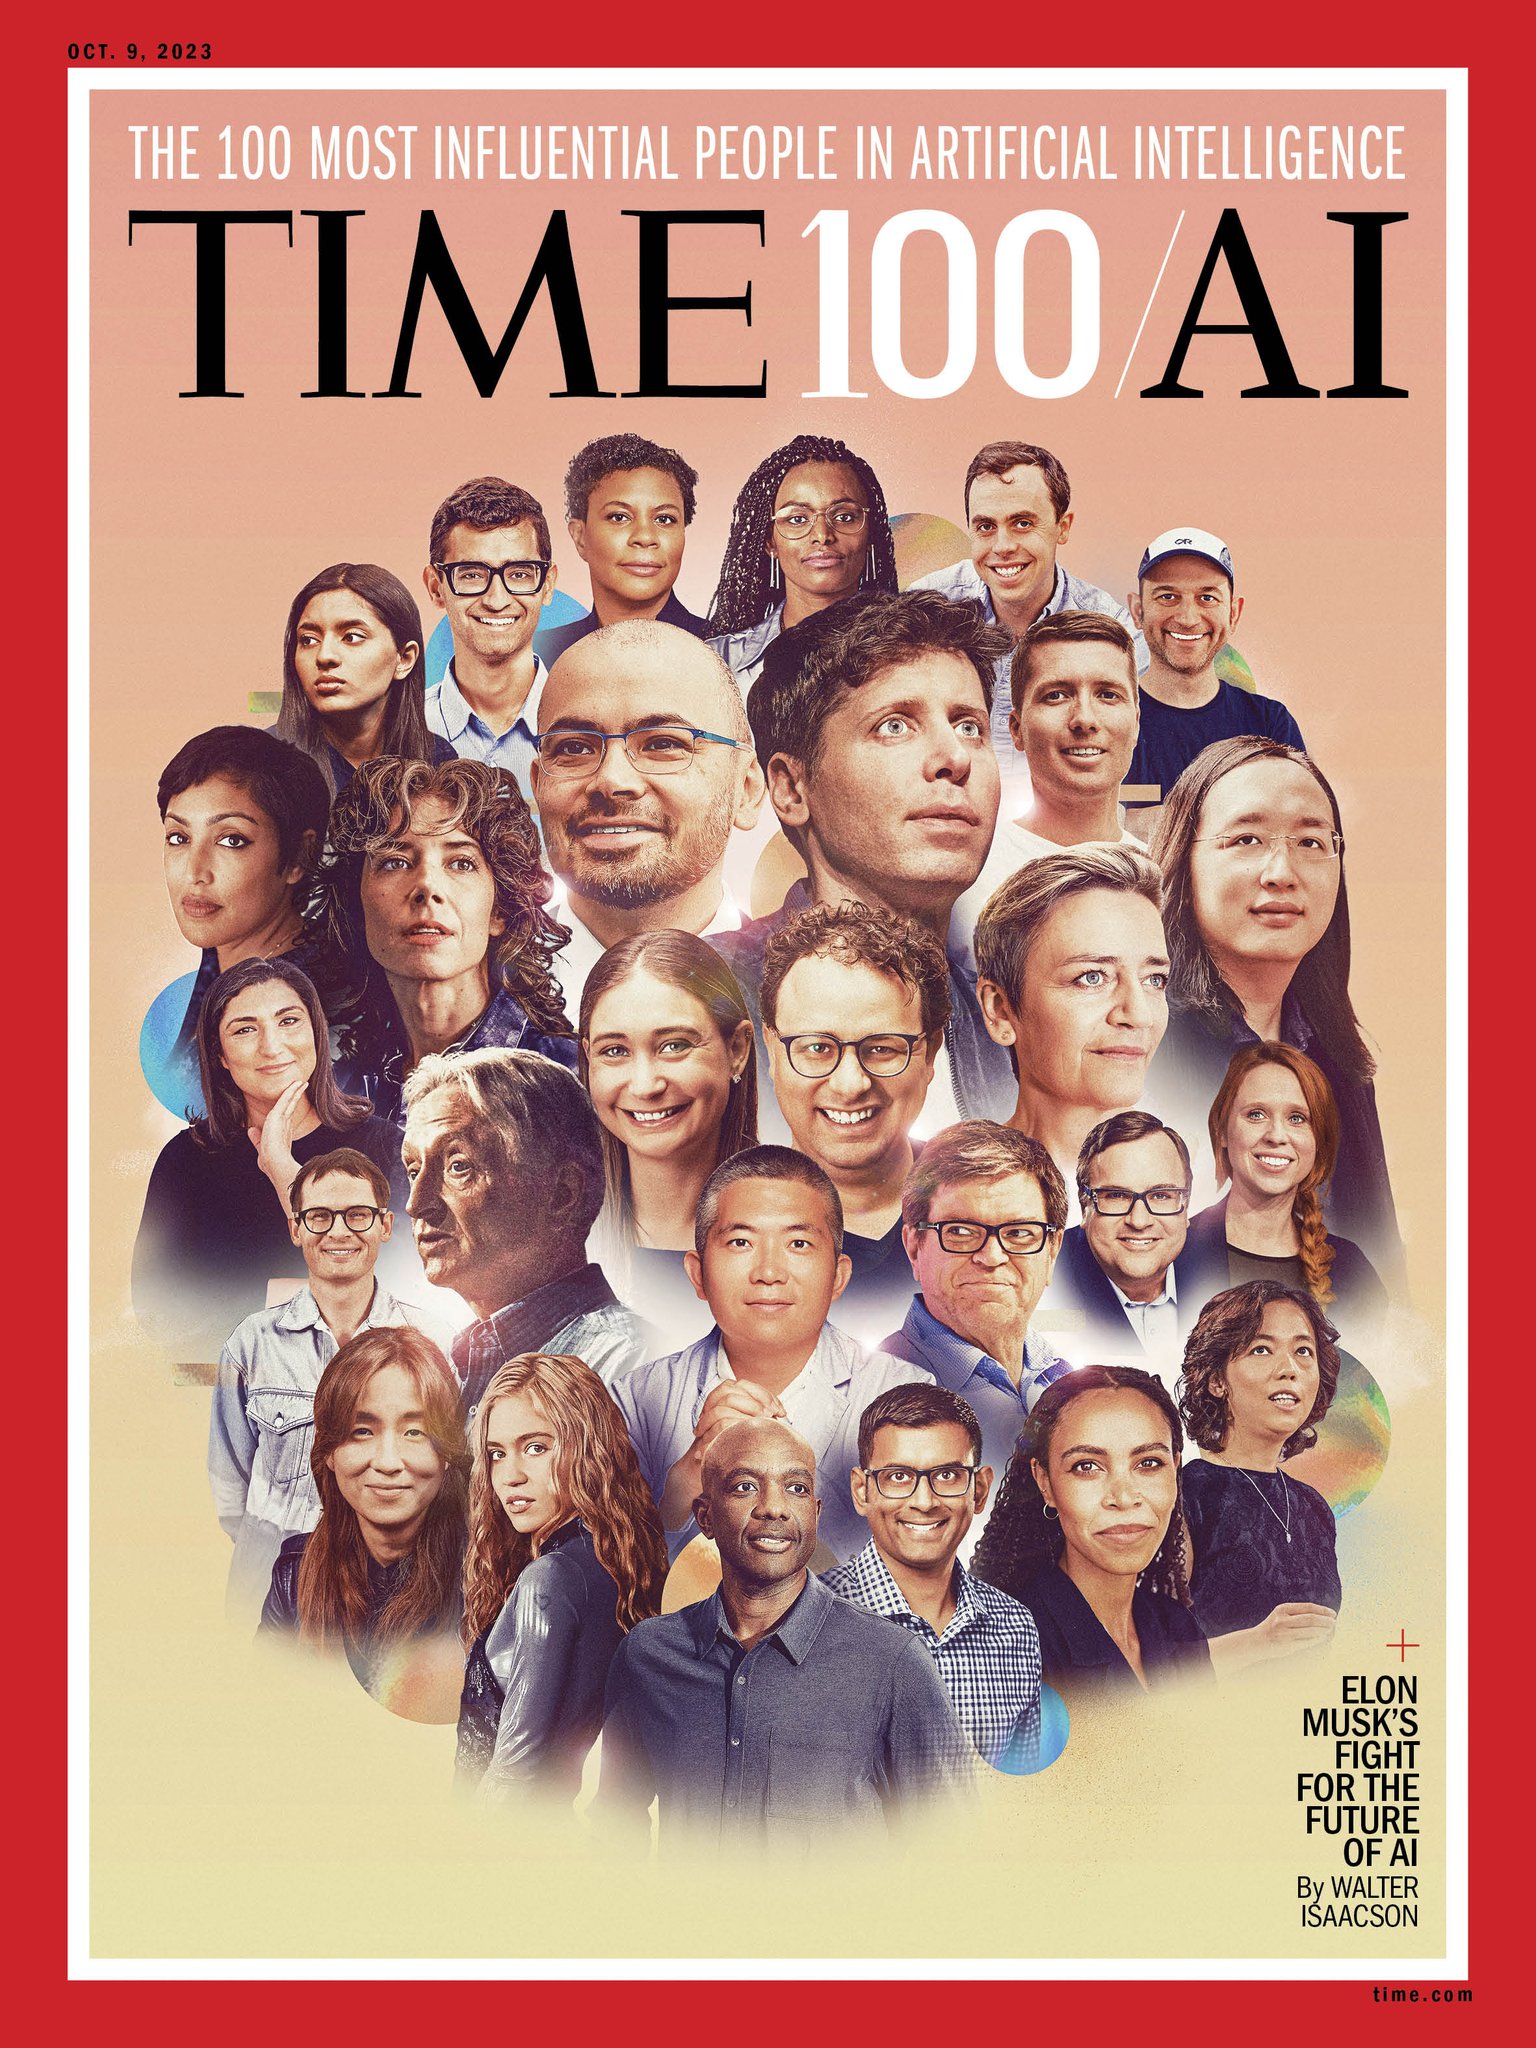
Hugging Face Leaders Recognized in Time’s 100 AI List
By
–
Mind-blowed to see both my amazing co-worker @mmitchell_ai and awesome co-founder @ClementDelangue selected in Time's 100 AI Super proud of what @huggingface is creating for the community (PS lot of great people missing from the list as well)
-
Dr. Almazrouei Team Releases Amazing AI Project Update
By
–
Amazing release Dr. Ebtesam Almazrouei and the team
-
Multilingual AI Dataset Benchmark on HuggingFace Platform
By
–
That’s a really cool datasets and benchmark! Super nice to push progress on multilinguality. Would you be maybe interested in hosting there http://
HuggingFace.co/facebook/ and/or think about having an automatically updated community leaderboard around it -
34B Parameter Models Now Run on Laptops, Massive Hardware Progress
By
–
Crazy how 34 billions parameters models seemed huge and unmanageable outside of a data center just maybe 1.5 years ago. Now it’s laptop stuff https://t.co/gXCg770BOM
— Thomas Wolf (@Thom_Wolf) 31 août 2023Crazy how 34 billions parameters models seemed huge and unmanageable outside of a data center just maybe 1.5 years ago. Now it’s laptop stuff
-
WizardCoder vs Phind-V2: Code Model Performance Comparison
By
–
The WizardCoder vs Phind-V2 perf challenge is fascinating to watch! Both seems really good code models: https://
reddit.com/r/LocalLLaMA/c
omments/165qeb3/wizardcoder_vs_phindv2_prelim_pass1_comparison
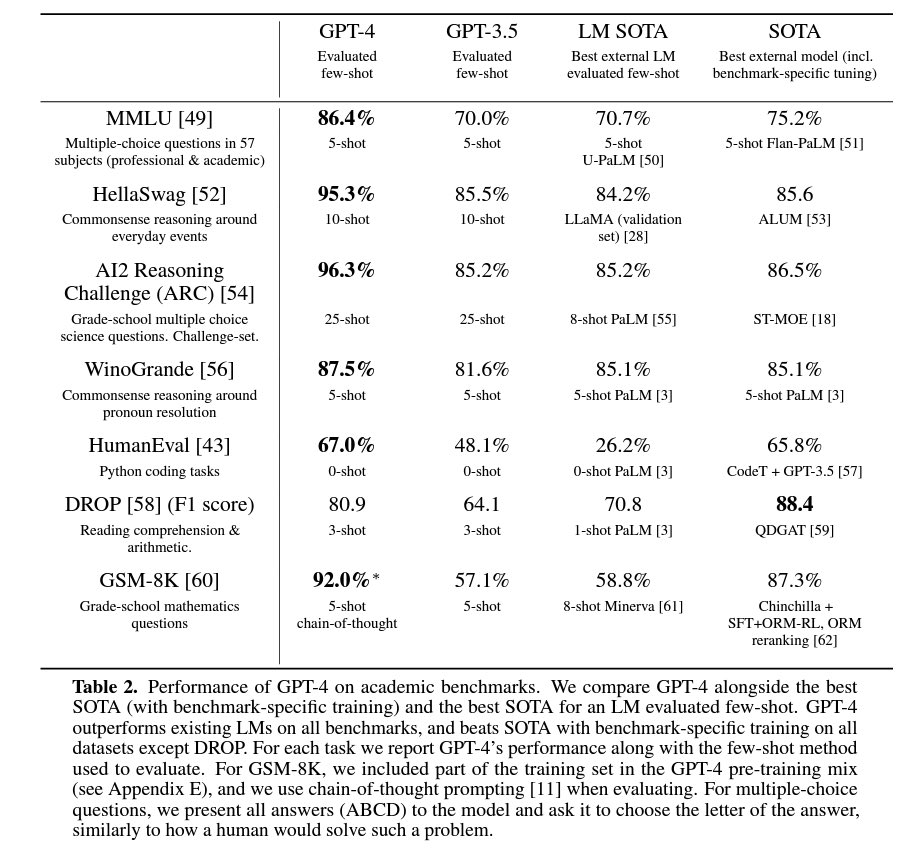
… Funny to remember that GPT4 was only scoring 67% on HumanEval at its release OpenAI also went a long way in a few months up to its current 84%! -
Current LLM Hallucination Benchmarks: Evaluating Factual Accuracy
By
–
What interesting benchmarks on LLM hallucinations exist currently?