You don't even need the skill that
Codex Cli is currently vibe-coding Take this screenshot and tell an agent-after it gives you an implementation plan-to use 1 of the 2 paths (you need to specify) for the actual implementation using parallel agents Done
@theahmadosman
-
Vibe-coding with Codex Cli using parallel agents for implementation
By
–
-
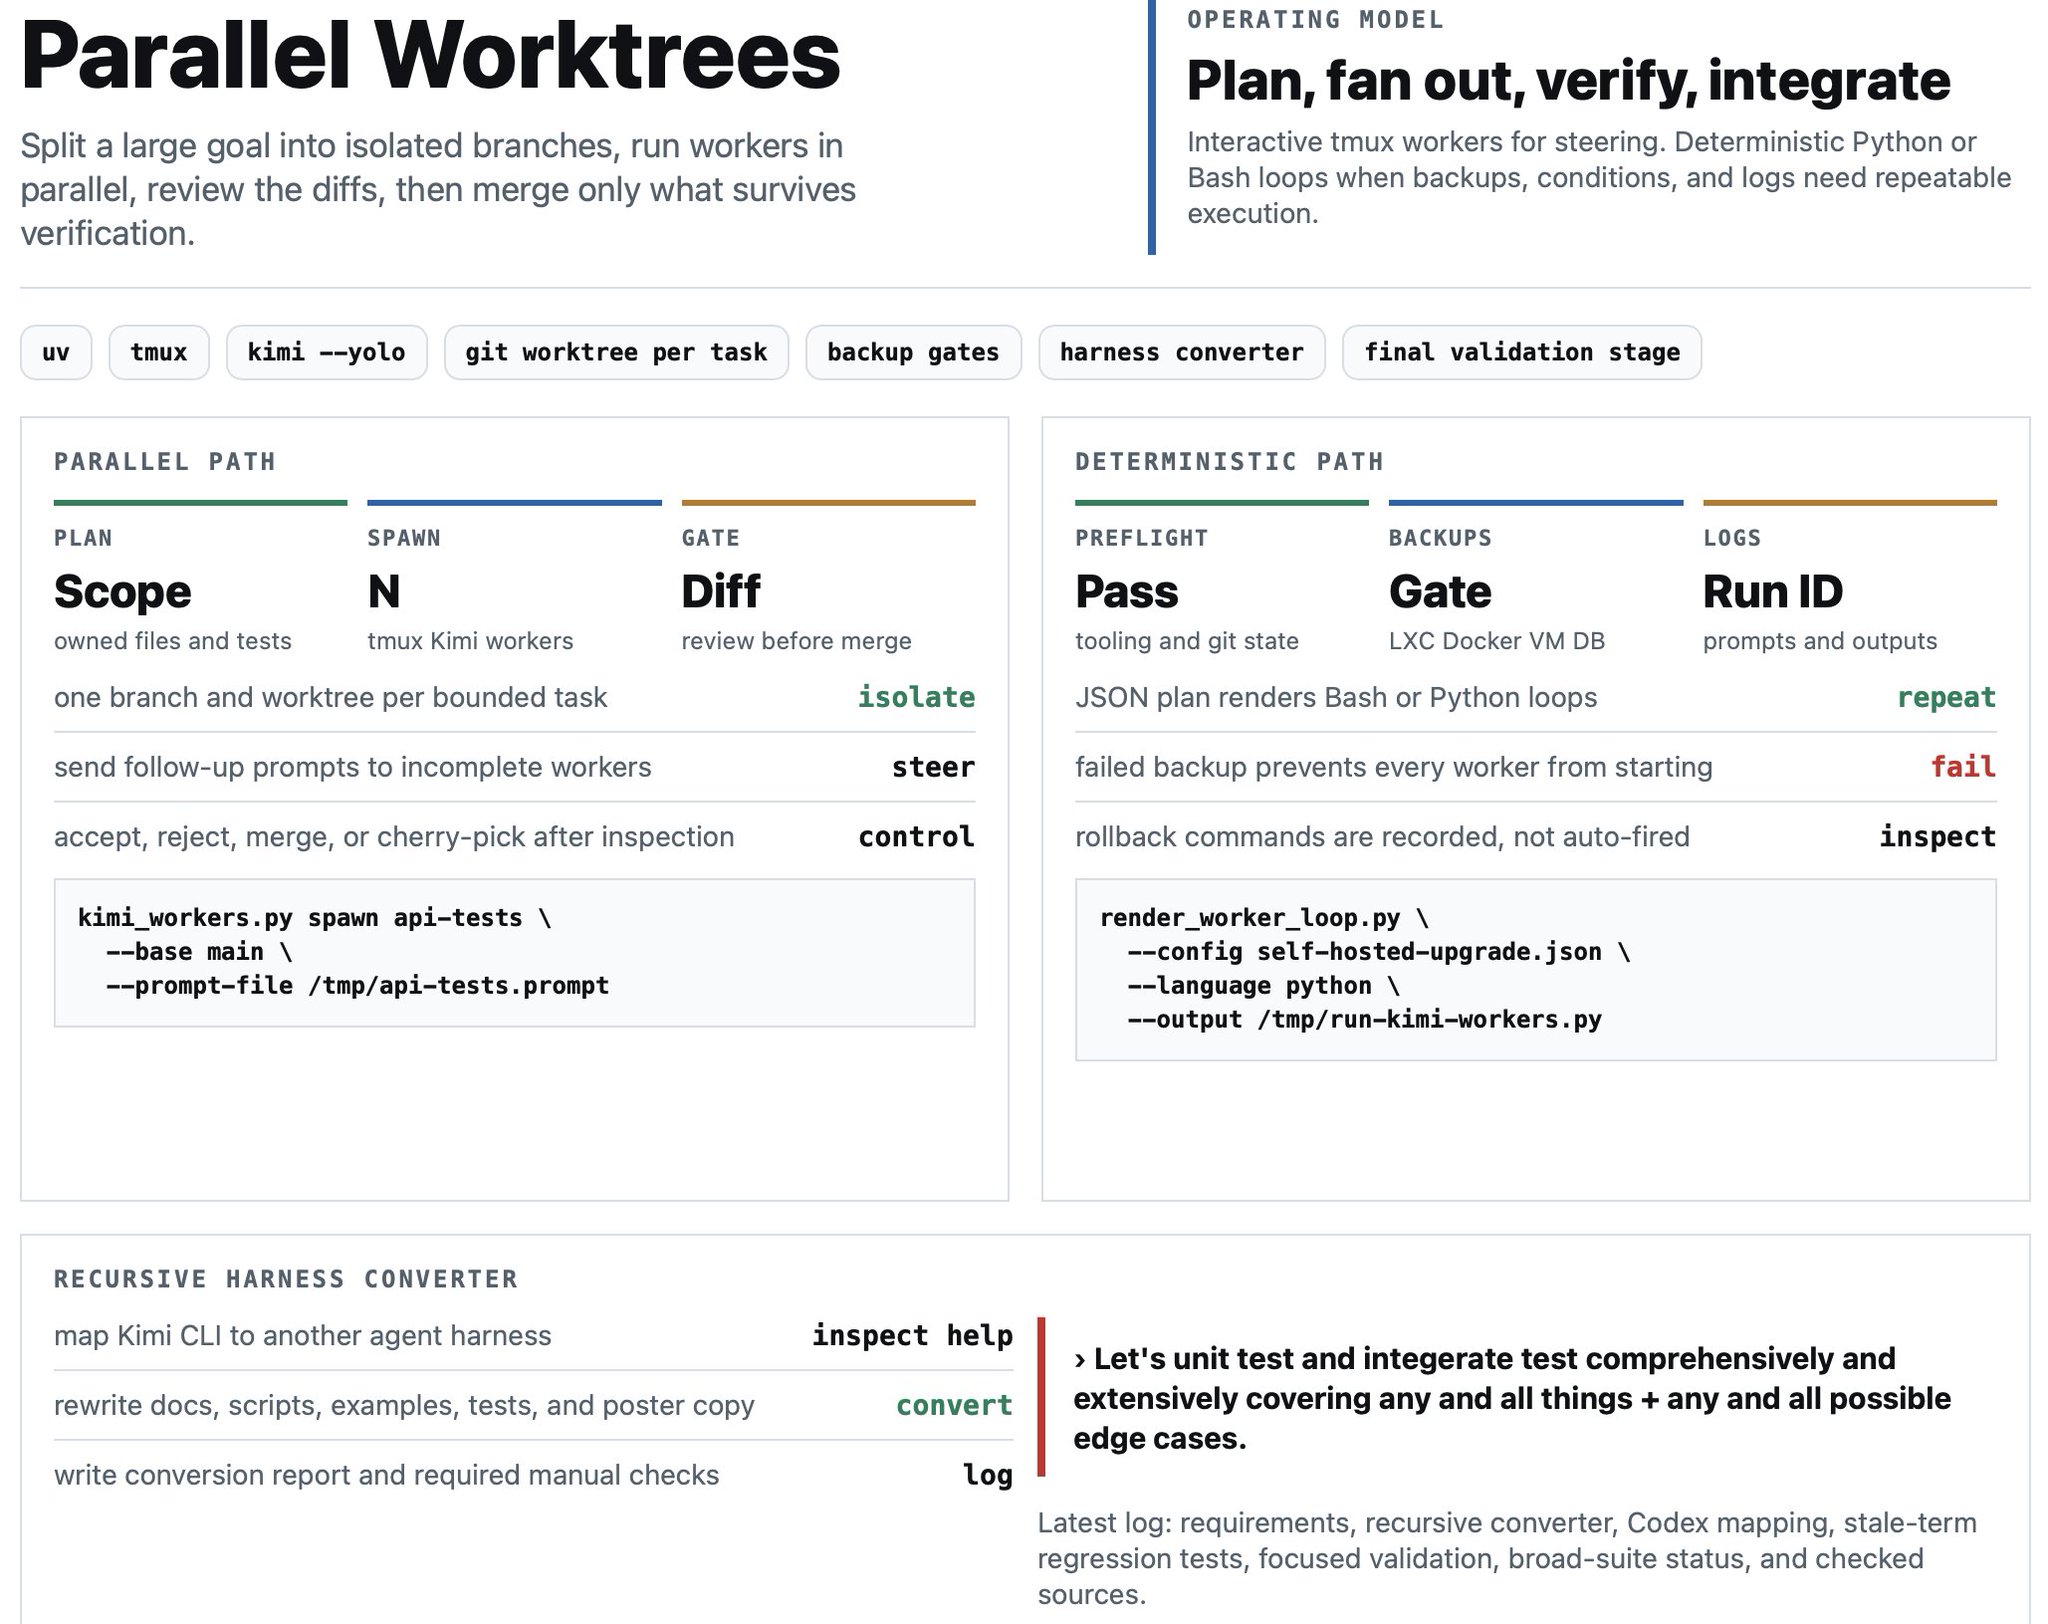
Running parallel agents interactively and deterministically with git worktrees
By
–
In the Space today I broke down how I run parallel agents both interactively & deterministically > Ask the main agent to spin up workers (ex: Kimi Cli) > Go fully deterministic with Python/Bash loops w/ separate git worktrees as backups Turning this into a Skill for u guys rn
-
21.5s video rendered in 12 mins using 4 DGX Sparks
By
–
Rendered a 21.5s short video on
— Ahmad (@TheAhmadOsman) 11 avril 2026
4x DGX Sparks w/ LTX-2.3 HQ BF16
> Entire thing took 12 minutes (end-2-end)
> The whole thing was vibe-coded by Codex Cli
Breakdown
> 4 story shots in parallel
> wall-clock ≈ slowest shot (~12 min per scene)
> instead of ~45 min sequential… pic.twitter.com/GSnqdLukhSRendered a 21.5s short video on
4x DGX Sparks w/ LTX-2.3 HQ BF16 > Entire thing took 12 minutes (end-2-end)
> The whole thing was vibe-coded by Codex Cli Breakdown
> 4 story shots in parallel
> wall-clock ≈ slowest shot (~12 min per scene)
> instead of ~45 min sequential -
Master Unix, Git, and SSH to boost your AI agent’s leverage
By
–
Bash (tool / philosophy) plays a major role in how useful AI Agents are today
— Ahmad (@TheAhmadOsman) 10 avril 2026
Take a weekend and learn
> unix basics (cd, mv, cp, nano, etc)
> git (branch, merge, revase)
> ssh, ports & firewalls 101
Highest leverage multiplier for agents
> every tool becomes callable
>… https://t.co/ssdQdUxPypBash (tool / philosophy) plays a major role in how useful AI Agents are today Take a weekend and learn > unix basics (cd, mv, cp, nano, etc)
> git (branch, merge, revase) > ssh, ports & firewalls 101 Highest leverage multiplier for agents > every tool becomes callable
> -

Chatting with Plex server via Hermes agent for automated movie management
By
–
I now chat with my Plex server + automation stack through a local Hermes agent > RTX 3070 (8GB)
> Qwen 3.5 9B (quantized) Gave my wife access via Telegram she can: > search movies
> add / grab them instantly Hermes: > learns her ratings + rewatches
> picks up patterns
> -
Setting up GLM-5.1 4-bit on 4x DGX Sparks cluster
By
–
Qwen3.5-397B-A17B-FP8 via OpenCode
— Ahmad (@TheAhmadOsman) 10 avril 2026
Helping me setup GLM-5.1 (4-bit)
On the 4x DGX Sparks cluster https://t.co/OTKXZ2vzkm pic.twitter.com/somZODNXQxQwen3.5-397B-A17B-FP8 via OpenCode Helping me setup GLM-5.1 (4-bit) On the 4x DGX Sparks cluster
-
New video on model scaling and Tensor Parallelism performance.
By
–
New quick video, more coming up
— Ahmad (@TheAhmadOsman) 9 avril 2026
Goal isn't just to show how large models perform but also to show how small and medium models scale up as you multiply # of nodes and how Tensor Parallelism performs on Unified Memory hardwarehttps://t.co/U9XhuLmJHfNew quick video, more coming up Goal isn't just to show how large models perform but also to show how small and medium models scale up as you multiply # of nodes and how Tensor Parallelism performs on Unified Memory hardware
-
User manages and evaluates infrastructure with long-term agents
By
–
I LOVE IT I basically manage and evaluate all my infra using long-term agents at this point
-
AI agent autonomously probes its own multi-GPU setup and stats
By
–
running Qwen3.5 397B MoE (17B active/token)
— Ahmad (@TheAhmadOsman) 9 avril 2026
on 4x DGX Sparks in FP8 (~400GB)
> OpenCode driving
> agent exploring its own config
> probing all 4 Sparks (via ssh) + reporting thermals
> inspecting how vLLM is serving it
> collecting + analyzing its own stats
local AI is awesome https://t.co/KU9u30GgXk pic.twitter.com/yPWSbSKto8running Qwen3.5 397B MoE (17B active/token) on 4x DGX Sparks in FP8 (~400GB) > OpenCode driving
> agent exploring its own config
> probing all 4 Sparks (via ssh) + reporting thermals
> inspecting how vLLM is serving it
> collecting + analyzing its own stats local AI is awesome -
Longing for NVFP4 models to give Blackwell the love it deserves
By
–
I long to the day labs will release their models in NVFP4, not only their BF16 and FP8 Give Blackwell some love friends