
Tried more quants (4-bit, 5-bit) on upstream llama.cpp Next up is benchmarking TurboQuant for the same quants The goal is finding the best quant that fits with the highest context in q8_0/turbo3 asymmetric
@theahmadosman
-
Codex benchmarks models and finds optimal inference engine for your hardware
By
–
The best use of Codex is to make it benchmark models for your hardware and fine you the best inference engine for your hardware stack and model of choice as up-to-date as of April 18, 2026
-
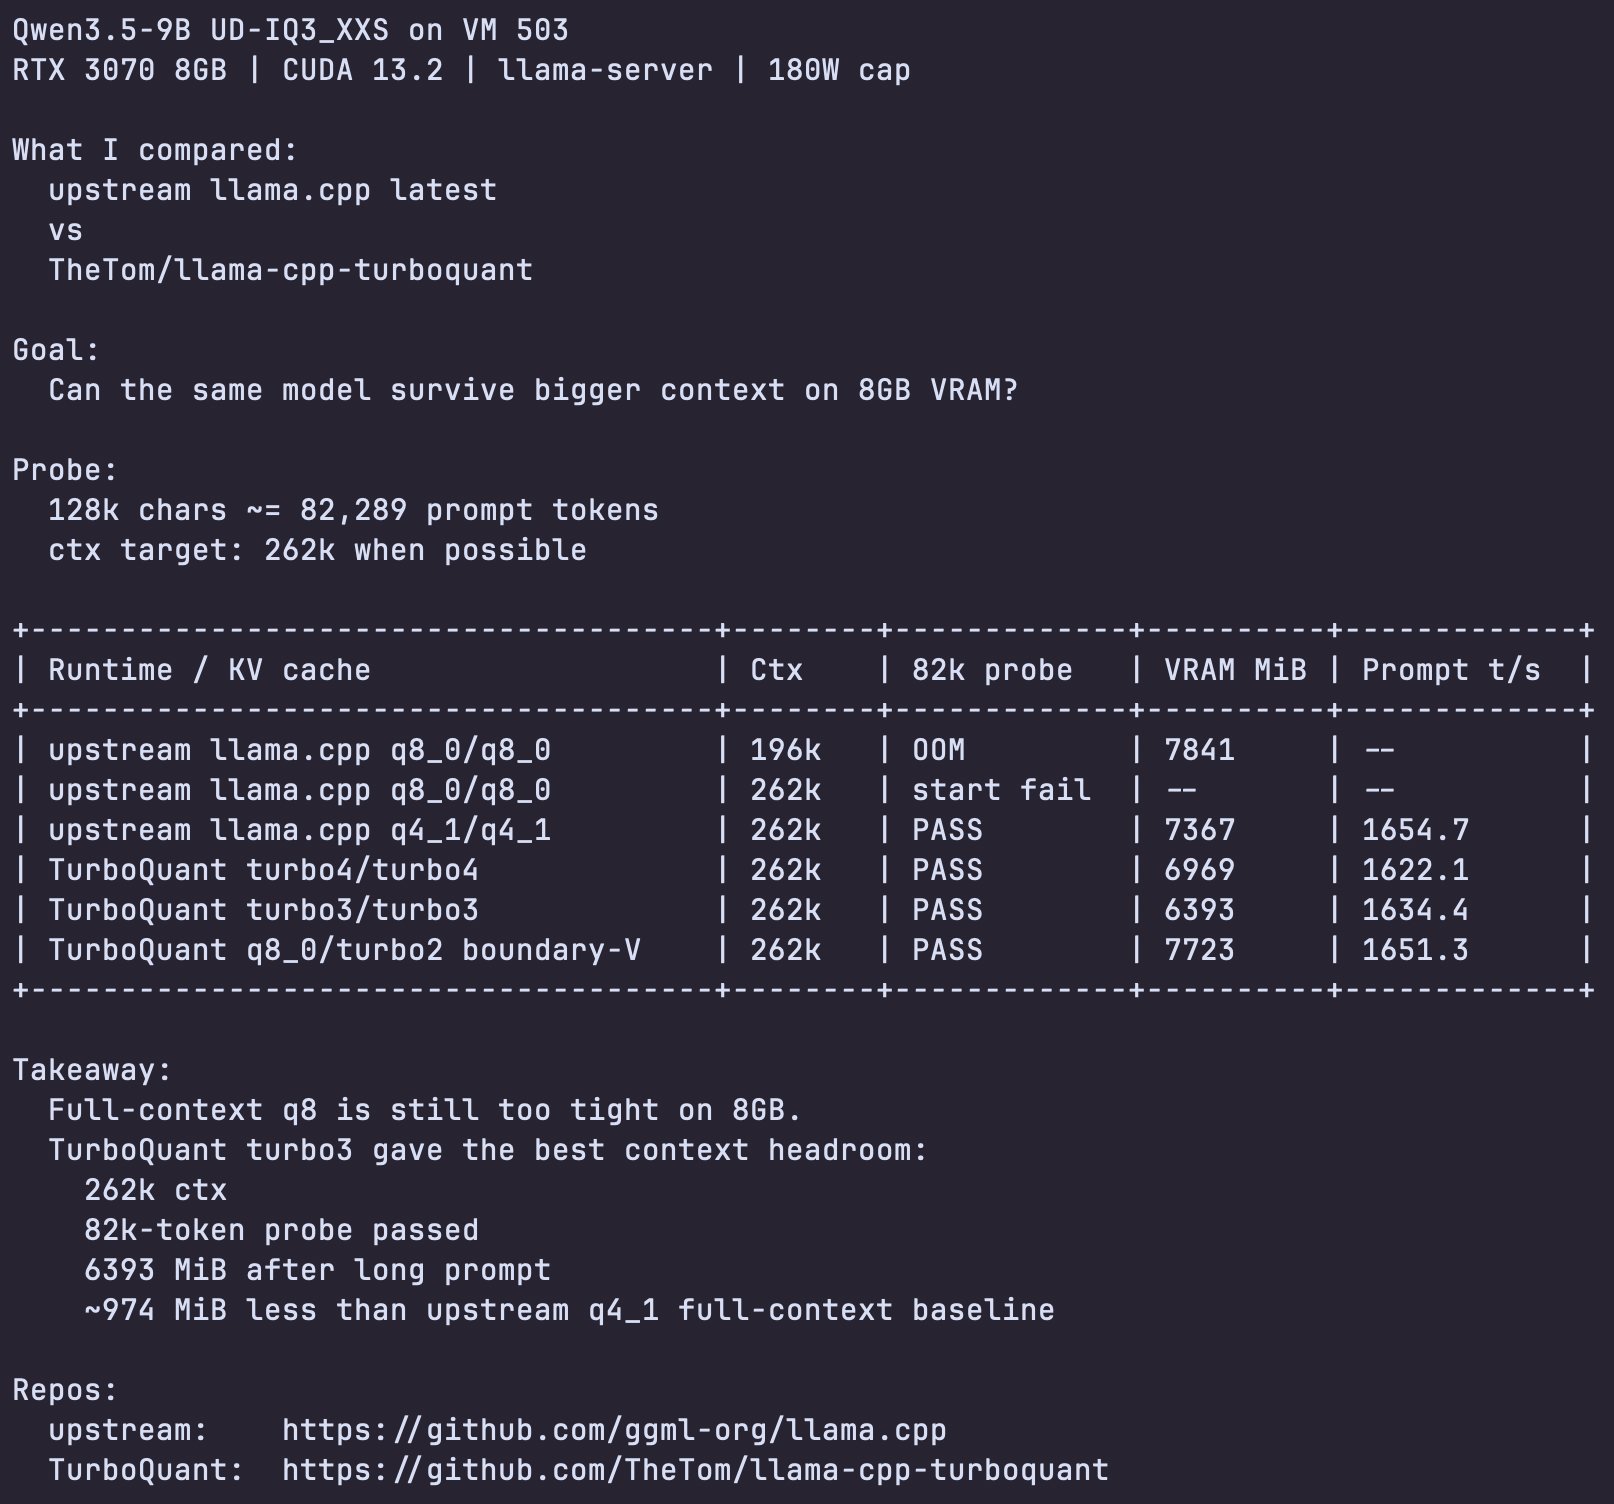
Qwen3.5 9B benchmarked: TurboQuant avoids OOM at full context
By
–
Benchmarked the same Qwen3.5 9B UD-IQ3_XXS GGUF on an RTX 3070 8GB using – Latest upstream llama.cpp VS – TheTom's TurboQuant llama.cpp fork TurboQuant allowed me to reach full context length without OOM, more in the screenshot below
-

Agent and Harness Traceability for Cross-Session Verification
By
–
Agent / harness traceability Allows you to ask an agent to basically remind you of what happened in a previous session and cross-check across different agents / harnesses as well Much needed in this space Repo: eric-tramel/moraine
-
Inference Engines for Local LLMs in 2026
By
–
Article coming up: Inference Engines for local LLMs in 2026
-
Claude Code running with local AI models on home GPU cluster
By
–
Here’s an old video showing Claude Code running w/ local models on my own GPUs at home
— Ahmad (@TheAhmadOsman) 18 avril 2026
> SGLang serving MiniMax-M2.1
> on 8x RTX 3090s
> nvtop showing live GPU load
> Claude Code generating code + docs
> end-2-end on my AI clusterpic.twitter.com/Kj8P3ndOeJ https://t.co/hPqPjwv6aQHere’s an old video showing Claude Code running w/ local models on my own GPUs at home > SGLang serving MiniMax-M2.1
> on 8x RTX 3090s
> nvtop showing live GPU load
> Claude Code generating code + docs
> end-2-end on my AI cluster -
Running GLM-5.1 locally and amazed by its intelligence
By
–
Currently running GLM-5.1 locally Cannot believe this thing is running on my own GPUs, its really smart
-
Local AI made easy with overnight agent tuning and evals
By
–
Let me make local AI easy for you Inference setup & optimization are simple now
across pretty much any Inference Engine Just have an agent run evals overnight
sweep a few quants per GPU / inference stack
and generate bash scripts with best configs Wake up to tuned performance -

GPUs beat Unified Memory for local inference, warns expert
By
–
I have all kinds of hardware, and I can tell you with full confidence that GPUs beat Unified Memory for local inference There's too much hype in this space, please do your research before you spend your hard-earned money
-
MoE models recommended over dense models for unified memory
By
–
Dense models like Qwen 3.5 27B & Gemma 4 31B on unified memory are a bad idea Simple rule: Lower memory bandwidth works best w/ fewer active parameters per token MoE like Gemma 4 26B-A4B would work much faster on Unified Memory