This is honestly a baffling response. You cant be saying that benchmarking FP32 vs TF32 (just the dtype) is a "compiler optimization".
Honestly, I'm lost at the face of so much evidence, how you're just still sticking to your story.
@soumithchintala
-
FP32 vs TF32 Benchmarking: Compiler Optimization Debate
By
–
-
Open Source AI Models Initiative Launches in NYC
By
–
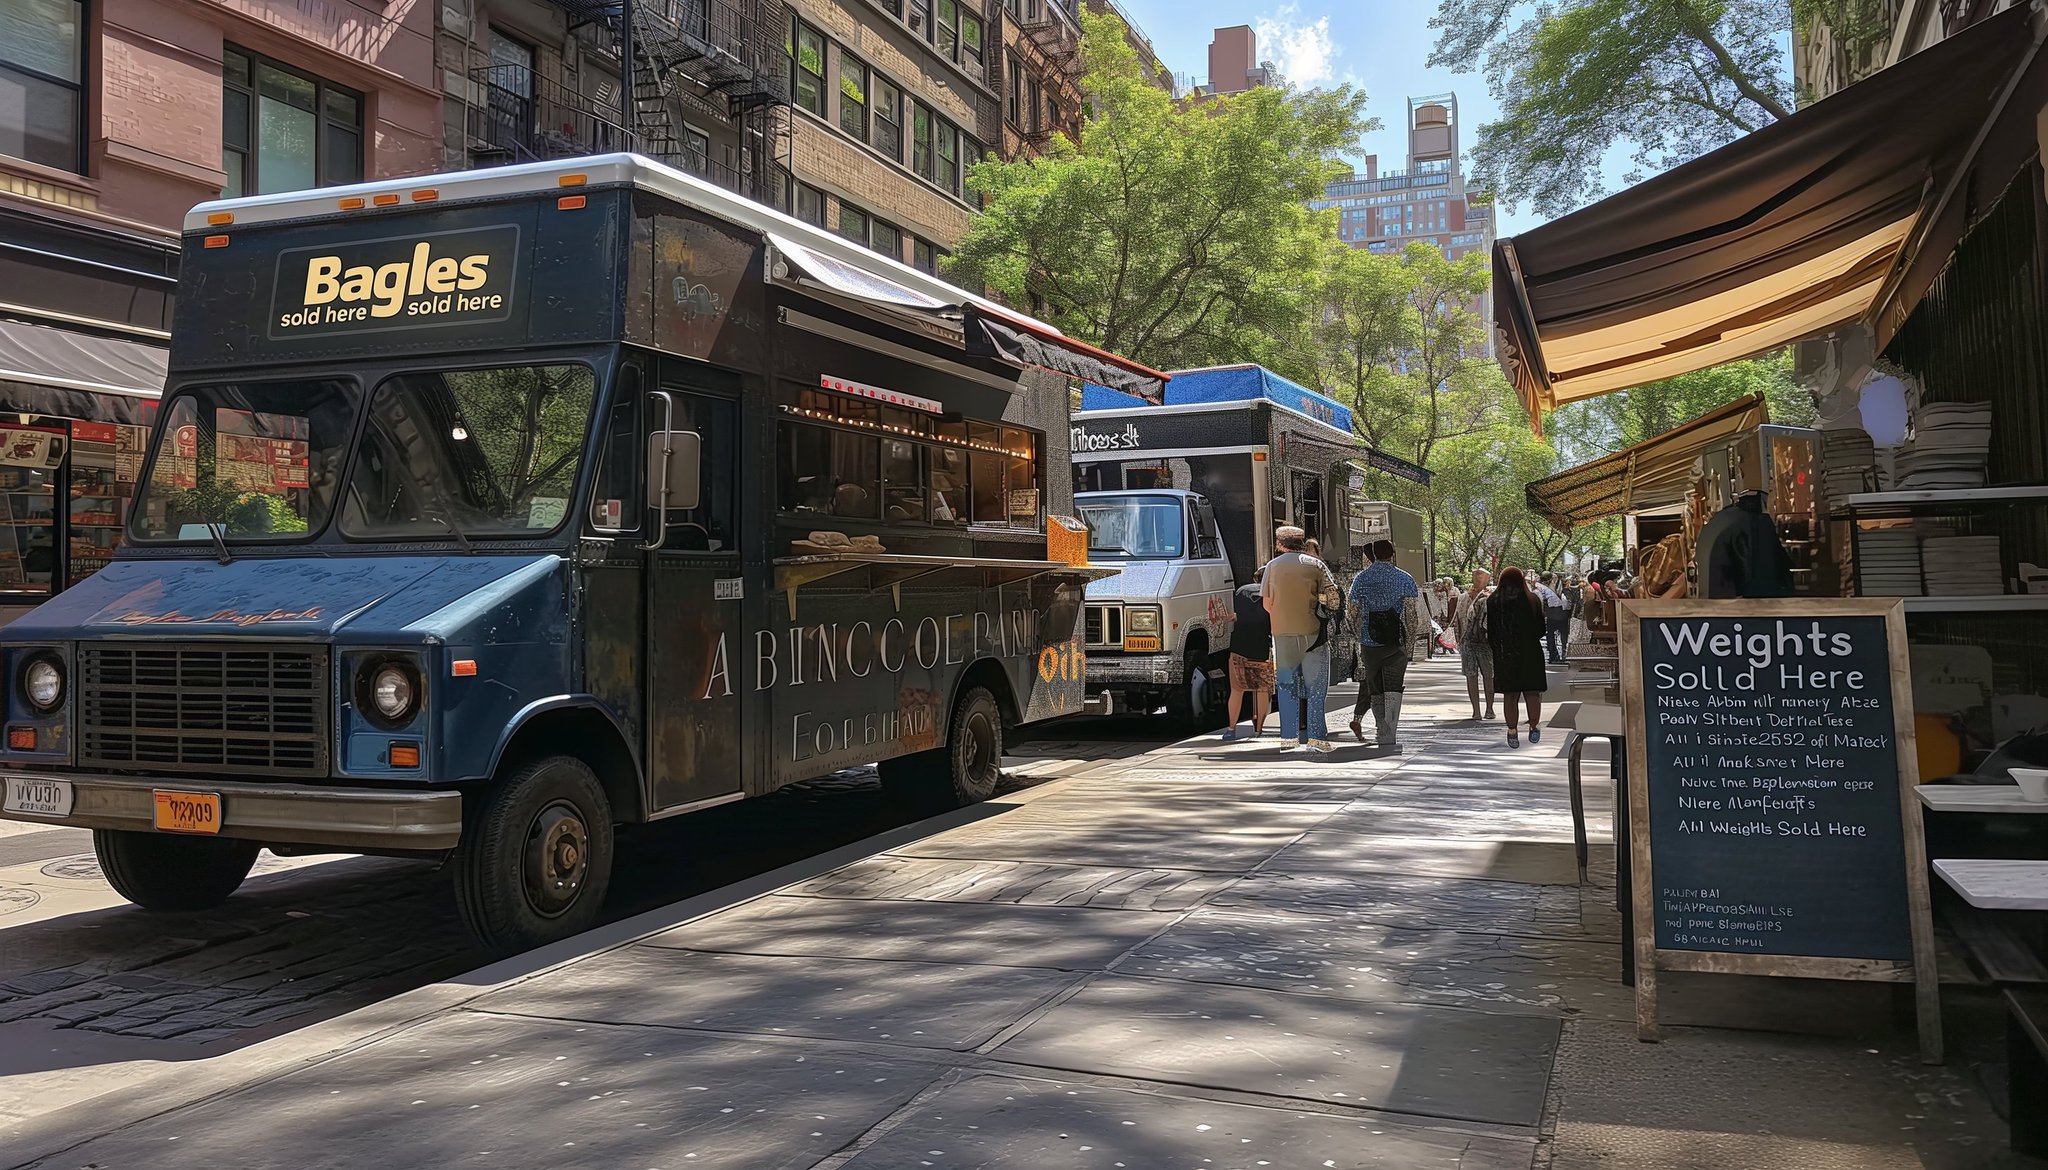
move to NYC.
build open models.
distribute bootleg books of model weights alongside bagels and ice cream trucks. @srush_nlp @kchonyc @jefrankle and I will be around. -
Mosaic Databricks Releases Competitive New Open Model
By
–
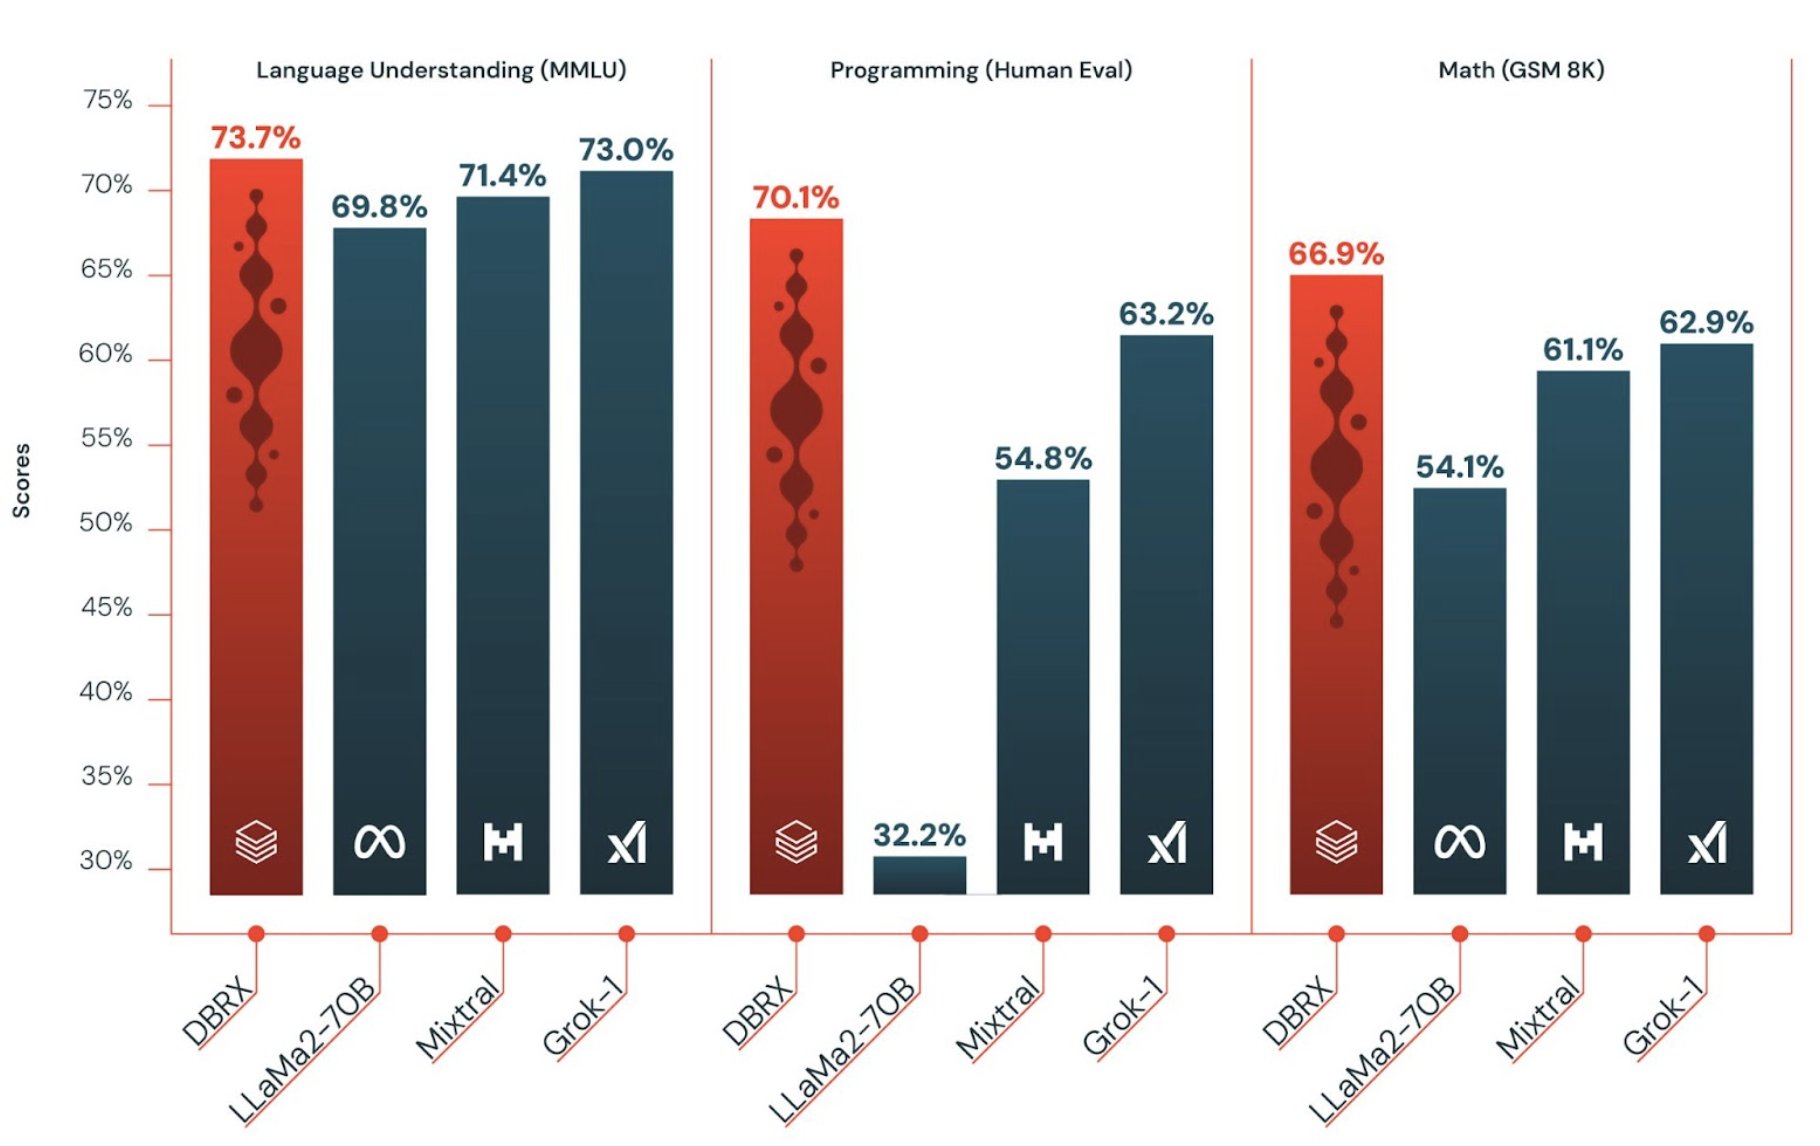
legit new open model just dropped from Mosaic/Databricks.
Seems very competitive on offline benchmarks.
Check it out -
Open Source AI Project Success with torch.compile Integration
By
–
congratulations! excited to see where this goes.
really nice to see it compose with torch.compile. congrats @ThomasViehmann @lantiga @mikeruberry @IvanYashchuk @JirkaBorovec Taylor Robie, Jie and other familiar faces 🙂 -
ImageNet-12 Dataset Fits in DGX GPU Memory Easily
By
–
yes, imagenet-12 classification set is only 200GB compressed. can literally load it into gpu memory on a dgx box easy.
-
Meta Infrastructure Scheduler: Open-Source Limitations and Market Analysis
By
–
its a bigger lift to open-source that, very specific to a lot of how we build Meta Infra.
Also, there isn't a good addressable market, SLURM already exists and is a good HPC scheduler. -
Custom Scheduler vs SLURM for Workload Management
By
–
we have our own scheduler, but I'd assume SLURM would be a good choice as well.
-
Meta’s 24k H100 Cluster Pods Infrastructure for Llama3
By
–
Here's details on Meta's 24k H100 Cluster Pods that we use for Llama3 training.
* Network: two versions RoCEv2 or Infiniband. * Llama3 trains on RoCEv2
* Storage: NFS/FUSE based on Tectonic/Hammerspace
* Stock PyTorch: no real modifications that aren't upstreamed
* NCCL with -
Crowdsourced GPU Cluster Ratings and TPU Comparison
By
–
Great post by Yi.
It's time for crowd-sourced ratings for GPU clusters. Maybe an AirBnB for GPU Clusters. I also tried to explain some of the differences between TPU clusters and most public GPU clusters; as well as made some practical recommendations here: -
XLA-RT and Lower-Level TPU Infrastructure Documentation
By
–
lower layer, as I understand. XLA-RT or something? The lower-level TPU stuff is not well-documented publicly 🙂