Snorkel contributed: • An agentic RL eval environment • FinQA-Reasoning dataset • Finance Reasoning benchmark Full technical breakdown from the rLLM team + our enterprise takeaways here:
@snorkelai
-
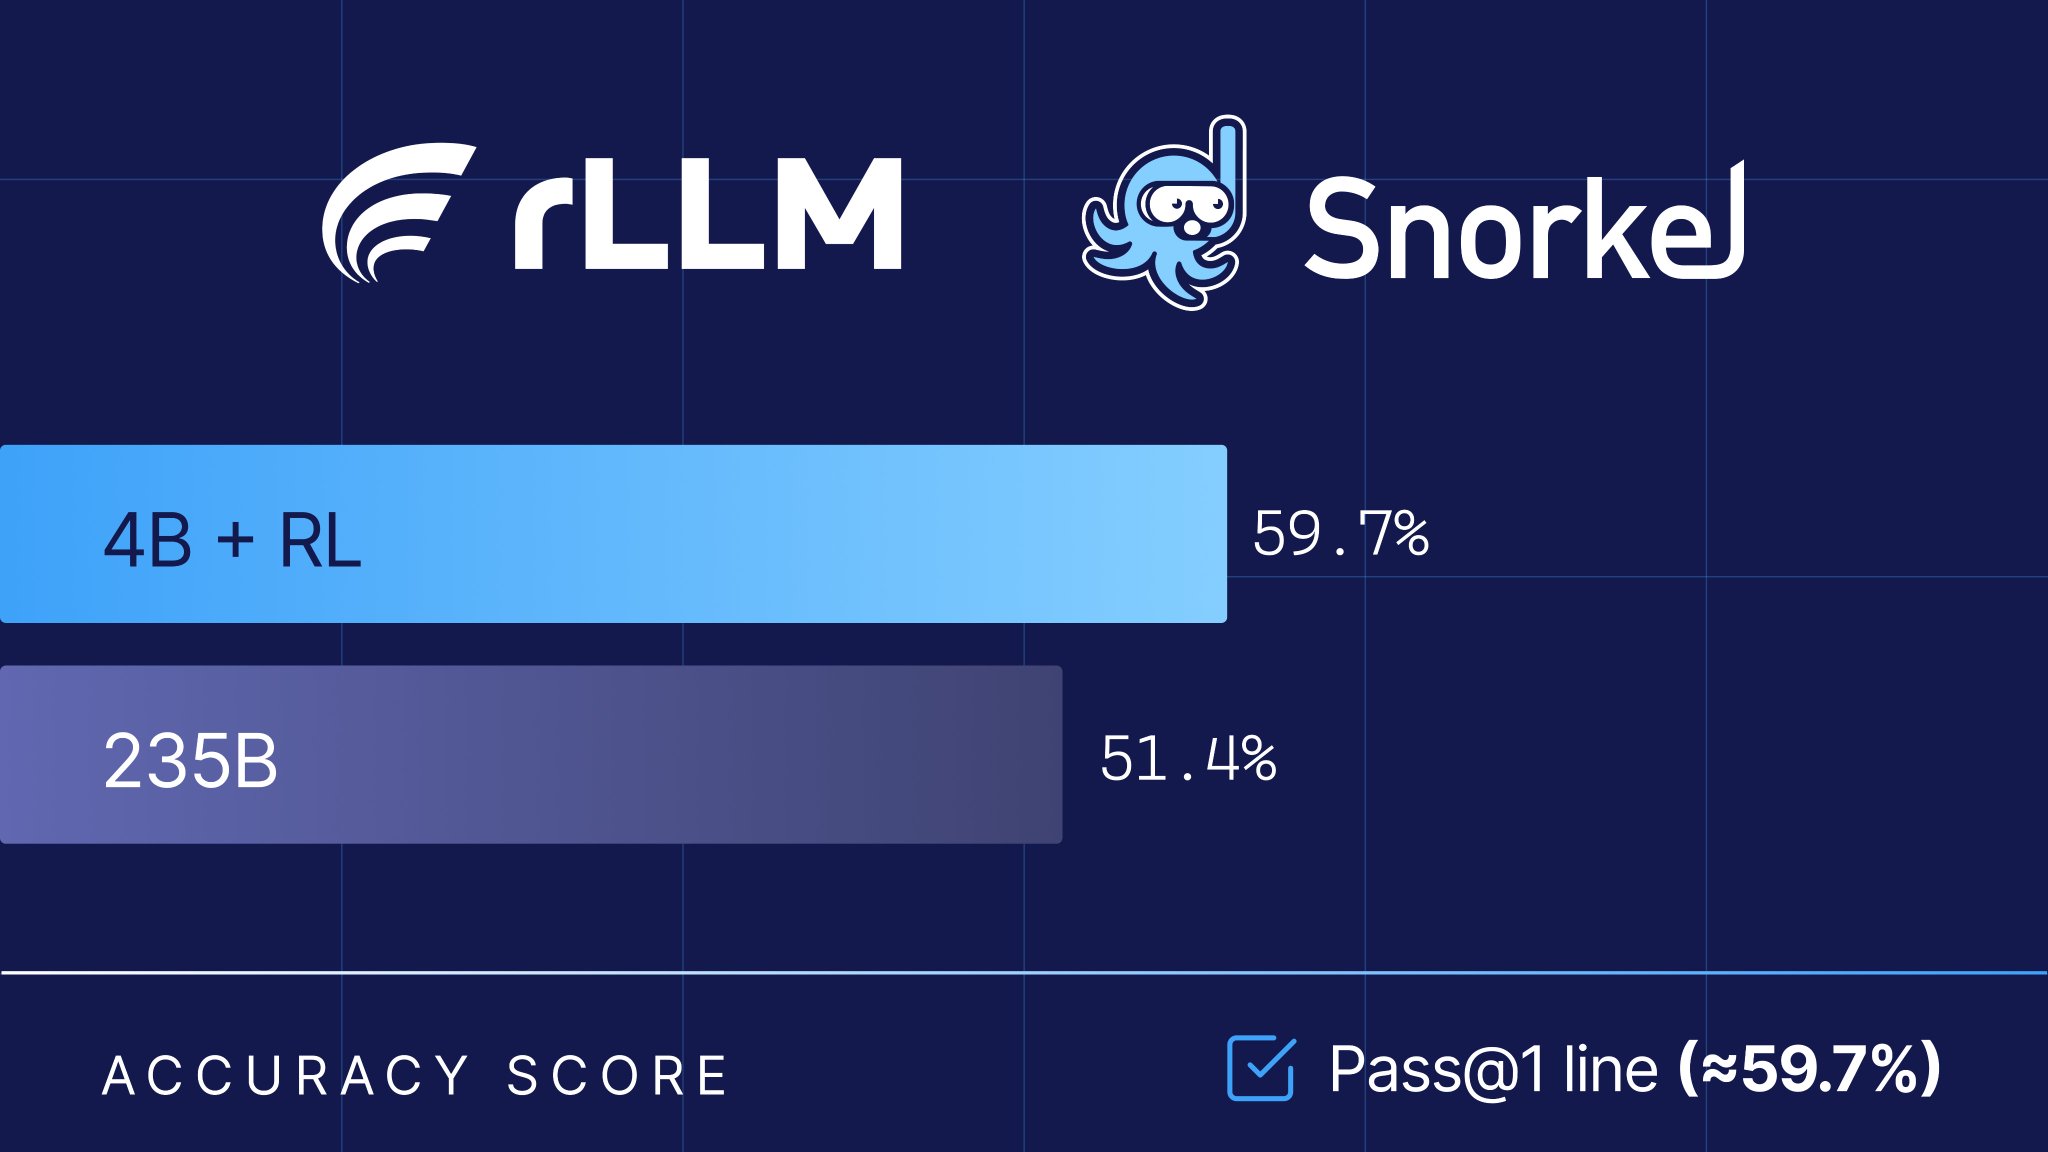
4B Model Outperforms 235B on Financial Reasoning Tasks
By
–
A 4B model > 235B on financial reasoning. We partnered with @rllm_project to fine-tune Qwen3-4B-Instruct-2507 — and it outperformed Qwen3-235B-A22B on expert-curated financial benchmarks.
-
Six Key Insights on AI Long-Horizon Reliability and Autonomy
By
–
We break down 6 key insights that show the way forward to improve long-horizon reliability and greater autonomy. Full analysis from @RamyaRamakri here:
-
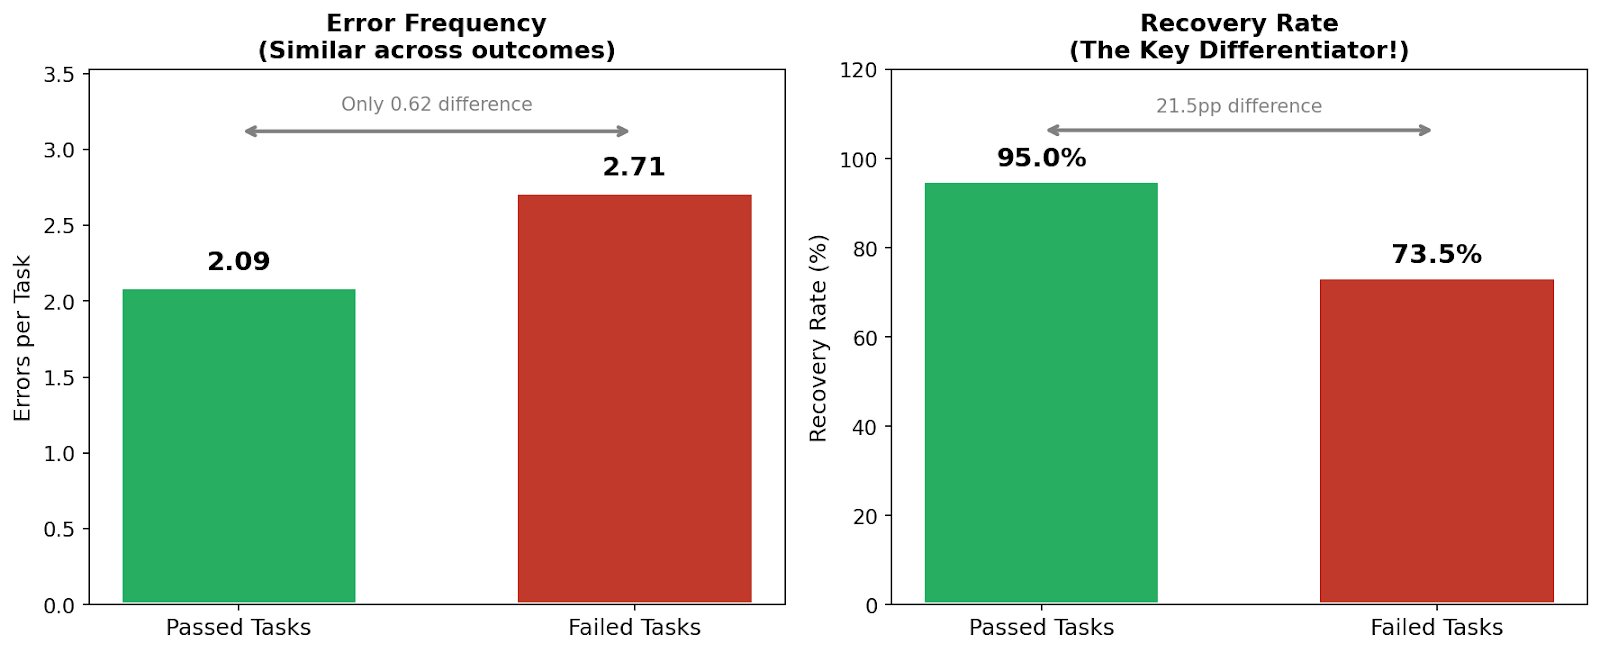
Error Recovery Rate Gap in AI Task Performance
By
–
Passed and failed tasks encounter similar errors (2.09 vs 2.71 per task). The difference? • Passed tasks recover from 95.0% of errors • Failed tasks recover from 73.5% A 21.5-point gap. Recovery > avoidance.
-

Agentic Coding Success: Recovery Matters More Than Error Prevention
By
–
What separates success from failure in agentic coding? Not fewer errors.
Better recovery. We analyzed ~4,000 classified errors across 1,805 Agentic Coding task runs from 8 frontier models. Here’s what we found -

$3M Grants for Open Source Agentic AI Benchmarks
By
–
We’re incredibly excited to launch Open Benchmarks Grants, a new program committing $3M in grants to fund new open source benchmarks advancing agentic AI.
— Snorkel AI (@SnorkelAI) 12 février 2026
We’re partnering up with @HuggingFace, @togethercompute, @PrimeIntellect, Factory HQ, @harborframework, and @PyTorch to… pic.twitter.com/4sXnfHitAOWe’re incredibly excited to launch Open Benchmarks Grants, a new program committing $3M in grants to fund new open source benchmarks advancing agentic AI. We’re partnering up with @HuggingFace
, @togethercompute
, @PrimeIntellect
, Factory HQ, @harborframework
, and @PyTorch to -

Company Sponsors ARC Prize Foundation for AI Reasoning Benchmarks
By
–
We’re proud to sponsor the ARC Prize Foundation (
@arcprize
) —supporting open, enduring benchmarks that reveal where AI still falls short of basic human reasoning.
Excited to join in the support of one of the biggest influences in pushing the frontier of AI. Thanks @fchollet
, -
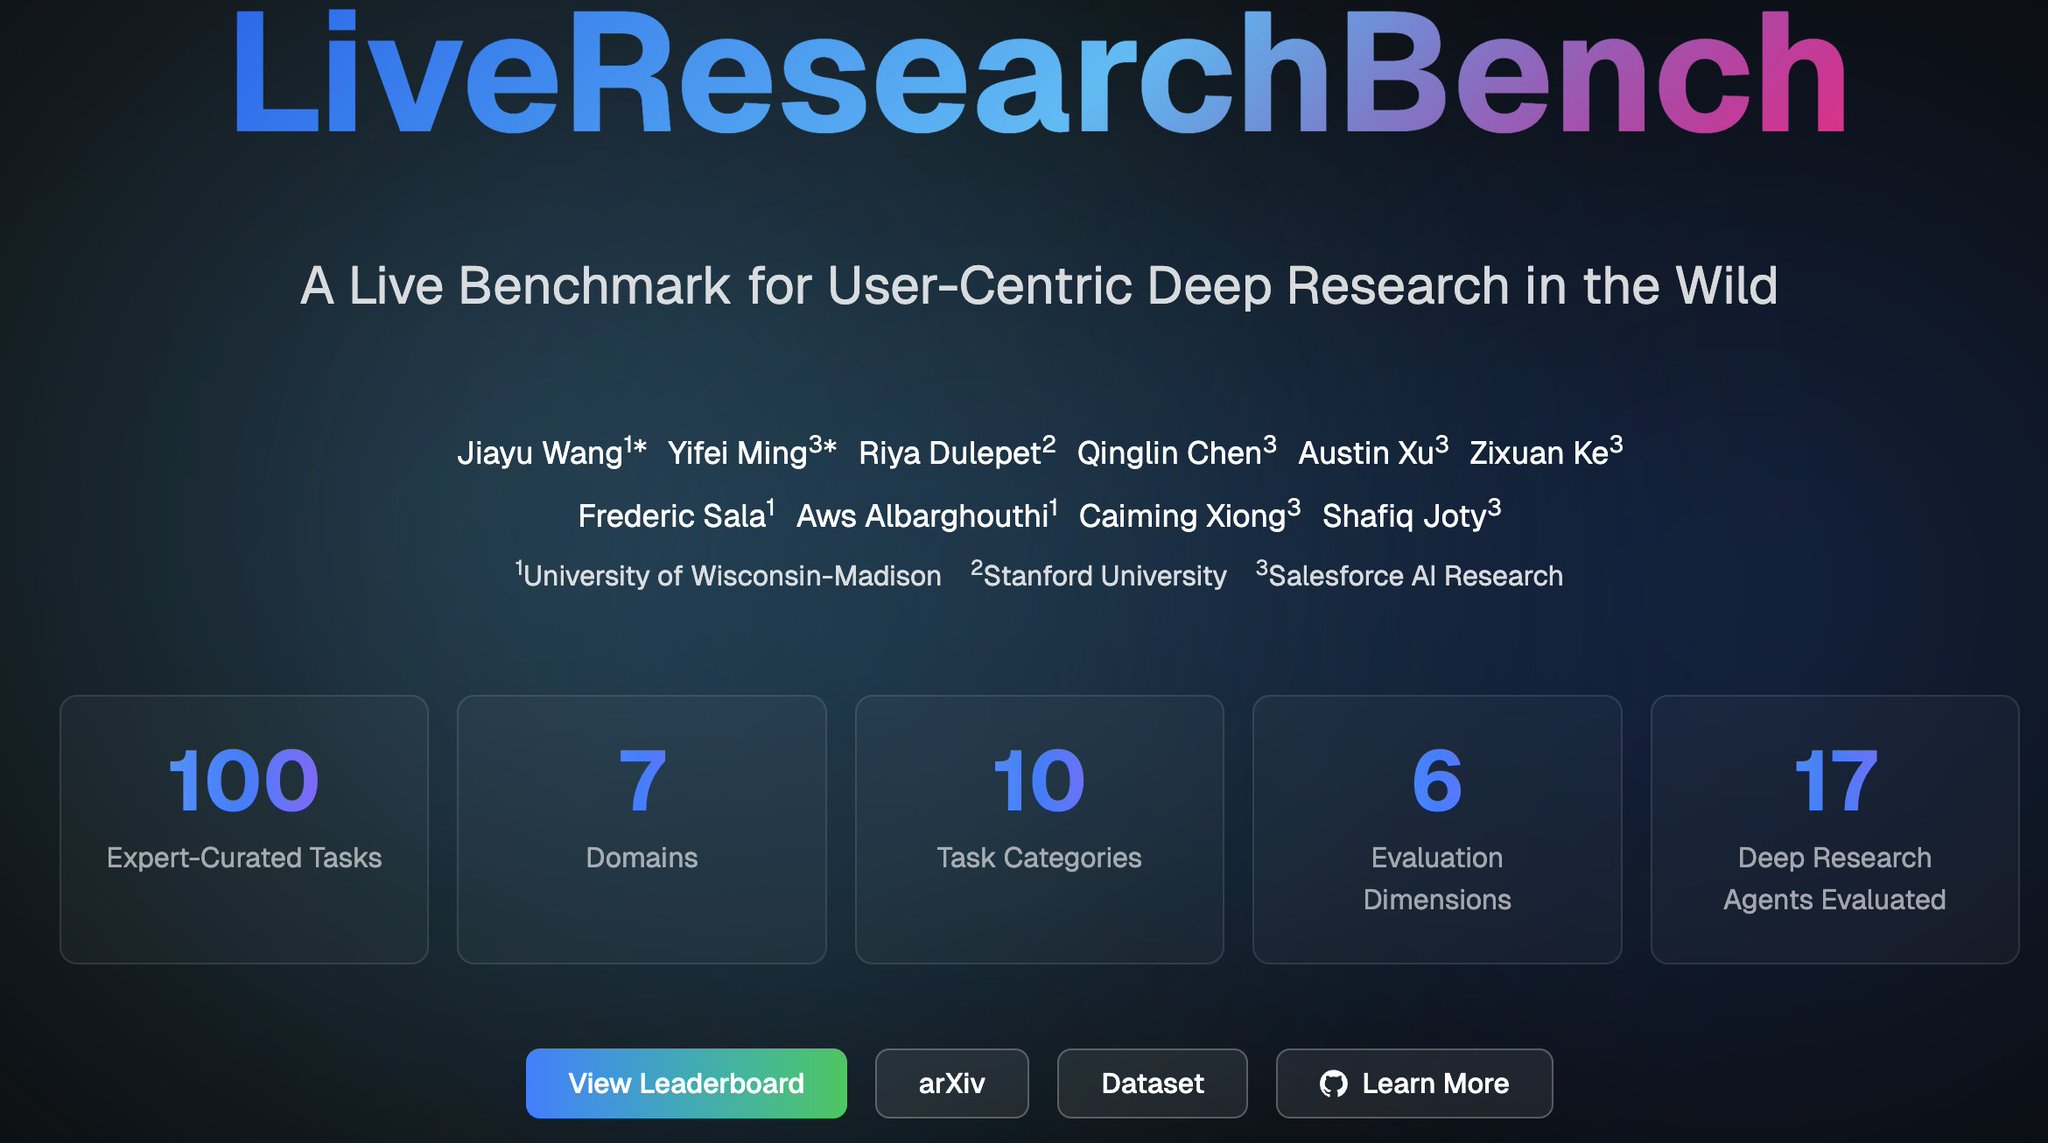
Wisconsin CS Team Benchmarks Accepted to ICLR 2026
By
–
Great to see benchmarks like this! Congrats to @wisconsinCS on this work and the authors on #ICLR2026 acceptance: @jiayuwang111 @ming5_alvin @DulepetRiya @LSearch123
, Austin Xu, @KeZixuan @fredsala @awsTO @CaimingXiong @JotyShafiq Always great partnering across academia and -
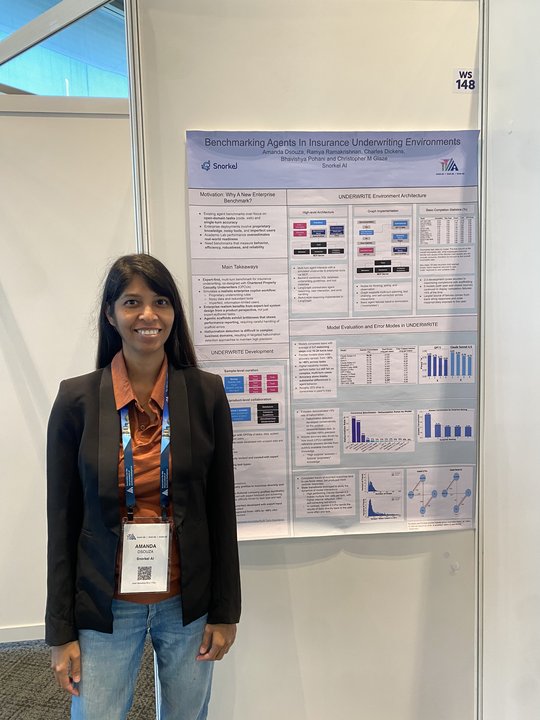
Benchmarking Agentic AI in Insurance Underwriting Applications
By
–
#AAAI26 was a great space for thoughtful conversations around Agentic AI, especially its applications in real-world domains. @amanda_dsouza presented our poster, Benchmarking Agents in Insurance Underwriting Environments at the Agentic AI Benchmarks & Applications workshop. The
-
Data Efficiency Research for RLVR Accepted to MLSys 2026
By
–
Exciting work from our team, studying data efficiency for RLVR. These kinds of insights inform our dataset creation work for foundation model labs. Kudos to @realjustinbauer @pham_derek for this paper's acceptance to #MLSys 2026!