almost same, though I fire off a lot of codex web queries from chat
@reach_vb
-
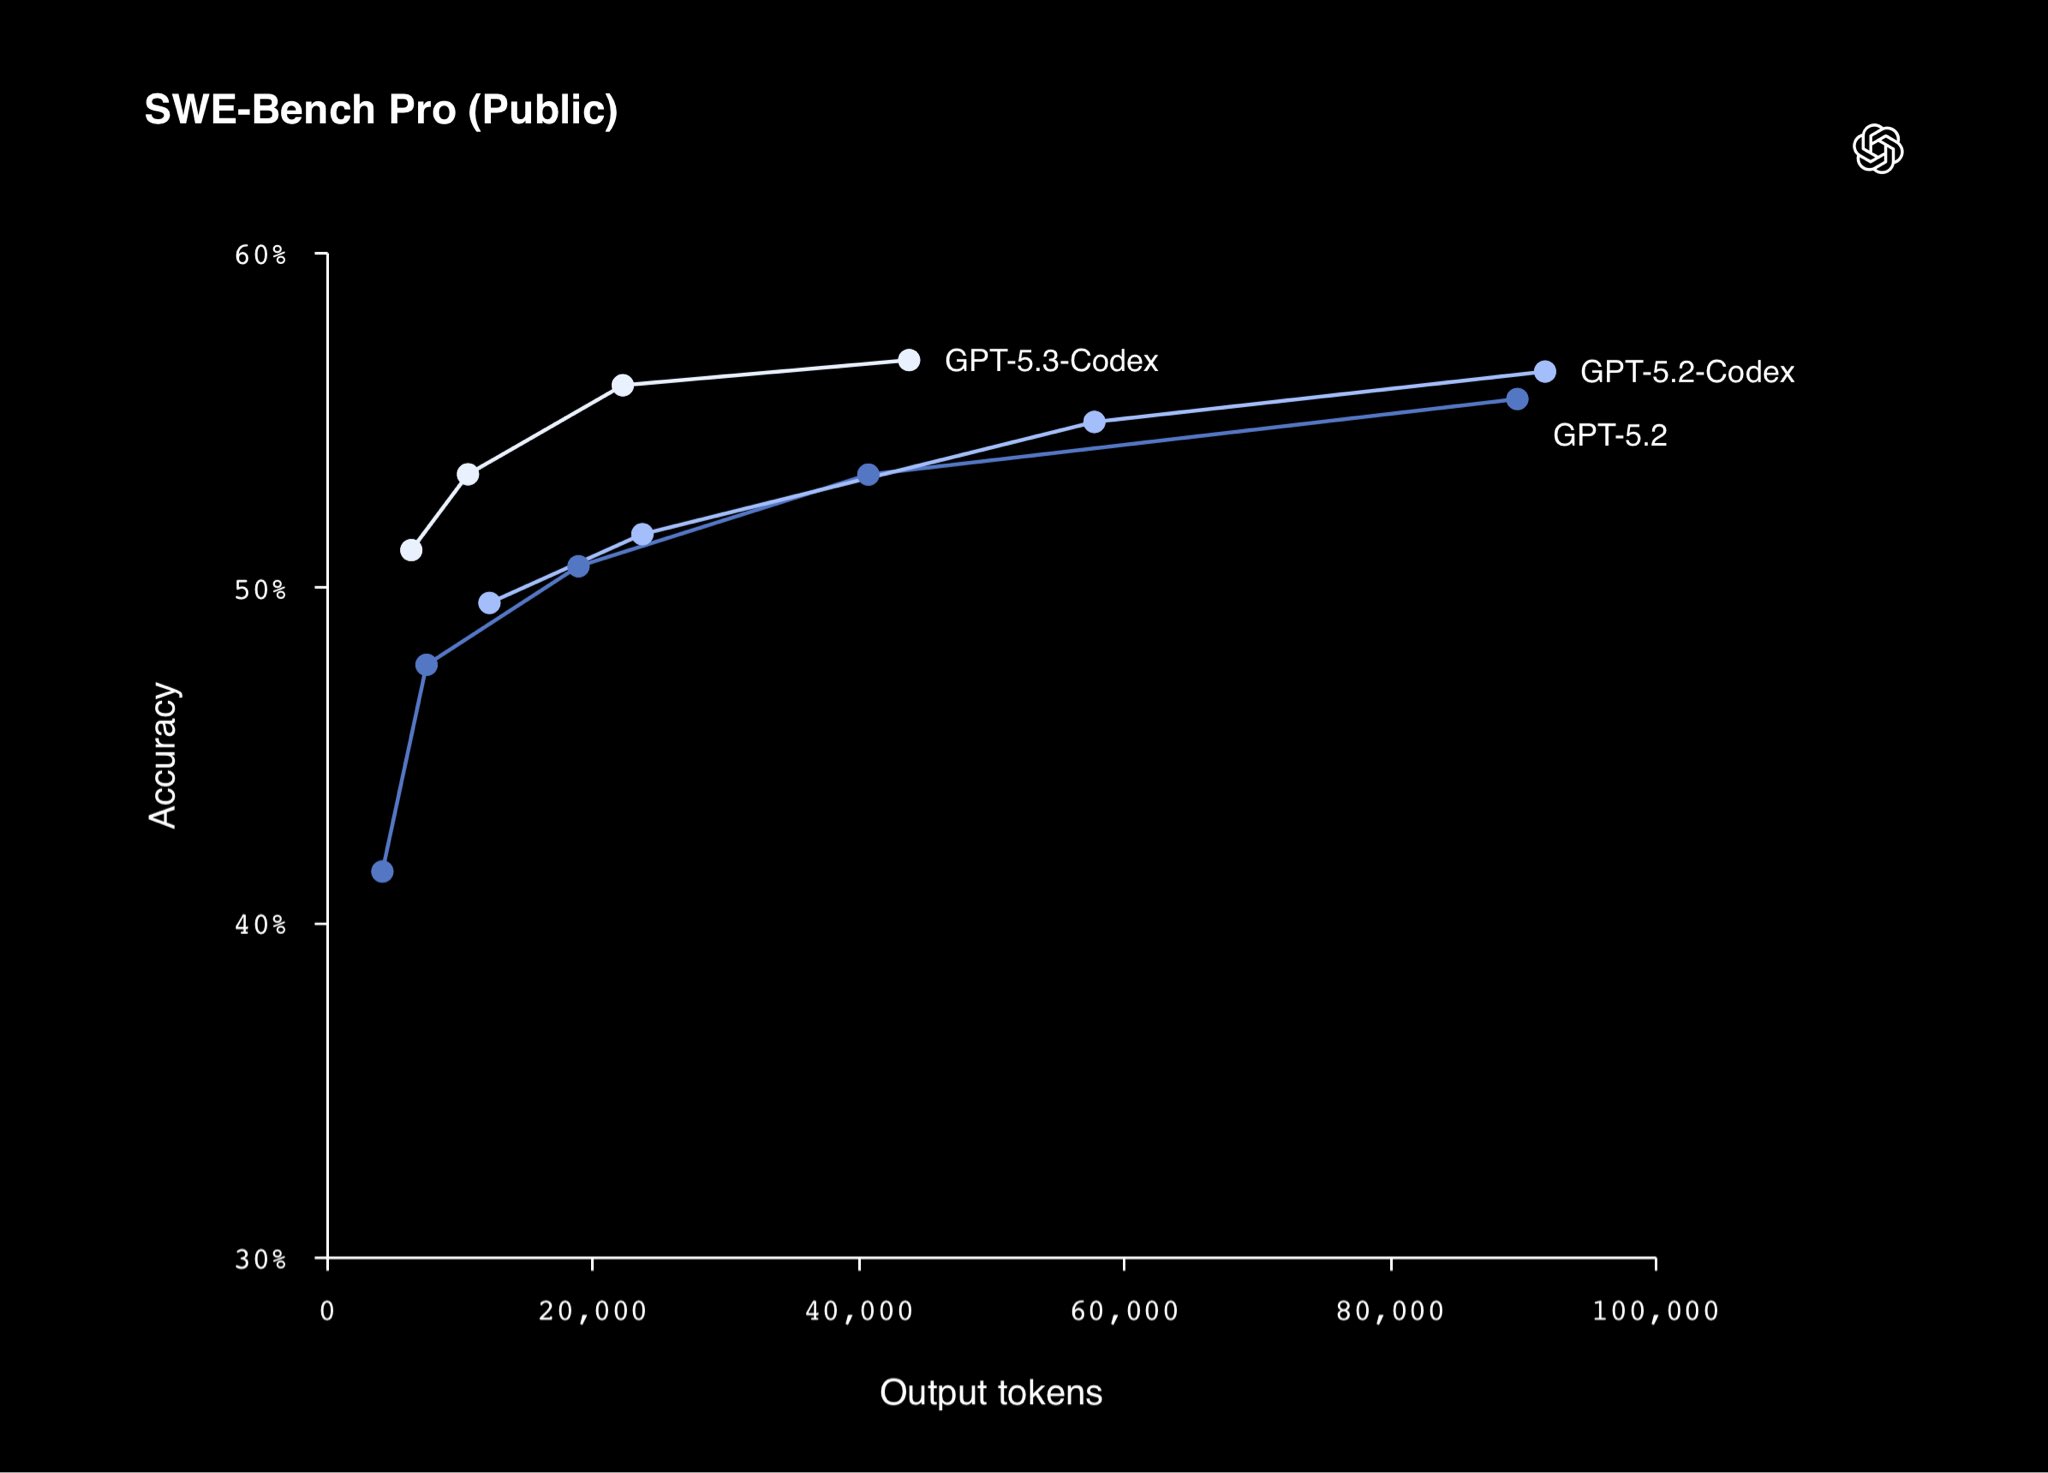
GPT-5.3-Codex Achieves Better Performance Lower Token Output
By
–
GPT-5.3-Codex delivers better performance at considerably lower token output (faster and better) Token efficiency ftw!
-
Team Focus on Material Improvements in AI Development
By
–
active focus area for the team atm, material improvements coming soon
-
Debugging AI Sessions: Codex Pattern Analysis Tips
By
–
hey Scott – any repeatable patterns or something specific tripping you up? tip: you can point codex to your sessions and ask it to analyse them and point out prospective issues DMs open if there’s anyway we can help make the experience better
-
Using AI coding assistants to automate utility app development
By
–
This! I’ve had so much fun building small utility apps for tracking expenses, keeping track of investments and chores Codex makes it significantly easy to build apps and interacts quite well with xcodebuild CLI to automate & screenshots skill to help close the loop
-
Technical troubleshooting of ChatGPT API and model availability
By
–
The error makes sense since 5.3-Codex is not available via API (yet) Though if you're on API Key it shouldn't show you the 5.3 Codex option in the first place or is this happening when you "Sign in w/ ChatGPT".
-
Customizing AI Assistant Personality and Instructions
By
–
not sure if you’ve tried this but you can change the personality w/ “/personality” – there’s two options “friendly” and “pragmatic” (default) in addition to that you can add custom instructions that you want codex to follow and it nudges its responses towards that
-
Automating Task Management with AI Agents
By
–
I have a similar setup with automations in codex app which reads slack DMs to myself which has an ever so growing list of things I’d like to do. Codex looks through the DMs, breaks it into independent issues. Refines the issue and adds more context. Opens a Branch/ PR for it.
-
AI Model Inference Speed Increased by 30 Percent
By
–
Our fastest model just got 30% faster! ~1200 tokens per second
-
The impact of llama.cpp on LLM proliferation and accessibility
By
–
I'd go to the extent that if it wasn't for @ggerganov and llama.cpp contributors we'd have significantly less proliferation of LLMs in day-to-day! He really kick started a revolution back in 2023