Nice, I haven't seen that, yet! Thanks for the ping! Should probably reference that in the confidence interval section of my new Machine Learning Q and AI book
@rasbt
-
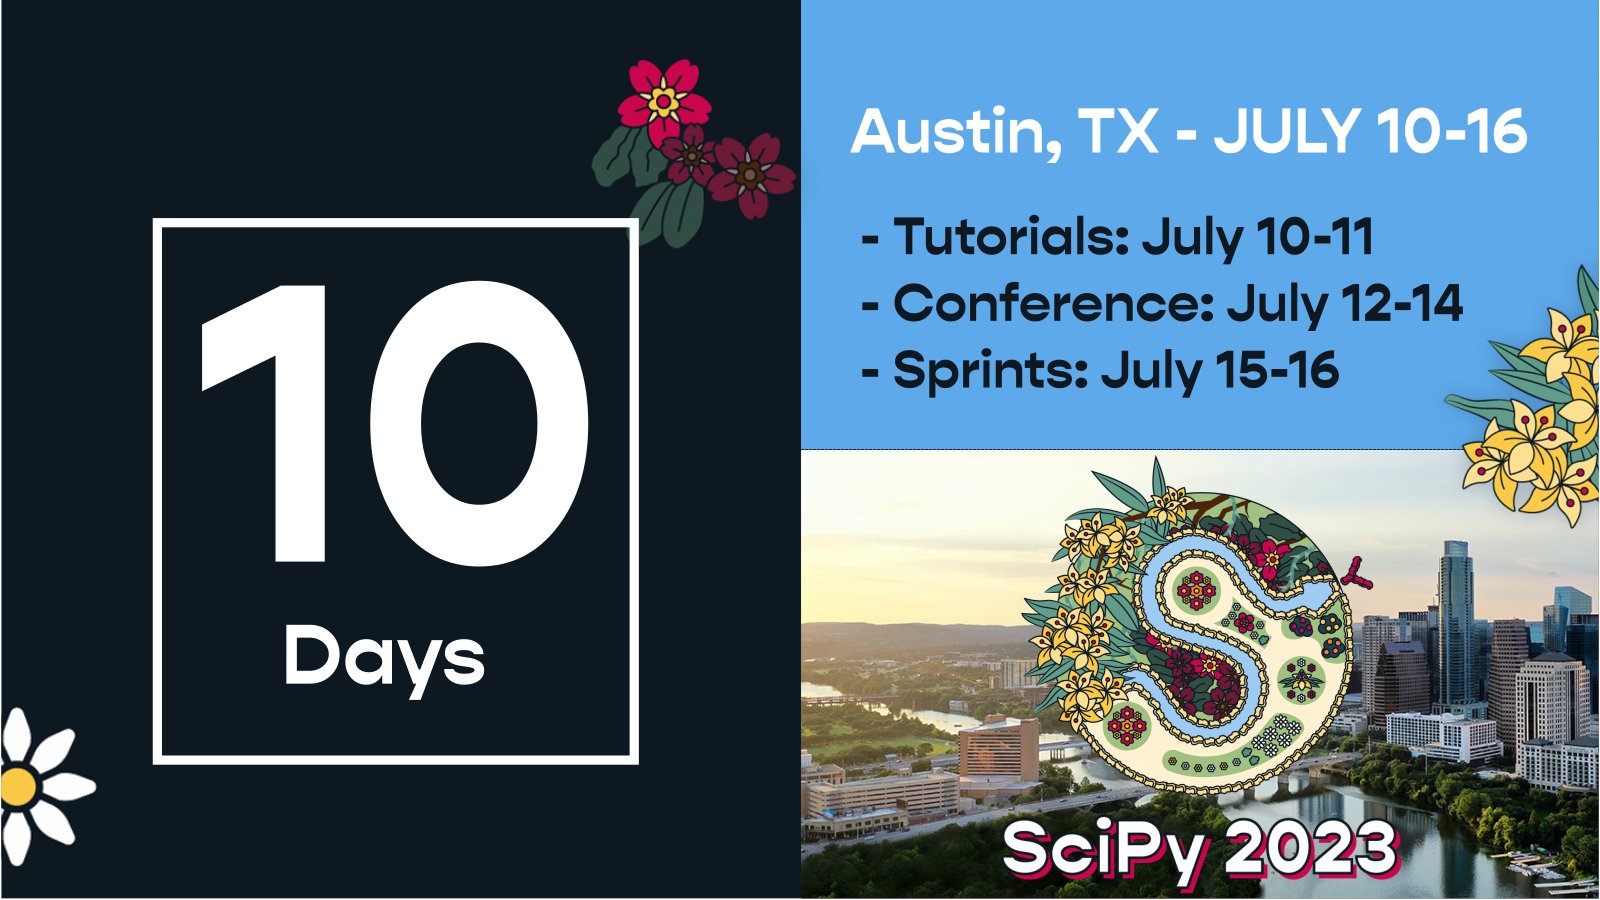
Attending favorite computing conference and preparing deep learning tutorial
By
–
Pretty excited to me attending my favorite computing conference once more! If I’ve been a bit quiet on socials lately that’s because I’m head down working on my deep learning tutorial for SciPy in a bit more than a week! Hope to see you there!
-
Specialized AI assistants preferred over general purpose for business
By
–
That’s only true for general purpose assistants. But for most business applications, you don’t want “general purpose”
-
Strategic Synthetic Data Generation Beyond Random Sampling
By
–
Synthetic data is a broad term. I think the paper looks at a very extreme case. One can blindly generate synthetic data by sampling from an upstream model. But yeah, I can see how being more strategic than that can actually be beneficial.
-
Questioning the Curse of Recursion Paper’s Future Relevance
By
–
For more context, since I didn't see a link in the article, are we talking about the "The Curse of Recursion: Training on Generated Data Makes Models Forget" paper? (
https://
arxiv.org/abs/2305.17493) And the claim is that the findings in this paper don't / won't hold in the future? -
OpenAssistant’s shift from RLHF to supervised instruction-finetuning
By
–
So on that note, OpenAssistant's earlier models used RLHF for instruction-finetuning (
https://
huggingface.co/OpenAssistant/
oasst-rlhf-2-llama-30b-7k-steps-xor
…); The later one seem to use supervised instruction-finetuning. Maybe @ykilcher has some insights whether RLHF wasn't worth the effort vs supervised? -
RLHF versus Supervised Instruction Tuning Clarification
By
–
Isn’t RLHF also instruction finetuning? You mean supervised instruction tuned?
-
Data Compensation for Commercial AI Training: Need Government Guidance
By
–
I am in strong favor of compensating those whose data was used for training if it’s purely for commercial (vs research or educational) purposes. But wouldn’t it make sense to have a state-/government-issued guidance (like Japan did) before wasting time & money on these lawsuits?
-
FlashAttention and KV Caching for Improved Model Performance
By
–
No, absolutely. But I think for this it's maybe worthwhile adopting methods that don't negatively impact modeling performance, like FlashAttention and kv caching.
-
State-of-the-Art Models First, Efficiency Through Distillation Later
By
–
For most, the goal is to push the state-of-the-art and show that these models can achieve impressive results. You can always distill models later to make them more efficient.