According to "Lost in the Middle: How Language Models Use Long Contexts" (
https://
arxiv.org/abs/2307.03172) LLMs are good at retrieving information at the beginning of documents. They do less well in terms of retrieving information if its contained in the middle of a document. 2/5
@rasbt
-
LLMs Struggle Retrieving Information from Document Middle
By
–
-
ChatGPT Limitations in Research Summary Writing
By
–
I must say I would use ChatGPT with a grain of salt. I tried that for doing the research highlights in my newsletter (like https://
magazine.sebastianraschka.com/p/ai-research-
highlights-in-3-sentences-2a1
…) but yeah, next to the occasional mistake it didn't always pick the most relevant parts so I am sticking to manual summaries. -
Interest in long context methods performance on transformer tasks
By
–
Hah, it just came out yesterday and I haven't had a chance to read it. They pose an interesting question! I think they are analyzing regular self-attention transformers, so yeah, it would indeed be interesting to know how these "long context methods" perform on these tasks.
-
BigBird Encoder vs Decoder LLM Architecture Comparison
By
–
It's been a while and would have to check again, but wasn't BigBird a encoder LLM? Versus this is a decoder-style LLM for generating texts. But generally yes!
-
LongNet: Scaling Transformers to 1 Billion Tokens with Dilated Attention
By
–
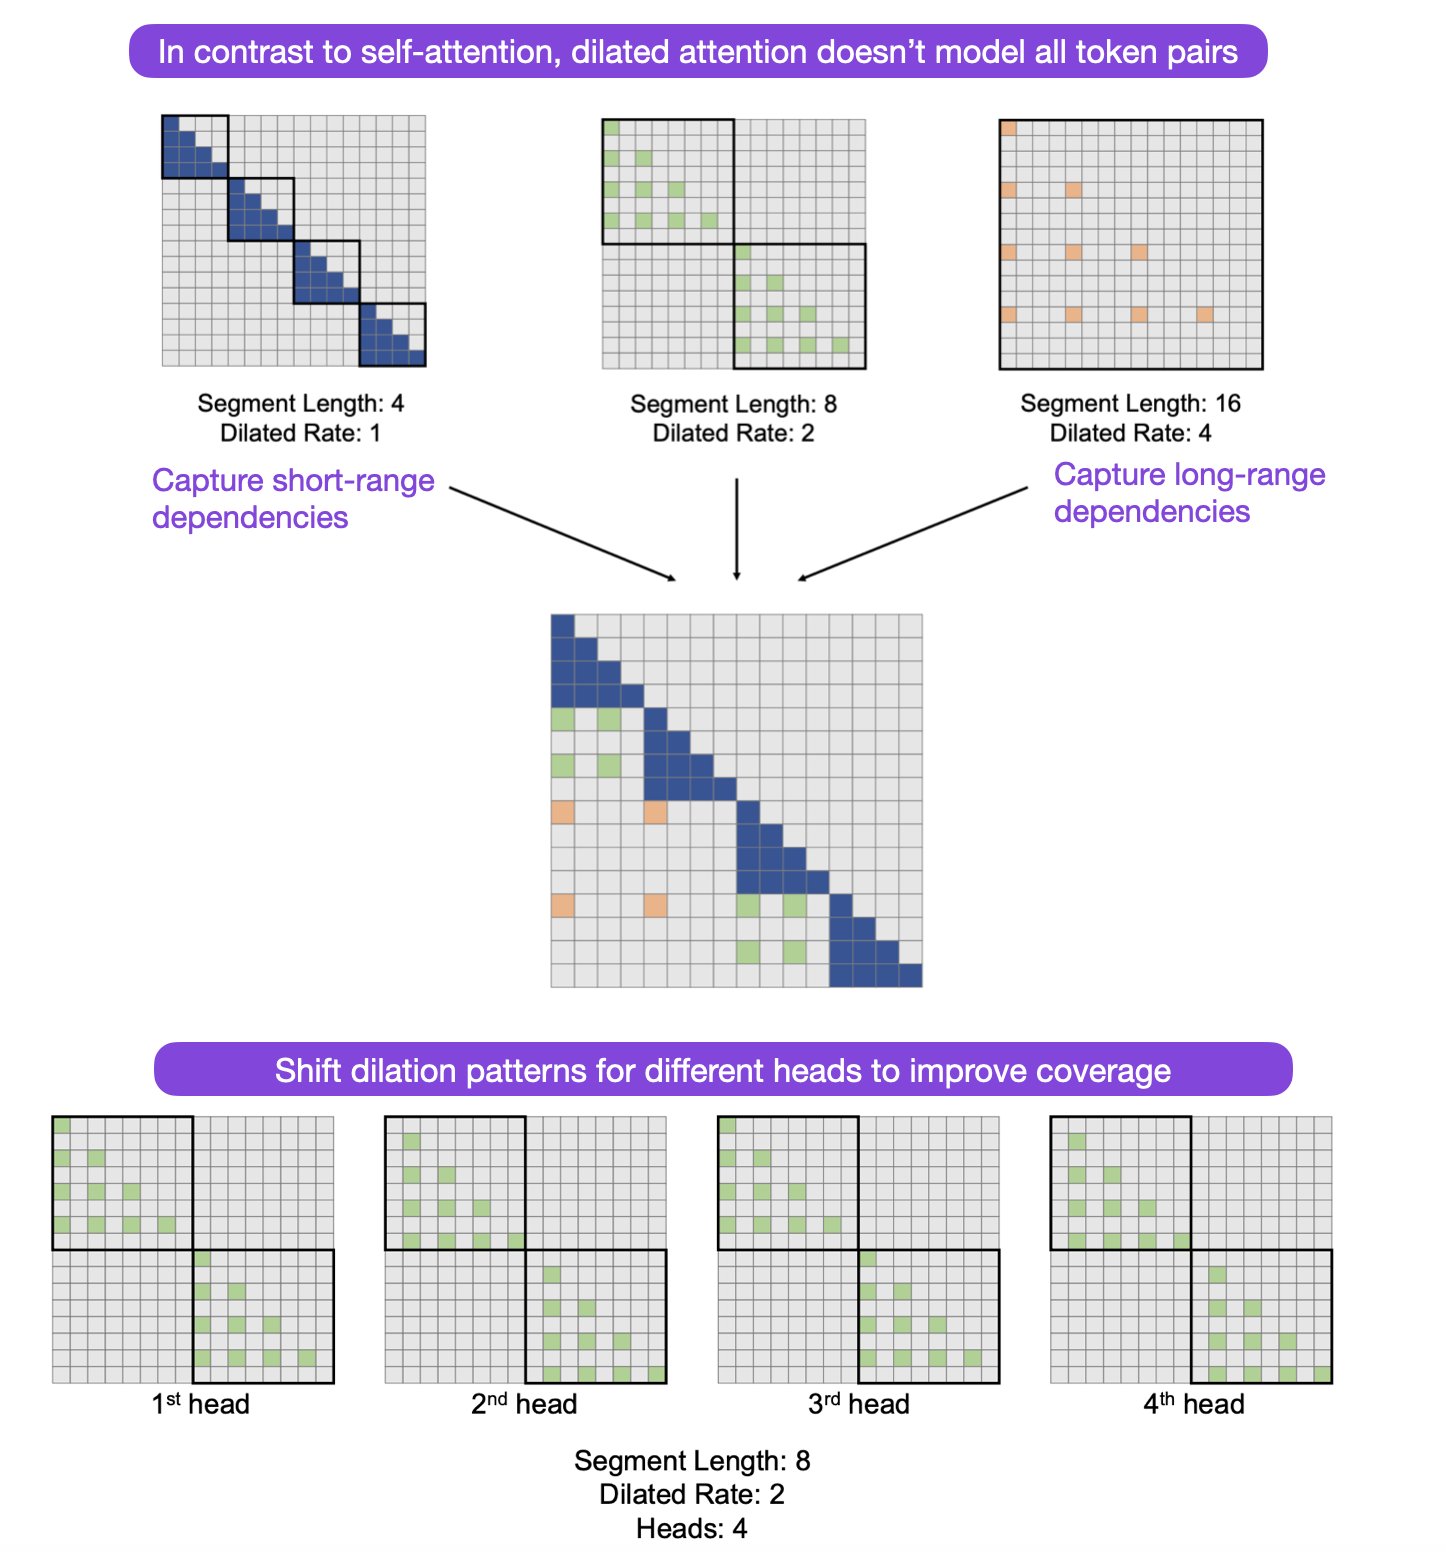
We had 1) the RMT paper on scaling Transformers to 1M tokens, and 2) the convolutional Hyena LLM for 1M tokens. How about 3) LONGNET: Scaling Transformers to 1 Billion Tokens (
https://
arxiv.org/abs/2307.02486)!? It achieves linear (vs quadratic) scaling via dilated (vs self) attention. -
Open Source Algorithm vs Trade Secrets Claims
By
–
Not sure what they include in "trade secrets", but last time I checked "the algorithm" was open source
-
Memory-Lowering Techniques for PyTorch Hardware Optimization
By
–
Depending on the hardware, and next to parameter-efficient finetuning, there are a bunch of memory-lowering techniques you can try. Summarized them here: https://
github.com/rasbt/pytorch-
memory-optim
… -
LLM Guidelines for Training, Finetuning, and Inference
By
–
I am not aware of a guideline, but it usually also depends on what you are after: (pre)training, finetuning, inference. We have a unified codebase for several LLMs you can try here: https://
github.com/Lightning-AI/l
it-gpt
… -
ViT-everything: Summarizing the main theme
By
–
Thanks! Hah, and to maybe summarize the main theme so far: ViT-everything!
