3/3
Here are the papers for reference: Llama 2: Open Foundation and Fine-Tuned Chat Models: https://
arxiv.org/abs/2307.09288 DeBERTa: Decoding-enhanced BERT with Disentangled Attention: https://
arxiv.org/abs/2006.03654
@rasbt
-
Reference Papers for Llama 2 and DeBERTa Models
By
–
-
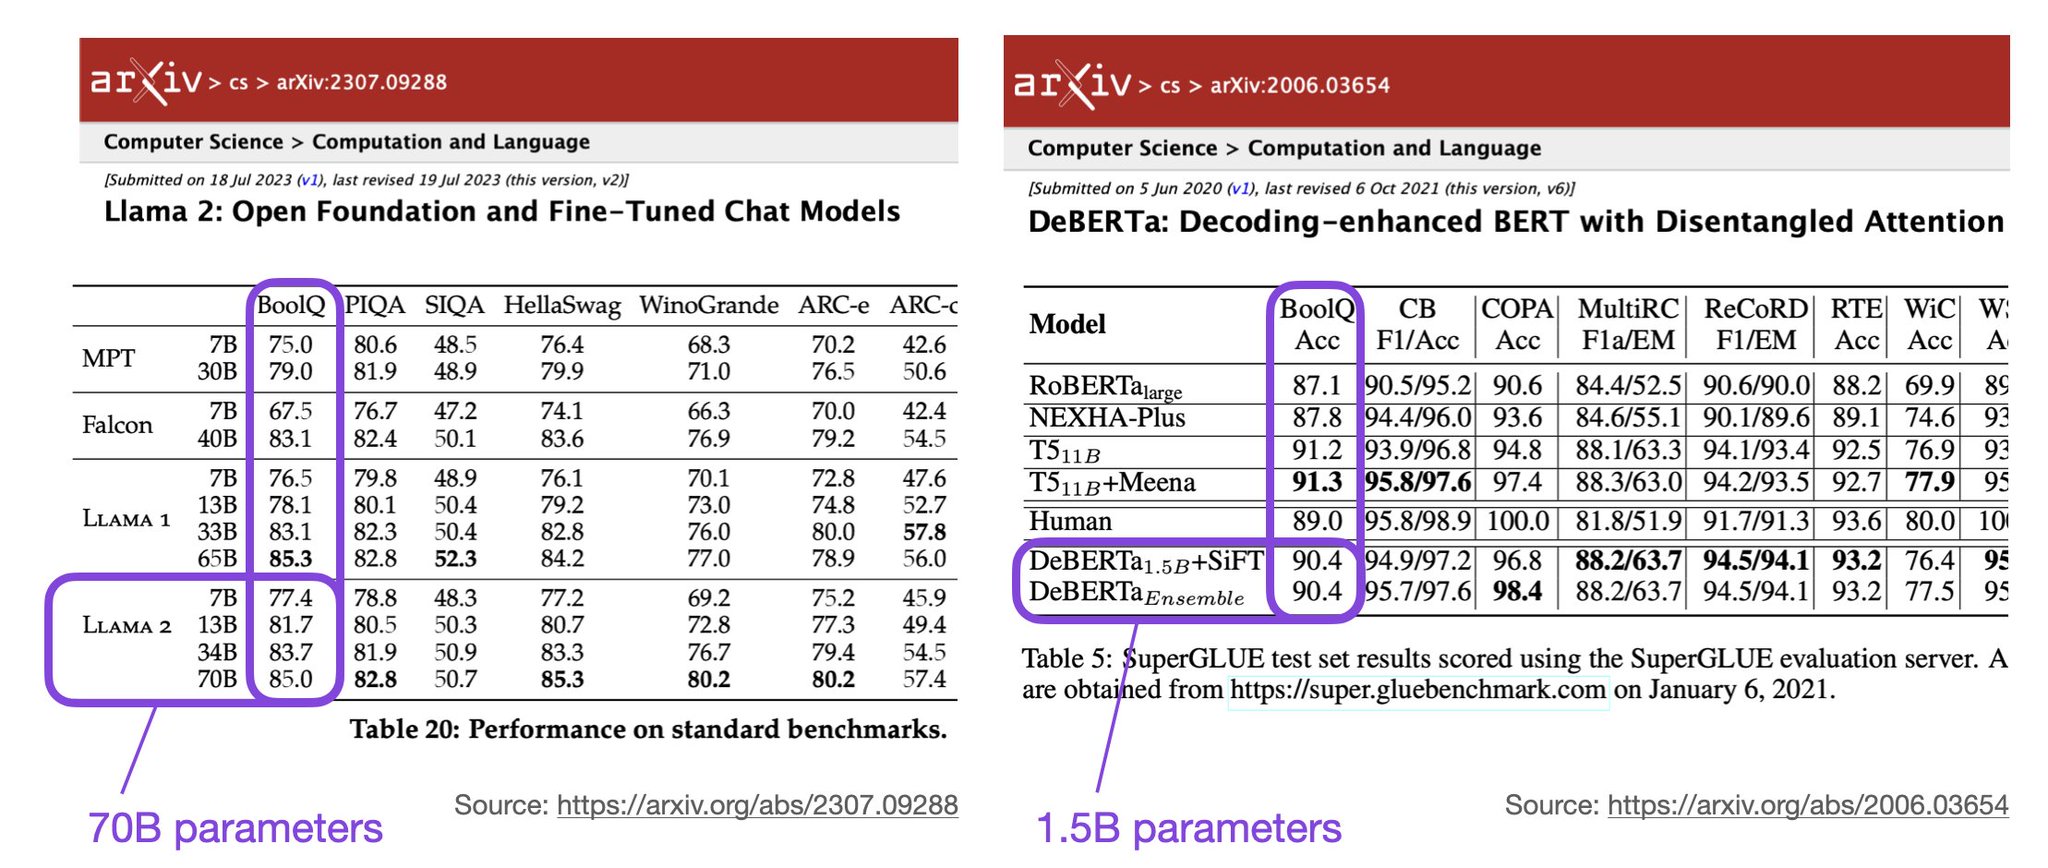
DeBERTa-1.5B Outperforms Llama 2 on BoolQ Classification Task
By
–
Interestingly, DeBERTa-1.5B (and encoder-only model) beats Llama 2 on BoolQ, which is a nice example that encoders still outperform large decoders on classification task. For fairness: The DeBERTa-1.5B model was likely finetuned on the training data 1/3
-
RLHF and Encoder Modules in Decoder Architectures
By
–
Sure I don’t disagree, but since all these were before RLHF finetuned decoder architectures, I am curious whether it’s still necessary to have an encoder module. LLaMA-Adapter would be an example of adding img2txt capabilities w/o cross attention.
-
Fancy Index Lookups in Embedding Layers and Batch Matrix Operations
By
–
*fancy index lookups in embedding layers followed by fancy batch matrix-matrix products
-
Curiosity about empirical results in NeurIPS LLM efficiency challenge
By
–
Oh yeah, that makes intuitive sense. I am just curious about how this works out empirically. (The NeurIPS LLM efficiency challenge permits encoder, encoder-decoder, and decoder LLMs, so will will probably have to wait until the leaderboard is finalized haha)
-
Decoder-Only Architectures for Vision-Language Models
By
–
That makes sense. But you could also use a decoder-only architecture (with embedded image tokens as part of the input, as in LLaMA-Adapter, for example). (* This uses an encoder for the tokens, but it's still a decoder-only architecture due to the lack of cross-attention)
-
Neural Networks with Gzip Compression for Language Models
By
–
NN + Gzip because we got bored waiting https://
magazine.sebastianraschka.com/p/large-langua
ge-models-and-nearest
… -
Foundation math textbooks and advanced ML AI resources
By
–
Depends on your background and interests. Math textbooks are usually a good foundation for most technical fields.
Shameless plug: if you are into ML and AI and want to pick up some more advanced concepts after an intro book, my ML Q & AI might be useful: -
NVIDIA GPU and CUDA Manual Confusion in Molecular Dynamics Lab
By
–
Can confirm: I was interning at a molecular dynamics lab ~10 years ago. NVIDIA gave us a Tesla GPU, which came with a ~500-page CUDA manual — no one knew what to do with it
-
Comparison of decoder models with ChatGPT and GPT-4 after RLHF
By
–
! I’m mainly curious how it compared to decoders like ChatGPT or GPT-4 after RHLF