Catching up on improving LLMs by scaling inference-time compute, new LLM scaling laws for precision, and more…
"Noteworthy AI Research Papers 2024 Part 2" is now formatted and published. It was certainly an eventful year for this fast-moving field:
@rasbt
-
Noteworthy AI Research Papers 2024 Part 2 Review
By
–
-
Classic LLMs Like ChatGPT Explanation Capabilities
By
–
Classic LLMs like ChatGPT will probably happily explain
-
Rejection Sampling and SFT with 17k Examples Discussion
By
–
I mean, rejection sampling and SFT on just 17k examples, what's not to like ?
-
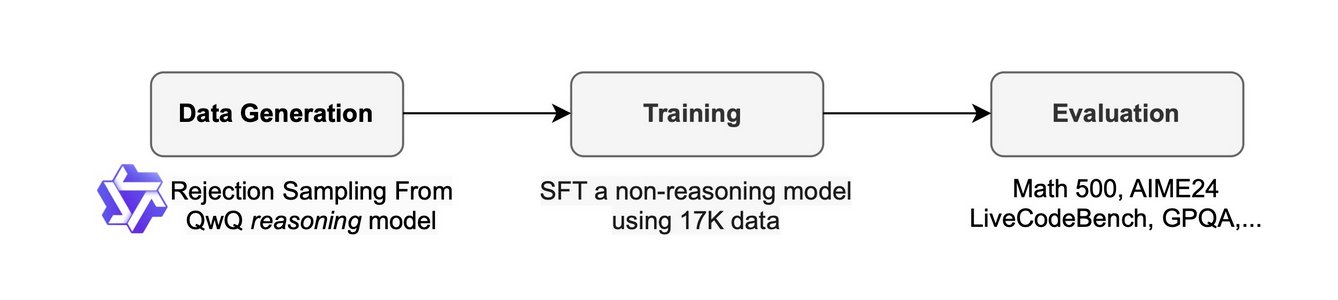
Sky-T1-32B: Open-Source Reasoning Model Rivals o1-Preview Performance
By
–
"Sky-T1-32B-Preview, our reasoning model that performs on par with o1-preview on popular reasoning and coding benchmarks."
That was quick! Is this already the Alpaca moment for reasoning models? Source: https://
novasky-ai.github.io/posts/sky-t1/ -
Leveraging Unified Memory in PyTorch with Blackwell GH200
By
–
Totally missed that and that sounds awesome. Genuine question, how do you leverage unified memory in PyTorch though? Was discussing this with a user who was using Blackwell GH200 the other day here:
-
Loading Pretrained Weights and Selecting Foundation Models
By
–
And in addition, as you will see later in chapter 5, it's necessary to load pretrained weights.
Now there are many open-weight models available, but my reason for this one was also that it's a) the basis for everything that came after (other architectures can be covered in -
Book Update: Future Plans for RNN, LSTM, and GAN Content Revision
By
–
Thanks for your interest in this. I hope to find the time some day, but it won't be very soon I'm afraid. I agree with your suggestions regarding RNN, LSTM, GANs (would replace them with more LLM and diffusion model contents). Unfortunately, the book was already at the max page
-
Synthetic Data Quality Limitations Compared to Raw Data
By
–
yes, totally. But my guess is model-generated synthetic data will always be a bit inferior then raw data (assuming raw data doesn't contain too much false information).
Because in the best case synthetic data preserves the information & in the worst case it adds hallucinations -
Synthetic Data for Pretraining: Proof-of-Concept Study
By
–
True, but I think it's more of a proof-of-concept / study of synthetic data for pretraining rather than generating a production-ready model.