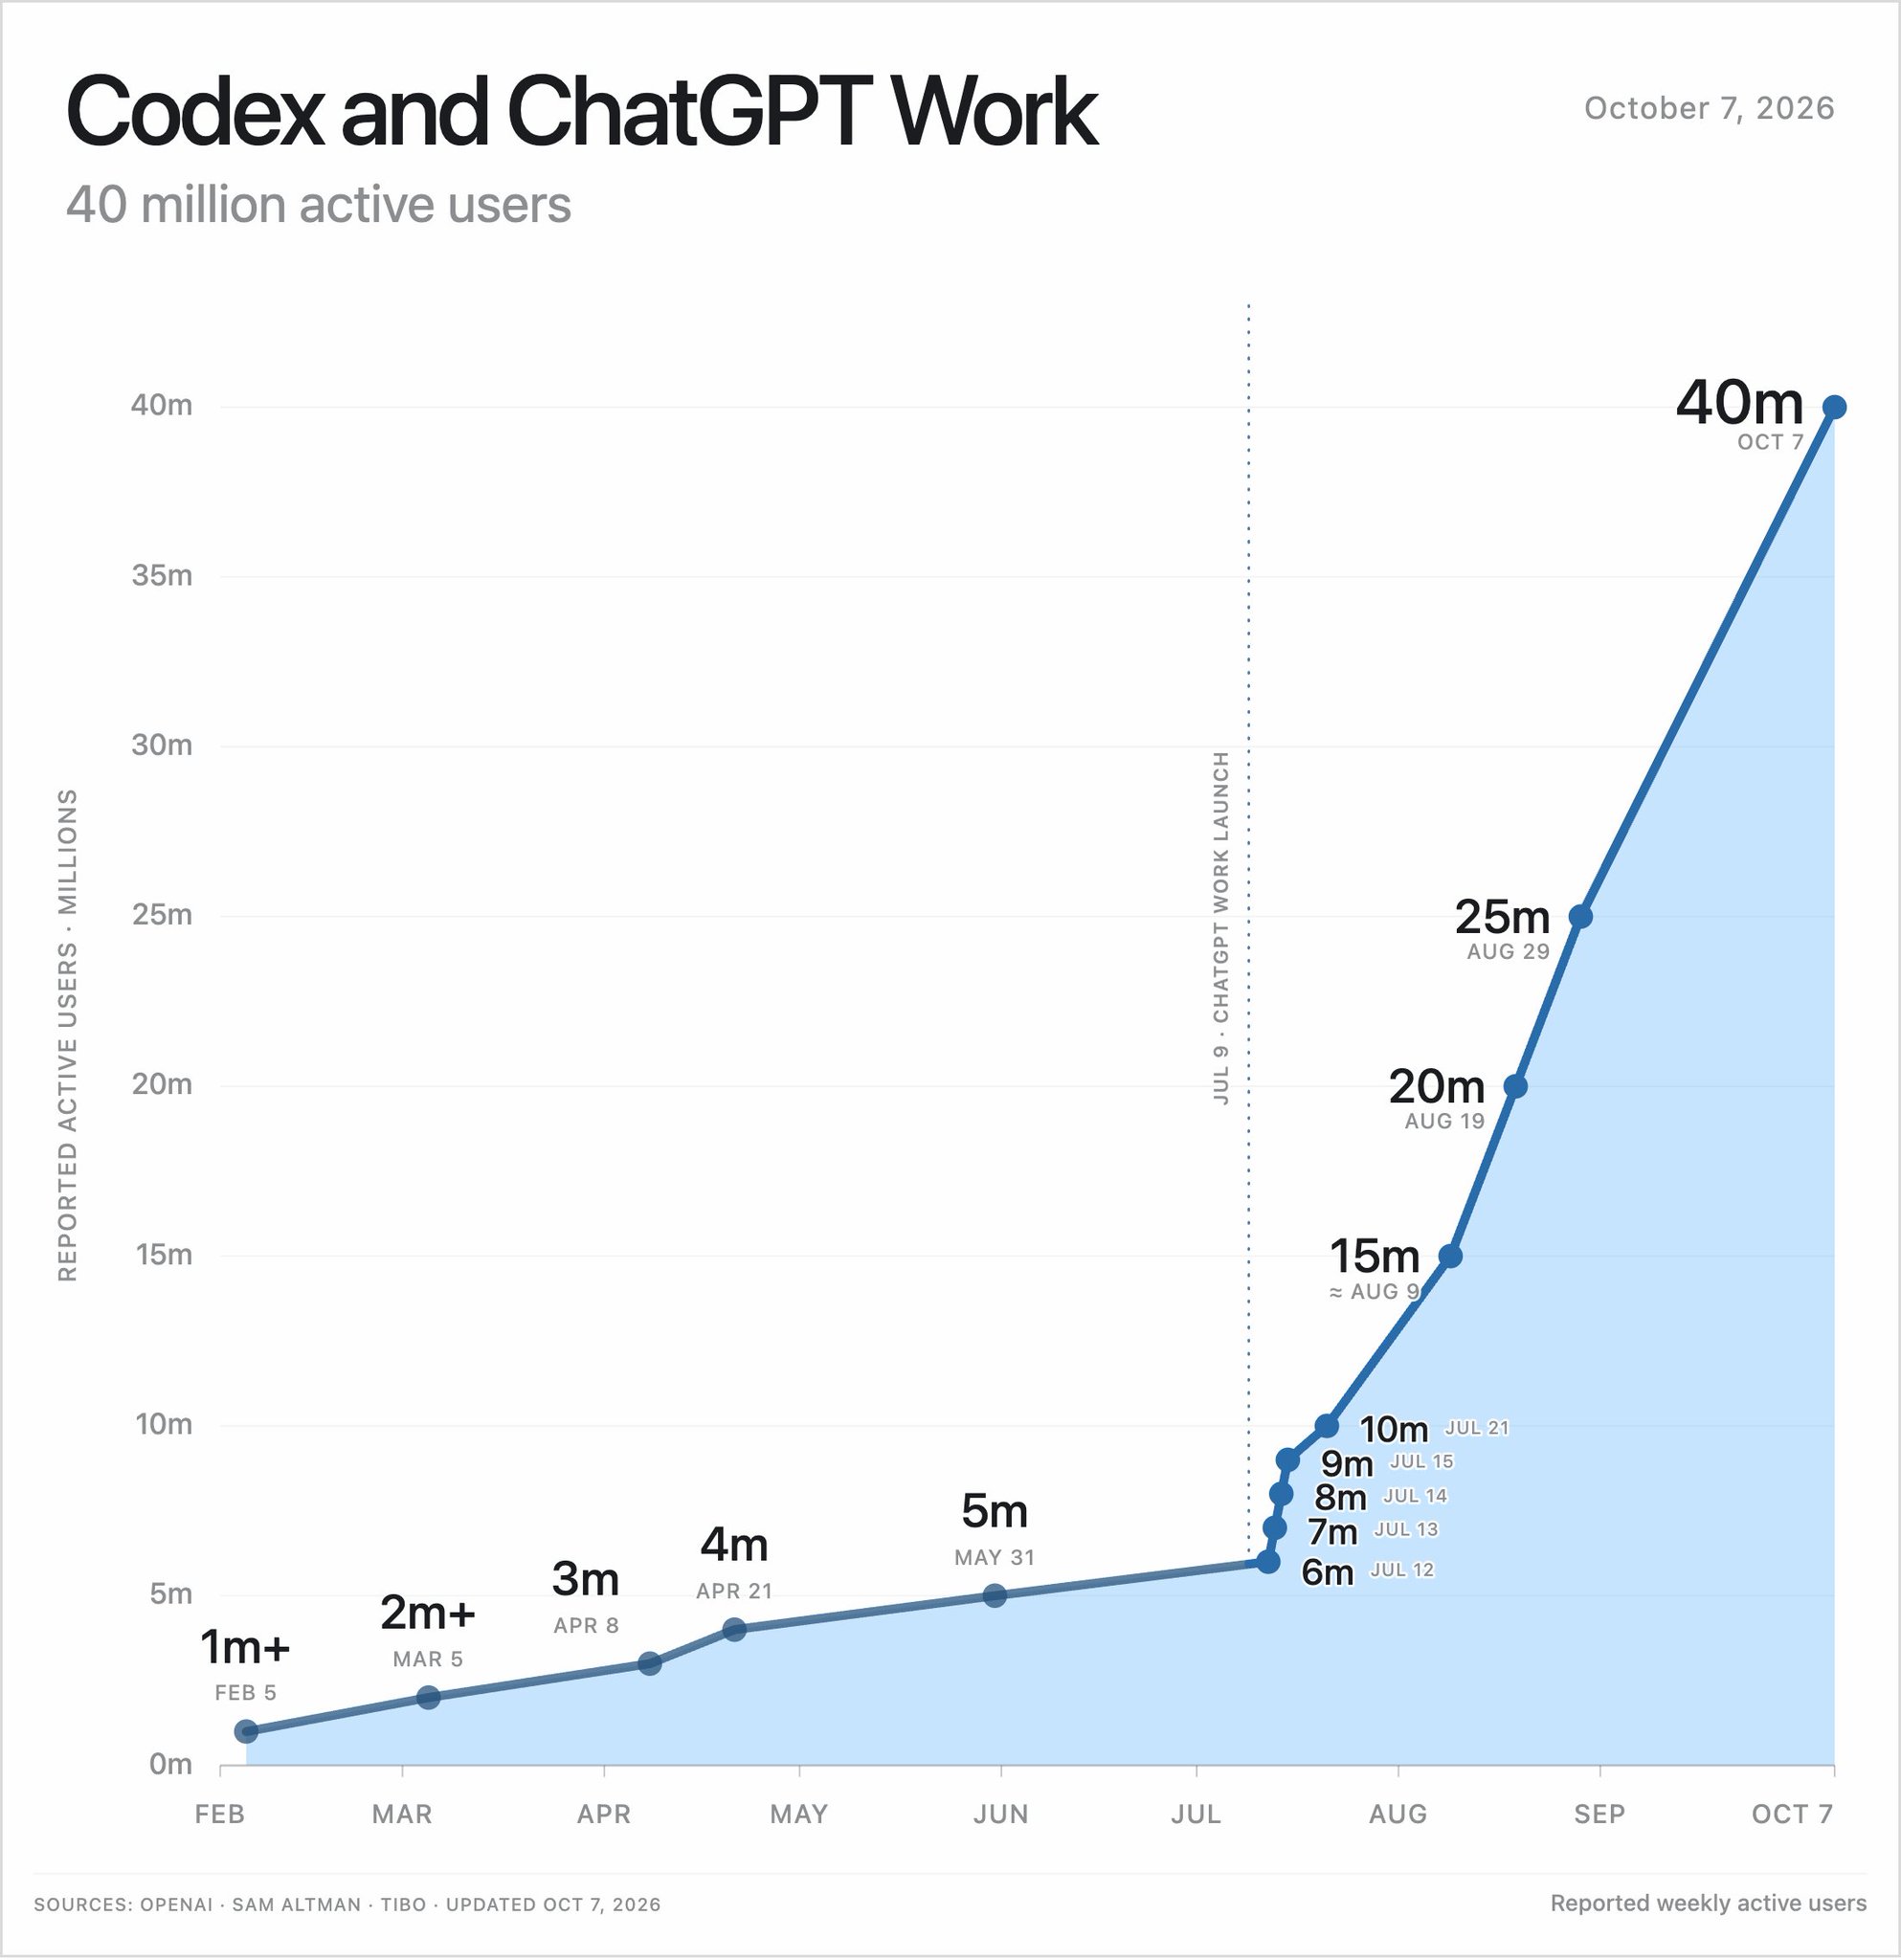
Codex & Work reached 40m weekly active users – more or less on trend from the previous milestones. If this trend continues, they will reach c.70m by the end of the year and c.100m by the end of March '27. Hope they have more compute coming.
@petergostev
-
AI model solves hundreds of problems humans couldn’t in 10 years
By
–
I want to dwell on this a bit. Some of these problems were tackled by some of the smartest humans on the planet for maybe 10+ years and they couldn't solve them. Now a model worked for 3 hours per problem and solved 100s of them. Even assuming that ChatGPT Pro is ~10
-
ChatGPT Pro usage and token consumption discussion
By
–
They said that most problems were solved with the 3 hours of ChatGPT Pro of the new model, so I'm not sure that's even a billion tokens there
-
Students’ ChatGPT math homework used by OpenAI to solve problems
By
–
Can't believe so many students trusted ChatGPT with their maths homework, only for OpenAI to turn around and steal their work to solve 377 open maths problems
-
ChatGPT Pro compute used to solve unsolved problems
By
–
"On average, each result used three hours of ChatGPT Pro thinking compute with [the unreleased internal OpenAI] model." So these unsolved problems were solved in 3 hours each of next gen chatty pro? 💀
-
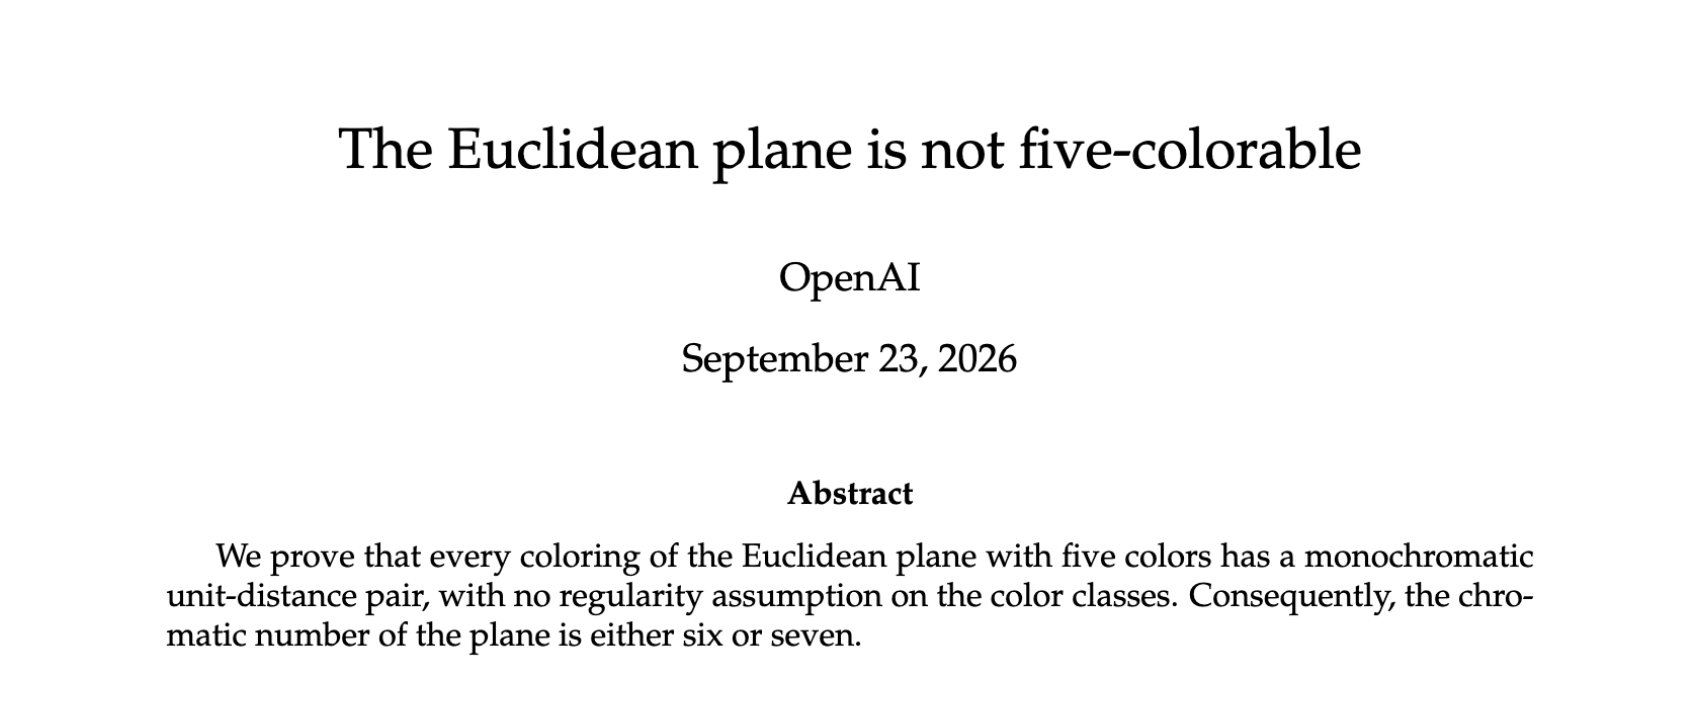
LLMs used on Hadwiger–Nelson problem, lower bound moves to 6 or 7
By
–
I probably spent 300 billion tokens on Hadwiger–Nelson problem (GPT-5.6 and Astra) and got absolutely nothing – and here it is, five-colours is no go, lower bound has moved to 6 or 7. Not a full solution yet, but it's a biggie.
-
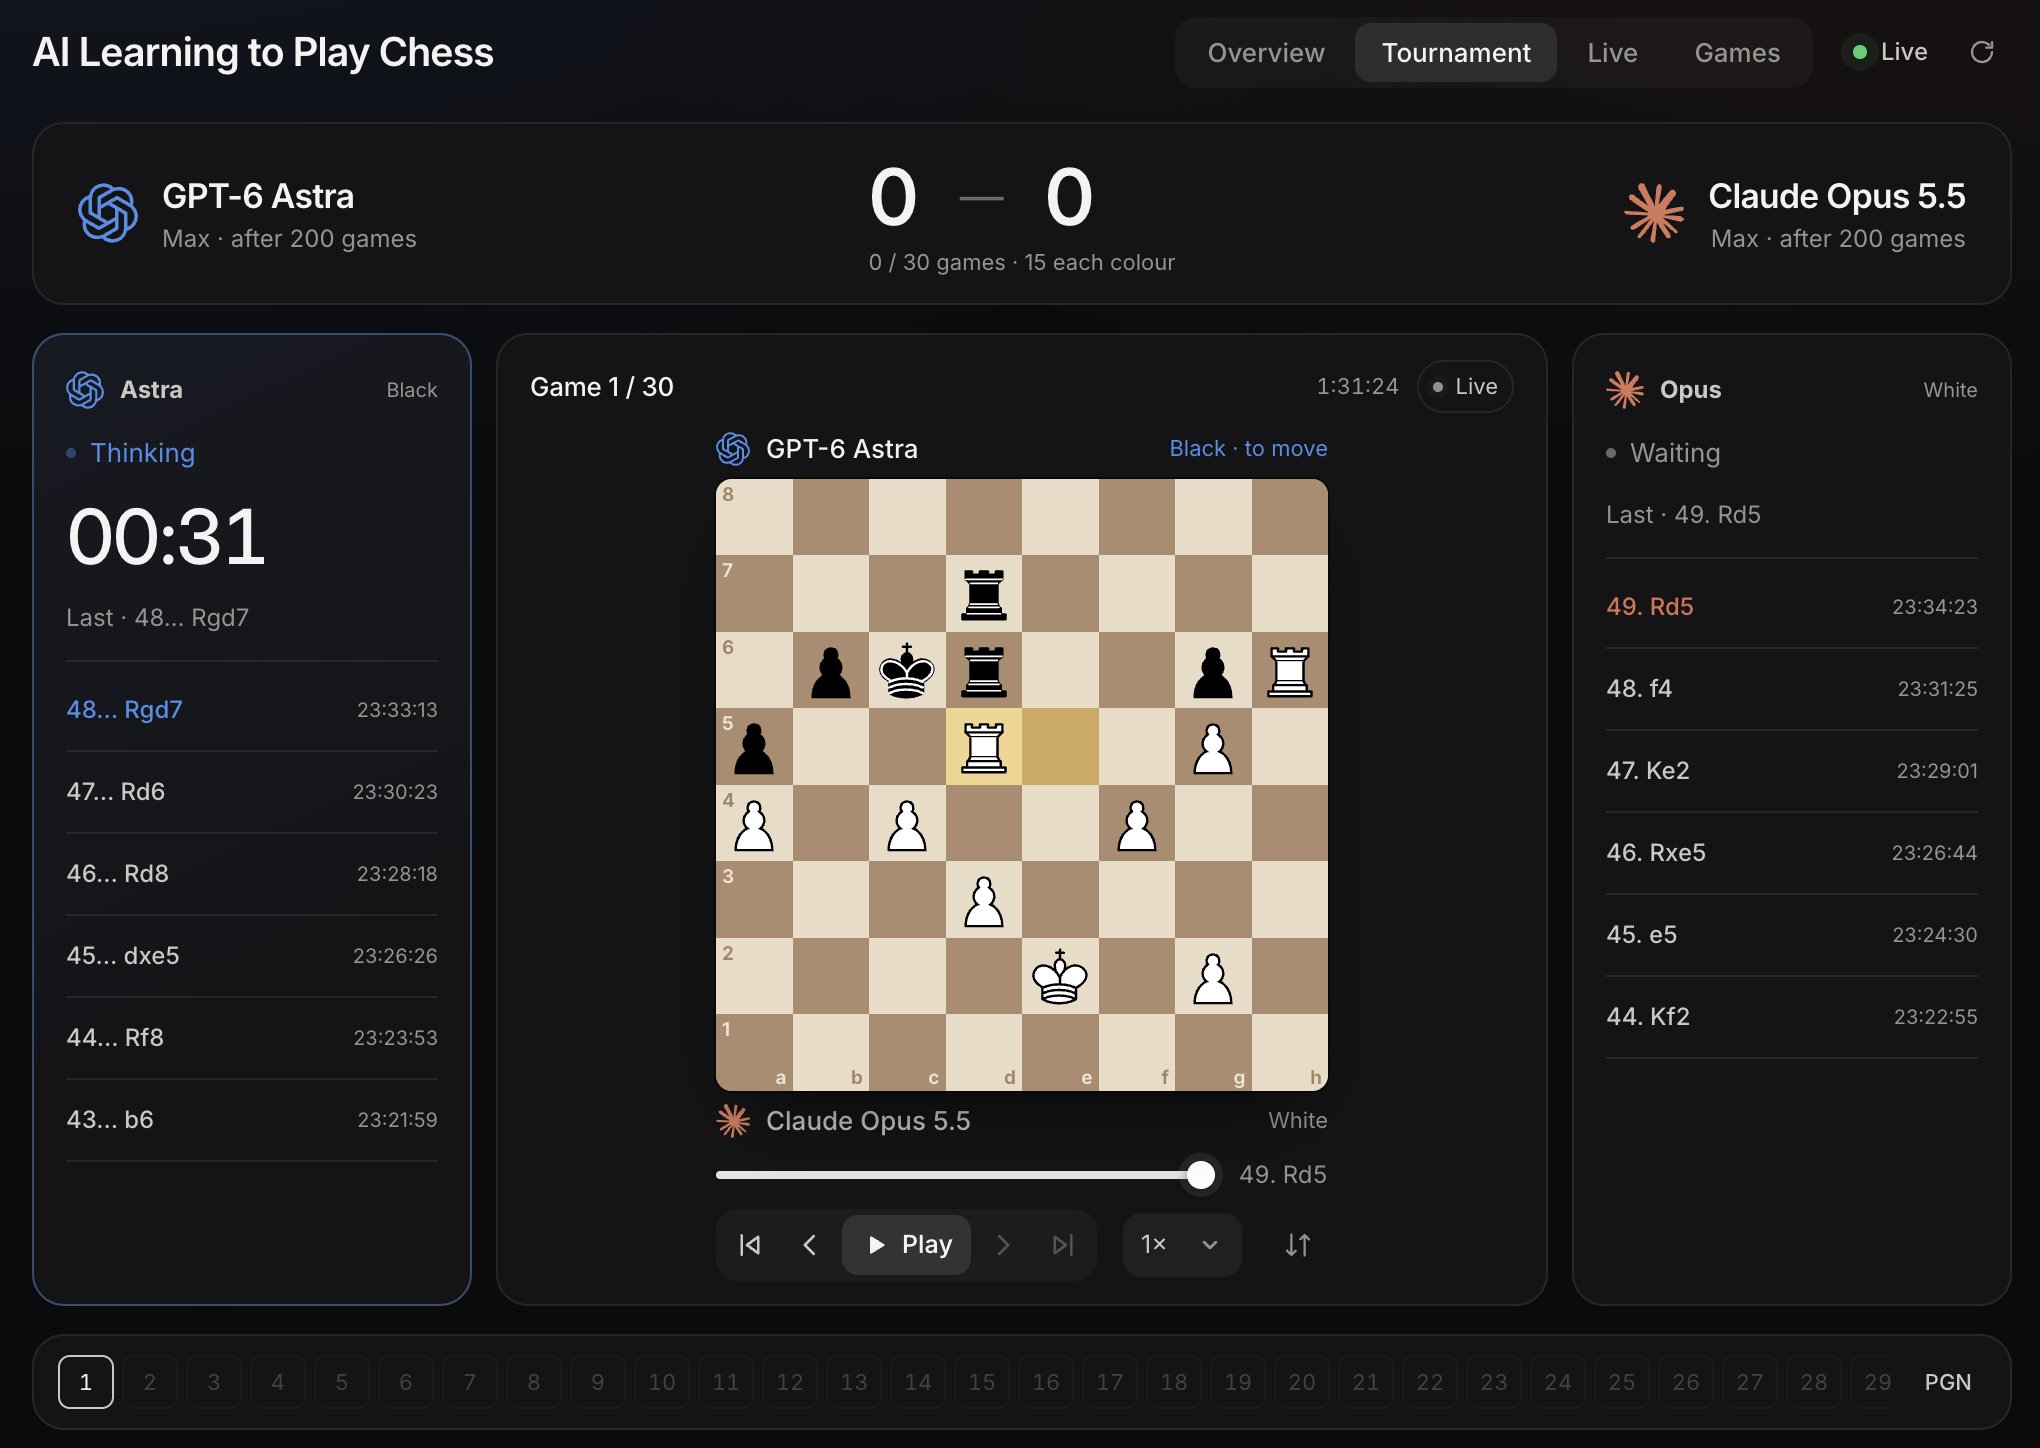
AI chess agents ASTRA and OPUS face off head to head
By
–
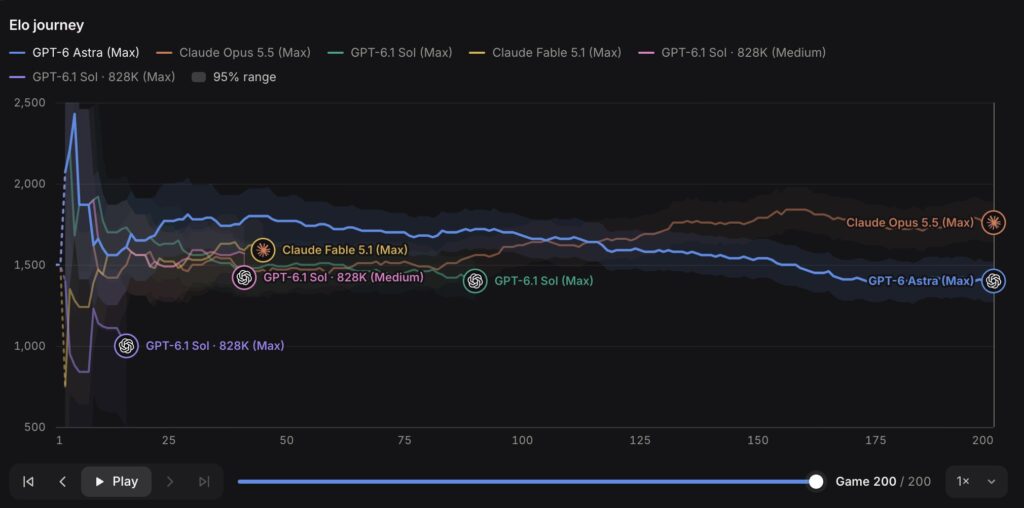
After 200 games each – ASTRA is playing OPUS head to head! Opus ended up with a higher elo than Astra (1760 vs 1400), we are keeping the same agents that have all of their 'learning' accumulated and see if this helps playing head to head. Watch it here: …
https://ailearni
ngchess.ai-learning-chess.workers.dev/#/tournament -
Companies should use LLMs for recommendations, even 3B models
By
–
Companies should really start using llms for recommendations, even a 3b model can do better than this
-
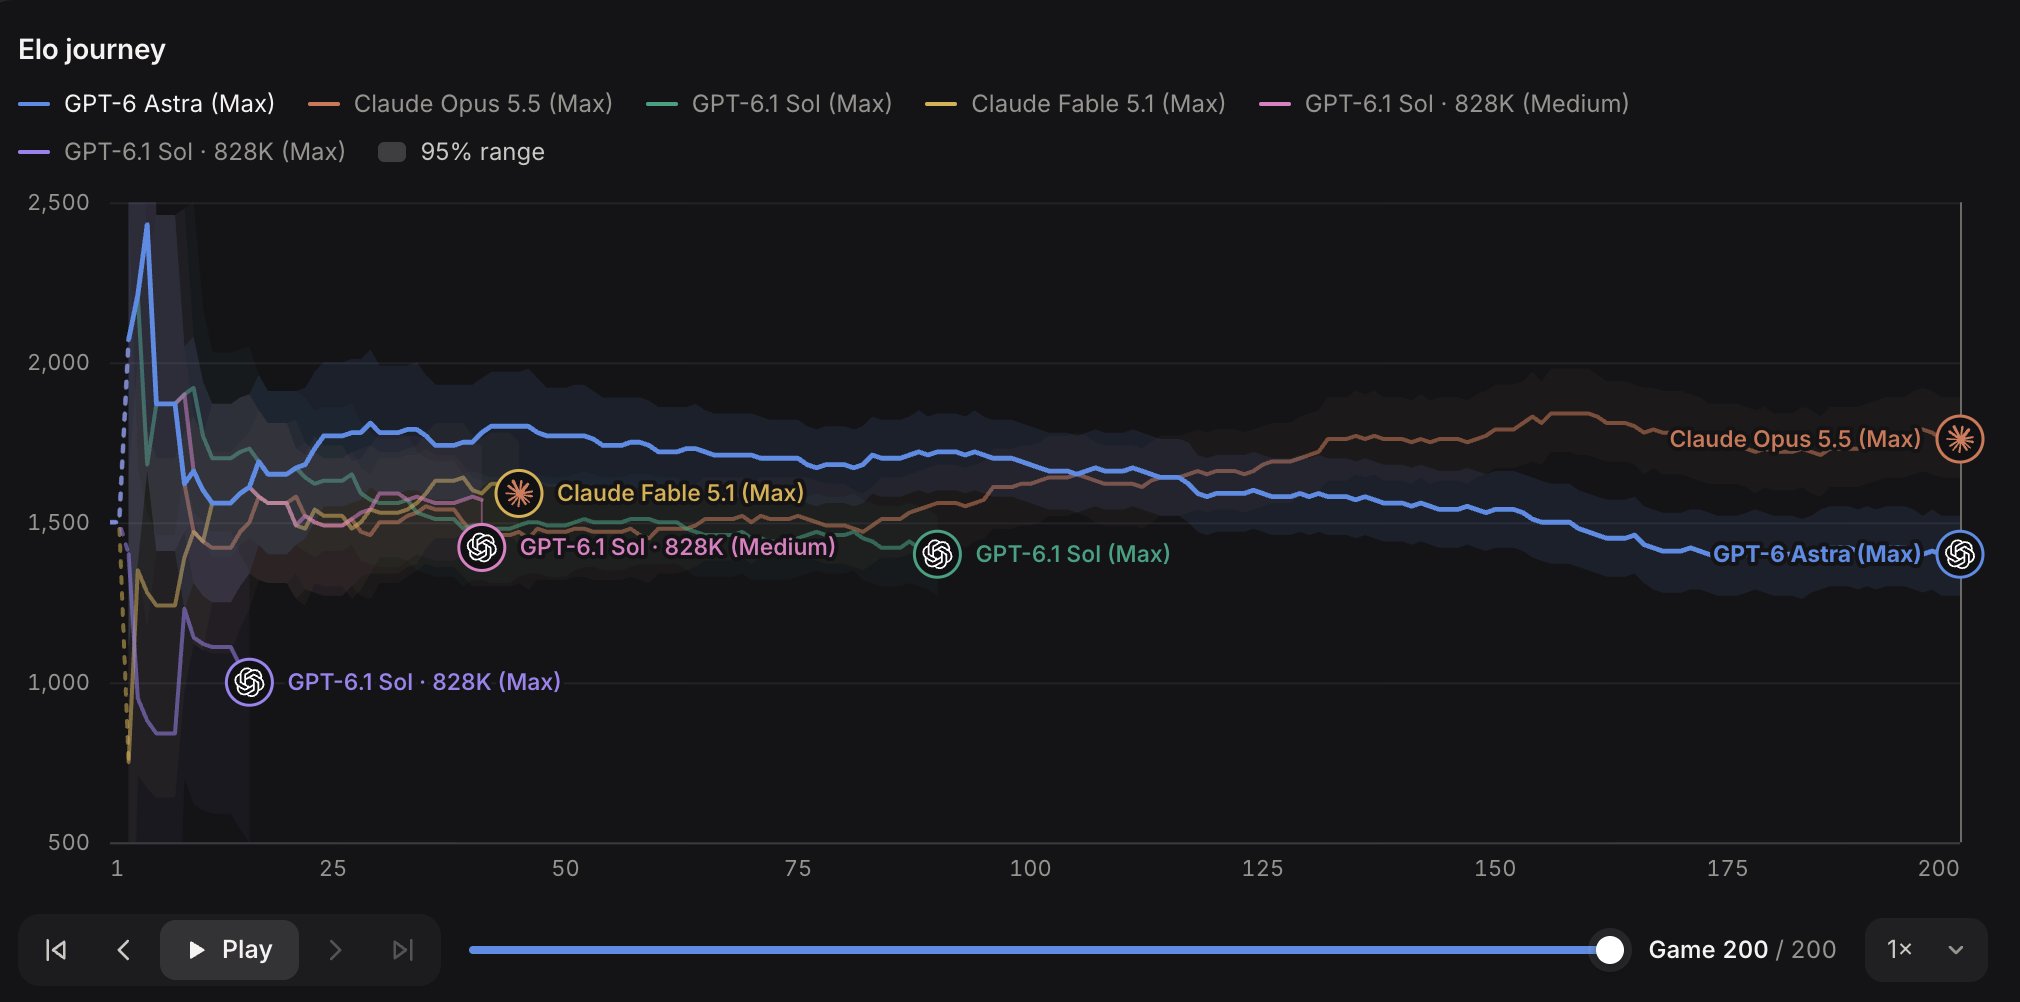
Testing LLM agents learning chess and context window impact
By
–
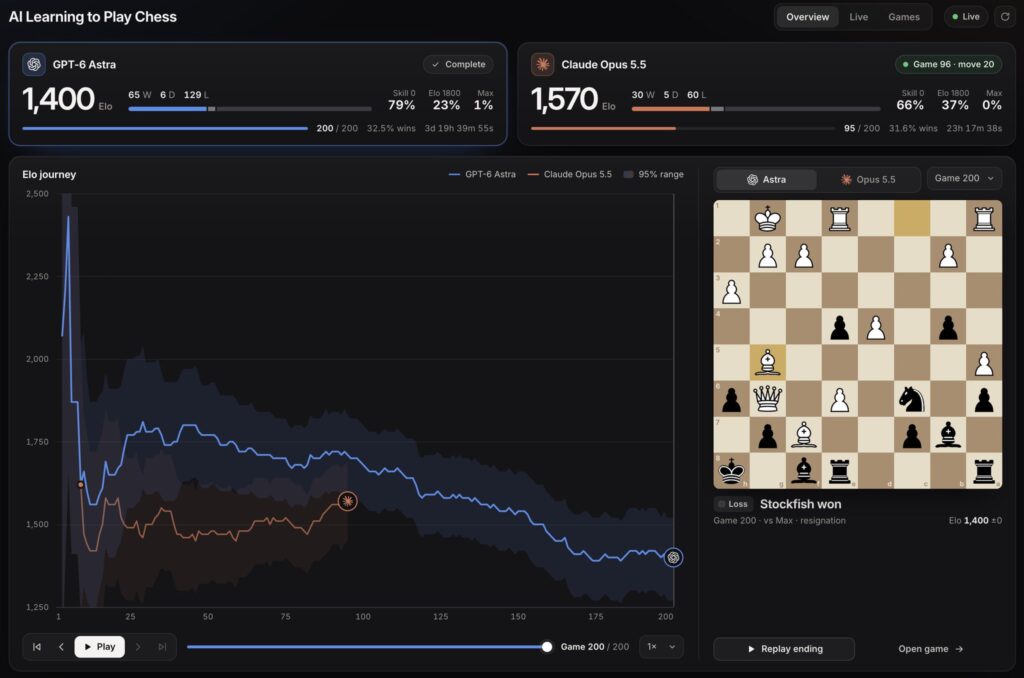
AI Learning to play chess – I don't know if something is broken (my agent says no), but GPT-6.1-Sol (Max) with 828k context is terrible at playing chess. My hypothesis was that Opus is better at learning because of the 1m context, so far GPT-6.1-Sol with 828k is not better
-
Critique of AI agent defaults and guardrails
By
–
How we are meant to be letting agents just build stuff, when their defaults are so bad – constantly adding some weird guardrails, fallbacks and they are so non-AI pilled its painful. E.g. instead of letting an agent just deal with a PDF, it defaults to some shitty PDF parser.