Today we're open-sourcing Bumblebee, a read-only scanner for macOS and Linux. It checks developer machines for risky packages, extensions, and AI tool configs. Connected to Computer, it can trigger deeper scans whenever a new supply-chain risk emerges. https://
github.com/perplexityai/b
umblebee
…
@perplexity_ai
-
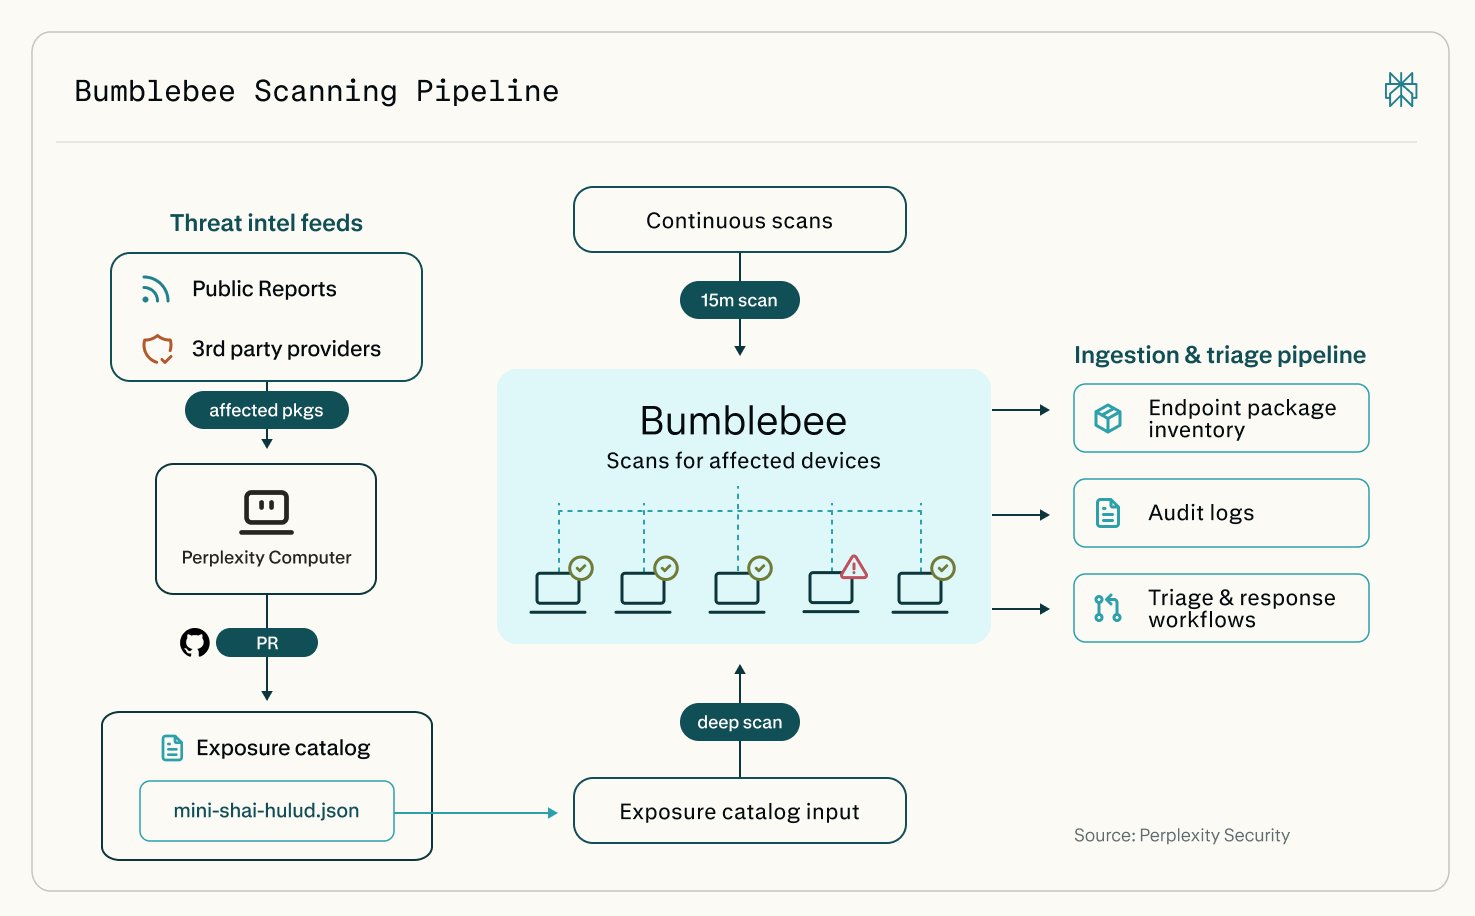
Bumblebee scanner for AI tool configs on developer machines
By
–
-
Query-Aware Context Compression in RAG Systems
By
–
Context compression isn't new in RAG. Our contribution is making it query-aware, citation-preserving, and fast enough for orchestration. Read the full research blog:
-
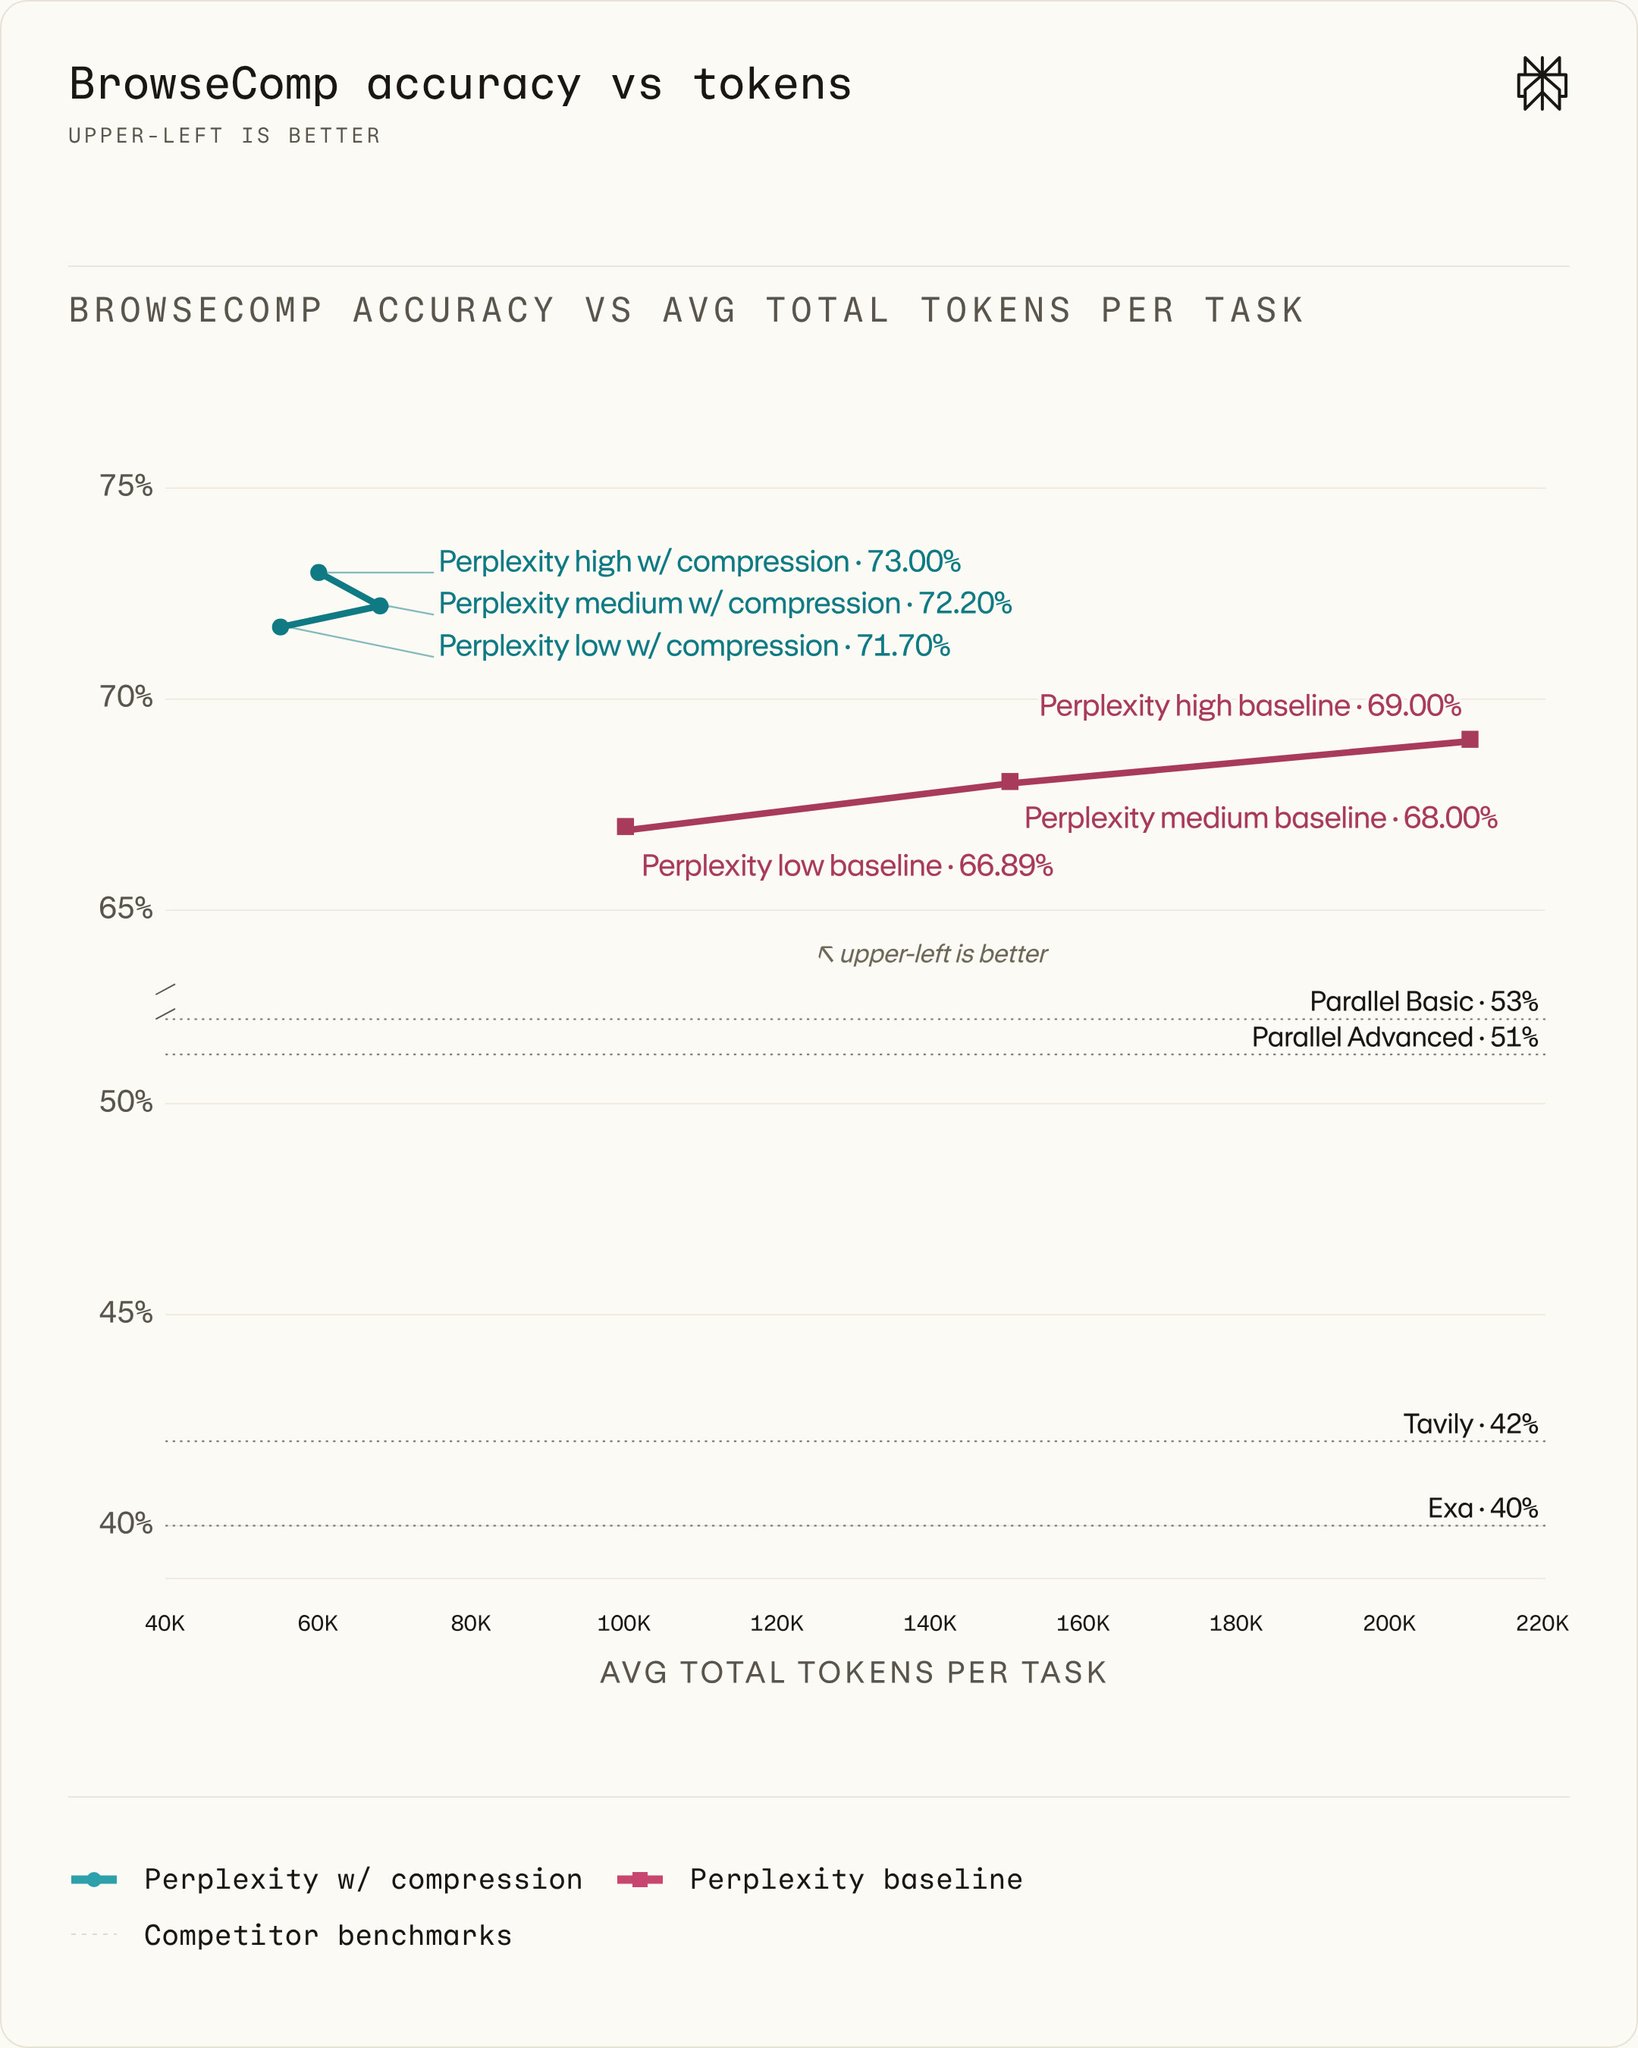
AI-Powered Query-Aware Compression for Enhanced Search Accuracy
By
–
We've productionized query-aware compression for faster, cleaner, more-accurate search. Better context is better than more context. Our system cuts context tokens up to 70% while improving answer quality.
-
AI Tool Saves 120 Work Hours by Automating Task Management
By
–
Rho cut weekly meeting time by 90% with Perplexity Computer. Computer checks Slack, Notion, Jira, Figma, and Google Docs, then flags missing tasks and changes the team needs to see. 120 work hours saved during a 12-week project. Read the customer story:
-
AI Agent Integration Enables Automated Data Analysis with Snowflake
By
–
Computer now connects to Snowflake.
— Perplexity (@perplexity_ai) 14 mai 2026
Run end-to-end work against live warehouse data and get answers with SQL, source tables, filters, and metrics.
It’s like a personal data science team, on call with accurate answers from live company data. pic.twitter.com/L1uQC6u5zZComputer now connects to Snowflake. Run end-to-end work against live warehouse data and get answers with SQL, source tables, filters, and metrics. It’s like a personal data science team, on call with accurate answers from live company data.
-
NVIDIA GB200 Architecture Optimized for Large-Model Inference
By
–
This NVIDIA remains the strongest platform for large-model inference at scale. Prefill/decode disaggregation, Blackwell-native quantization, custom kernels, and rack-scale NVLink turn GB200 into faster answers lower serving cost. Read the full paper here
-
Performance Benchmarks: NVIDIA H200 vs GB200 for AI Workloads
By
–
The benchmarks show the gap. NVLS all-reduce latency drops from 586.1µs on H200 to 313.3µs on GB200. In MoE prefill at EP=4, combine falls from 730.1µs to 438.5µs. For decode, GB200 sustains much higher throughput at high token speeds.
-
Hardware Optimization for AI Model Prefill and Decode Phases
By
–
Prefill and decode stress hardware differently. Prefill is compute-bound, so Blackwell Tensor Cores, memory bandwidth, NVLink, and SHARP reductions help. Decode is latency/memory-bound, where GB200’s rack-scale NVLink domain opens up parallelism Hopper could not.
-

Research on Serving Qwen3 235B Models on NVIDIA GB200 Racks
By
–
We published new research on how we serve post-trained Qwen3 235B models on NVIDIA GB200 NVL72 Blackwell racks. GB200 is a major step up over Hopper for high-throughput inference on large MoE models, not just a training platform.
-
Internal Manual for Building AI Agent Skills Published
By
–
We've published our internal manual for building agent skills. Skills require a new way of thinking for developers.