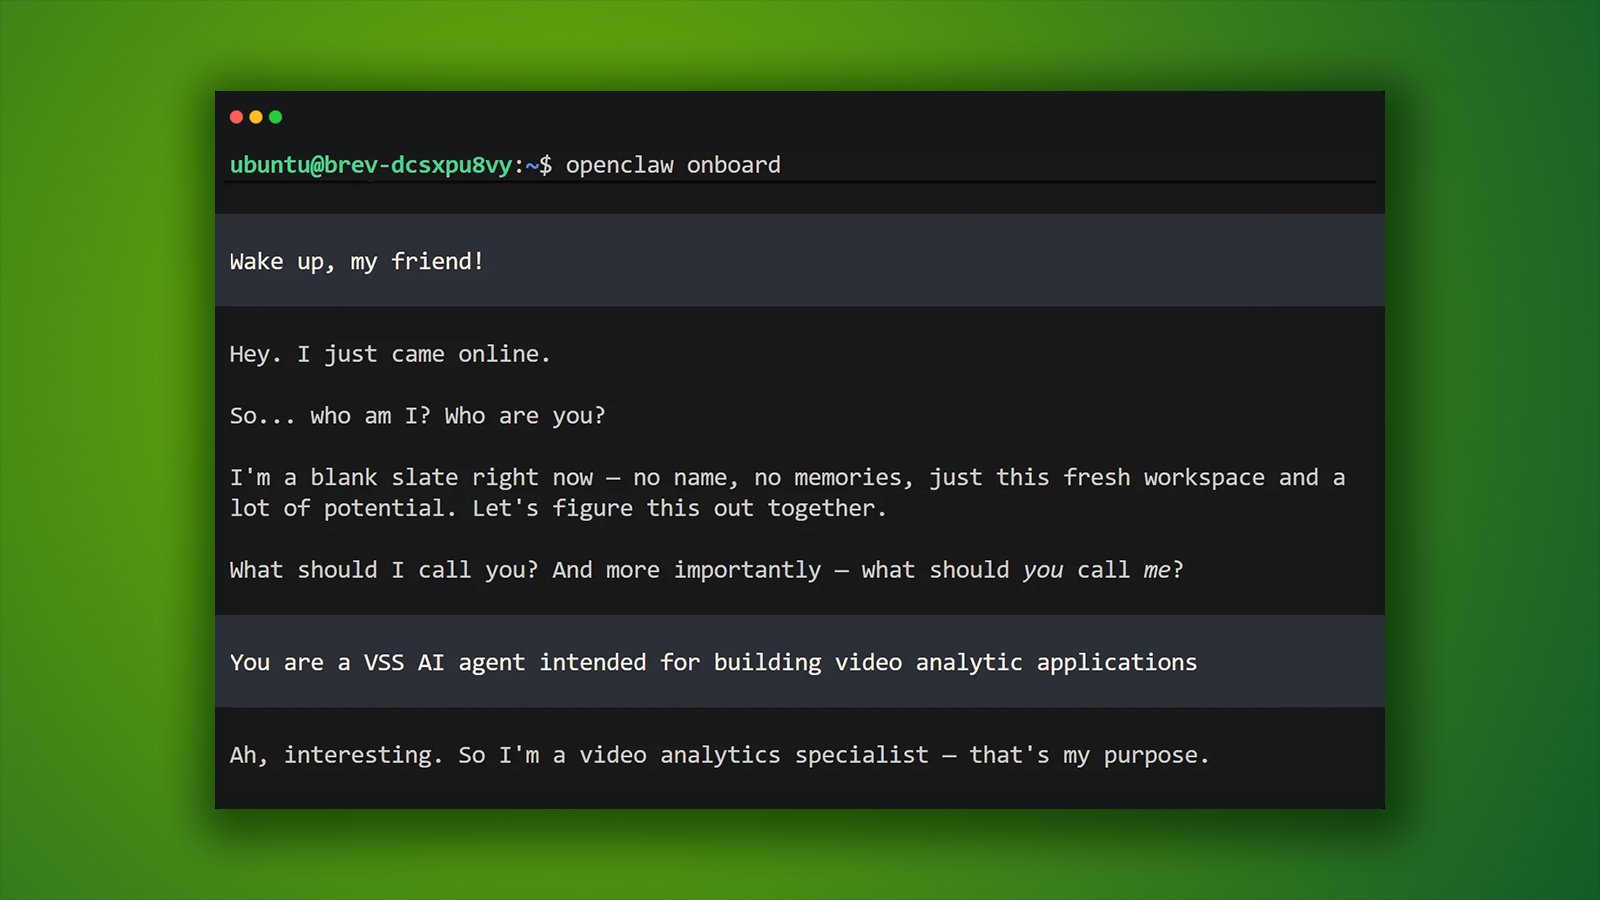
Hours of video, now searchable by your agent. We just released a new set of agent skills and modular architecture for the Metropolis Blueprint for Search and Summarization, eliminating the need for manual configuration of multiple microservices. Load the skills into a
@nvidiaai
-
Step 3.7 Flash MoE Model with 256K Context Released
By
–
Step 3.7 Flash is here ICYMI: 198B MoE with 11B active params, 256K context, native image + video support. Day 0 support is live on http://
build.nvidia.com with GPU-accelerated endpoints, deploy with NVIDIA NIM inference microservices, and fine-tune with the NVIDIA NeMo -
LocateAnything: Vision-Language Detection Model for AI Agents
By
–
This #CVPR2026 paper from our research team is trending #1 on @HuggingFace 🤗
— NVIDIA AI (@NVIDIAAI) 28 mai 2026
Meet LocateAnything: a vision-language detection model that rethinks bounding box prediction. For AI agents and robots, “seeing” is only useful if a model can pinpoint where something is fast enough to… pic.twitter.com/2OGaQnUCnXThis #CVPR2026 paper from our research team is trending #1 on @HuggingFace Meet LocateAnything: a vision-language detection model that rethinks bounding box prediction. For AI agents and robots, “seeing” is only useful if a model can pinpoint where something is fast enough to
-
Linux Foundation OpenMDW Framework for Open Models
By
–
We're adopting the Linux Foundation’s OpenMDW framework across our open model families. This helps make open model licensing simpler and more consistent at scale. A single legal framework across models, code, documentation, and data helps reduce friction for developers and
-
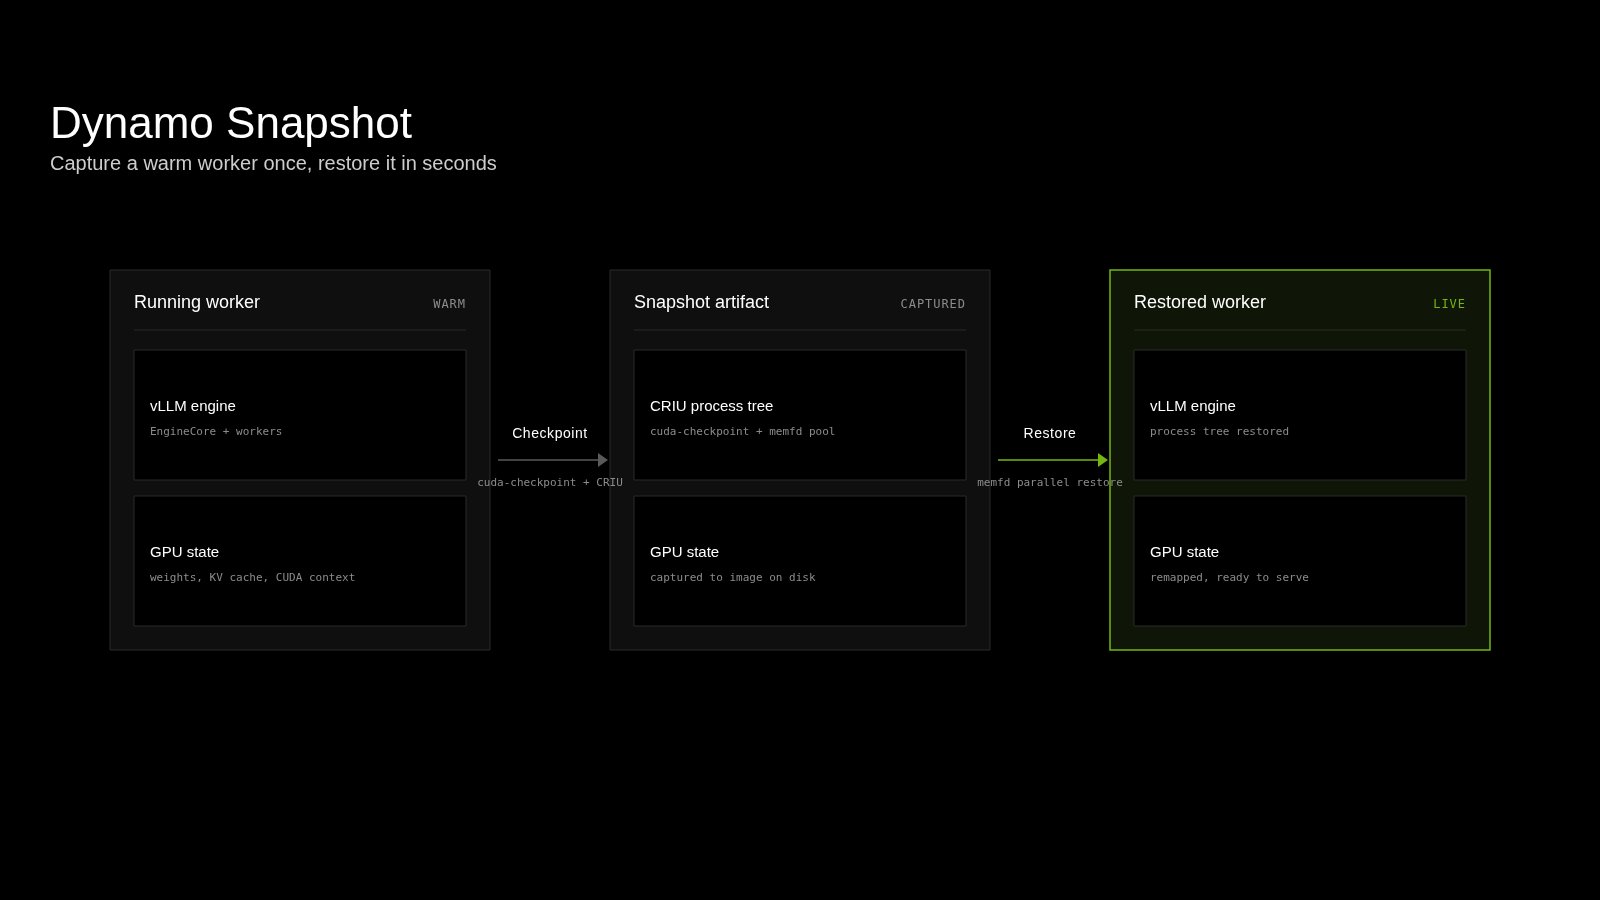
Dynamo Snapshot: Fast Inference Startup on Kubernetes
By
–
Introducing Dynamo Snapshot, our approach for fast startup for inference workloads on Kubernetes, which reduces startup time from minutes to under 5 seconds. In production inference deployments demand fluctuates over time. Cold-starting inference workloads can take minutes,
-
5-second video generation in 4.2s on single Blackwell GPU open-sourced
By
–
You should read this thread.
— NVIDIA AI (@NVIDIAAI) 27 mai 2026
It used to take about 25 seconds to generate a 5-second video on 8 Blackwell GPUs. The legends at @haoailab brought that down to just 4.2 seconds on a single Blackwell GPU… and then open sourced the tech behind it. https://t.co/egQnhx0N1eYou should read this thread. It used to take about 25 seconds to generate a 5-second video on 8 Blackwell GPUs. The legends at @haoailab brought that down to just 4.2 seconds on a single Blackwell GPU… and then open sourced the tech behind it.
-
Text Diffusion and Elastic Reasoning from Nemotron Labs
By
–
From the Lab: Text Diffusion and Elastic Reasoning | Nemotron Labs https://
x.com/i/broadcasts/1
dxYllaRLMLJX
… -
16 Local AI Agents Running on DGX and MiniMax M2.7
By
–
(2x DGX Sparks) + MiniMax M2.7 NVFP4 = 16 local AI agents running simultaneously 👀 https://t.co/Oaf5J1dyuF
— NVIDIA AI (@NVIDIAAI) 25 mai 2026(2x DGX Sparks) + MiniMax M2.7 NVFP4 = 16 local AI agents running simultaneously
-
LongLive-2.0 AI Model Generates Long Videos with Consistency
By
–
A closer look at LongLive-2.0: • Generates long video at 720p
• Preserves subject and background consistency across multi-shot sequences
• Able to switch prompts at chunk boundaries -
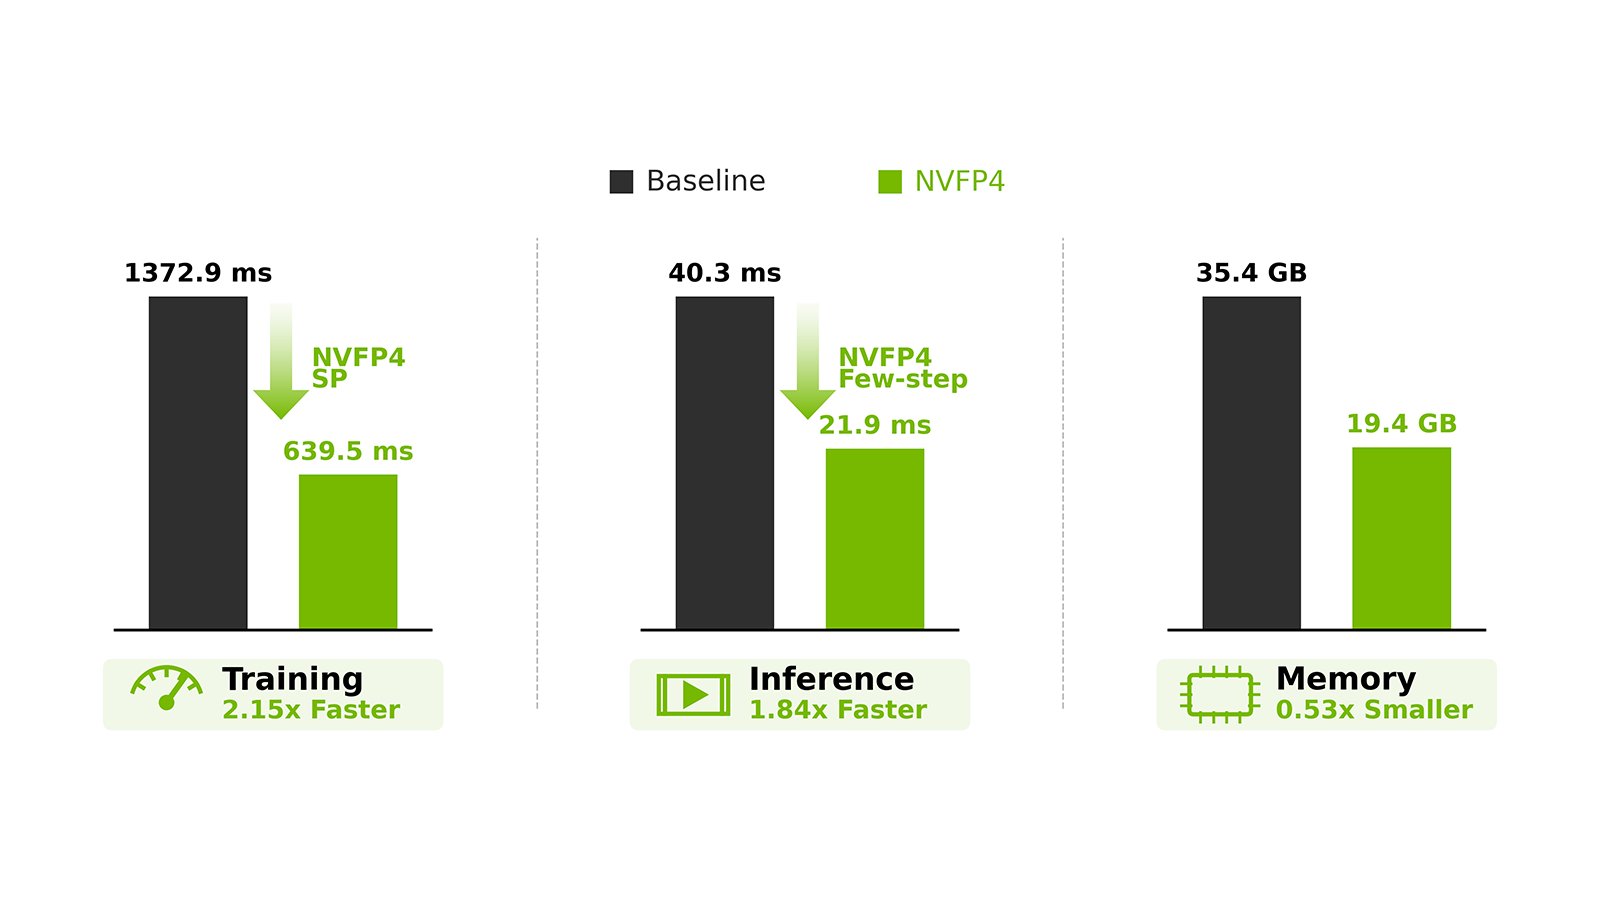
NVIDIA Research Introduces LongLive-2.0 for Long Video Generation
By
–
Long video generation is a systems problem.
— NVIDIA AI (@NVIDIAAI) 22 mai 2026
Introducing LongLive-2.0 from NVIDIA Research: an end-to-end NVFP4 training and inference system for long video generation.
Low-precision deployment often relies on post-training quantization, creating a gap between how models are… pic.twitter.com/rRg35QNOVGLong video generation is a systems problem. Introducing LongLive-2.0 from NVIDIA Research: an end-to-end NVFP4 training and inference system for long video generation. Low-precision deployment often relies on post-training quantization, creating a gap between how models are