Compared to models that’ve only gone through pre- and post-training, models that harness test-time scaling generate many tokens to solve a complex problem.
@nvidiaai
-
AI Factories Optimize Token Revenue at Minimal Cost
By
–
And AI factories maximize token revenue generation at the lowest possible cost. Learn more:
-
Scaling AI Inference Profitably Without Increasing Compute Costs
By
–
To make AI inference profitable, enterprises must scale AI reasoning output—generating more tokens—without driving up compute costs.
-
Smart AI Cost Management for Enterprise Performance and Profit
By
–
Get smart about AI costs to unlock performance, efficiency, and profit at scale. As AI models evolve and adoption grows, enterprises must perform a delicate balancing act to achieve maximum value.
-
Scaling AI Inference Efficiency Through Full-Stack Platforms
By
–
Thanks for the clear explainer! As reasoning grows more compute-intensive, our full-stack AI platform is key to delivering efficient, scalable inference at every step. As demand grows, efficiency isn't optional—it’s foundational.
-
EXFO Leverages NVIDIA Training to Accelerate AI Adoption
By
–
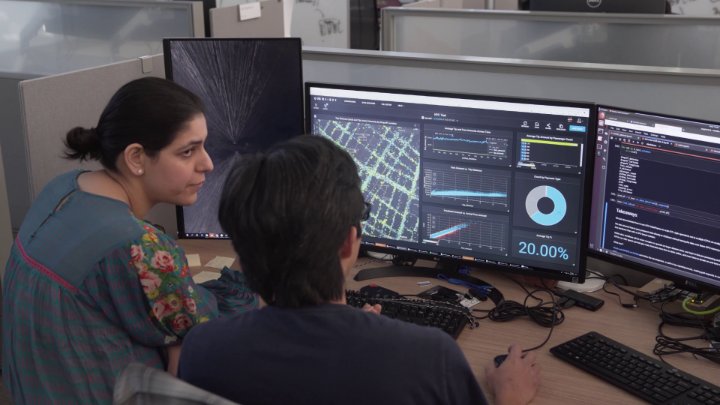
Want to close the gap between AI potential and real-world business impact? Hear how EXFO’s Rajesh Bhosale uses #NVIDIATraining to better connect with customers, communicate AI’s value, and accelerate AI adoption. Watch how technical fluency can unlock new opportunities:
-
Real-time AI and 3D Transform Advertising Landscape
By
–
It’s amazing to see how advertising is transforming with real-time AI and 3D!
-
AI Inference: Delivering Real-World ROI Through Production Models
By
–
AI can’t deliver ROI until it’s optimally running in the real world. That’s where AI inference comes in. It’s the process of applying trained models to new data to make predictions, decisions, or generate responses in real time.
-
Understanding AI Inference: Deployment to Business Impact
By
–
Want a deeper understanding of AI inference, from real-time deployment to business impact? Read our glossary page https://
nvda.ws/4lVUgVm