We will add support soon, it's still W.I.P. due to the how hybrid cache support is handled by vLLM V1.
@maximelabonne
-
Hugging Face SmolLM3: Excellent 3B Model Release
By
–
And shoutout to friends at @huggingface for their SmolLM3 release! It's an excellent 3B model if you want to go bigger, and I loved reading their blog post (cc @eliebakouch and team)
-
Liquid Foundation Models V2 Generative AI Series Released
By
–
Here's the link to our blog post: https://
liquid.ai/blog/liquid-fo
undation-models-v2-our-second-series-of-generative-ai-models
… And you'll find below a link to the @huggingface models. Stay tuned, we have many more announcement to make! -
Local LLM Apps: Decentralized Alternative to Big Tech Monopolies
By
–
I'm really happy with what we've accomplished with LFM2. I'd love to see a future where everybody makes LLM-powered apps with efficient, local models that you own. It's so much sexier than a monopoly of giant companies stealing your data.
-
Fine-tuning tiny AI models with Colab notebooks tutorial
By
–
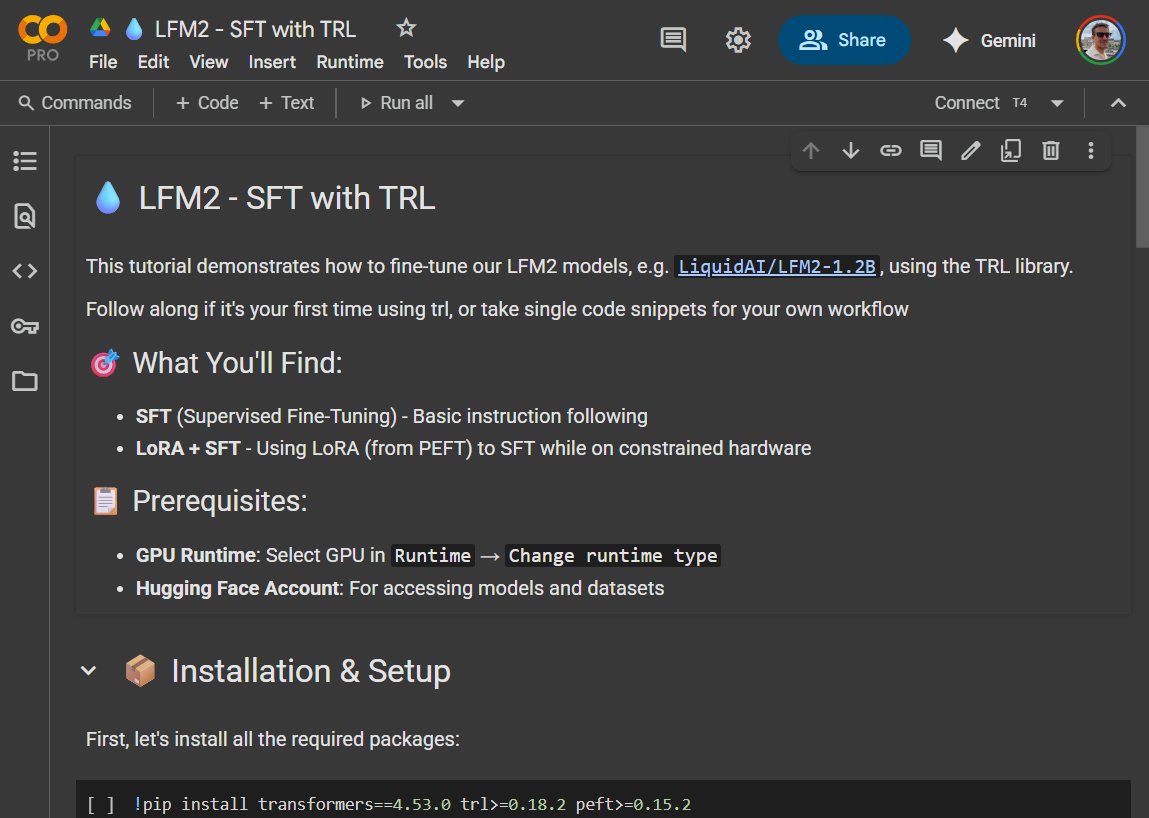
Note that these models are tiny, so I would always recommend fine-tuning them for your use case. My colleague @EdoardMosca created two Colab notebooks to help you in this adventure. You can find them in the model cards. More tutorials to come! 🙂
-
LLM-as-Judge Benchmark: Multi-Turn Conversation Evaluation
By
–
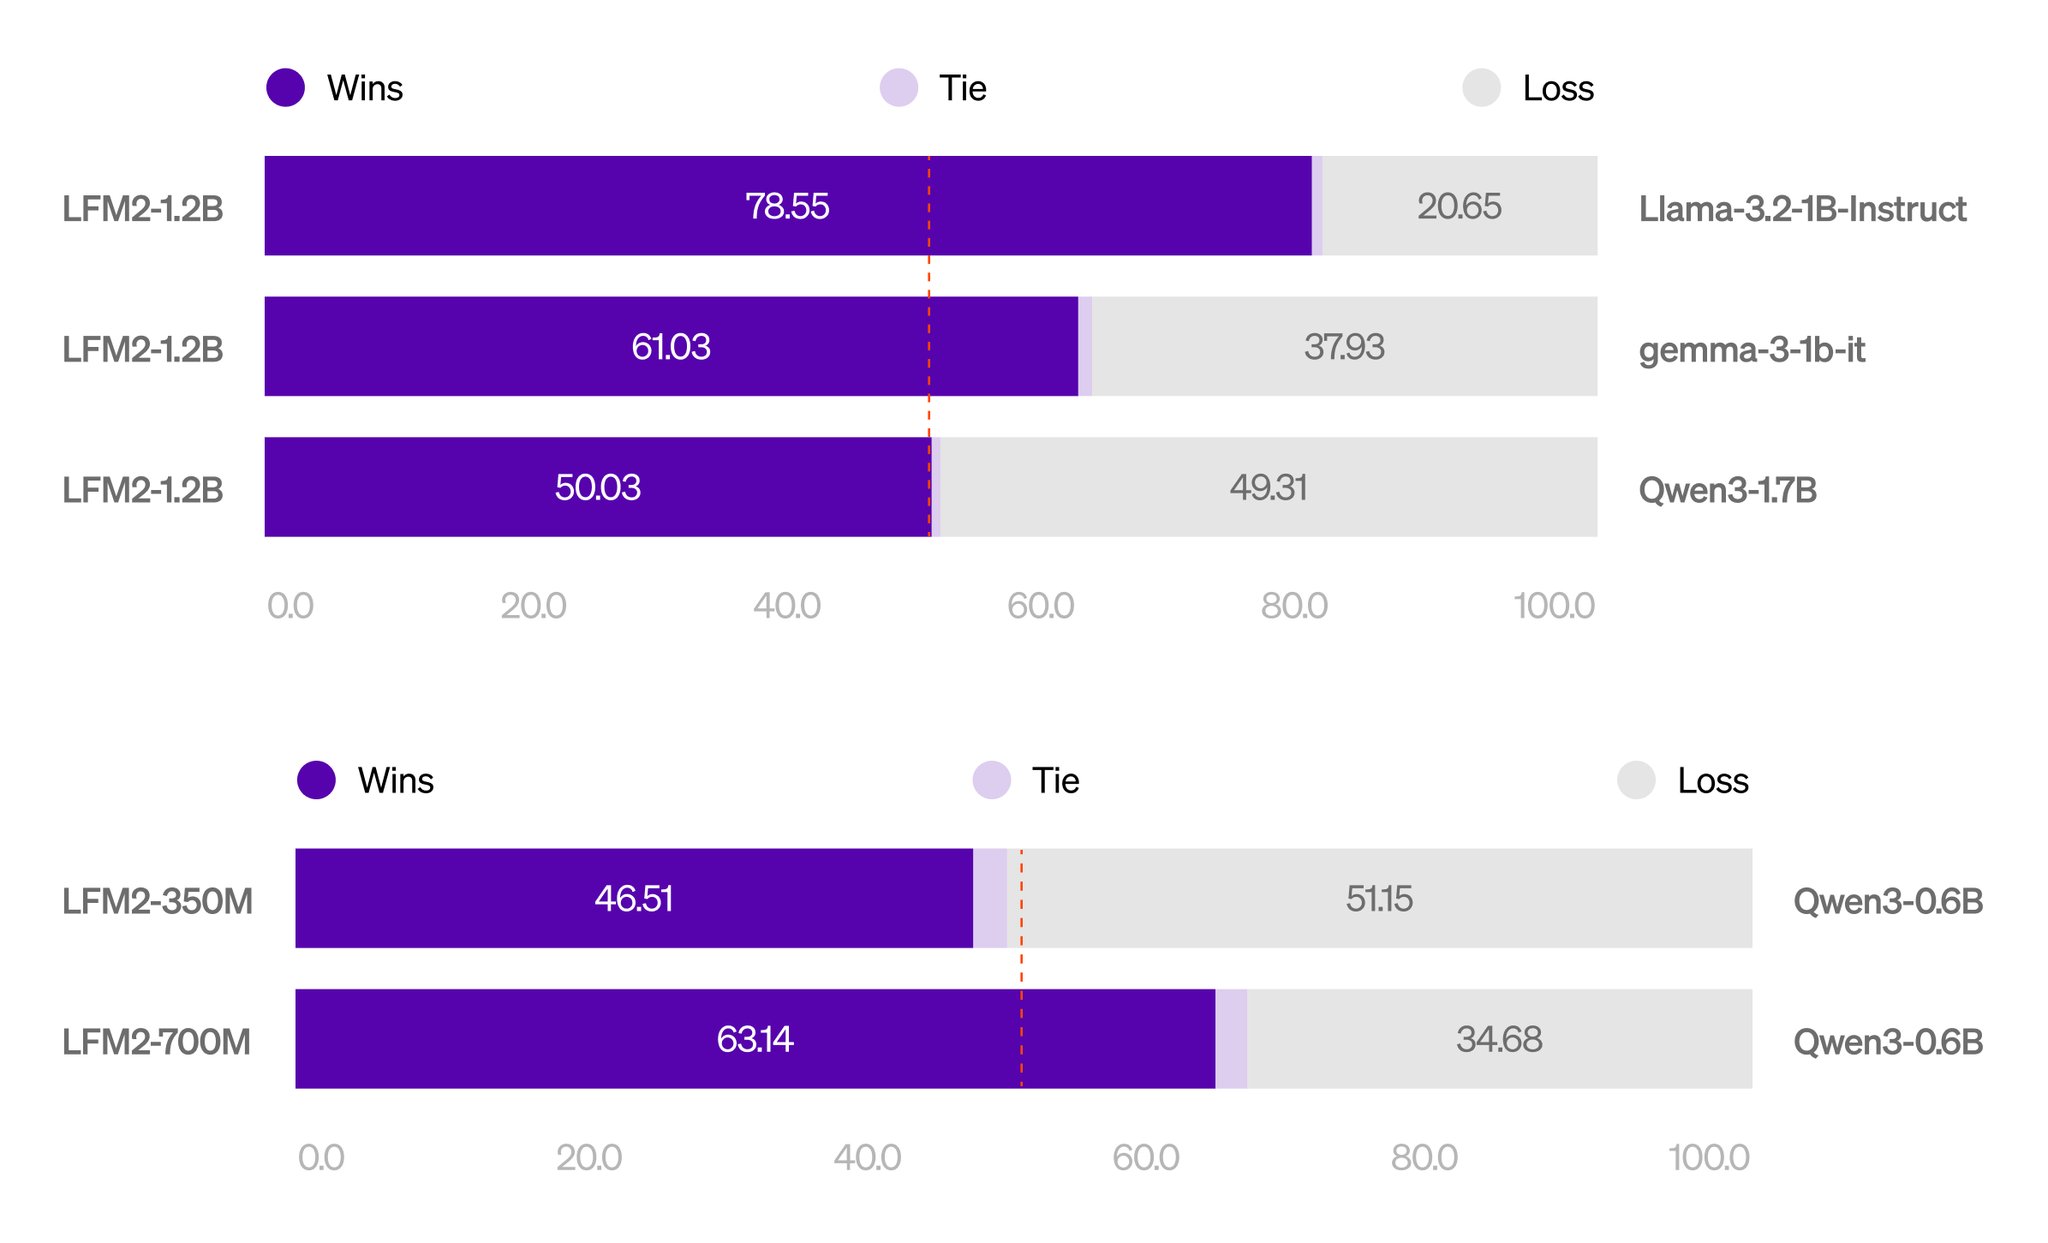
They're also admirable conversationalists for their size. Here's an LLM-as-a-judge benchmark with multi-turn conversations extracted from WildChat and judged by 5 LLMs ↓
-
LFM2-1.2B outperforms larger Qwen3 model through efficient training
By
–
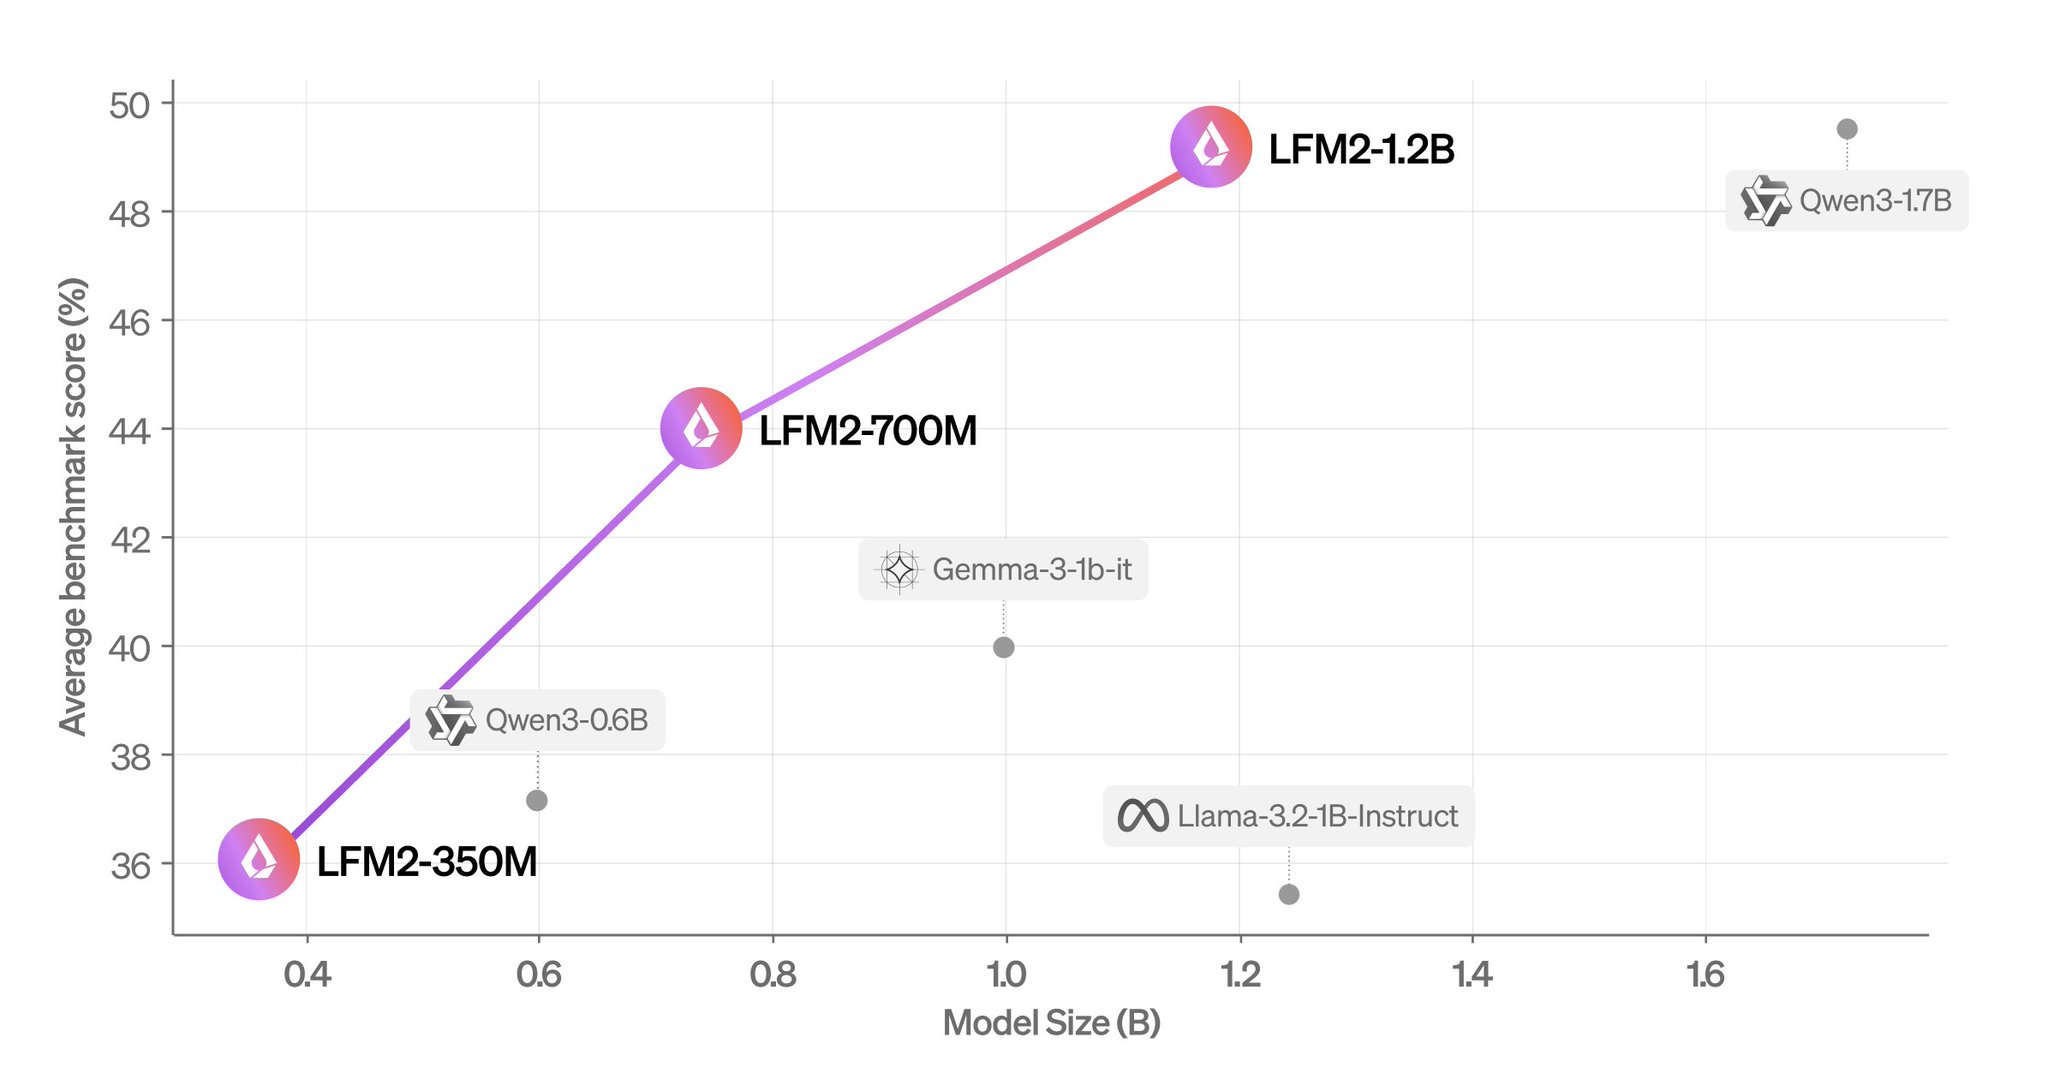
This speed should come at a cost but, thanks to efficient training, we managed to squeeze incredible performance in these tiny models. LFM2-1.2B is competitive with Qwen3-1.7B, a model 47% larger!
-

Hybrid Model with Multiplicative Gates and Short Convolutions
By
–
The result is a hybrid model with multiplicative gates and short convolutions: – 10 double-gated short-range LIV convolution blocks
– 6 grouped query attention (GQA) blocks It's REALLY fast, especially on CPU! -

New Edge AI Architecture Treats Models as First-Class Citizens
By
–
Over the past year, we worked with startups and Fortune 500 companies to understand their needs. They all wanted one thing: fast and performant edge models. So we designed a new architecture to finally treat edge AI as a first-class citizen!
-
Liquid AI Open-Sources LFM2 Edge LLMs Generation
By
–
Liquid AI open-sources a new generation of edge LLMs! I'm so happy to contribute to the open-source community with this release on @huggingface
! LFM2 is a new architecture that combines best-in-class inference speed and quality into 350M, 700M, and 1.2B models.