Oh no, Grok is falling into C-tier
@maximelabonne
-
Frontier Models Overview: Current AI Landscape Assessment
By
–
Alright, this is just frontier models. Not ranking the companies or products.
-
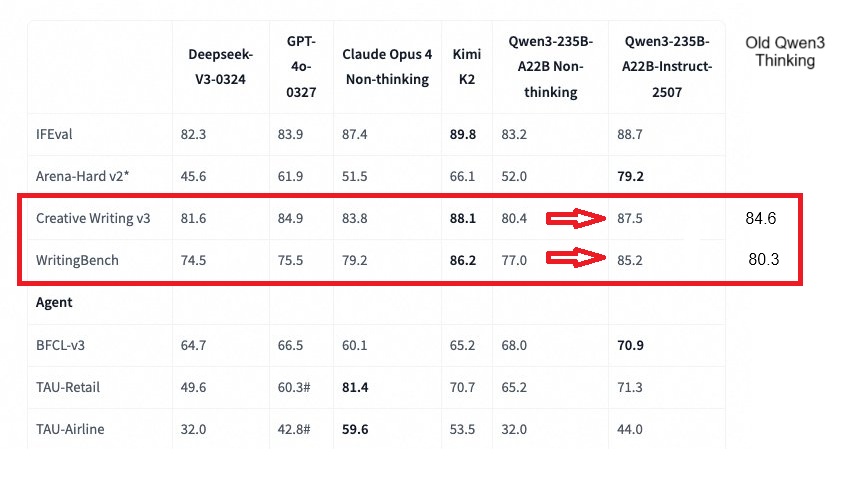
Qwen3 Model Excels at Reasoning and Creative Writing Tasks
By
–
Very nice post-training lesson from the new Qwen3 model: – A pure reasoning model is expected to perform better on pure reasoning benchmarks. Nothing surprising. – We previously saw that pure reasoning models also perform very well on non-reasoning tasks, like creative writing.
-
LFM2-1.2B May Not Be Strongest Frontier Model
By
–
I'm afraid LFM2-1.2B might not be the strongest frontier model
-
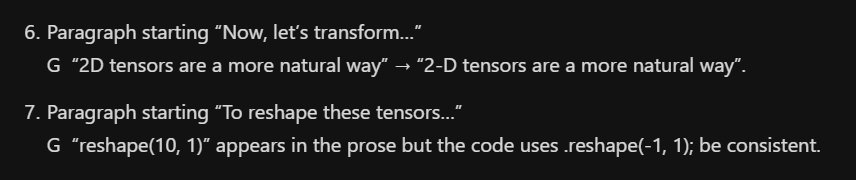
Kimi K2 AI Hallucinations in Code Review Analysis
By
–
I really like Kimi K2's writing style, but it completely hallucinates errors in my article review haha .reshape(-1, 1) isn't mentioned a single time
-
Healthcare AI Blog Post Recommendation for Learning
By
–
I recommend reading the blog post to learn more about healthcare AI
-
vLLM Integration Now Available for Development
By
–
Thanks! We're currently working on vLLM integration. Go wild with it!
-
Apollo Launch Receives Congratulations from Community
By
–
Apollo is a banger, congrats guys! 👏 https://t.co/7jxqSBJzSG
— Maxime Labonne @ ICLR (@maximelabonne) 16 juillet 2025Apollo is a banger, congrats guys!
-
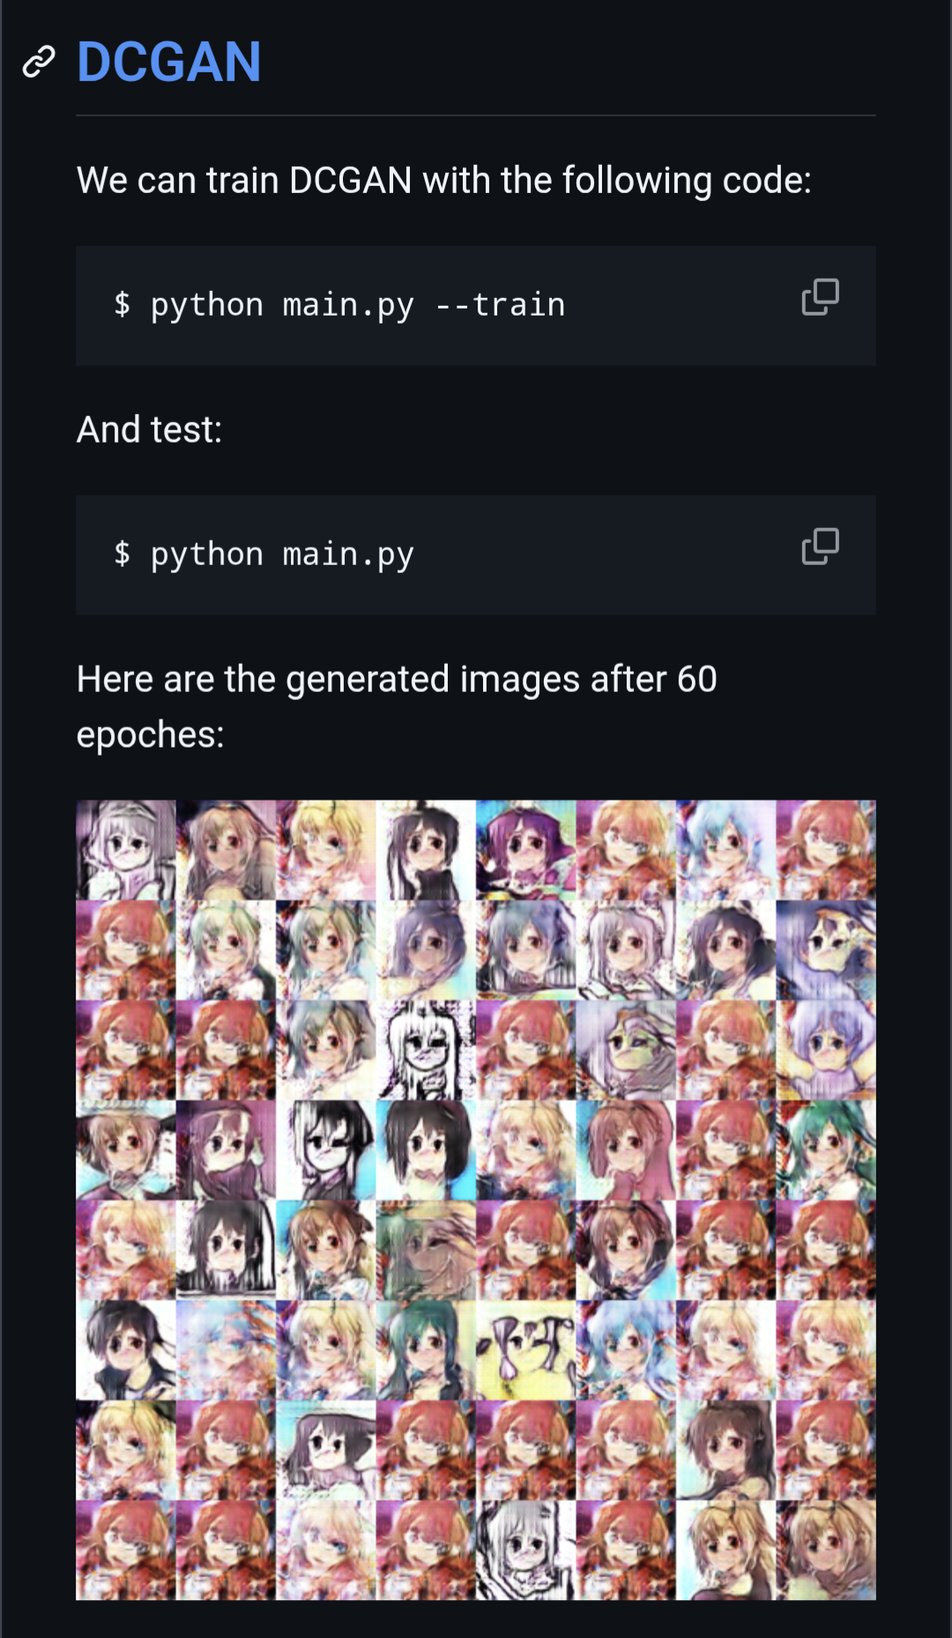
WaifuGAN Team Achieves Six-Year Research Goals Successfully
By
–
So proud of the WaifuGAN guys for fulfilling their dreams after six years and a research department
-
Fixing AI System Prompt Training Issues
By
–
Looks like someone is trying to fix a training issue with system prompting